
LLM Architecture Gallery
A curated reference for modern language-model architectures
Compare architecture diagrams, implementation links, release dates, attention mechanisms, decoder types, and compact fact sheets without digging through individual posts.
The gallery focuses on text-only LLMs and language-model backbones. For multimodal releases, cards usually describe the text decoder/backbone rather than every vision, audio, or image-generation component.
Corrections are welcome in the issue tracker. If the latest changes are missing, try a hard reload (macOS: Command + Shift + R; Windows: Ctrl + F5).
Support this project
Your support helps me maintain and expand the gallery. The downloads below are a thank-you for paid Ahead of AI subscribers.
Architecture images
Download all diagrams and use the poster builder to make your own poster.
Download ImagesModel metadata
Download model specs and info as YAML for your own analyses.
Download MetadataArchitecture diff tool
Select two models to compare their architectures
If you want to compare two architectures side by side instead of browsing the gallery, use this diff tool.
You can use the selectors here or the Model A / Model B actions on each card.
No models match these filters.
Late-2019 dense baseline included here as a reference point for how much decoder stacks have changed since GPT-2.
- Scale
- 1.5B parameters
- Context (tokens)
- 1,024
- License
- OpenAI "Modified MIT" license
- Date
- 2019-11-05
- Decoder type
- Dense
- Attention
- MHA with learned absolute positional embeddings
- Layer mix
- 48 MHA
- KV cache / token (bf16) info
- 300 KiB · High
- Key detail
- Classic GPT-2 recipe with dropout, GELU, LayerNorm, and full multi-head attention.
- Pretraining data
- 40 GB of text; over 8M documents WebText corpus size after filtering and deduplication. The report does not provide a total training-token count. GPT-2 report
- Post-training methods
- None (base model) Original pretrained language model; no instruction or preference post-training in this release. GPT-2 report
Related concepts
Compare
Reference dense Llama stack used to contrast OLMo 2's normalization and attention choices.
- Scale
- 8B parameters
- Context (tokens)
- 8,192
- License
- Llama 3 Community License Agreement
- Date
- 2024-04-18
- Decoder type
- Dense
- Attention
- GQA with RoPE
- Layer mix
- 32 GQA
- KV cache / token (bf16) info
- 128 KiB · Moderate
- Key detail
- Pre-norm baseline; wider than OLMo 2 at a similar scale.
- Pretraining data
- >15T tokens Pretraining budget for the original April 2024 Llama 3 release. Model card
- Post-training methods
- SFT, DPO, RLHF The Instruct variant uses SFT, rejection sampling, PPO, and DPO with preference rankings. These stages apply to the instruct counterpart of the gallery's base configuration. Release post
Compare
Small dense Llama baseline in the Qwen comparison, with fewer layers but more width.
- Scale
- 1B parameters
- Context (tokens)
- 128,000
- License
- Llama Community License Agreement (variant-specific)
- Date
- 2024-09-25
- Decoder type
- Dense
- Attention
- GQA
- Layer mix
- 16 GQA
- KV cache / token (bf16) info
- 32 KiB · Low
- Key detail
- Wider architecture with more heads than Qwen3 0.6B.
- Pretraining data
- Up to 9T tokens Pretraining-only figure reported for the 1B and 3B models. Pruning and teacher-logit distillation are part of their pretraining. Model card
- Post-training methods
- SFT, DPO The Instruct variant uses repeated SFT, rejection sampling, and DPO. These alignment stages apply to the instruct counterpart of the gallery's base configuration. Model card
Compare
Transparent dense model that keeps classic MHA and pushes normalization changes for training stability.
- Scale
- 7B parameters
- Context (tokens)
- 4,096
- License
- Apache License 2.0
- Date
- 2024-11-25
- Decoder type
- Dense
- Attention
- MHA with QK-Norm
- Layer mix
- 32 MHA
- KV cache / token (bf16) info
- 512 KiB · Very high
- Key detail
- Uses inside-residual post-norm instead of the usual pre-norm layout.
- Pretraining data
- 4.05T tokens per training branch 4T initial pretraining tokens, then three separate 50B-token mid-training branches whose weights are averaged. OLMo 2 technical report
- Post-training methods
- SFT, DPO, RLVR The 7B Instruct release follows the Tulu 3 pipeline of supervised fine-tuning, direct preference optimization, and verifiable-reward RL. OLMo 2 technical report
Compare
DeepSeek's flagship template kicked off the recent wave of large open MoE models.
- Scale
- 671B total, 37B active (5.5% active)
- Context (tokens)
- 128,000
- License
- DeepSeek License Agreement v1.0
- Date
- 2024-12-26
- Decoder type
- Sparse MoE
- Attention
- MLA
- Layer mix
- 61 MLA
- KV cache / token (bf16) info
- 68.6 KiB · Low
- Key detail
- Uses a dense prefix, shared expert, and MTP-1 objective to keep a very large model practical.
- Pretraining data
- 14.8T tokens Base pretraining budget, before post-training. DeepSeek V3 report
- Post-training methods
- SFT, RLVR, RL, Distillation SFT includes R1-generated reasoning data. GRPO combines rule-based math/code rewards with learned reward models. DeepSeek V3 report
Compare
Reasoning-tuned DeepSeek model built on the V3 architecture rather than a new base design.
- Scale
- 671B total, 37B active (5.5% active)
- Context (tokens)
- 128,000
- License
- MIT License
- Date
- 2025-01-20
- Decoder type
- Sparse MoE
- Attention
- MLA
- Layer mix
- 61 MLA
- KV cache / token (bf16) info
- 68.6 KiB · Low
- Key detail
- Architecture matches DeepSeek V3, including the MTP-1 path; the main change is the reasoning-oriented training recipe.
- Pretraining data
- 14.8T tokens (inherited base) R1 starts from DeepSeek V3 Base; this is the base pretraining count, excluding R1 post-training. DeepSeek V3 report · DeepSeek R1 report
- Post-training methods
- SFT, RLVR, RLHF Cold-start SFT, reasoning GRPO, rejection-sampling SFT, then RL with verifiable rewards and human-preference reward models. DeepSeek R1 report
Compare
Gemma's flagship text stack leans on local attention more aggressively than Gemma 2.
- Scale
- 27B parameters
- Context (tokens)
- 128,000
- Vocabulary
- 262,144 (~262k)
- License
- Gemma Terms of Use + Gemma Prohibited Use Policy
- Date
- 2025-03-11
- Decoder type
- Dense
- Attention
- GQA with QK-Norm and 5:1 sliding-window/global attention
- Layer mix
- 52 sliding-window + 10 global
- KV cache / token (bf16) info
- 496 KiB · Very high
- Key detail
- Built around a 27B sweet spot with heavier local attention and a large 262k multilingual vocabulary.
- Pretraining data
- 14T tokens Includes text and image data; pretraining uses knowledge distillation. Gemma 3 report
- Post-training methods
- Distillation, RLHF, RLVR IT checkpoint uses teacher distillation and RL with human-feedback reward models, code execution, and math ground truth. Gemma 3 report
Compare
Fast dense 24B model that drops the sliding-window setup used in older Mistral releases.
- Scale
- 24B parameters
- Context (tokens)
- 128,000
- License
- Apache License 2.0
- Date
- 2025-03-18
- Decoder type
- Dense
- Attention
- Standard GQA
- Layer mix
- 40 GQA
- KV cache / token (bf16) info
- 160 KiB · Moderate
- Key detail
- Latency-focused design with a smaller KV cache and fewer layers than Gemma 3 27B.
- Pretraining data
- Not disclosed No pretraining-token total is given for this version. Mistral Small 3.1 Instruct model card
- Post-training methods
- Instruction tuning The released Instruct counterpart is instruction-tuned; the detailed supervised, preference, or RL recipe is not specified. Mistral Small 3.1 Instruct model card
Compare
Meta's large MoE follows the DeepSeek V3 playbook but with a more conventional attention stack.
- Scale
- 400B total, 17B active (4.3% active)
- Context (tokens)
- 1,000,000
- License
- Llama 4 Community License Agreement
- Date
- 2025-04-05
- Decoder type
- Sparse MoE
- Attention
- GQA with RoPE in chunked layers and NoPE in full-attention layers
- Layer mix
- 36 chunked + 12 full GQA
- KV cache / token (bf16) info
- 192 KiB · High
- Key detail
- Alternates dense and MoE blocks and uses fewer, larger experts than DeepSeek V3.
- Pretraining data
- ~22T tokens Pretraining-token count reported for Maverick, including its multimodal training data. Model card
- Post-training methods
- SFT, RL, DPO The Maverick Instruct recipe uses SFT, online RL, and a final lightweight DPO stage. Release post
Compare
Tiny current-generation Qwen model that trades width for more depth and a low memory footprint.
- Scale
- 0.6B parameters
- Context (tokens)
- 32,768
- License
- Apache License 2.0
- Date
- 2025-04-28
- Decoder type
- Dense
- Attention
- GQA
- Layer mix
- 28 GQA
- KV cache / token (bf16) info
- 112 KiB · Moderate
- Key detail
- Deeper than Llama 3.2 1B and unusually practical for local experiments and teaching.
- Pretraining data
- ≈36T tokens Family pretraining budget; excludes post-training. Qwen3 technical report
- Post-training methods
- SFT, Distillation Instruction/reasoning counterpart uses response-supervised and on-policy teacher distillation. Base checkpoints have no post-training. Qwen3 technical report
Compare
Large sparse Qwen variant that stays very close to DeepSeek V3 while removing the shared expert.
- Scale
- 235B total, 22B active (9.4% active)
- Context (tokens)
- 128,000
- License
- Apache License 2.0
- Date
- 2025-04-28
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm
- Layer mix
- 94 GQA
- KV cache / token (bf16) info
- 188 KiB · High
- Key detail
- High-capacity MoE design optimized for serving efficiency without a shared expert.
- Pretraining data
- ≈36T tokens Family pretraining budget; excludes post-training. Qwen3 technical report
- Post-training methods
- SFT, RLVR, RLHF Cold-start/fusion SFT, reasoning RL, and general RL with human-preference rewards. Qwen3 technical report
Compare
Small sparse Qwen3 model that sits close to GPT-OSS in active size but uses a deeper stack.
- Scale
- 30B total, 3B active (10% active)
- Context (tokens)
- 128,000
- License
- Apache License 2.0
- Date
- 2025-04-28
- Decoder type
- Sparse MoE
- Attention
- GQA
- Layer mix
- 48 GQA
- KV cache / token (bf16) info
- 96 KiB · Moderate
- Key detail
- Deeper, narrower MoE alternative to GPT-OSS without a shared expert.
- Pretraining data
- ≈36T tokens Family pretraining budget; excludes post-training. Qwen3 technical report
- Post-training methods
- SFT, Distillation Instruction/reasoning counterpart uses response-supervised and on-policy teacher distillation. Base checkpoints have no post-training. Qwen3 technical report
Compare
Large dense Qwen3 model that serves as the clearest like-for-like comparison for OLMo 3 32B.
- Scale
- 32B parameters
- Context (tokens)
- 128,000
- License
- Apache License 2.0
- Date
- 2025-04-28
- Decoder type
- Dense
- Attention
- GQA with QK-Norm
- Layer mix
- 64 GQA
- KV cache / token (bf16) info
- 256 KiB · High
- Key detail
- Reference dense Qwen stack with QK-Norm and 8 KV heads.
- Pretraining data
- ≈36T tokens Family pretraining budget; excludes post-training. Qwen3 technical report
- Post-training methods
- SFT, RLVR, RLHF Cold-start/fusion SFT, reasoning RL, and general RL with human-preference rewards. Qwen3 technical report
Compare
Mid-size dense Qwen3 model used here as a clean baseline against SmolLM3 and Tiny Aya.
- Scale
- 4B parameters
- Context (tokens)
- 32,768
- License
- Apache License 2.0
- Date
- 2025-04-28
- Decoder type
- Dense
- Attention
- GQA with QK-Norm
- Layer mix
- 36 GQA
- KV cache / token (bf16) info
- 144 KiB · Moderate
- Key detail
- Compact Qwen3 dense stack with QK-Norm and a 151k vocabulary.
- Pretraining data
- ≈36T tokens Family pretraining budget; excludes post-training. Qwen3 technical report
- Post-training methods
- SFT, Distillation Instruction/reasoning counterpart uses response-supervised and on-policy teacher distillation. Base checkpoints have no post-training. Qwen3 technical report
Compare
Dense Qwen3 baseline used here to show how little OLMo 3 changed the overall decoder recipe.
- Scale
- 8B parameters
- Context (tokens)
- 128,000
- License
- Apache License 2.0
- Date
- 2025-04-28
- Decoder type
- Dense
- Attention
- GQA with QK-Norm
- Layer mix
- 36 GQA
- KV cache / token (bf16) info
- 144 KiB · Moderate
- Key detail
- Reference Qwen3 dense stack with QK-Norm and 8 KV heads.
- Pretraining data
- ~36T tokens Reported Qwen3 pretraining budget. Technical report
- Post-training methods
- SFT, Distillation The 8B model uses off-policy response distillation followed by on-policy teacher-logit alignment. Technical report
Compare
Compact dense model that experiments with leaving out positional encodings in selected layers.
- Scale
- 3B parameters
- Context (tokens)
- 131,072
- License
- Apache License 2.0
- Date
- 2025-06-19
- Decoder type
- Dense
- Attention
- GQA with periodic NoPE layers
- Layer mix
- 36 GQA
- KV cache / token (bf16) info
- 72 KiB · Low
- Key detail
- Every fourth layer omits RoPE to test a NoPE-style cadence.
- Pretraining data
- 11.2T tokens Reported pretraining total; reasoning mid-training adds 140B tokens separately. Model card
- Post-training methods
- SFT, APO For SmolLM3-3B Instruct, SFT is followed by Anchored Preference Optimization and checkpoint merging. The linked Base checkpoint precedes these stages. Training recipe
Compare
Trillion-parameter Moonshot model that essentially scales the DeepSeek V3 recipe upward.
- Scale
- 1T total, 32B active (3.2% active)
- Context (tokens)
- 128,000
- License
- Modified MIT License
- Date
- 2025-07-10
- Decoder type
- Sparse MoE
- Attention
- MLA
- Layer mix
- 61 MLA
- KV cache / token (bf16) info
- 68.6 KiB · Low
- Key detail
- More experts and fewer MLA heads than DeepSeek V3.
- Pretraining data
- 15.5T tokens Total tokens used to pretrain the released Kimi K2 base. Technical report
- Post-training methods
- SFT, RLVR Kimi-K2-Instruct uses SFT and RL with verifiable rewards, plus self-critique rubric rewards for open-ended tasks. The gallery architecture is shared with the base model. Technical report
Compare
Agent-oriented instruction/reasoning hybrid that borrows DeepSeek's dense-prefix MoE layout.
- Scale
- 355B total, 32B active (9% active)
- Context (tokens)
- 128,000
- License
- MIT License
- Date
- 2025-07-28
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm
- Layer mix
- 92 GQA
- KV cache / token (bf16) info
- 368 KiB · Very high
- Key detail
- Starts with three dense layers before MoE routing, keeps a shared expert, and uses MTP during training.
- Pretraining data
- 23T tokens Combined pretraining and mid-training budget. GLM-4.5 report
- Post-training methods
- SFT, RLVR, RLHF, RLAIF, Distillation SFT and expert RL cover reasoning, agents, and chat; expert capabilities are distilled into the final model. GLM-4.5 report
Compare
Larger gpt-oss variant keeps the same alternating-attention recipe as the 20B model.
- Scale
- 117B total, 5.1B active (4.4% active)
- Context (tokens)
- 128,000
- License
- Apache License 2.0
- Date
- 2025-08-04
- Decoder type
- Sparse MoE
- Attention
- GQA with alternating sliding-window and global layers
- Layer mix
- 18 sliding-window + 18 global
- KV cache / token (bf16) info
- 72 KiB · Low
- Key detail
- Shared architectural template scaled up for OpenAI's flagship open-weight release.
- Pretraining data
- Trillions of tokens; exact count undisclosed Text-only pretraining; no per-model token total is published. gpt-oss model card
- Post-training methods
- SFT, RL SFT followed by high-compute reasoning and tool-use RL, with deliberative alignment and instruction-hierarchy training. gpt-oss release
Compare
OpenAI's smaller open-weight MoE model favors width and alternating local/global attention.
- Scale
- 21B total, 3.6B active (17.1% active)
- Context (tokens)
- 128,000
- License
- Apache License 2.0
- Date
- 2025-08-04
- Decoder type
- Sparse MoE
- Attention
- GQA with alternating sliding-window and global layers
- Layer mix
- 12 sliding-window + 12 global
- KV cache / token (bf16) info
- 48 KiB · Low
- Key detail
- Wider and shallower than Qwen3, with attention bias and sink mechanisms.
- Pretraining data
- Trillions of tokens; exact count undisclosed Text-only pretraining; no per-model token total is published. gpt-oss model card
- Post-training methods
- SFT, RL SFT followed by high-compute reasoning and tool-use RL, with deliberative alignment and instruction-hierarchy training. gpt-oss release
Compare
Tiny Gemma 3 variant that preserves the family's local-global attention recipe at a toy scale.
- Scale
- 270M parameters
- Context (tokens)
- 32,768
- Vocabulary
- 262,144 (~262k)
- License
- Gemma Terms of Use + Gemma Prohibited Use Policy
- Date
- 2025-08-14
- Decoder type
- Dense
- Attention
- Multi-query attention with QK-Norm and 5:1 sliding-window/global attention
- Layer mix
- 15 sliding-window + 3 global
- KV cache / token (bf16) info
- 18 KiB · Very low
- Key detail
- Keeps the Gemma 3 stack shape while shrinking down to 4 attention heads, a single KV head, and the same 262k vocabulary.
- Pretraining data
- 6T tokens Pretraining budget for the 270M model. Gemma 3 270M model card
- Post-training methods
- Instruction tuning An IT checkpoint accompanies the pretrained model; its specific alignment stages are not disclosed. Gemma 3 270M release
Compare
Rare production-model release that shows an older MoE style with fewer, larger experts.
- Scale
- 270B parameters
- Context (tokens)
- 131,072
- License
- Grok 2 Community License Agreement
- Date
- 2025-08-22
- Decoder type
- Sparse MoE
- Attention
- GQA
- Layer mix
- 64 GQA
- KV cache / token (bf16) info
- 256 KiB · High
- Key detail
- Adds an always-on SwiGLU path that effectively behaves like a shared expert.
- Pretraining data
- Not disclosed The released Grok 2 checkpoint does not publish its training-data size. Grok 2 model card
- Post-training methods
- Not disclosed The release is post-trained, but its model card does not specify SFT, DPO, or reward methods. Grok 2 model card
Compare
Efficiency-focused Qwen refresh that swaps standard attention for a DeltaNet-attention hybrid.
- Scale
- 80B total, 3B active (3.8% active)
- Context (tokens)
- 262,144
- License
- Apache License 2.0
- Date
- 2025-09-09
- Decoder type
- Sparse hybrid
- Attention
- 3:1 Gated DeltaNet and Gated Attention
- Layer mix
- 12 gated attention + 36 DeltaNet
- KV cache / token (bf16) info
- 24 KiB · Very low
- Key detail
- Adds many more experts, a shared expert, native 262k context, and MTP for speculative decoding.
- Pretraining data
- 15T tokens Base pretraining count reported for Qwen3-Next-80B-A3B. Model card
- Post-training methods
- RL The release describes RL for the Instruct and Thinking variants without detailing the full recipe. Release blog
Related concepts
Compare
MiniMax's flagship returns to full attention and looks like a leaner, sparser cousin of Qwen3.
- Scale
- 230B total, 10B active (4.3% active)
- Context (tokens)
- 196,608
- License
- Modified MIT License
- Date
- 2025-10-23
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm and partial RoPE
- Layer mix
- 62 GQA
- KV cache / token (bf16) info
- 248 KiB · High
- Key detail
- Uses per-layer QK-Norm, much sparser MoE routing than Qwen3, and MTP during training.
- Pretraining data
- 29.2T tokens (M2-series base) The series report gives 19.9T tokens in the constant phase and 9.3T in decay and context extension. It does not separate pretraining budgets by M2-series checkpoint. Technical report
- Post-training methods
- SFT, RLVR The M2-series recipe uses SFT and mixed-domain RL with executable task rewards, plus process and completion-time rewards. The recipe evolves across M2, M2.5, and M2.7. Technical report
Compare
Linear-attention hybrid that keeps a transformer backbone but replaces most full-attention layers.
- Scale
- 48B total, 3B active (6.3% active)
- Context (tokens)
- 1,000,000
- License
- MIT License
- Date
- 2025-10-30
- Decoder type
- Sparse hybrid
- Attention
- 3:1 Kimi Delta Attention and MLA
- Layer mix
- 7 MLA + 20 Kimi Delta Attention
- KV cache / token (bf16) info
- 7.9 KiB · Very low
- Key detail
- Uses NoPE in MLA layers, channel-wise KDA gating, and kernel-4 ShortConv preprocessing for Q, K, and V in KDA layers.
- Pretraining data
- 5.7T tokens Budget for the final released checkpoint; the report's 1.4T-token runs are architecture comparisons. Technical report
- Post-training methods
- SFT, RL The Instruct variant uses multi-stage SFT followed by RL on math, code, and STEM tasks, with concurrent supervised training to preserve general capabilities. Technical report
Related concepts
Compare
Scaled-up OLMo 3 keeps the same block design but moves to grouped-query attention.
- Scale
- 32B parameters
- Context (tokens)
- 65,536
- License
- Apache License 2.0
- Date
- 2025-11-20
- Decoder type
- Dense
- Attention
- GQA with QK-Norm and 3:1 sliding-window/global attention
- Layer mix
- 48 sliding-window + 16 global
- KV cache / token (bf16) info
- 256 KiB · High
- Key detail
- Keeps post-norm while scaling width and applying YaRN only on global layers.
- Pretraining data
- 5.7T tokens per training branch 5.5T initial pretraining tokens, two 100B-token mid-training branches merged together, then 100B context-extension tokens. Aggregate training across both branches is 5.8T. OLMo 3 32B base model card
- Post-training methods
- SFT, DPO, RLVR The 32B Think release uses supervised fine-tuning, direct preference optimization, and verifiable-reward RL. OLMo 3 32B Think model card
Compare
New transparent Allen AI model that keeps OLMo's post-norm flavor while modernizing context handling.
- Scale
- 7B parameters
- Context (tokens)
- 65,536
- License
- Apache License 2.0
- Date
- 2025-11-20
- Decoder type
- Dense
- Attention
- MHA with QK-Norm and 3:1 sliding-window/global attention
- Layer mix
- 24 sliding-window + 8 global
- KV cache / token (bf16) info
- 512 KiB · Very high
- Key detail
- Retains post-norm, keeps MHA, and applies YaRN only on global layers.
- Pretraining data
- 6.08T tokens 5.93T initial pretraining, 100B mid-training, and 50B context-extension tokens. The 7B model uses no branch merging. OLMo 3 7B base model card
- Post-training methods
- SFT, DPO, RLVR The released Think and Instruct counterparts use SFT, DPO, and RLVR. The Base checkpoint itself has no post-training. OLMo 3 7B base model card
Compare
DeepSeek's successor keeps the V3 template but adds sparse attention to cut long-context costs.
- Scale
- 671B total, 37B active (5.5% active)
- Context (tokens)
- 128,000
- License
- MIT License
- Date
- 2025-12-01
- Decoder type
- Sparse MoE
- Attention
- MLA with DeepSeek Sparse Attention
- Layer mix
- 61 MLA
- KV cache / token (bf16) info
- 68.6 KiB · Low
- Key detail
- Adds sparse attention while retaining the DeepSeek V3-style MTP path.
- Pretraining data
- 943.7B continued-training tokens + 2.1B indexer warm-up Additional DSA training from V3.1-Terminus. The report does not give a cumulative pretraining total. DeepSeek V3.2 report
- Post-training methods
- SFT, RLVR, RL, Distillation Specialist distillation and mixed GRPO; rule-based reasoning/agent rewards and rubric-based generative rewards. Tool-use cold start uses SFT. DeepSeek V3.2 report
Compare
Mistral's new flagship effectively adopts the DeepSeek architecture and retunes the expert sizes.
- Scale
- 673B total, 41B active (6.1% active)
- Context (tokens)
- 262,144
- License
- Apache License 2.0
- Date
- 2025-12-02
- Decoder type
- Sparse MoE
- Attention
- MLA
- Layer mix
- 61 MLA
- KV cache / token (bf16) info
- 68.6 KiB · Low
- Key detail
- Near-clone of DeepSeek V3 with larger experts, fewer routed experts, and multimodal support.
- Pretraining data
- Not disclosed The model card describes training from scratch but does not report a training-token total. Mistral Large 3 model card
- Post-training methods
- Instruction tuning The released model is instruction-tuned; the card does not specify its supervised, preference, or RL training stages. Mistral Large 3 model card
Compare
NVIDIA's Nano model is the most extreme transformer-state-space hybrid in the gallery.
- Scale
- 30B total, 3B active (10% active)
- Context (tokens)
- 1,000,000
- License
- NVIDIA Nemotron Open Model License
- Date
- 2025-12-04
- Decoder type
- Hybrid MoE
- Attention
- Mostly Mamba-2 with a few GQA layers using NoPE
- Layer mix
- 6 GQA + 23 Mamba-2 + 23 MoE
- KV cache / token (bf16) info
- 6 KiB · Very low
- Key detail
- Interleaves Mamba-2 and MoE blocks, using attention only sparingly.
- Pretraining data
- 25T + 121B long-context tokens The main pretraining run uses 25T tokens, followed by 121B tokens of long-context continued pretraining. Nemotron 3 Nano technical report
- Post-training methods
- SFT, RLVR, RLHF Supervised fine-tuning, multi-environment reinforcement learning with verifiable rewards, and human-feedback alignment. Nemotron 3 Nano technical report
Related concepts
Compare
Large MoE model that pushes sliding-window attention harder than most contemporaries.
- Scale
- 309B total, 15B active (4.9% active)
- Context (tokens)
- 262,144
- License
- MIT License
- Date
- 2025-12-16
- Decoder type
- Sparse MoE
- Attention
- 5:1 sliding-window/global attention
- Layer mix
- 40 sliding-window + 8 global
- KV cache / token (bf16) info
- 144 KiB · Moderate
- Key detail
- Uses an unusually small 128-token local window plus multi-token prediction.
- Pretraining data
- 27T tokens Reported pretraining budget. Model card
- Post-training methods
- SFT, RL, Distillation, RLVR SFT, domain-specialized RL, and multi-teacher on-policy distillation. Verifiable tasks use programmatic and LLM verification; subjective helpfulness and safety use rubric-based LLM rewards. Technical report
Compare
Immediate GLM predecessor that stays closer to the older GLM-4.5 style before the MLA shift.
- Scale
- 355B total, 32B active (9% active)
- Context (tokens)
- 202,752
- License
- MIT License
- Date
- 2025-12-22
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm
- Layer mix
- 92 GQA
- KV cache / token (bf16) info
- 368 KiB · Very high
- Key detail
- Serves as the pre-MLA, pre-sparse-attention baseline and uses an MTP-3-style setup.
- Pretraining data
- 23T tokens (inherited GLM-4.5 base) The team confirms GLM-4.5, 4.6, and 4.7 share a base model; 23T is its pretraining and mid-training budget. GLM-4.5 report · GLM team AMA
- Post-training methods
- SFT, RL Reprocessed SFT data followed by RL using the slime framework; the full reward recipe is not specified. GLM team AMA
Compare
Arcee's flagship blends several efficiency tricks into a DeepSeek-like coarse MoE design; the AA score shown here refers to the Trinity Large Thinking checkpoint.
- Scale
- 400B total, 13B active (3.3% active)
- Context (tokens)
- 512,000
- License
- Apache License 2.0
- Date
- 2026-01-27
- Decoder type
- Sparse MoE
- Attention
- GQA with gated attention and 3:1 sliding-window/global attention
- Layer mix
- 45 sliding-window + 15 global
- KV cache / token (bf16) info
- 240 KiB · High
- Key detail
- Combines QK-Norm, RoPE+NoPE, sandwich norm, and a coarse-grained MoE.
- Pretraining data
- 17T tokens Full Base checkpoint, including its mid-training anneals; the earlier TrueBase checkpoint used 10T. Trinity Large report · Trinity Large Thinking model card
- Post-training methods
- SFT, RL Preview uses SFT; the later Thinking checkpoint adds instruction tuning and agentic RL. Trinity Large report · Trinity Large Thinking model card
Compare
Huge GLM refresh that adopts both MLA and DeepSeek Sparse Attention for flagship-scale inference.
- Scale
- 744B total, 40B active (5.4% active)
- Context (tokens)
- 202,752
- License
- MIT License
- Date
- 2026-02-11
- Decoder type
- Sparse MoE
- Attention
- MLA with DeepSeek Sparse Attention
- Layer mix
- 78 MLA
- KV cache / token (bf16) info
- 87.8 KiB · Moderate
- Key detail
- Bigger than GLM-4.7, with more experts, fewer layers, and DeepSeek-style MTP.
- Pretraining data
- 28.5T tokens Combined pretraining and mid-training budget for the base model. GLM-5 report
- Post-training methods
- SFT, RLVR, RL, Distillation SFT, reasoning/agentic/general RL, and on-policy cross-stage distillation. General RL combines rule-based and model-based rewards. GLM-5 report
Compare
The Super variant scales up Nano and adds both latent experts and native speculative decoding support.
- Scale
- 120B total, 12B active (10% active)
- Context (tokens)
- 1,000,000
- License
- NVIDIA Nemotron Open Model License
- Date
- 2026-03-11
- Decoder type
- Hybrid MoE
- Attention
- Mostly Mamba-2 with a few GQA layers using NoPE
- Layer mix
- 8 GQA + 40 Mamba-2 + 40 MoE
- KV cache / token (bf16) info
- 8 KiB · Very low
- Key detail
- Adds latent-space MoE and shared-weight MTP for fast inference.
- Pretraining data
- 25T + 51B long-context tokens The main pretraining run uses 25T tokens. Two context-extension phases add 34B and 17B tokens. Nemotron 3 Super technical report
- Post-training methods
- SFT, RLVR, RLHF Supervised fine-tuning, multi-environment and software-engineering RL with verifiable rewards, then human-feedback alignment. Nemotron 3 Super technical report
Compare
Dense Gemma 4 scales the family to a 256K-context multimodal checkpoint without changing the core local-global recipe much.
- Scale
- 30.7B parameters
- Context (tokens)
- 256,000
- Vocabulary
- 262,144 (~262k)
- License
- Apache License 2.0
- Date
- 2026-04-02
- Decoder type
- Dense
- Attention
- GQA with QK-Norm, unified K/V on global layers, p-RoPE on global layers, and 5:1 sliding-window/global attention
- Layer mix
- 50 sliding-window + 10 global
- KV cache / token (bf16) info
- 840 KiB · Very high
- Key detail
- Carries Gemma's unusual pre/post-norm stack into a larger 31B dense model with 256K context.
- Pretraining data
- Not disclosed No per-model pretraining-token count is published. Gemma 4 model card
- Post-training methods
- Instruction tuning IT variant; the report refers to Gemma 3-like post-training without itemizing alignment stages. Gemma 4 report
Compare
Sparse Gemma 4 variant that keeps the local:global attention backbone while swapping dense FFNs for MoE layers.
- Scale
- 25.2B total, 3.8B active (15.1% active)
- Context (tokens)
- 256,000
- Vocabulary
- 262,144 (~262k)
- License
- Apache License 2.0
- Date
- 2026-04-02
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm, unified K/V on global layers, p-RoPE on global layers, and 5:1 sliding-window/global attention
- Layer mix
- 25 sliding-window + 5 global
- KV cache / token (bf16) info
- 210 KiB · High
- Key detail
- Uses 128 total experts with only 8 routed plus 1 shared expert active per token.
- Pretraining data
- Not disclosed No per-model pretraining-token count is published. Gemma 4 model card
- Post-training methods
- Instruction tuning IT variant; the report refers to Gemma 3-like post-training without itemizing alignment stages. Gemma 4 report
Compare
Dense Gemma 4 12B Unified uses an encoder-free multimodal input path, while its text decoder keeps the 31B-style local-global attention recipe.
- Scale
- 12B parameters
- Context (tokens)
- 262,144
- Vocabulary
- 262,144 (~262k)
- License
- Apache License 2.0
- Date
- 2026-06-03
- Decoder type
- Dense
- Attention
- GQA with QK-Norm, unified K/V on global layers, p-RoPE on global layers, and 5:1 sliding-window/global attention
- Layer mix
- 40 sliding-window + 8 global
- KV cache / token (bf16) info
- 328 KiB · Very high
- Key detail
- Figure shows the 48-layer text decoder; the full 12B Unified model also projects audio, image, and video inputs directly into the decoder input stream.
- Pretraining data
- Not disclosed No per-model pretraining-token count is published. Gemma 4 model card
- Post-training methods
- Instruction tuning IT variant; the report refers to Gemma 3-like post-training without itemizing alignment stages. Gemma 4 report
Compare
Small Llama baseline used to show how closely Nanbeige follows the mainstream compact decoder recipe.
- Scale
- 3B parameters
- Context (tokens)
- 128,000
- License
- Llama 3.2 Community License Agreement
- Date
- 2024-09-25
- Decoder type
- Dense
- Attention
- GQA
- Layer mix
- 28 GQA
- KV cache / token (bf16) info
- 112 KiB · Moderate
- Key detail
- Reference small-model Llama architecture with tied embeddings.
- Pretraining data
- Up to 9T tokens Pretraining-only figure reported for the 1B and 3B models. Pruning and teacher-logit distillation are part of their pretraining. Model card
- Post-training methods
- SFT, DPO The Instruct variant uses repeated SFT, rejection sampling, and DPO. These alignment stages apply to the instruct counterpart of the gallery's base configuration. Model card
Compare
Coding-tuned Qwen model that keeps a straightforward grouped-query MoE stack instead of the newer hybrid-attention variants.
- Scale
- 30B total, 3.3B active (11% active)
- Context (tokens)
- 256,000
- License
- Apache License 2.0
- Date
- 2025-07-31
- Decoder type
- Sparse MoE
- Attention
- GQA
- Layer mix
- 48 GQA
- KV cache / token (bf16) info
- 96 KiB · Moderate
- Key detail
- Uses 128 experts with 8 active per token and a native 256k context window for coding workloads.
- Pretraining data
- Not disclosed The 30B card omits a token count. The 7.5T figure in the initial Coder release describes the 480B model. Model card · Coder release
- Post-training methods
- Not disclosed The 30B card confirms post-training but does not give a separate method breakdown. Model card
Compare
Native-multimodal Moonshot flagship that keeps the K2/DeepSeek-style MoE layout and pushes native context to 256k.
- Scale
- 1T total, 32B active (3.2% active)
- Context (tokens)
- 256,000
- License
- Modified MIT License
- Date
- 2026-01-27
- Decoder type
- Sparse MoE
- Attention
- MLA
- Layer mix
- 61 MLA
- KV cache / token (bf16) info
- 68.6 KiB · Low
- Key detail
- Keeps the 384-expert K2 backbone, but adds multimodal capabilities (not shown) and doubles the native context length.
- Pretraining data
- ~15T additional tokens Continued pretraining from Kimi K2 on a mixed visual and text corpus; this excludes K2's earlier pretraining. Technical report
- Post-training methods
- SFT, RLVR SFT and RL combine verifiable outcome rewards with generative reward models. Parallel-agent RL trains the orchestrator to delegate work. Technical report
Compare
Throughput-oriented MoE model that stays competitive with much larger DeepSeek-style systems.
- Scale
- 196B total, 11B active (5.6% active)
- Context (tokens)
- 262,144
- License
- Apache License 2.0
- Date
- 2026-02-01
- Decoder type
- Sparse MoE
- Attention
- GQA with 3:1 sliding-window attention
- Layer mix
- 36 sliding-window + 12 global
- KV cache / token (bf16) info
- 192 KiB · High
- Key detail
- Uses MTP-3 during both training and inference for unusually high throughput.
- Pretraining data
- ~17.6T tokens + 750B mid-training tokens Section 4.2 gives 14.6T + 3T pretraining tokens. The introduction's 17.2T figure conflicts with that detailed schedule. Technical report
- Post-training methods
- SFT, RLVR, RLHF, Distillation Two-stage SFT, domain RL with verifiable and human-preference rewards, and self-distillation. Technical report
Compare
Small on-device oriented model that stays close to Llama 3.2 while nudging the scaling choices.
- Scale
- 3B parameters
- Context (tokens)
- 262,144
- License
- Apache License 2.0
- Date
- 2026-02-10
- Decoder type
- Dense
- Attention
- GQA
- Layer mix
- 32 GQA
- KV cache / token (bf16) info
- 64 KiB · Low
- Key detail
- Llama-like stack without tying input embeddings to the output layer.
- Pretraining data
- 23T tokens (inherited base) Uses Nanbeige4-3B-Base, whose four pretraining phases total 23T tokens. The 4.1 release adds post-training. Nanbeige 4 base model card · Nanbeige 4.1 technical report
- Post-training methods
- SFT, RLHF, RLVR SFT, human-preference reward-model RL, pairwise RL, and reasoning/code RL with executable correctness checks. Nanbeige 4.1 technical report
Compare
Popular 230B coder that opts for a classic architecture instead of the newer hybrid-attention ideas.
- Scale
- 230B total, 10B active (4.3% active)
- Context (tokens)
- 196,608
- License
- Modified MIT License
- Date
- 2026-02-12
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm
- Layer mix
- 62 GQA
- KV cache / token (bf16) info
- 248 KiB · High
- Key detail
- Deliberately avoids sliding-window or linear-attention hybrids while keeping a 10B active path and three MTP modules.
- Pretraining data
- 29.2T tokens (M2-series base) The series report gives 19.9T tokens in the constant phase and 9.3T in decay and context extension. It does not separate pretraining budgets by M2-series checkpoint. Technical report
- Post-training methods
- SFT, RLVR The M2-series recipe uses SFT and mixed-domain RL with executable task rewards, plus process and completion-time rewards. The recipe evolves across M2, M2.5, and M2.7. Technical report
Compare
Compact multilingual model from Cohere with a rare parallel transformer block.
- Scale
- 3.35B parameters
- Context (tokens)
- 8,192
- License
- Creative Commons Attribution-NonCommercial 4.0
- Date
- 2026-02-13
- Decoder type
- Dense
- Attention
- GQA with 3:1 sliding-window attention
- Layer mix
- 27 sliding-window + 9 global
- KV cache / token (bf16) info
- 72 KiB · Low
- Key detail
- Runs attention and the MLP in parallel while mixing RoPE with NoPE.
- Pretraining data
- 6T tokens Pretraining budget for Tiny Aya Base. Technical report
- Post-training methods
- SFT, Preference tuning, Model merging Global and regional variants add SFT; Global adds minimal preference tuning, and regional releases merge checkpoints. Tiny Aya Base precedes these stages. Technical report
Compare
Trillion-parameter long-context model that swaps DeltaNet for Lightning Attention.
- Scale
- 1T total, 63B active (6.3% active)
- Context (tokens)
- 256,000
- License
- MIT License
- Date
- 2026-02-15
- Decoder type
- Sparse hybrid
- Attention
- Lightning Attention plus MLA
- Layer mix
- 10 MLA + 70 Lightning Attention
- KV cache / token (bf16) info
- 11.2 KiB · Very low
- Key detail
- Uses a 7:1 linear-attention/MLA ratio and a much larger 63B active path.
- Pretraining data
- 9T additional tokens Continued pretraining after retrofitting the Ling 2.0 base. The card separately describes a pretraining corpus expanded from 20T to 29T tokens. Model card
- Post-training methods
- RL Reported methods include correctness and redundancy rewards, bidirectional RL feedback, and agentic RL in interactive environments. Model card
Related concepts
Compare
Mainline Qwen refresh that brings the Next-style hybrid attention into the flagship series.
- Scale
- 397B total, 17B active (4.3% active)
- Context (tokens)
- 262,144
- License
- Apache License 2.0
- Date
- 2026-02-16
- Decoder type
- Sparse hybrid
- Attention
- 3:1 Gated DeltaNet and Gated Attention
- Layer mix
- 15 gated attention + 45 DeltaNet
- KV cache / token (bf16) info
- 30 KiB · Low
- Key detail
- Turns the former Qwen3-Next side branch into the new core design with 512 experts and 17B active parameters.
- Pretraining data
- Not disclosed The model card describes multimodal pretraining without a token total. Model card
- Post-training methods
- RL Large-scale RL across agent environments is confirmed; the card does not specify all post-training stages. Model card
Related concepts
Compare
Reasoning-oriented Indian-language sparse MoE that keeps GQA at the smaller size.
- Scale
- 30B total, 2.4B active (8% active)
- Context (tokens)
- 131,072
- License
- Apache License 2.0
- Date
- 2026-03-03
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm
- Layer mix
- 19 GQA
- KV cache / token (bf16) info
- 19 KiB · Very low
- Key detail
- Large vocabulary and strong Indic language support paired with a reasoning-focused sparse MoE design.
- Pretraining data
- 16T tokens Reported pretraining budget. Training overview
- Post-training methods
- SFT, RLVR RL combines verifiable outcomes with rubric-based rewards, using asynchronous group-relative optimization. Training overview
Compare
Larger Sarvam variant keeps the sparse MoE layout but switches from GQA to MLA.
- Scale
- 105B total, 10.3B active (9.8% active)
- Context (tokens)
- 131,072
- License
- Apache License 2.0
- Date
- 2026-03-03
- Decoder type
- Sparse MoE
- Attention
- MLA with KV LayerNorm and NoPE + RoPE
- Layer mix
- 32 MLA
- KV cache / token (bf16) info
- 36 KiB · Low
- Key detail
- Large vocabulary and strong Indic language support carried into the larger MLA-based sparse MoE variant.
- Pretraining data
- 12T tokens Reported pretraining budget. Training overview
- Post-training methods
- SFT, RLVR RL combines verifiable outcomes with rubric-based rewards, using asynchronous group-relative optimization. Training overview
Compare
Microsoft's 14B dense Phi refresh stays close to Phi-3-medium but swaps its sliding-window attention for full-context GQA and a larger tokenizer.
- Scale
- 14B parameters
- Context (tokens)
- 16,384
- License
- MIT License
- Date
- 2024-12-12
- Decoder type
- Dense
- Attention
- GQA with RoPE
- Layer mix
- 40 GQA
- KV cache / token (bf16) info
- 200 KiB · High
- Key detail
- Classic pre-norm RMSNorm stack with GQA, 40 heads, 10 KV heads, and a 100,352-token vocabulary.
- Pretraining data
- 9.8T tokens The model card reports 9.8T training tokens. Phi-4 model card
- Post-training methods
- SFT, DPO Supervised fine-tuning followed by pivotal-token and judge-guided DPO stages. Phi-4 technical report
Compare
Recurrent 7B language model that replaces self-attention with xLSTM blocks built around matrix memory.
- Scale
- 7B parameters
- Context (tokens)
- No explicit limit
- License
- NXAI Community License Agreement
- Date
- 2025-03-17
- Decoder type
- Recurrent
- Attention
- No self-attention; mLSTM recurrent layers with matrix memory
- Layer mix
- 32 mLSTM
- KV cache / token (bf16) info
- 0 B · No cache
- Key detail
- Stateful recurrent architecture aimed at fast long-context inference without an explicit context window.
- Pretraining data
- ~2.3T tokens DCLM and selected high-quality data. Model card
- Post-training methods
- None (base model) The linked xLSTM-7b release is a pretrained completion model. Model card
Related concepts
Compare
Compact GLM-4.5 companion that keeps the same agent-oriented sparse MoE recipe at a smaller serving footprint.
- Scale
- 106B total, 12B active (11.3% active)
- Context (tokens)
- 128,000
- License
- MIT License
- Date
- 2025-07-28
- Decoder type
- Sparse MoE
- Attention
- GQA
- Layer mix
- 46 GQA
- KV cache / token (bf16) info
- 184 KiB · High
- Key detail
- Shrinks the GLM-4.5 layout to 46 layers, keeps the dense warmup, and inherits the MTP training recipe.
- Pretraining data
- Not disclosed The report gives 23T tokens for GLM-4.5 but does not separately establish Air's budget. GLM-4.5 report
- Post-training methods
- SFT, RLVR, RLHF, RLAIF, Distillation The series recipe combines SFT, expert RL with rule-based, human, and AI feedback, and expert distillation. GLM-4.5 report
Compare
ByteDance's dense LoopLM reuses one 48-layer MHA stack across four recurrent passes and trains an exit gate over the intermediate representations.
- Scale
- 2.6B parameters
- Context (tokens)
- 65,536
- Vocabulary
- 49,152 (~49k)
- License
- Apache License 2.0
- Date
- 2025-10-29
- Decoder type
- Dense
- Attention
- MHA with RoPE
- Layer mix
- 48 shared MHA layers × 4 passes
- KV cache / token (bf16) info
- 1.5 MiB · Very high
- Key detail
- Reuses the same 48-layer MHA stack across four passes, yielding 192 block applications, with sandwich RMSNorm and a learned exit gate.
- Pretraining data
- ≈7.7T tokens The report's rounded total covers initial pretraining, continued training, context extension, and mid-training before reasoning SFT. Ouro technical report
- Post-training methods
- SFT Reasoning SFT on approximately 8.3M examples produces the Thinking release. Separate exploratory RLVR runs did not outperform the final SFT checkpoint. Ouro technical report
Related concepts
Compare
Large-scale RL post-training of GLM-4.5-Air that keeps the compact 106B sparse MoE backbone intact.
- Scale
- 106B total, 12B active (11.3% active)
- Context (tokens)
- 128,000
- License
- MIT License
- Date
- 2025-11-26
- Decoder type
- Sparse MoE
- Attention
- GQA
- Layer mix
- 46 GQA
- KV cache / token (bf16) info
- 184 KiB · High
- Key detail
- Keeps the GLM-4.5-Air architecture unchanged and shifts the capability profile through SFT plus large-scale RL.
- Pretraining data
- Not disclosed Post-trained from GLM-4.5-Air-Base. A pretraining-token total for that Air base is not disclosed in the checked sources. Technical report · Model card
- Post-training methods
- SFT, RLVR Two SFT phases are followed by large-scale RL with verifiable rewards across reasoning and agentic tasks. Technical report
Compare
Meituan's LongCat-Next text backbone is a lightweight MoE that shifts a large share of parameters into N-gram embeddings while keeping sparse inference around 3B active parameters.
- Scale
- 68.5B total, ~3B active avg (4.4% active)
- Context (tokens)
- 256,000
- Vocabulary
- 131,072
- License
- MIT License
- Date
- 2026-01-28
- Decoder type
- Sparse MoE
- Attention
- MLA with RoPE + NoPE
- Layer mix
- 14 logical layers / 28 MLA sublayers
- KV cache / token (bf16) info
- 31.5 KiB · Low
- Key detail
- Uses N-gram embedding expansion, Shortcut MoE routing over 256 routed plus 128 zero/identity experts, and top-k 12 expert choices per token.
- Pretraining data
- 11T + 1.5T midtraining tokens 11T tokens of initial pretraining are followed by 1.5T tokens of midtraining and context extension, for 12.5T before SFT. Technical report
- Post-training methods
- SFT The report states that the released chat model is supervised fine-tuned after pretraining and midtraining. Technical report
Compare
Multimodal Mistral Small refresh that jumps from the older dense 24B stack to an MLA-based sparse MoE design.
- Scale
- 119B total, 6.63B active (5.6% active)
- Context (tokens)
- 256,000
- License
- Apache License 2.0
- Date
- 2026-03-16
- Decoder type
- Sparse MoE
- Attention
- MLA
- Layer mix
- 36 MLA
- KV cache / token (bf16) info
- 22.5 KiB · Very low
- Key detail
- Uses 128 experts with 4 routed plus 1 shared expert active per token while unifying instruct, reasoning, and vision.
- Pretraining data
- Not disclosed The model card does not report the pretraining-token total. Mistral Small 4 model card
- Post-training methods
- Not disclosed The model card describes hybrid reasoning and instruction following but does not identify the post-training methods. Mistral Small 4 model card
Compare
Compact on-device hybrid that compresses Nemotron Nano 9B v2 into a mostly Mamba-2 stack with only four attention layers.
- Scale
- 4B parameters
- Context (tokens)
- 262,144
- License
- NVIDIA Nemotron Open Model License
- Date
- 2026-03-16
- Decoder type
- Dense hybrid
- Attention
- GQA with NoPE in 4 attention layers
- Layer mix
- 4 GQA + 21 Mamba-2 + 17 FFN
- KV cache / token (bf16) info
- 16 KiB · Very low
- Key detail
- Uses a 42-layer stack with 21 Mamba-2 blocks, 17 ReLU² FFNs, and just 4 GQA layers.
- Pretraining data
- 213B recovery-distillation tokens Compressed from Nano 9B v2, descended from a 20T-token pretrained 12B model. The 4B recovery stages use 63B and 150B tokens; this is additional recovery training, not a from-scratch pretraining total. NVIDIA Nano 4B training details · NVIDIA Nemotron Nano 2 technical report
- Post-training methods
- Distillation, SFT, RLVR Compression recovery distillation, two SFT stages, and three RLVR stages for instruction following and tool use. NVIDIA Nano 4B training details
Related concepts
Compare
Agent-focused 230B follow-up built for self-evolution, agent harnesses, and productivity workflows.
- Scale
- 230B total, 10B active (4.3% active)
- Context (tokens)
- 204,800
- License
- MiniMax M2.7 Non-Commercial License
- Date
- 2026-03-18
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm
- Layer mix
- 62 GQA
- KV cache / token (bf16) info
- 248 KiB · High
- Key detail
- Keeps the M2.5-style 62-layer sparse MoE stack and adds three MTP modules for speculative decoding support.
- Pretraining data
- 29.2T tokens (M2-series base) The shared base recipe uses 19.9T constant-phase and 9.3T decay/long-context tokens. Separate budgets for M2, M2.5, and M2.7 are not given. MiniMax M2 series technical report
- Post-training methods
- SFT, RLVR Supervised fine-tuning and multi-domain RL, including executable verification for coding and agent tasks. Other domains also use learned rewards. MiniMax M2 series technical report
Compare
Smallest Gemma 4 edge model keeps the family's hybrid attention stack and adds native audio on a phone-scale multimodal footprint. Uses per-layer embeddings, which add small layer-specific token vectors without scaling the full compute path, so its compute footprint is closer to 2.3B than a full 5.1B dense model.
- Scale
- 5.1B parameters (2.3B effective)
- Context (tokens)
- 128,000
- Vocabulary
- 262,144 (~262k)
- License
- Apache License 2.0
- Date
- 2026-04-02
- Decoder type
- Dense
- Attention
- Multi-query attention with QK-Norm, unified K/V on global layers, p-RoPE on global layers, and 4:1 sliding-window/global attention
- Layer mix
- 28 sliding-window + 7 global
- KV cache / token (bf16) info
- 35 KiB · Low
- Key detail
- Uses a double-wide GELU MLP plus a single KV head to stay light enough for offline edge deployments.
- Pretraining data
- Not disclosed No per-model pretraining-token count is published. Gemma 4 model card
- Post-training methods
- Instruction tuning IT variant; the report refers to Gemma 3-like post-training without itemizing alignment stages. Gemma 4 report
Compare
Larger Gemma 4 edge variant keeps the same multimodal hybrid recipe but doubles width and KV heads for a stronger 128K mobile checkpoint. Uses per-layer embeddings, which add small layer-specific token vectors without scaling the full compute path, so its compute footprint is closer to 4.5B than a full 8B dense model.
- Scale
- 8B parameters (4.5B effective)
- Context (tokens)
- 128,000
- Vocabulary
- 262,144 (~262k)
- License
- Apache License 2.0
- Date
- 2026-04-02
- Decoder type
- Dense
- Attention
- GQA with QK-Norm, unified K/V on global layers, p-RoPE on global layers, and 5:1 sliding-window/global attention
- Layer mix
- 35 sliding-window + 7 global
- KV cache / token (bf16) info
- 84 KiB · Moderate
- Key detail
- Steps up to a 42-layer stack with 2 KV heads while keeping the same edge-oriented local/global template.
- Pretraining data
- Not disclosed No per-model pretraining-token count is published. Gemma 4 model card
- Post-training methods
- Instruction tuning IT variant; the report refers to Gemma 3-like post-training without itemizing alignment stages. Gemma 4 report
Compare
DeepSeek's efficient V4 preview keeps the million-token architecture while reducing the MoE scale to 284B parameters and 13B active parameters.
- Scale
- 284B total, 13B active (4.6% active)
- Context (tokens)
- 1,048,576
- License
- MIT License
- Date
- 2026-04-24
- Decoder type
- Sparse MoE
- Attention
- MLA-style CSA/HCA with mHC
- Layer mix
- 43 CSA/HCA
- KV cache / token (bf16) info
- 5.4 KiB · Very low
- Key detail
- Uses 256 experts, 6 routed plus 1 shared expert per token, hash-based routing, compressed attention, and the V4 MTP path.
- Pretraining data
- 32T tokens Includes staged context extension to 1M tokens. DeepSeek V4 report
- Post-training methods
- SFT, RLVR, RL, Distillation Domain experts receive SFT and GRPO, using verifiers and generative rewards, then are combined through on-policy distillation. DeepSeek V4 report
Compare
DeepSeek's flagship V4 preview scales to 1.6T parameters and introduces compressed sparse attention plus manifold-constrained hyper-connections for million-token contexts.
- Scale
- 1.6T total, 49B active (3.1% active)
- Context (tokens)
- 1,048,576
- License
- MIT License
- Date
- 2026-04-24
- Decoder type
- Sparse MoE
- Attention
- MLA-style CSA/HCA with mHC
- Layer mix
- 61 CSA/HCA
- KV cache / token (bf16) info
- 7.7 KiB · Very low
- Key detail
- Uses 384 experts, 6 routed plus 1 shared expert per token, hash-based routing, compressed attention caches, and the V4 MTP path.
- Pretraining data
- 33T tokens Includes staged context extension to 1M tokens. DeepSeek V4 report
- Post-training methods
- SFT, RLVR, RL, Distillation Domain experts receive SFT and GRPO, using verifiers and generative rewards, then are combined through on-policy distillation. DeepSeek V4 report
Compare
Poolside's open-weight agentic coding MoE uses mixed sliding-window/global attention and activates only 3B of 33B parameters per token.
- Scale
- 33B total, 3B active (9.1% active)
- Context (tokens)
- 262,144
- License
- Apache License 2.0
- Date
- 2026-04-28
- Decoder type
- Sparse MoE
- Attention
- Gated GQA with QK-Norm and 3:1 sliding-window/global attention
- Layer mix
- 30 sliding-window + 10 global
- KV cache / token (bf16) info
- 160 KiB · Moderate
- Key detail
- Uses per-layer query-head counts, a 512-token SWA window, sigmoid MoE routing, and one shared expert alongside the top-8 routed experts.
- Pretraining data
- >30T tokens Pretraining tokens seen, sampled from a pool of about 27T unique tokens. The corpus size and training budget are different quantities. Technical report
- Post-training methods
- SFT, RLVR Supervised instruction tuning is followed by reinforcement learning with verifiable rewards using CISPO. Technical report
Compare
Zyphra's compact reasoning MoE pairs CCA/GQA attention updates with top-1 routed expert FFN updates to keep fewer than 1B parameters active per token.
- Scale
- 8.4B total, 760M active/token (9% active)
- Context (tokens)
- 131,072
- Vocabulary
- 262,272
- License
- Apache License 2.0
- Date
- 2026-05-06
- Decoder type
- Sparse MoE
- Attention
- CCA with 4:1 GQA, RoPE, and Q/K L2 norm
- Layer mix
- 40 CCA/GQA attention + 40 top-1 MoE FFN entries
- KV cache / token (bf16) info
- 40 KiB · Low
- Key detail
- Key detail is CCA/GQA attention, which performs attention in a compressed latent space while keeping a 4:1 GQA layout. Sidenote: the config lists 80 alternating layer entries, equivalent to 40 CCA/GQA attention updates paired with 40 top-1 MoE FFN updates.
- Pretraining data
- 12T tokens + 1.2T mid-training tokens Base phases consume 8T + 4T; 32K mid-training adds 1.2T. The separate SFT stage consumes 660B tokens. Technical report
- Post-training methods
- SFT, RLVR, RLHF SFT, three verifiable reasoning RL stages, then behavioral RLHF for chat and instruction following. Technical report
Compare
Post-trained GLM refresh that keeps the GLM-5 backbone intact but targets stronger long-horizon agentic coding.
- Scale
- 744B total, 40B active (5.4% active)
- Context (tokens)
- 202,752
- License
- MIT License
- Date
- 2026-04-07
- Decoder type
- Sparse MoE
- Attention
- MLA with DeepSeek Sparse Attention
- Layer mix
- 78 MLA
- KV cache / token (bf16) info
- 87.8 KiB · Moderate
- Key detail
- Architecture stays aligned with GLM-5, including its MTP-capable backbone; the main shift is post-training.
- Pretraining data
- Not disclosed The official model card does not give a version-specific pretraining-token total. GLM-5.1 model card
- Post-training methods
- Not disclosed The official model card and documentation do not itemize version-specific training stages. GLM-5.1 documentation
Compare
Compact Qwen3.6 open-weight MoE that keeps the Qwen3.5 hybrid Gated DeltaNet/Gated Attention recipe while activating only about 3B parameters.
- Scale
- 35B total, 3B active (8.6% active)
- Context (tokens)
- 262,144
- License
- Apache License 2.0
- Date
- 2026-04-15
- Decoder type
- Sparse hybrid
- Attention
- 3:1 Gated DeltaNet and Gated Attention
- Layer mix
- 10 gated attention + 30 DeltaNet
- KV cache / token (bf16) info
- 20 KiB · Very low
- Key detail
- Uses 256 experts with 8 routed plus 1 shared expert active inside a 40-layer hybrid stack.
- Pretraining data
- Not disclosed The model card does not report the pretraining token count. Model card
- Post-training methods
- Not disclosed The card identifies a post-trained checkpoint without naming the methods. Model card
Related concepts
Compare
Native-multimodal K2.5 successor that keeps the same 1T sparse MoE backbone while targeting stronger long-horizon coding, design, and agent orchestration.
- Scale
- 1T total, 32B active (3.2% active)
- Context (tokens)
- 256,000
- License
- Modified MIT License
- Date
- 2026-04-20
- Decoder type
- Sparse MoE
- Attention
- MLA
- Layer mix
- 61 MLA
- KV cache / token (bf16) info
- 68.6 KiB · Low
- Key detail
- Uses the same text architecture as Kimi K2.5, with the main change coming from the multimodal and agentic training recipe.
- Pretraining data
- Not disclosed The version-specific model card and release post do not give a pretraining-token total. Model card · Release post
- Post-training methods
- Not disclosed The checked release sources describe capabilities without disclosing a version-specific post-training recipe. Model card · Release post
Compare
Dense Qwen3.6 model that keeps the Qwen3.5-style Gated DeltaNet/Gated Attention hybrid stack while replacing MoE blocks with dense FFNs.
- Scale
- 27B parameters
- Context (tokens)
- 262,144
- License
- Apache License 2.0
- Date
- 2026-04-22
- Decoder type
- Dense hybrid
- Attention
- 3:1 Gated DeltaNet and Gated Attention
- Layer mix
- 16 gated attention + 48 DeltaNet
- KV cache / token (bf16) info
- 64 KiB · Low
- Key detail
- Uses a 64-layer dense hybrid layout with 48 DeltaNet layers and 16 full-attention layers.
- Pretraining data
- Not disclosed The model card does not report the pretraining token count. Model card
- Post-training methods
- Not disclosed The card identifies a post-trained checkpoint without naming the methods. Model card
Related concepts
Compare
Omnimodal sparse MoE model that extends the MiMo-V2-Flash backbone with vision and audio encoders.
- Scale
- 310B total, 15B active (4.8% active)
- Context (tokens)
- 1,048,576
- License
- MIT License
- Date
- 2026-04-22
- Decoder type
- Sparse omnimodal MoE
- Attention
- 5:1 sliding-window/global attention
- Layer mix
- 39 sliding-window + 9 global
- KV cache / token (bf16) info
- 144 KiB · Moderate
- Key detail
- Adds native image, video, and audio encoders to the MiMo-V2-Flash-style sparse MoE backbone with MTP support.
- Pretraining data
- ~48T tokens Reported total for text and multimodal pretraining. Model card
- Post-training methods
- SFT, RL, Distillation SFT, agentic RL, and multi-teacher on-policy distillation (MOPD). Model card
Compare
Trillion-parameter sparse MoE model for long-horizon agentic and software-engineering tasks.
- Scale
- 1.02T total, 42B active (4.1% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 152,576 (~152k)
- License
- MIT License
- Date
- 2026-04-22
- Decoder type
- Sparse MoE
- Attention
- GQA with 6:1 sliding-window/global attention
- Layer mix
- 60 sliding-window + 10 global
- KV cache / token (bf16) info
- 350 KiB · Very high
- Key detail
- Scales the MiMo-V2.5 Pro stack to 70 layers, 384 routed experts, top-8 routing, and a 1M-token context window.
- Pretraining data
- 27T tokens Reported pretraining budget for the Pro model. Model card
- Post-training methods
- SFT, RL, Distillation SFT, domain-specialized RL teachers, and multi-teacher on-policy distillation (MOPD). Model card
Compare
Ling 2.5 successor that keeps the Lightning Attention and MLA hybrid stack while adding an MTP layer for multi-token prediction.
- Scale
- 1T total, 63B active (6.3% active)
- Context (tokens)
- 262,144
- License
- MIT License
- Date
- 2026-04-23
- Decoder type
- Sparse hybrid
- Attention
- Lightning Attention plus MLA
- Layer mix
- 10 MLA + 70 Lightning Attention + 1 MTP layer
- KV cache / token (bf16) info
- 11.2 KiB · Very low
- Key detail
- Keeps the 7:1 linear-attention/MLA ratio and adds one multi-token-prediction layer for speculative decoding.
- Pretraining data
- ~9.6T additional tokens Architectural migration and continued pretraining from the Ling 2.0 base; the inherited base training is separate from this budget. Technical report
- Post-training methods
- SFT, RLVR, Distillation SFT and specialist RL include verifiable reasoning and tool-use rewards. Specialist capabilities are then distilled into a unified Ling 2.6 model. Technical report
Related concepts
Compare
Tencent Hunyuan's 295B sparse MoE preview combines a dense first FFN layer, GQA with QK-Norm, and one extra MTP layer for faster generation.
- Scale
- 295B total, 21B active (7.1% active)
- Context (tokens)
- 262,144
- License
- Tencent Hy Community License Agreement
- Date
- 2026-04-23
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm
- Layer mix
- 80 GQA + 1 MTP layer
- KV cache / token (bf16) info
- 320 KiB · Very high
- Key detail
- Uses 192 routed experts, 8 routed plus 1 shared expert active per token, sigmoid routing with expert bias, and a 3.8B MTP layer.
- Pretraining data
- Not disclosed The model card and release post describe pretraining without a token count. Model card · Release post
- Post-training methods
- RL Tencent reports reinforcement learning for coding and agentic tasks; the full alignment recipe and reward types are not specified. Model card
Compare
IBM's dense 30B Granite 4.1 model keeps a straightforward long-context GQA transformer stack and improves tool calling, instruction following, and chat behavior through post-training.
- Scale
- 30B parameters
- Context (tokens)
- 131,072
- Vocabulary
- 100,352
- License
- Apache License 2.0
- Date
- 2026-04-29
- Decoder type
- Dense
- Attention
- GQA with RoPE
- Layer mix
- 64 GQA
- KV cache / token (bf16) info
- 256 KiB · High
- Key detail
- Uses a 4096-wide dense stack, 32 query heads, 8 KV heads, SwiGLU MLPs, shared input/output embeddings, and Granite-specific MuP scaling factors.
- Pretraining data
- Approximately 15T tokens Multi-stage pretraining, including long-context extension. Granite 4.1 training details
- Post-training methods
- SFT, RLHF, RL SFT on about 4.1M examples, then multi-domain, chat RLHF, identity, and math RL using GRPO with DAPO loss. Granite 4.1 training details
Compare
Cohere's open sparse MoE model scales the Command A parallel transformer block to 218B total parameters while keeping 25B active per token.
- Scale
- 218B total, 25B active/token (11.5% active)
- Context (tokens)
- 128K input, 64K output
- Vocabulary
- 262,144
- License
- Apache License 2.0
- Date
- 2026-05-20
- Decoder type
- Sparse MoE
- Attention
- 16:1 GQA with 3:1 sliding-window/global attention
- Layer mix
- 24 sliding-window + 8 global GQA/MoE
- KV cache / token (bf16) info
- 128 KiB · Moderate
- Key detail
- Runs attention and MoE in parallel, which Cohere reports gives similar quality to a sequential block with better throughput.
- Pretraining data
- Not disclosed The model card does not report a pretraining token count. Model card
- Post-training methods
- Distillation Quantization-aware distillation (QAD) is confirmed for the W4A4 release. The broader alignment recipe is not disclosed. Model card
Compare
Liquid AI's 1.2B LFM2.5 model keeps the 16-layer hybrid LIV convolution and GQA stack at a wider hidden size.
- Scale
- 1.2B parameters
- Context (tokens)
- 32,768
- Vocabulary
- 65,536 (~65k)
- License
- LFM Open License v1.0
- Date
- 2026-05-28
- Decoder type
- Dense hybrid
- Attention
- LIV convolution blocks plus GQA with QK-Norm
- Layer mix
- 10 LIV conv + 6 GQA
- KV cache / token (bf16) info
- 12 KiB · Very low
- Key detail
- Keeps the 16-layer LFM2.5 hybrid stack but doubles the hidden size to 2048 and uses 32 query heads.
- Pretraining data
- 28T tokens Pretraining budget for the 1.2B base used by the Thinking checkpoint. Model card
- Post-training methods
- SFT, DPO, RLVR The Thinking variant uses SFT, DPO, and domain-specific RL with verifiable rewards; the final recipe also merges RL checkpoints. Release post
Compare
Liquid AI's compact LFM2.5 model combines double-gated LIV convolution blocks with periodic GQA layers.
- Scale
- 350M parameters
- Context (tokens)
- 32,768
- Vocabulary
- 65,536 (~65k)
- License
- LFM Open License v1.0
- Date
- 2026-05-28
- Decoder type
- Dense hybrid
- Attention
- LIV convolution blocks plus GQA with QK-Norm
- Layer mix
- 10 LIV conv + 6 GQA
- KV cache / token (bf16) info
- 12 KiB · Very low
- Key detail
- Uses a 16-layer hybrid stack with 10 LIV convolution layers and 6 GQA layers.
- Pretraining data
- 28T tokens The pretraining budget was extended from 10T to 28T tokens. Model card · Release post
- Post-training methods
- RL The release confirms large-scale multi-stage reinforcement learning without a complete breakdown of the alignment methods. Release post
Compare
Liquid AI's sparse LFM2.5 model combines LIV convolution, GQA, and MoE routing with 4 of 32 experts active per token.
- Scale
- 8.3B total, 1.5B active (18.1% active)
- Context (tokens)
- 128,000
- Vocabulary
- 128,000
- License
- LFM Open License v1.0
- Date
- 2026-05-28
- Decoder type
- Sparse hybrid
- Attention
- LIV convolution blocks plus GQA with QK-Norm and MoE
- Layer mix
- 18 LIV conv + 6 GQA + MoE FFNs
- KV cache / token (bf16) info
- 12 KiB · Very low
- Key detail
- Uses 24 layers, 32 MoE experts with 4 active per token, and leaves the first two layers dense before sparse routing begins.
- Pretraining data
- 38T tokens The release reports pretraining scaled from 12T to 38T tokens. It also describes 2T and 400B context-extension stages without clearly separating them from that total. Release post
- Post-training methods
- RL, Preference optimization Large-scale RL includes a targeted hallucination-reduction stage. A separate preference-optimization stage reduces reasoning loops; its objective is not named DPO. Release post
Compare
JetBrains' Mellum2 Thinking is a compact reasoning-tuned sparse MoE for code and agentic workflows.
- Scale
- 12B total, 2.5B active (20.8% active)
- Context (tokens)
- 131,072
- Vocabulary
- 98,304 (~98k)
- License
- Apache License 2.0
- Date
- 2026-06-01
- Decoder type
- Sparse MoE
- Attention
- GQA with 3:1 sliding-window/full attention
- Layer mix
- 21 sliding-window + 7 full GQA
- KV cache / token (bf16) info
- 56 KiB · Low
- Key detail
- Uses 64 experts with 8 active per token, a 1024-token sliding window, and YaRN scaling on full-attention layers.
- Pretraining data
- ~10.6T + 117B context-extension tokens Approximately 10.6T tokens in the main three-phase pretraining curriculum, followed by a separate approximately 117B-token long-context stage. Technical report
- Post-training methods
- SFT, RLVR The Thinking checkpoint uses SFT followed by RL with verifiable rewards, using GRPO across code, math, tool use, and other tasks. Technical report
Compare
NVIDIA's Ultra model scales the Nemotron 3 hybrid stack to 550B total parameters while keeping 55B active per token.
- Scale
- 550B total, 55B active (10% active)
- Context (tokens)
- 1,000,000
- License
- NVIDIA Nemotron Open Model License
- Date
- 2026-06-04
- Decoder type
- Hybrid MoE
- Attention
- Mostly Mamba-2 with a few GQA layers using NoPE
- Layer mix
- 12 GQA + 48 Mamba-2 + 48 MoE
- KV cache / token (bf16) info
- 12 KiB · Very low
- Key detail
- Scales the latent-MoE hybrid to 108 layers with 48 Mamba-2, 48 latent MoE, and 12 GQA layers.
- Pretraining data
- 20T + 33B long-context tokens The main pretraining run uses 20T tokens, followed by 33B tokens of long-context continued pretraining. Nemotron 3 Ultra technical report
- Post-training methods
- SFT, RLVR, RLHF, Distillation SFT and multi-environment RLVR train the student. Specialized teachers, including RLHF-trained chat and alignment teachers, are consolidated through multi-teacher on-policy distillation. Nemotron 3 Ultra technical report
Related concepts
Compare
Cohere's compact agentic coding MoE adapts the parallel Cohere2-MoE block to a 30B total, 3B active model.
- Scale
- 30B total, 3B active (10% active)
- Context (tokens)
- 256K input, 64K output
- Vocabulary
- 262,144
- License
- Apache License 2.0
- Date
- 2026-06-05
- Decoder type
- Sparse MoE
- Attention
- 8:1 GQA with 3:1 sliding-window/global attention
- Layer mix
- 36 sliding-window + 13 global GQA/MoE
- KV cache / token (bf16) info
- 98 KiB · Moderate
- Key detail
- Runs attention and MoE in parallel, with RoPE in sliding-window layers, NoPE in global layers, and top-8 routing over 128 experts.
- Pretraining data
- Not disclosed The model card and release article do not report a pretraining token count. Training overview
- Post-training methods
- SFT, RLVR Two-stage cascaded SFT followed by asynchronous RL with verifiable rewards for coding agents. Training overview
Compare
Coding-focused K2.6 successor that keeps the same 1T sparse MoE text backbone and emphasizes long-horizon software engineering agents.
- Scale
- 1T total, 32B active (3.2% active)
- Context (tokens)
- 256,000
- License
- Modified MIT License
- Date
- 2026-06-12
- Decoder type
- Sparse MoE
- Attention
- MLA
- Layer mix
- 61 MLA
- KV cache / token (bf16) info
- 68.6 KiB · Low
- Key detail
- Keeps the Kimi K2.5/K2.6 text architecture and shifts the release focus toward coding-agent workflows.
- Pretraining data
- Not disclosed The release card does not disclose a version-specific pretraining-token total. Model card
- Post-training methods
- Not disclosed The release card does not specify the post-training methods used for this checkpoint. Model card
Compare
Native multimodal MiniMax model that adds sparse attention to an M2-style MoE backbone for 1M-token context.
- Scale
- 428B total, 23B active (5.4% active)
- Context (tokens)
- 1,048,576
- License
- MiniMax Community License
- Date
- 2026-06-13
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm and MiniMax Sparse Attention
- Layer mix
- 3 full GQA + 57 MiniMax Sparse Attention
- KV cache / token (bf16) info
- 120 KiB · Moderate
- Key detail
- Uses three dense prefix layers, then 57 sparse-attention MoE layers with 128 routed experts and 4 routed plus 1 shared expert active per token.
- Pretraining data
- Not disclosed The release describes native multimodal pretraining but gives no token total for the production 428B model. MiniMax M3 release
- Post-training methods
- RL, Rejection sampling Proof and verifier experts use RL with generative judges. Rejection-sampled fine-tuning trains a repair expert. These experts enter M3's merged training; the complete recipe is unspecified. MiniMax MaxProof training details
Compare
Qwen2.5-Coder-based dense reasoner whose gains mainly come from verifier-driven post-training rather than a new block design.
- Scale
- 3B parameters
- Context (tokens)
- 131,072
- Vocabulary
- 151,936 (~152k)
- License
- MIT License
- Date
- 2026-06-15
- Decoder type
- Dense
- Attention
- 8:1 GQA with RoPE
- Layer mix
- 36 GQA
- KV cache / token (bf16) info
- 36 KiB · Low
- Key detail
- Standard Qwen2.5-Coder-style dense stack strengthened by curriculum SFT, MGPO RL, Long2Short RL, offline self-distillation, and Instruct RL.
- Pretraining data
- 5.5T tokens (base-model coding training) Inherited Qwen2.5-Coder-3B budget; VibeThinker adds post-training rather than a new reported pretraining run. Technical report · Model card
- Post-training methods
- SFT, RLVR, Distillation, RL Two-stage SFT, verifiable reasoning RL, offline self-distillation, then instruction RL with rubric rewards. Technical report
Compare
Long-context GLM refresh that keeps the 744B sparse MoE backbone and adds IndexShare for 1M-token DSA inference.
- Scale
- 744B total, 40B active (5.4% active)
- Context (tokens)
- 1,048,576
- License
- MIT License
- Date
- 2026-06-17
- Decoder type
- Sparse MoE
- Attention
- MLA with DeepSeek Sparse Attention and IndexShare
- Layer mix
- 78 MLA/DSA
- KV cache / token (bf16) info
- 87.8 KiB · Moderate
- Key detail
- Reuses each full DSA indexer result across the next three layers, making 1M-token sparse attention cheaper.
- Pretraining data
- Not disclosed The model card does not publish a pretraining-token total for this version. GLM-5.2 model card
- Post-training methods
- RL, Distillation Agentic RL includes PPO-based CompactionRL. Parallel on-policy distillation merges more than ten expert models. CompactionRL report · GLM-5.2 release
Compare
Poolside's 33B Laguna refresh extends the sparse MoE architecture to 262k context while keeping about 3B parameters active per token.
- Scale
- 33B total, 3B active (9.1% active)
- Context (tokens)
- 262,144
- Vocabulary
- 100,352 (~100k)
- License
- OpenMDW License 1.1
- Date
- 2026-07-02
- Decoder type
- Sparse MoE
- Attention
- Gated GQA with QK-Norm and 3:1 sliding-window/global attention
- Layer mix
- 30 sliding-window + 10 global GQA
- KV cache / token (bf16) info
- 160 KiB · Moderate
- Key detail
- Uses 256 routed experts with top-8 routing plus one shared expert, a dense first layer, and per-layer query-head counts.
- Pretraining data
- Not disclosed The version-specific release sources do not give a token total; the linked earlier report covers XS.2. Model card · Release post
- Post-training methods
- RL The model card confirms reinforcement learning but does not publish the complete version-specific post-training recipe. Model card
Compare
German-English base model that retrains the Nemotron 3 Nano architecture on 26.68T tokens with a fully documented data mixture.
- Scale
- 31.6B total, 3.2B active (10.1% active)
- Context (tokens)
- 1,048,576
- License
- Custom license (preview)
- Date
- 2026-07-10
- Decoder type
- Hybrid MoE
- Attention
- Mostly Mamba-2 with 6 GQA layers and no positional embeddings (NoPE)
- Layer mix
- 6 GQA + 23 Mamba-2 + 23 MoE
- KV cache / token (bf16) info
- 6 KiB · Very low
- Key detail
- Reuses the Nemotron 3 Nano architecture without modification, isolating the effect of a German-English data and training recipe.
- Pretraining data
- ~26.68T tokens Consumed tokens across pretraining, annealing, and context extension; the report rounds this to ~27T. Technical report
- Post-training methods
- None (base model) This entry is Soofi-S-Base. Instruction and reasoning post-training are described as future work. Technical report
Related concepts
Compare
Thinking Machines Lab's native multimodal model combines a 66-layer sparse MoE decoder with a 5:1 mix of local and global GQA.
- Scale
- 975B total, 41B active (4.2% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 200,058 (~200k)
- License
- Apache License 2.0
- Date
- 2026-07-15
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm and learned relative-position bias in a 5:1 sliding-window/global pattern
- Layer mix
- 55 sliding-window + 11 global GQA
- KV cache / token (bf16) info
- 484 KiB · Very high
- Key detail
- Uses learned relative-position bias instead of RoPE and adds four short convolutions to each decoder layer.
- Pretraining data
- 45T tokens Multimodal pretraining on text, images, audio, and video. Training overview
- Post-training methods
- SFT, RL Synthetic-data SFT bootstrap followed by large-scale asynchronous RL across multiple domains. Training overview
Compare
Agent-oriented Qwen3.6-27B derivative that adds a rank-32 LoRA adapter for coding, structured tool use, and long multi-turn execution.
- Scale
- 27B base + 934 MB LoRA adapter
- Context (tokens)
- 262,144
- Vocabulary
- 248,320 (~248k)
- License
- Apache License 2.0
- Date
- 2026-07-20
- Decoder type
- Dense hybrid
- Attention
- 3:1 Gated DeltaNet and Gated Attention
- Layer mix
- 16 gated attention + 48 DeltaNet
- KV cache / token (bf16) info
- 64 KiB · Low
- Key detail
- Retains Qwen3.6-27B's 64-layer hybrid stack while adapting its attention, DeltaNet, and FFN projections through rank-32 LoRA.
- Pretraining data
- Not disclosed Qwen3.6-27B derivative; its model card does not disclose a pretraining token count. BTL-3 model card
- Post-training methods
- RL, LoRA Released as the RL-0013 rank-32 LoRA adapter. The card does not specify the reward source or a separate SFT stage. BTL-3 model card
Related concepts
Compare
Cisco Foundation AI's compact terminal agent uses a dense Granite 4.0 backbone and is post-trained with SFT and GRPO for vulnerability localization.
- Scale
- 1B parameters
- Context (tokens)
- 131,072
- Vocabulary
- 100,352
- License
- Apache License 2.0
- Date
- 2026-07-21
- Decoder type
- Dense
- Attention
- GQA with RoPE
- Layer mix
- 40 GQA
- KV cache / token (bf16) info
- 80 KiB · Moderate
- Key detail
- Retains Granite 4.0's MuP scaling multipliers and tied input/output embeddings, then adds SFT and GRPO for terminal-based vulnerability localization.
- Pretraining data
- Not disclosed Initialized from Granite 4.0 1B; the Antares report does not give an inherited pretraining-token total. Antares report
- Post-training methods
- SFT, RLVR, Distillation Teacher-generated SFT trajectories, followed by GRPO with vulnerability-localization rewards against ground truth. Antares report
Compare
Poolside's 118B sparse MoE scales the Laguna XS recipe to 48 layers and 1M context while activating about 8B parameters per token.
- Scale
- 118B total, 8B active (6.8% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 100,352 (~100k)
- License
- OpenMDW License 1.1
- Date
- 2026-07-21
- Decoder type
- Sparse MoE
- Attention
- Gated GQA with QK-Norm and 3:1 sliding-window/global attention
- Layer mix
- 36 sliding-window + 12 global GQA
- KV cache / token (bf16) info
- 192 KiB · High
- Key detail
- Uses 256 routed experts with top-10 routing plus one shared expert, a dense first layer, and per-layer query-head counts.
- Pretraining data
- Not disclosed Uses the same pretraining data as XS 2.1, but the release post does not give a token count for either run. Release post
- Post-training methods
- SFT, RLVR SFT with partly synthetic data is followed by RL on harder tasks, including software changes checked against executable test suites. Release post
Compare
Large sparse MoE that combines Grouped Differential Latent Attention, per-expert PolyNorm, and modified mHC in a 53-layer decoder.
- Scale
- 314B total, 13B active (4.1% active)
- Context (tokens)
- 262,144
- Vocabulary
- 220,160 (~220k)
- License
- Motif Technologies Non-Commercial License
- Date
- 2026-07-21
- Decoder type
- Sparse MoE
- Attention
- GDLA with MLA-style latent projections, RoPE, and 3:1 sliding-window/full attention
- Layer mix
- 39 sliding-window + 14 full GDLA
- KV cache / token (bf16) info
- 530 KiB · Very high
- Key detail
- Routes each token through 8 of 384 experts plus one shared expert, with per-expert PolyNorm and a 3:1 sliding-window/full GDLA pattern.
- Pretraining data
- Not disclosed This is an intermediate beta checkpoint. The later Motif 3 report gives about 12.5T tokens for the final release, without a separate beta budget. Motif 3 Beta model card · Motif 3 final-release report
- Post-training methods
- Not disclosed The beta card gives no training recipe. The later final-release SFT and distillation pipeline is not explicitly attributed to this checkpoint. Motif 3 Beta model card · Motif 3 final-release report
Compare
Compact agentic model that runs the same 22-layer dense transformer stack twice, resulting in 44 transformer blocks (layers) without duplicating the layer weights.
- Scale
- 4B total, 3B non-embedding
- Context (tokens)
- 262,144
- Vocabulary
- 166,144 (~166k)
- License
- Apache License 2.0
- Date
- 2026-07-21
- Decoder type
- Dense
- Attention
- GQA with RoPE
- Layer mix
- 22 shared GQA layers × 2 passes
- KV cache / token (bf16) info
- 176 KiB · High
- Key detail
- Reuses the same 22-layer stack for a second pass, giving 44 block applications with 3B non-embedding parameters.
- Pretraining data
- 28T tokens The new looped architecture was pretrained from scratch on 28T tokens. Nanbeige 4.2 technical report
- Post-training methods
- SFT, RLHF, RLVR Three-stage SFT, two-stage RLHF, reasoning RL with correctness and length rewards, and agentic RL using executable task checks and action rubrics. Nanbeige 4.2 technical report
Related concepts
Compare
Upstage's sparse hybrid alternates one gated GQA layer with three Kimi Delta Attention layers and reaches a 1M-token context without positional embeddings.
- Scale
- 250B total, 15B active (6% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 196,608 (~197k)
- License
- Upstage Solar License
- Date
- 2026-07-22
- Decoder type
- Sparse hybrid
- Attention
- 3:1 Kimi Delta Attention and gated GQA with NoPE
- Layer mix
- 12 gated GQA + 36 Kimi Delta Attention
- KV cache / token (bf16) info
- 48 KiB · Low
- Key detail
- Uses a repeating gated-GQA/KDA hybrid stack, kernel-4 ShortConv in KDA, and top-8 routing over 320 experts plus one shared expert.
- Pretraining data
- ~12T additional tokens After selective weight transfer from Solar Open 1, the stages consume 10T + 1T + 0.9T tokens. Technical report
- Post-training methods
- SFT, RLVR, Distillation SFT and multi-domain verifiable RL are followed by specialist training and multi-teacher on-policy distillation. Technical report
Related concepts
Compare
2.8T sparse hybrid that combines a 3:1 KDA and Gated MLA stack with Block Attention Residuals and Stable LatentMoE. It is also native multimodal, but the figure focuses on the text portion.
- Scale
- 2.8T total, 104B active (3.7% active)
- Context (tokens)
- 1,048,576
- License
- Kimi K3 License
- Date
- 2026-07-27
- Decoder type
- Sparse hybrid
- Attention
- 3:1 Kimi Delta Attention and Gated MLA with NoPE
- Layer mix
- 69 KDA + 24 Gated MLA
- KV cache / token (bf16) info
- 27 KiB · Low
- Key detail
- Uses eight Block Attention Residual groups and Stable LatentMoE with 16 of 896 routed experts active per token.
- Pretraining data
- Not disclosed The report describes native multimodal pretraining and context extension without publishing the total training tokens. Technical report
- Post-training methods
- SFT, RL, Distillation SFT is followed by domain- and effort-specialized RL, then multi-teacher on-policy distillation into one model. Technical report
- AA Intelligence Index v5.0 info
- Total score N/A Knowledge Work N/A Coding N/A Science 20.7 General N/A
Related concepts
Compare
Hybrid MoE that alternates five Kimi Delta Attention layers with one gated MLA layer.
- Scale
- 124B total, 5.1B active (4.1% active)
- Context (tokens)
- 262,144
- Vocabulary
- 157,184 (~157k)
- License
- MIT License
- Date
- 2026-08-04
- Decoder type
- Sparse hybrid
- Attention
- 5:1 Kimi Delta Attention and gated MLA
- Layer mix
- 35 Kimi Delta Attention + 7 gated MLA + 1 MTP layer
- KV cache / token (bf16) info
- 7.9 KiB · Very low
- Key detail
- Uses fine-grained diagonal KDA gating, top-8 routing over 512 experts plus one shared expert, and one MTP layer.
- Pretraining data
- >10T tokens (training corpus) The official disclosure gives a lower bound on the preprocessed text corpus for the Ling 3.0 family, including Flash. It does not give tokens seen during pretraining. Training data summary
- Post-training methods
- RL Ant's developer documentation attributes improved long-horizon tool calling to reinforcement learning with stronger checks. The full alignment recipe is not disclosed. Developer documentation
Related concepts
Compare
Meta's dense 29.6B multimodal model combines a 52-layer sandwich-norm decoder with gated GQA and a separate perception encoder; the figure focuses on the text backbone.
- Scale
- 29.6B parameters (including perception encoder)
- Context (tokens)
- 131,072+
- Vocabulary
- 202,048 (~202k)
- License
- Apache License 2.0
- Date
- 2026-08-10
- Decoder type
- Dense
- Attention
- Gated GQA with scaleless QK-Norm, local-only RoPE, global NoPE, and 3:1 sliding-window/global attention
- Layer mix
- 39 sliding-window + 13 global gated GQA
- KV cache / token (bf16) info
- 52 KiB · Low
- Key detail
- Applies RoPE only in 2,048-token local layers, uses NoPE in global layers, and gates the attention output before projection.
- Pretraining data
- Not disclosed The report describes pretraining through logit co-distillation and later mid-training, but does not report total training tokens. Muse Glimmer technical report
- Post-training methods
- SFT, Distillation, RL Supervised fine-tuning, on-policy distillation from Muse Spark, and reinforcement learning. Muse Glimmer technical report
Compare
NVIDIA's 30B hybrid model keeps 3B parameters active and extends the Nemotron 3 Nano backbone with a 1M-token context window and multi-token prediction.
- Scale
- 30B total, 3B active (10% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 131,072
- License
- OpenMDW 1.1
- Date
- 2026-08-11
- Decoder type
- Hybrid MoE
- Attention
- Mostly Mamba-2 with six GQA layers using NoPE
- Layer mix
- 6 GQA + 23 Mamba-2 + 23 MoE; GQA + MoE MTP predictor
- KV cache / token (bf16) info
- 6 KiB · Very low
- Key detail
- Adds a shared GQA-plus-MoE MTP predictor to the 52-layer Nemotron 3 Nano backbone.
- Pretraining data
- 1.021T additional tokens Continued from Nemotron 3 Nano Base with 1T distillation tokens and 21B long-context tokens. A separate 100B-token MTP-head warmup freezes the backbone. Nemotron 3.5 technical report
- Post-training methods
- SFT, RLVR Single-stage text-only supervised fine-tuning followed by reinforcement learning with verifiable rewards. Nemotron 3.5 technical report
Compare
Dense 27B native vision-language model with a 64-layer Gated DeltaNet and Gated Attention language backbone; the figure omits the vision encoder and MTP head.
- Scale
- 27B parameters
- Context (tokens)
- 262,144
- Vocabulary
- 248,320 (~248k)
- License
- Apache License 2.0
- Date
- 2026-08-14
- Decoder type
- Dense hybrid
- Attention
- 3:1 Gated DeltaNet and Gated Attention
- Layer mix
- 16 gated attention + 48 DeltaNet
- KV cache / token (bf16) info
- 64 KiB · Low
- Key detail
- Uses a 64-layer 3:1 Gated DeltaNet/Gated Attention decoder with partial RoPE and one MTP layer.
- Pretraining data
- Not disclosed The model card does not report the pretraining token count. Model card
- Post-training methods
- Not disclosed The card identifies a post-trained checkpoint without naming the methods. Model card
Related concepts
Compare
Uses the same sparse-hybrid decoder geometry as Qwen3.6 35B-A3B, paired with Ornith's self-improvement training recipe.
- Scale
- 35B total, 3B active (8.6% active)
- Context (tokens)
- 262,144
- Vocabulary
- 248,320 (~248k)
- License
- MIT License
- Date
- 2026-08-23
- Decoder type
- Sparse hybrid
- Attention
- 3:1 Gated DeltaNet and Gated Attention
- Layer mix
- 10 gated attention + 30 DeltaNet
- KV cache / token (bf16) info
- 20 KiB · Very low
- Key detail
- Matches Qwen3.6 35B-A3B's 40-layer decoder geometry, with 256 routed experts, top-8 routing, and one shared expert.
- Pretraining data
- Not disclosed The card describes its Ornith 1.0 lineage but provides no inherited or additional pretraining-token total. Ornith 1.5 model card
- Post-training methods
- RL GRPO-based self-improvement trains on generated tasks, scaffolds, and agent rollouts. Rewards include correctness on verifiable tasks and broader completion criteria. Ornith 1.5 training details
Related concepts
Compare
Natively multimodal GLM refresh, previously previewed as Ox Alpha, that replaces most MLA/DSA layers with Kimi Delta Attention and adds four-stream mHC.
- Scale
- 320B total, 18B active (5.6% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 154,880 (~155k)
- License
- MIT License
- Date
- 2026-08-26
- Decoder type
- Sparse hybrid
- Attention
- 3:1 Kimi Delta Attention (Q/K L2 normalization) and MLA with DeepSeek Sparse Attention
- Layer mix
- 34 KDA + 11 MLA/DSA + 1 MTP layer
- KV cache / token (bf16) info
- 11 KiB · Very low
- Key detail
- Mixes 34 Kimi Delta Attention layers with 11 MLA/DSA layers and routes residuals through four mHC streams.
- Pretraining data
- 30T-token multimodal corpus Reported corpus size for a newly trained base; a separate tokens-seen total is not given. GLM-5.3 Flash release
- Post-training methods
- RL The release describes frontend-coding RL with environment feedback; other alignment stages are not itemized. GLM-5.3 Flash release
Compare
Experimental vision-language MoE whose text backbone combines Gated DeltaNet, micro-block QSA, four-branch gated residuals, and n-gram embeddings; the figure omits the vision encoder and MTP head.
- Scale
- 125B core, 6B active (4.8% active); plus 51B n-gram embeddings and 4B MTP
- Context (tokens)
- 262,144
- Vocabulary
- 248,320 (~248k)
- License
- Qwen Community License 1.0
- Date
- 2026-08-26
- Decoder type
- Sparse hybrid
- Attention
- 3:1 Gated DeltaNet and Qwen Sparse Attention (QSA)
- Layer mix
- 12 QSA + 36 DeltaNet
- KV cache / token (bf16) info
- 24 KiB · Very low
- Key detail
- Replaces full attention with micro-block QSA while using four gated residual branches and a 20M-entry n-gram embedding at layer 2.
- Pretraining data
- Not disclosed The architecture report gives proxy training budgets and relative savings, but no full-model token total. Architecture report
- Post-training methods
- Not disclosed The model card confirms post-training without specifying its methods. Model card
- AA Intelligence Index v5.0 info
- Total score N/A Knowledge Work N/A Coding N/A Science N/A General 26.6
Related concepts
Compare
Tencent's 770B sparse MoE combines gated DeepSeek Sparse Attention, cross-layer index reuse, and four-stream identity Hyper-Connections.
- Scale
- 770B backbone, 49B active (6.4% active); plus 10B MTP
- Context (tokens)
- 1,048,576
- Vocabulary
- 120,832 (~121k)
- License
- Apache License 2.0
- Date
- 2026-08-28
- Decoder type
- Sparse MoE
- Attention
- Gated MLA with DeepSeek Sparse Attention and IndexCache
- Layer mix
- 78 gated MLA/DSA + 1 MTP layer
- KV cache / token (bf16) info
- 87.8 KiB · Moderate
- Key detail
- Uses 256 routed experts with 8 routed plus 1 shared expert active per token, a top-2,048 DSA indexer, cross-layer index reuse, and four iHC residual streams.
- Pretraining data
- Not disclosed The release card says training data was scaled up but does not give a token count. Model card
- Post-training methods
- RL Core contributor Chenchen Zhang reports reinforcement-learning work on Hy4 preview. The full post-training recipe and reward types are not disclosed. Core contributor's project description · Model card
Related concepts
Compare
Causal encoder-decoder MoE with CSA2 cache sharing, Engram memory, and a million-token context. The figure shows the text backbone.
- Scale
- 552B backbone + 196B Engram; 8B active prefill, 16B active decode (2.9% of backbone)
- Context (tokens)
- 1,048,576
- Vocabulary
- 129,280
- License
- MIT License
- Date
- 2026-09-10
- Decoder type
- Sparse MoE (causal encoder-decoder)
- Attention
- MLA-style CSA2 + SWA with cross-layer KV and sparse-index reuse
- Layer mix
- 20 encoder + 20 decoder layers; 2 SWA-only + 38 CSA2/SWA
- KV cache / token (bf16) info
- 3.125 KiB · Very low
- Key detail
- Decoder global KV comes from final encoder states. Single-Pass mHC mixes four residual streams around each attention and MoE sublayer.
- Pretraining data
- 45T tokens Multimodal pretraining from scratch, including long-context training. DeepSeek V4.1 Flash model card
- Post-training methods
- SFT, RL, Distillation SFT, RL, then on-policy distillation; agent-task and environment synthesis expands the training data. DeepSeek V4.1 Flash model card
Compare
StepFun's 92-layer MoE pairs 512-token sliding-window attention with sparse GQA for a 1M-token context window; the figure shows the text decoder.
- Scale
- 600B total, 27B active (4.5% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 128,896 (~129k)
- License
- N/A
- Date
- 2026-09-20
- Decoder type
- Sparse MoE
- Attention
- Gated GQA with QK-Norm and 3:1 sliding-window/sparse attention
- Layer mix
- 69 sliding-window + 23 sparse GQA + 3 MTP layers
- KV cache / token (bf16) info
- N/A
- Key detail
- Uses top-512 sparse indexing with block size 8, 352 routed experts with 8 active plus one shared expert, and MTP-3. The first three and final backbone layers use dense FFNs with intermediate size 13,824.
- Pretraining data
- Not disclosed The official training overview does not report a pretraining token count. Training overview
- Post-training methods
- SFT, RLVR The overview identifies SFT and agentic RL with verifiable environments, outcome rewards, and a learned critic. Training overview
Compare
Omnimodal sparse MoE model with the MiMo-V2.5 text backbone, mixed-domain reinforcement learning, and a five-layer DFlash speculative decoder.
- Scale
- 309B total, 15B active (4.9% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 152,576 (~152k)
- License
- MIT License
- Date
- 2026-09-21
- Decoder type
- Sparse omnimodal MoE
- Attention
- GQA with sliding-window/global attention
- Layer mix
- 39 sliding-window + 9 global
- KV cache / token (bf16) info
- 217.5 KiB · High
- Key detail
- Uses 256 routed experts with top-8 routing, one dense prefix layer, no shared experts, and a 128-token sliding window.
- Pretraining data
- 48T tokens 26T text-stage tokens plus 22T omni-stage tokens. Technical report
- Post-training methods
- SFT, RLVR, Distillation Short SFT, mixed-task GRPO using tests and agentic graders, and MOPD2 distillation described in the series recipe. Technical report
Compare
Omnimodal sparse MoE model with the MiMo-V2.5-Pro text backbone, mixed-domain reinforcement learning, and a five-layer DFlash speculative decoder.
- Scale
- 1.02T total, 42B active (4.1% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 152,576 (~152k)
- License
- MIT License
- Date
- 2026-09-21
- Decoder type
- Sparse omnimodal MoE
- Attention
- GQA with 6:1 sliding-window/global attention
- Layer mix
- 60 sliding-window + 10 global
- KV cache / token (bf16) info
- 350 KiB · Very high
- Key detail
- Uses 384 routed experts with top-8 routing, one dense prefix layer, no shared experts, and a 128-token sliding window.
- Pretraining data
- 30T tokens 27T text-stage tokens plus 3T omni-stage tokens. Technical report
- Post-training methods
- SFT, RLVR, Distillation Short SFT, mixed-task GRPO using tests and agentic graders, and MOPD2 distillation described in the series recipe. Technical report
Compare
Fireworks' Kimi K3 derivative, post-trained for shorter reasoning traces. Architecture details follow the published Kimi K3 base model; the diagram focuses on its text backbone.
- Scale
- 2.8T total, 104B active (3.7% active)
- Context (tokens)
- 1,048,576
- License
- N/A
- Date
- 2026-09-23
- Decoder type
- Sparse hybrid
- Attention
- 3:1 Kimi Delta Attention and Gated MLA with NoPE
- Layer mix
- 69 KDA + 24 Gated MLA
- KV cache / token (bf16) info
- 27 KiB · Low
- Key detail
- Inherits Kimi K3's eight Block Attention Residual groups and Stable LatentMoE, with one dense layer followed by 92 MoE layers.
- Pretraining data
- Not disclosed Derived from Kimi K3; the release does not disclose a pretraining-token total. Ember-1 release
- Post-training methods
- Not disclosed The release describes additional training to shorten reasoning but does not name its training stages. Ember-1 release
Related concepts
Compare
MiMo-V2.5-derived sparse MoE that replaces its global attention layers with GQA-based DeepSeek Sparse Attention for a native 1M-token context.
- Scale
- 309B total, 15.5B active (5.0% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 152,576 (~152k)
- License
- MIT License
- Date
- 2026-09-27
- Decoder type
- Sparse MoE
- Attention
- GQA with sliding-window attention and DeepSeek Sparse Attention
- Layer mix
- 39 sliding-window + 9 GQA/DSA
- KV cache / token (bf16) info
- 219.75 KiB · High
- Key detail
- Pairs a 128-token local window with top-2,048 DSA selection, four DSA KV heads, and a 16-head indexer. Uses 256 routed experts with top-8 routing and no full-attention layers.
- Pretraining data
- 3T additional pretraining tokens Continued from MiMo-V2.5. The reported 3.25T adaptation budget also includes 50B frozen-backbone indexer-warmup tokens and 200B SFT tokens; inherited base training is separate. NaiveAI training procedure
- Post-training methods
- SFT The final learning-rate decay stage uses supervised fine-tuning for 200B tokens. NaiveAI training procedure
Compare
Aleph Alpha's German-English reasoning model uses 50 MoE blocks with a 4:1 mix of sliding-window and global GQA.
- Scale
- 78B total, 3.46B active (4.4% active)
- Context (tokens)
- 262,144 native; 1,048,576 extrapolated
- Vocabulary
- 128,000
- License
- Apache License 2.0
- Date
- 2026-10-03
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm and 4:1 sliding-window/global attention
- Layer mix
- 40 sliding-window + 10 global GQA
- KV cache / token (bf16) info
- 100 KiB · Moderate
- Key detail
- Uses top-6 routing over 384 experts plus one shared expert, with sandwich RMSNorm, RoPE in local layers, and NoPE in global layers.
- Pretraining data
- ~24T tokens Includes 20T pretraining, 3.4T midtraining, and 200B context-extension tokens; the report rounds the combined budget to 24T. Technical report
- Post-training methods
- SFT, RLVR, Distillation SFT is followed by RL with verifiable rewards across 38 environments, with targeted on-policy self-distillation for low-reward groups. Technical report
Compare
Hybrid MoE that extends Ling 3.0 Flash to 72 layers, with seven Kimi Delta Attention layers for every gated MLA layer.
- Scale
- 560B total, 25B active (4.5% active)
- Context (tokens)
- 1M reported; 262,144 in config
- Vocabulary
- 157,184 (~157k)
- License
- MIT License
- Date
- 2026-10-13
- Decoder type
- Sparse hybrid
- Attention
- 7:1 Kimi Delta Attention and gated MLA
- Layer mix
- 63 Kimi Delta Attention + 9 gated MLA + 1 MTP layer
- KV cache / token (bf16) info
- 10.1 KiB · Very low
- Key detail
- Uses four initial dense FFN layers, top-8 routing over 512 experts plus one shared expert, and MLA with a 1,536-dimensional query bottleneck and 512-dimensional KV latent.
- Pretraining data
- >10T tokens (training corpus) The official disclosure gives a lower bound on the preprocessed text corpus for Ling 3.1 Flash. It does not give tokens seen during pretraining. Training data summary
- Post-training methods
- RL The release post confirms reinforcement learning improved task performance while increasing reasoning length and interaction rounds. It does not specify the reward types or full recipe. Release post
Related concepts
Compare
Meta's multimodal MoE model combines 62 latent-expert blocks with gated GQA, local-only RoPE, global NoPE, and learned residual gates; the figure focuses on the text decoder.
- Scale
- 816B total, 42B active (5.1% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 202,048 (~202k)
- License
- Muse Model License
- Date
- 2026-10-15
- Decoder type
- Sparse MoE
- Attention
- Gated GQA with scaleless QK-Norm, local-only RoPE, global NoPE, and 3:1 sliding-window/global attention
- Layer mix
- 46 sliding-window + 16 global gated GQA
- KV cache / token (bf16) info
- 248 KiB · High
- Key detail
- Selects 8 of 256 experts, compresses the expert path from 8,192 to 4,096 dimensions, normalizes each expert output before combining, and uses no shared expert.
- Pretraining data
- Not disclosed The card lists multimodal data sources but does not provide a training-set size or token total. Muse Spark Open model card
- Post-training methods
- Not disclosed Additional safety post-training is confirmed, but the model card does not specify SFT, preference-optimization, or RL methods. Muse Spark Open model card
Compare
NVIDIA's vision-language model extends the Nemotron 3 Super backbone with C-RADIO vision encoding and shared-weight multi-token prediction. The figure shows the language backbone, with the vision encoder and MTP omitted.
- Scale
- 120B total, 12B active (10% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 131,072
- License
- OpenMDW 1.1
- Date
- 2026-10-15
- Decoder type
- Hybrid MoE
- Attention
- Mostly Mamba-2 with eight GQA layers using NoPE
- Layer mix
- 8 GQA + 40 Mamba-2 + 40 LatentMoE; GQA + MoE MTP predictor
- KV cache / token (bf16) info
- 8 KiB · Very low
- Key detail
- Routes each token to 22 of 512 experts in a 1,024-dimensional latent space, alongside one shared expert at the full 4,096-dimensional width.
- Pretraining data
- 1.2094T additional tokens Continued from Nemotron 3 Super Base with 1T distillation, 100B Indic, 35B context-extension, 65.4B agentic mid-training, and 9B context-recovery tokens. Separate 100B MTP-head warmup freezes the backbone. Nemotron 3.5 technical report
- Post-training methods
- SFT, RLVR, RLHF, Distillation Vision-language SFT, verifiable-reward RL, human-feedback RL, and multi-teacher on-policy distillation. Nemotron 3.5 technical report
Compare
Text-only MoE decoder with three dense FFN layers followed by 49 expert layers. Each MoE layer activates 8 of 256 experts without a shared expert.
- Scale
- 501.3B total, 23.4B active (4.7% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 151,936 (~152k)
- License
- Apache License 2.0
- Date
- 2026-10-16
- Decoder type
- Sparse MoE
- Attention
- Gated GQA with QK-Norm and sliding-window/global attention
- Layer mix
- 43 sliding-window + 9 global GQA
- KV cache / token (bf16) info
- 208 KiB · High
- Key detail
- Combines 512-token local RoPE attention with global NoPE and query scaling. Uses sandwich RMSNorm, depth-scaled residuals, and a final logit softcap of 30.
- Pretraining data
- Not disclosed The card describes the text/code corpus and mid-training sources without a token count. Model card
- Post-training methods
- RL RL environments cover coding, agentic tasks, and STEM; the full recipe is not disclosed. Model card
Compare
NVIDIA's dense looped transformer applies a shared 20-block core twice between 8-block input and output stacks, using normalized GPT (nGPT) residual updates.
- Scale
- 4B parameters
- Context (tokens)
- 262,144
- Vocabulary
- 131,072 (~131k)
- License
- OpenMDW 1.1
- Date
- 2026-10-16
- Decoder type
- Dense
- Attention
- Gated GQA; 3:1 sliding-window/full, RoPE
- Layer mix
- 8 input + 20 shared × 2 passes + 8 output (56 applications)
- KV cache / token (bf16) info
- 224 KiB · High
- Key detail
- Reinjects the input-stack output before each recurrent pass. The 36 distinct blocks give 56 block applications by default, with L2-normalized residual updates and a 1,024-token attention window.
- Pretraining data
- 6T tokens + 300B context-extension tokens The model card reports pretraining and context extension separately. Dory 1.0 model card
- Post-training methods
- SFT, RL, Distillation SFT uses teacher-generated data, followed by multi-environment GRPO for reasoning, coding, tool use, and instruction following. Dory 1.0 model card
Related concepts
Compare
Recursive's coding model uses two dense FFN layers followed by 47 MoE layers. The active-parameter count includes the output head.
- Scale
- 39.8B total, 2.5B active (6.3% active)
- Context (tokens)
- 262,144 configured; 512k supported
- Vocabulary
- 150,144
- License
- Apache License 2.0
- Date
- 2026-10-18
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm, learned attention sinks, and sliding-window/global attention
- Layer mix
- 35 sliding-window + 14 global GQA
- KV cache / token (bf16) info
- 98 KiB · Moderate
- Key detail
- Uses top-6 routing over 256 experts plus one shared expert, with RoPE in local layers, NoPE in global layers, and a local window covering the current token and 512 preceding tokens.
- Pretraining data
- Not disclosed The card describes training from scratch but omits the token count. Model card
- Post-training methods
- SFT, RL The card explicitly lists supervised fine-tuning and reinforcement learning after pretraining and mid-training. Model card
Compare
MiniMax M3 successor with sparse attention in all 60 decoder layers, quantization-aware training, and a DSpark draft head for speculative decoding.
- Scale
- 428B total, 23B active (5.4% active)
- Context (tokens)
- 1,048,576
- License
- MiniMax Community License
- Date
- 2026-10-19
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm and MiniMax Sparse Attention
- Layer mix
- 60 MiniMax Sparse Attention; 3 dense FFN + 57 MoE
- KV cache / token (bf16) info
- 120 KiB · Moderate
- Key detail
- All 60 layers use sparse attention; the first 3 retain dense FFNs, while the remaining 57 route to 4 of 128 experts plus 1 shared expert per token.
- Pretraining data
- Not disclosed No pretraining total is given. The release's 200T-token figure describes anonymous serving usage. MiniMax M3.1 Flash release · MiniMax M3.1 Flash model card
- Post-training methods
- Not disclosed The release and model card do not specify the instruction-tuning or reinforcement-learning recipe. MiniMax M3.1 Flash release · MiniMax M3.1 Flash model card
Compare
Dense model for coding and tool-use agents, with a 52-layer Llama-style decoder and a 524,288-token context.
- Scale
- 33B parameters
- Context (tokens)
- 524,288
- Vocabulary
- 166,912 (~167k)
- License
- Apache License 2.0
- Date
- 2026-10-24
- Decoder type
- Dense
- Attention
- GQA with RoPE
- Layer mix
- 52 GQA
- KV cache / token (bf16) info
- 208 KiB · High
- Key detail
- Uses 52 distinct decoder layers with 56 query heads, 8 KV heads, and untied input and output embeddings.
- Pretraining data
- Not disclosed The model and base-model cards do not disclose the pretraining token count for Nanbeige4.3-33B-Base. Nanbeige 4.3 base model card · Nanbeige 4.3 model card
- Post-training methods
- Not disclosed The released chat model is derived from Nanbeige4.3-33B-Base, but its model card does not specify the post-training methods. Nanbeige 4.3 model card
Compare
Liquid AI's 1.73B dense hybrid combines short convolutions with sliding-window and global GQA in a 24-layer stack.
- Scale
- 1.73B parameters
- Context (tokens)
- 262,144
- Vocabulary
- 128,000
- License
- LFM Open License v1.0
- Date
- 2026-10-27
- Decoder type
- Dense hybrid
- Attention
- ShortConv plus gated GQA with QK-Norm and sliding-window/global attention
- Layer mix
- 13 ShortConv + 5 sliding-window + 6 global GQA
- KV cache / token (bf16) info
- 22 KiB · Very low
- Key detail
- Uses kernel-7 ShortConv, a 256-token attention window, per-head sigmoid gates, and sandwich RMSNorm. Global attention uses 50% partial RoPE.
- Pretraining data
- 22T tokens Includes the last 3.5T tokens of midtraining and context extension; the separate SFT budget is excluded. Model card
- Post-training methods
- SFT, RL, Distillation SFT is followed by mixed-domain RL, on-policy distillation from six specialist RL teachers, and a final agentic RL stage. Model card
Compare
Mistral's trillion-parameter multimodal MoE combines MLA with sparse token selection and cross-layer KV sharing.
- Scale
- 1T total, 52B active (5.2% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 204,800
- License
- Mistral Ecosystem Open-Weight License
- Date
- 2026-10-29
- Decoder type
- Sparse MoE
- Attention
- MLA with modified DeepSeek Sparse Attention, index reuse, and KV sharing
- Layer mix
- 72 MLA/DSA
- KV cache / token (bf16) info
- 80.75 KiB · Moderate
- Key detail
- Selects the top 2,048 tokens, reuses sparse indices across layers, and alternates three LeRoPE layers with one NoPE layer.
- Pretraining data
- Not disclosed The technical report describes two multilingual multimodal pretraining phases but gives no total token count. Mistral Large 4 technical report
- Post-training methods
- SFT, RLVR Supervised fine-tuning followed by RL using executable task verification, alongside learned and model-judged rewards. Mistral Large 4 technical report
Related concepts
Compare
Meituan's native multimodal MoE combines Shortcut MoE, n-gram embeddings, and LongCat Sparse Attention. The figure shows the language backbone, with the vision encoder and MTP module omitted.
- Scale
- 1.6T total, ~48B active (3% active)
- Context (tokens)
- 524,288
- Vocabulary
- 163,840 (~164k)
- License
- MIT License
- Date
- 2026-11-02
- Decoder type
- Sparse MoE
- Attention
- MLA with LongCat Sparse Attention (LSA) and cross-layer index reuse
- Layer mix
- 38 blocks / 76 MLA + LSA sublayers
- KV cache / token (bf16) info
- 95 KiB · Moderate
- Key detail
- Reuses top-2,048 token selections across each attention pair. Shortcut MoE selects 12 of 768 learned and 128 identity experts; n-gram lookup tables hold about 135B parameters.
- Pretraining data
- Not disclosed The release card does not publish a pretraining-token total. Model card
- Post-training methods
- SFT, RL, Distillation The release describes long-sequence SFT, large-scale RL, and multi-teacher full-vocabulary KL distillation. Model card
Compare
Post-trained from Kimi K3, with its 24 Gated MLA layers converted to Gated DeepSeek Sparse Attention. The figure shows the text backbone of this native multimodal model.
- Scale
- 2.8T total, 104B active (3.7% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 163,840 (~160k)
- License
- Kimi K3.1 Pro License
- Date
- 2026-11-04
- Decoder type
- Sparse hybrid
- Attention
- Kimi Delta Attention and Gated MLA with DeepSeek Sparse Attention and NoPE
- Layer mix
- 69 KDA + 24 Gated DSA
- KV cache / token (bf16) info
- 33 KiB · Low
- Key detail
- Keeps eight Block Attention Residual groups and Stable LatentMoE with 16 of 896 routed experts plus two shared experts per token. The DSA indexer selects up to 2,048 tokens using 32 heads of 128 dimensions.
- Pretraining data
- Not disclosed Derived from Kimi K3; the release card does not disclose a pretraining-token total for K3.1 Pro. Model card
- Post-training methods
- RL The K3.1 Pro update is post-trained from K3 using large-scale joint RL across hundreds of domains. The card does not specify the reward types. Model card
Related concepts
Compare
Text-only base model with 37 heavily compressed attention layers and 6 MLA/DSA layers. Pretrained with up to 128K tokens of context; fine-tuning and inference support 1M tokens.
- Scale
- 280B total, 14B active (5.0% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 201,216 (~201k)
- License
- ERNIE 5.5 Flash Base Model License Agreement v1.0
- Date
- 2026-11-05
- Decoder type
- Sparse MoE
- Attention
- Gated HCA and MLA with DeepSeek Sparse Attention, VHA, and QK-Norm
- Layer mix
- 37 HCA + 6 MLA/DSA; 1 dense FFN + 42 latent MoE
- KV cache / token (bf16) info
- 8.54 KiB · Very low
- Key detail
- Four-stream mHC surrounds attention and latent MoE. Two sigmoid routers select 10 of 512 routed experts, alongside one always-active shared expert. ECHO reuses the final backbone layer for multi-token prediction.
- Pretraining data
- 33.5T tokens Text-only pretraining from scratch. ERNIE 5.5 Flash Base model card
- Post-training methods
- None (base model) Released at the end of pretraining, before any mid-training or post-training. ERNIE 5.5 Flash Base model card
Compare
Nous Research's supervised fine-tune of Qwen3.8-27B. The vision encoder was retained and frozen during text-only fine-tuning; the figure shows the language backbone.
- Scale
- 27B parameters
- Context (tokens)
- 262,144
- Vocabulary
- 248,320 (~248k)
- License
- Apache License 2.0
- Date
- 2026-11-06
- Decoder type
- Dense hybrid
- Attention
- 3:1 Gated DeltaNet and Gated Attention
- Layer mix
- 16 gated attention + 48 DeltaNet
- KV cache / token (bf16) info
- 64 KiB · Low
- Key detail
- Retains Qwen3.8-27B's 64-layer hybrid decoder with partial RoPE. The released checkpoint has no MTP head.
- Pretraining data
- Not disclosed Derived from Qwen3.8-27B. The Arete card does not disclose the inherited pretraining-token total. Arete 27B model card
- Post-training methods
- SFT Supervised fine-tuning with Inkling-generated supervision. The card explicitly excludes RL and preference optimization. Arete 27B model card
Related concepts
Compare
Multimodal sparse MoE with a 48-layer decoder, 8-of-384 expert routing, and block attention residuals.
- Scale
- 594B total, 17B active (2.9% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 200,058 (~200k; padded to 201,024)
- License
- Apache License 2.0
- Date
- 2026-11-12
- Decoder type
- Sparse MoE
- Attention
- Gated GQA with Q/K L2 clipping and learned relative-position bias in a 5:1 sliding-window/global pattern
- Layer mix
- 40 sliding-window + 8 global GQA
- KV cache / token (bf16) info
- 192 KiB · High
- Key detail
- Groups the decoder into eight 6-layer AttnRes blocks and adds kernel-4 short convolutions. The figure omits the vision encoder and 5-layer DSpark draft.
- Pretraining data
- 8.4T + 3.8T tokens (H1 + H2) H1 covers natural language, code, and images; H2 uses newer, higher-quality data at 512K context. H3 uses about 320B tokens of reasoning and agent trajectories alongside pretraining replay, and H4 uses about 34B agent-trajectory tokens. Training overview
- Post-training methods
- RL Joint asynchronous RL with StableReinforce across 1,075 steps, over 17M rollouts, and over 3T tokens. Task-specific graders include unit tests, reference answers, LLM judges, and pairwise reward models. Training overview
Related concepts
Compare
Qwen3-style research model, included for its excellent technical report on data curation, optimization, and controlled training experiments.
- Scale
- 30.4B total, 3.26B active (10.7% active)
- Context (tokens)
- 65,536
- Vocabulary
- 129,280 (~129k)
- License
- N/A
- Date
- 2026-11-16
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm and RoPE
- Layer mix
- 48 GQA
- KV cache / token (bf16) info
- 96 KiB · Moderate
- Key detail
- Uses Qwen3-30B-A3B's 48-layer backbone with 8 of 128 experts active per token, the DeepSeek V4 tokenizer, and AdamH optimization with explicit weight-norm constraints.
- Pretraining data
- 1T tokens XL curated model, pretrained from scratch on Datology-curated data. A further 10B tokens extend context from 8k to 64k. All token counts use the DeepSeek V4 tokenizer. Datology technical report
- Post-training methods
- SFT, RLVR, Model merging About 20B SFT tokens, followed by four GRPO specialists for mathematics, code, instruction following, and tool use. The specialists are merged into one model. Datology technical report
Compare
Marin's base model combines latent MoE with gated grouped-query attention. Every fourth layer attends to the full context. The other layers use a 2,048-token window.
- Scale
- 535.48B total, 22.76B active non-embedding (4.3% active)
- Context (tokens)
- 262,144
- Vocabulary
- 128,256 (~128k)
- License
- OpenMDW 1.1
- Date
- 2026-11-17
- Decoder type
- Sparse MoE
- Attention
- Gated GQA with exclusive self-attention (XSA). Local layers apply RoPE to half of each head, and global layers use NoPE.
- Layer mix
- 36 sliding-window + 12 global GQA
- KV cache / token (bf16) info
- 252 KiB · High
- Key detail
- Each token uses 8 of 384 routed SwiGLU experts at half width (3,072 dimensions) and 2 shared experts at full width (6,144). Kernel-4 short convolutions act on the keys, the attention output, and the MoE output.
- Pretraining data
- 18.2T tokens The pretraining run extended context from 4k to 16k, then 65k and 262k tokens. The final checkpoint is step 393,491. Open Athena checkpoint release · Marin Mochi model card
- Post-training methods
- None (base model) All 57 released checkpoints are base models from the pretraining run. Open Athena checkpoint release
Compare
Source article
The Big LLM Architecture Comparison
The original comparison article that walks through the architecture figures in context and explains the key design choices across dense, MoE, MLA, and hybrid decoder families.
Read article
Source article
From GPT-2 to gpt-oss: Analyzing the Architectural Advances
A focused follow-up article on the GPT-2 to gpt-oss shift, covering the architectural changes around RoPE, SwiGLU, MoE, GQA, sliding-window attention, and RMSNorm.
Read article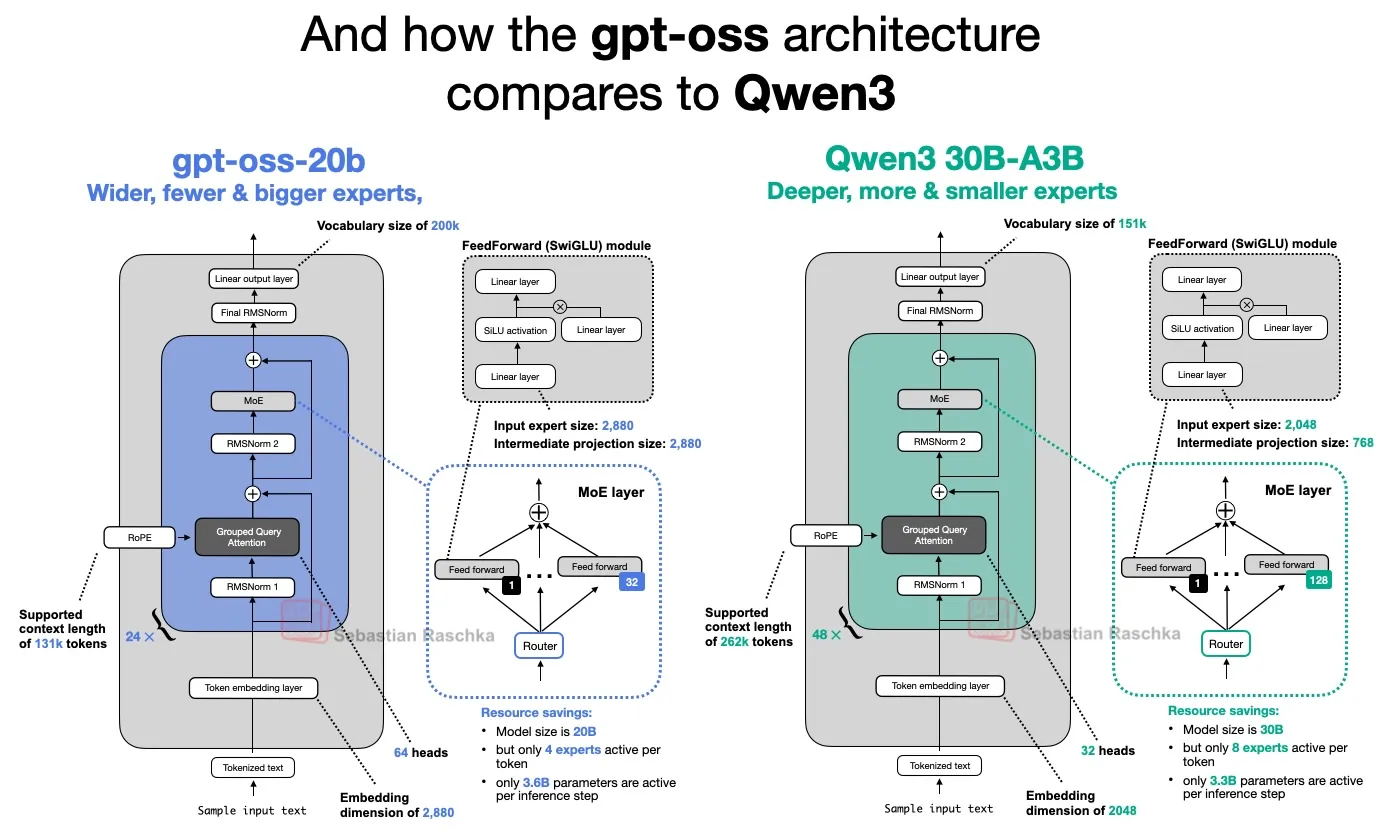
Source article
From DeepSeek V3 to V3.2: Architecture, Sparse Attention, and RL Updates
A DeepSeek-focused follow-up covering the V3.2 architecture updates, sparse attention changes, and the broader RL-related developments around the release.
Read article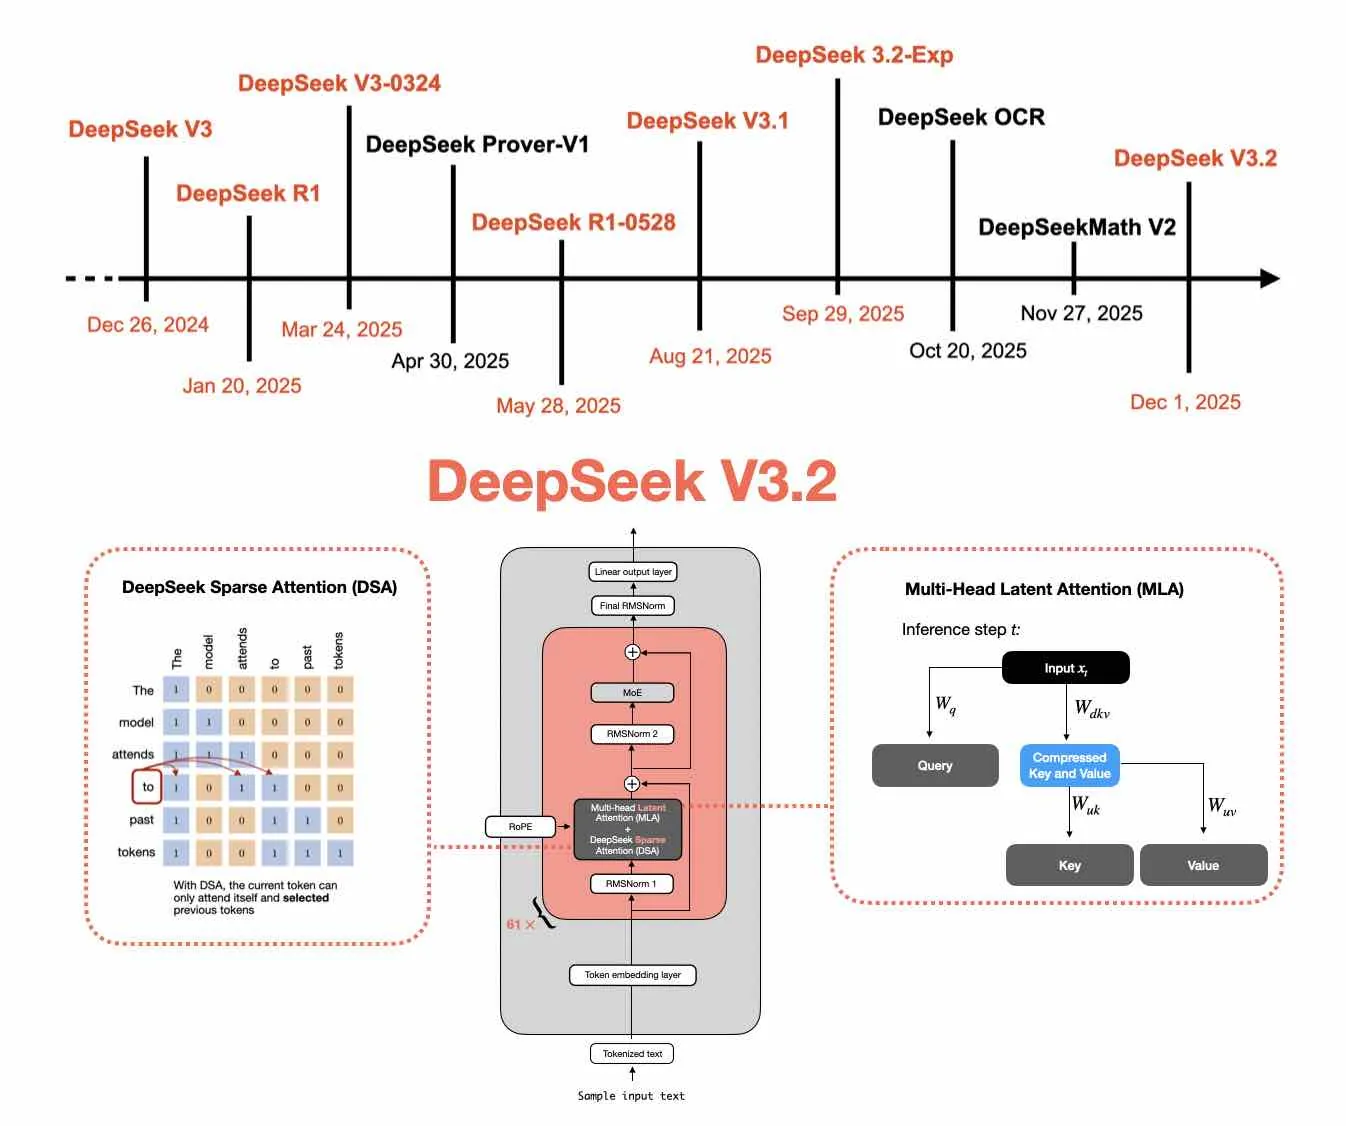
Source article
A Dream of Spring for Open-Weight LLMs
Follow-up article covering the additional open-weight architecture releases from early 2026, including the newer MiniMax, Qwen, Ling, and Sarvam families.
Read article
Source article
A Visual Guide to Attention Variants in Modern LLMs
A visual overview of MHA, GQA, MLA, sliding-window attention, sparse attention, and hybrid architectures, with examples from the gallery.
Read article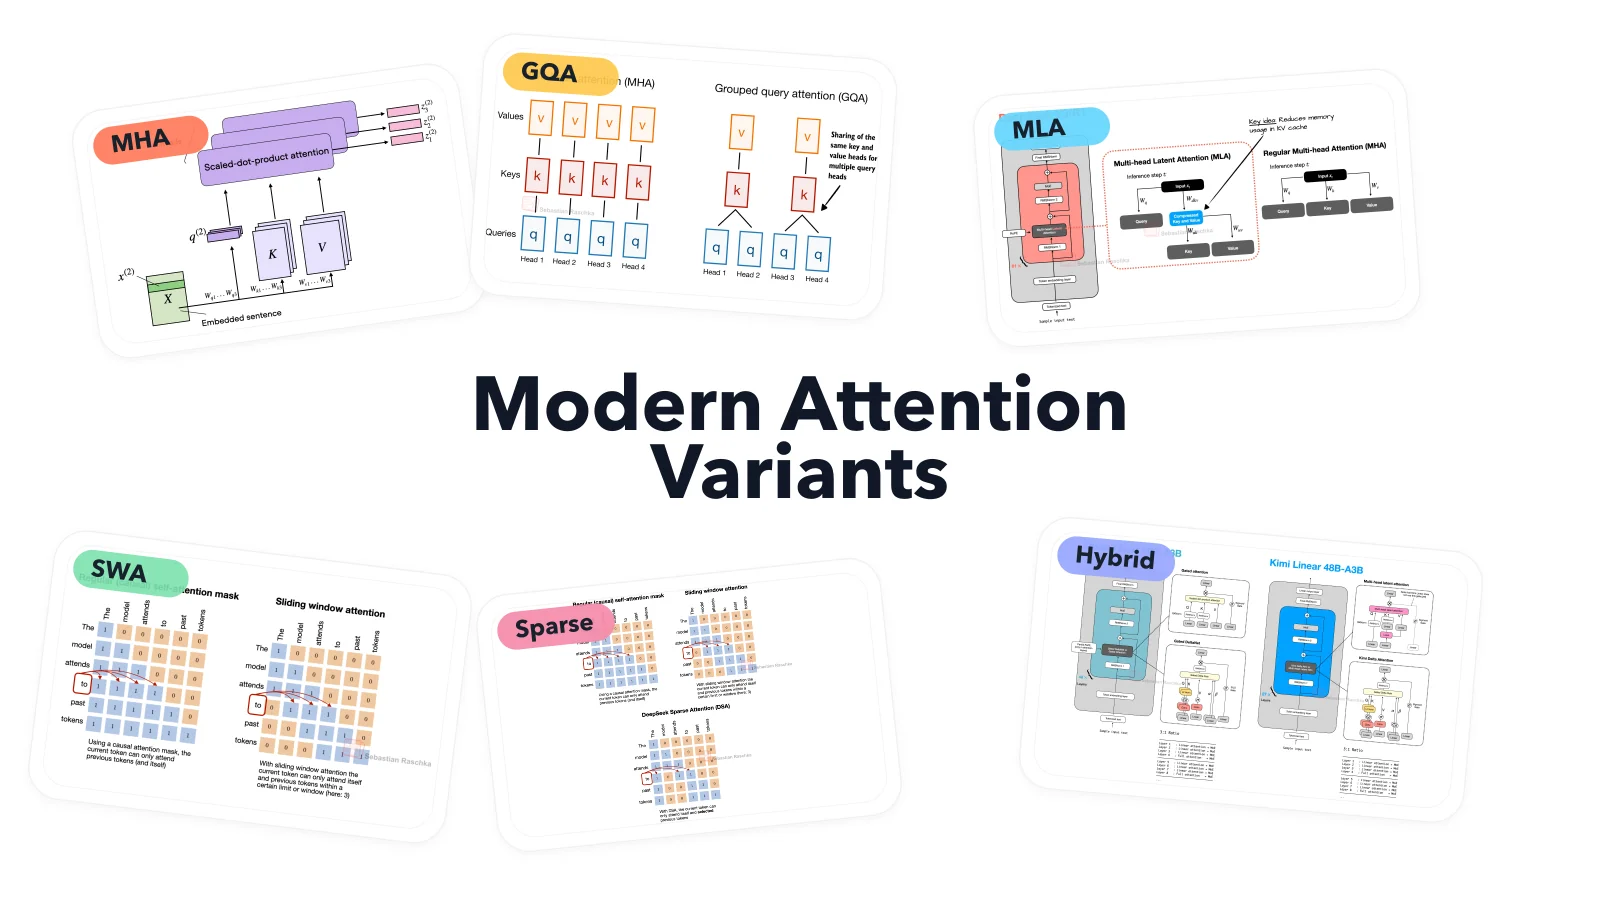
Source article
Recent Developments in LLM Architectures: KV Sharing, mHC, and Compressed Attention
Architecture updates in Gemma 4, Laguna XS.2, ZAYA1, and DeepSeek V4, covering KV sharing, per-layer embeddings, attention budgeting, mHC, and compressed attention.
Read article
Cite / Share
Canonical URL
Short Description
A curated LLM Architecture Gallery with model architecture figures, compact fact sheets, source links, implementation links, and comparison tools for modern language models.
BibTeX
@misc{raschka2026llmarchitecturegallery,
  author = {Raschka, Sebastian},
  title = {LLM Architecture Gallery},
  year = {2026},
  month = {March},
  url = {https://sebastianraschka.com/llm-architecture-gallery/},
  note = {Accessed: 2026-11-18}
}
Suggested Share Text
LLM Architecture Gallery by Sebastian Raschka: https://sebastianraschka.com/llm-architecture-gallery/
Support this project
Your support helps me maintain and expand the gallery. The downloads below are a thank-you for paid Ahead of AI subscribers.
Architecture images
Download all diagrams and use the poster builder to make your own poster.
Download ImagesModel metadata
Download model specs and info as YAML for your own analyses.
Download Metadata