
Kimi K3.1 Pro Architecture
Back to Kimi K3.1 Pro in the gallery
Moonshot AI
Post-trained from Kimi K3, with its 24 Gated MLA layers converted to Gated DeepSeek Sparse Attention. The figure shows the text backbone of this native multimodal model.
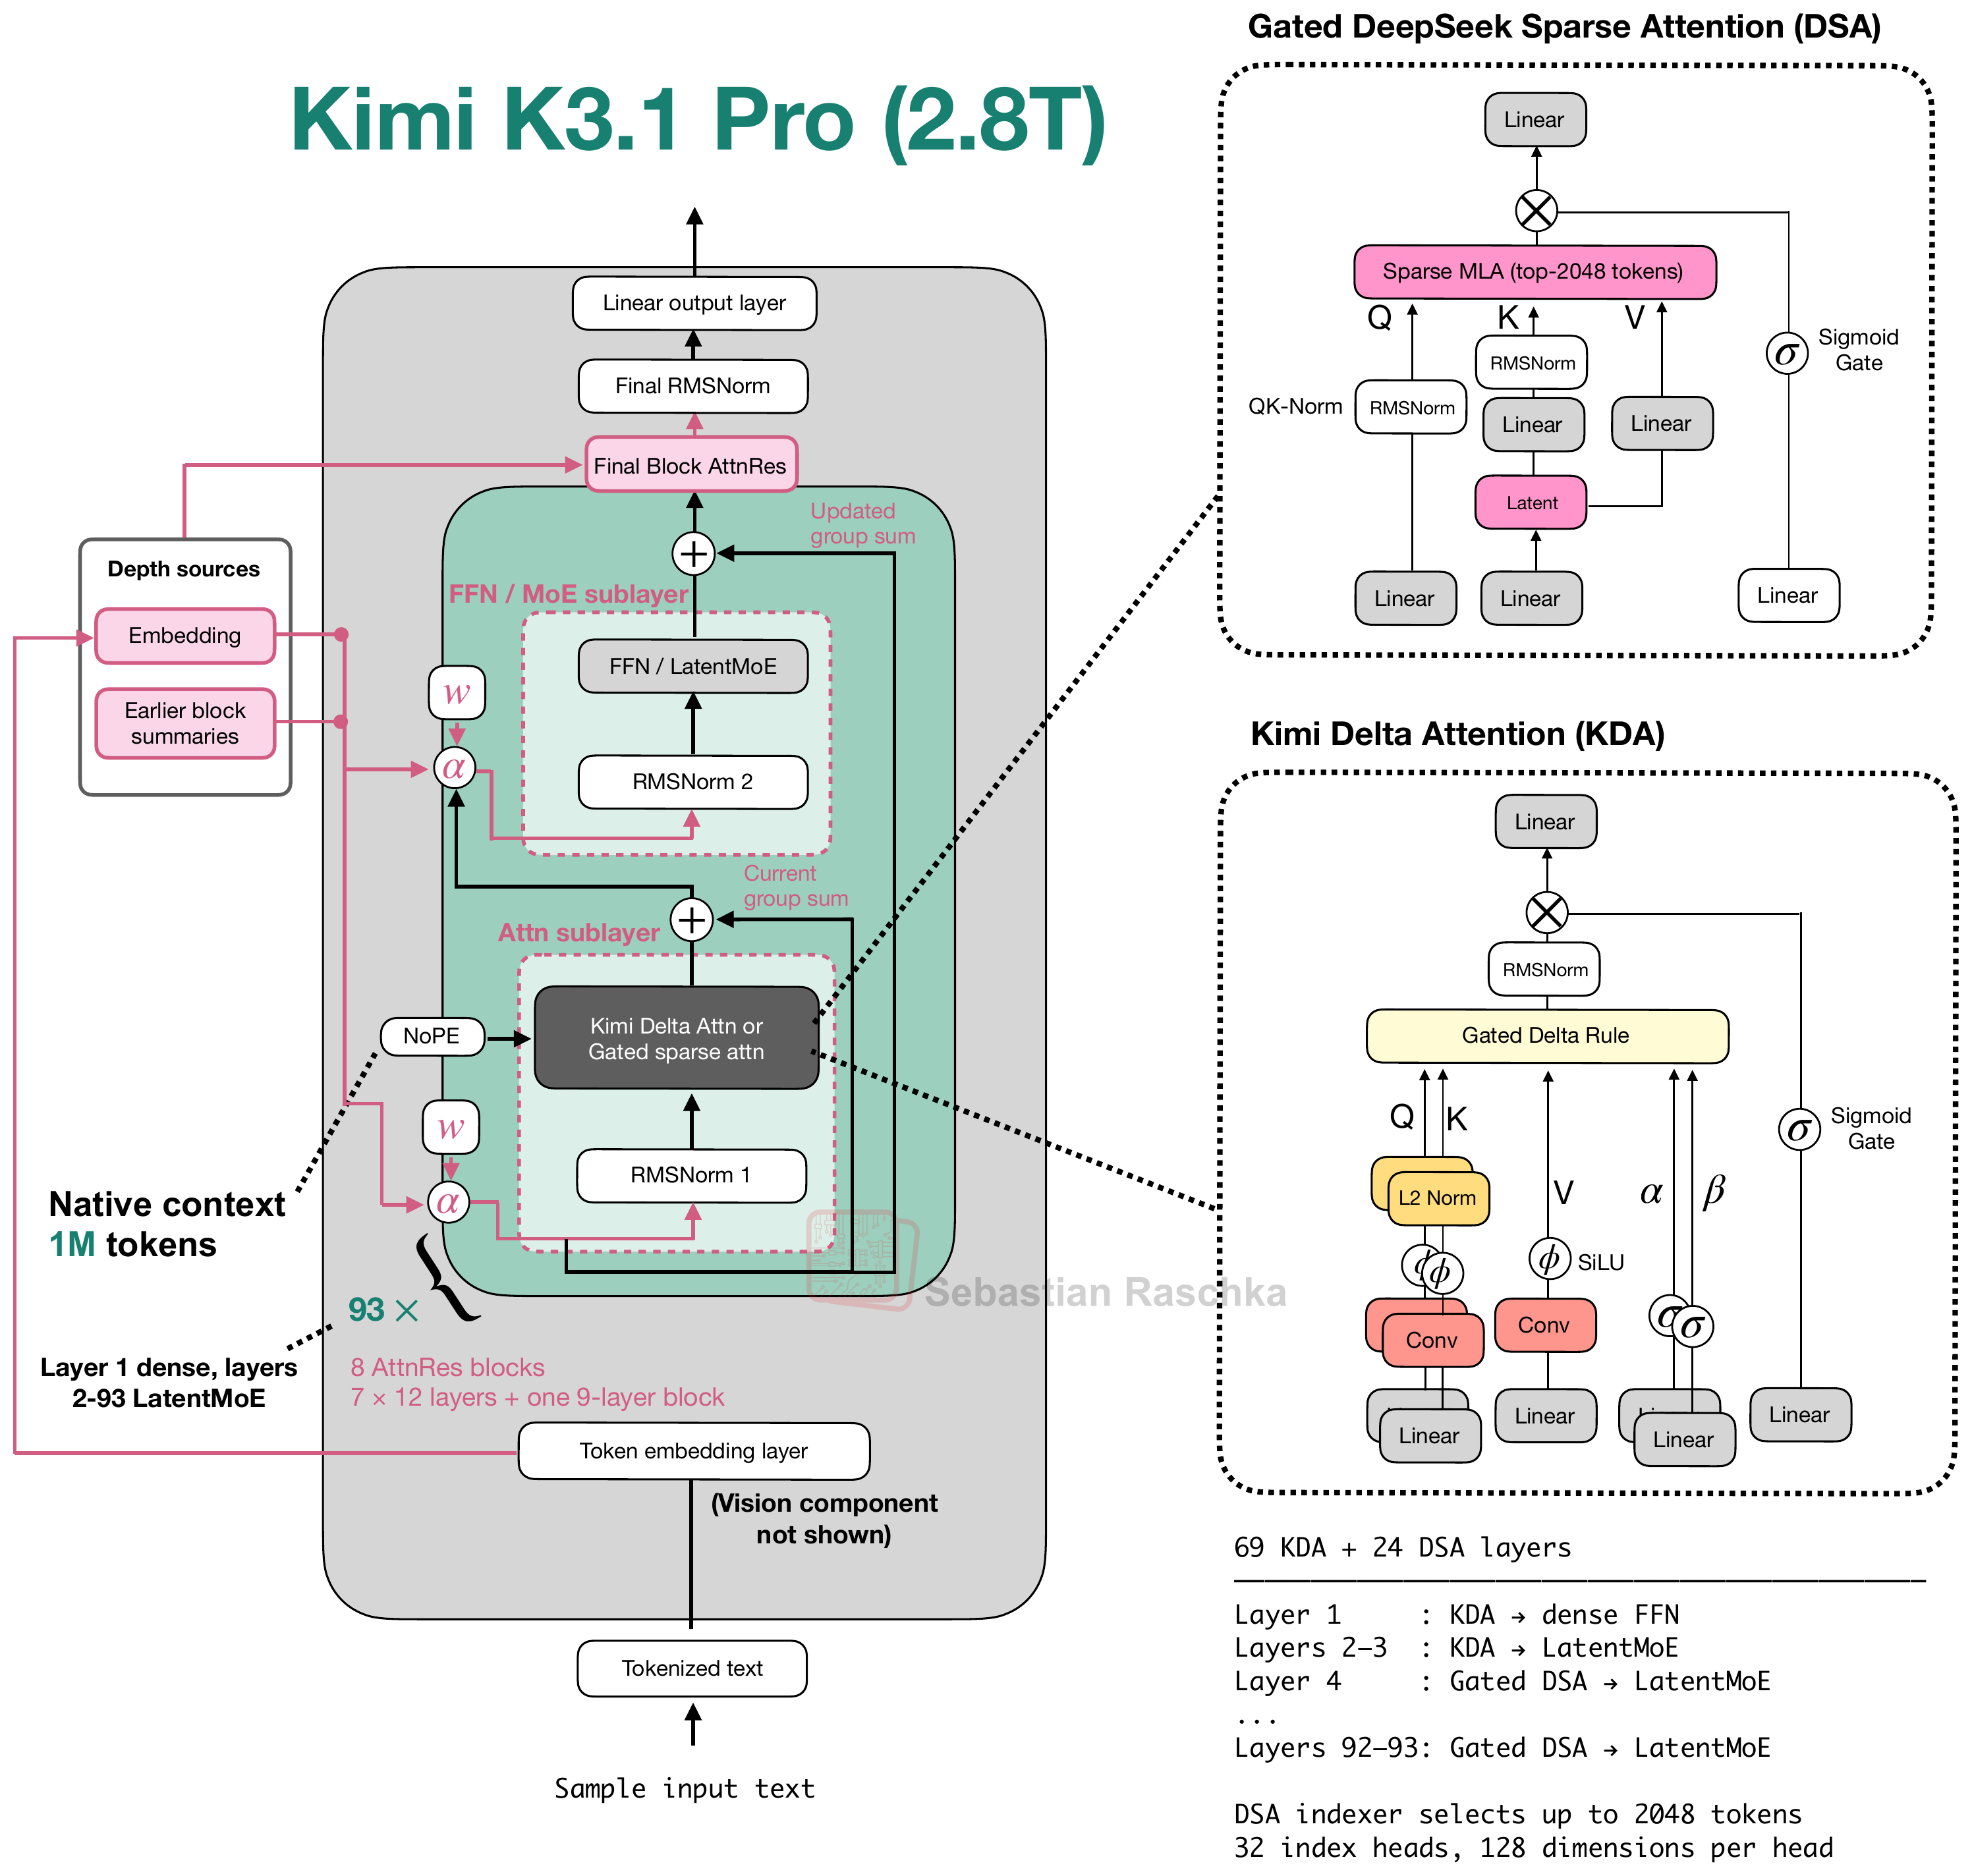
Architecture and specifications
- Scale
- 2.8T total, 104B active (3.7% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 163,840 (~160k)
- License
- Kimi K3.1 Pro License
- Date
- 2026-11-04
- Decoder type
- Sparse hybrid
- Attention
- Kimi Delta Attention and Gated MLA with DeepSeek Sparse Attention and NoPE
- Layer mix
- 69 KDA + 24 Gated DSA
- KV cache / token (bf16) info
- 33 KiB · Low
- Key detail
- Keeps eight Block Attention Residual groups and Stable LatentMoE with 16 of 896 routed experts plus two shared experts per token. The DSA indexer selects up to 2,048 tokens using 32 heads of 128 dimensions.
Training and benchmarks
- Pretraining data
- Not disclosed Derived from Kimi K3; the release card does not disclose a pretraining-token total for K3.1 Pro. Model card
- Post-training methods
- RL The K3.1 Pro update is post-trained from K3 using large-scale joint RL across hundreds of domains. The card does not specify the reward types. Model card