
Qwen3.8-Flash-Next 125B-A6B Architecture
Back to Qwen3.8-Flash-Next 125B-A6B in the gallery
Alibaba Cloud
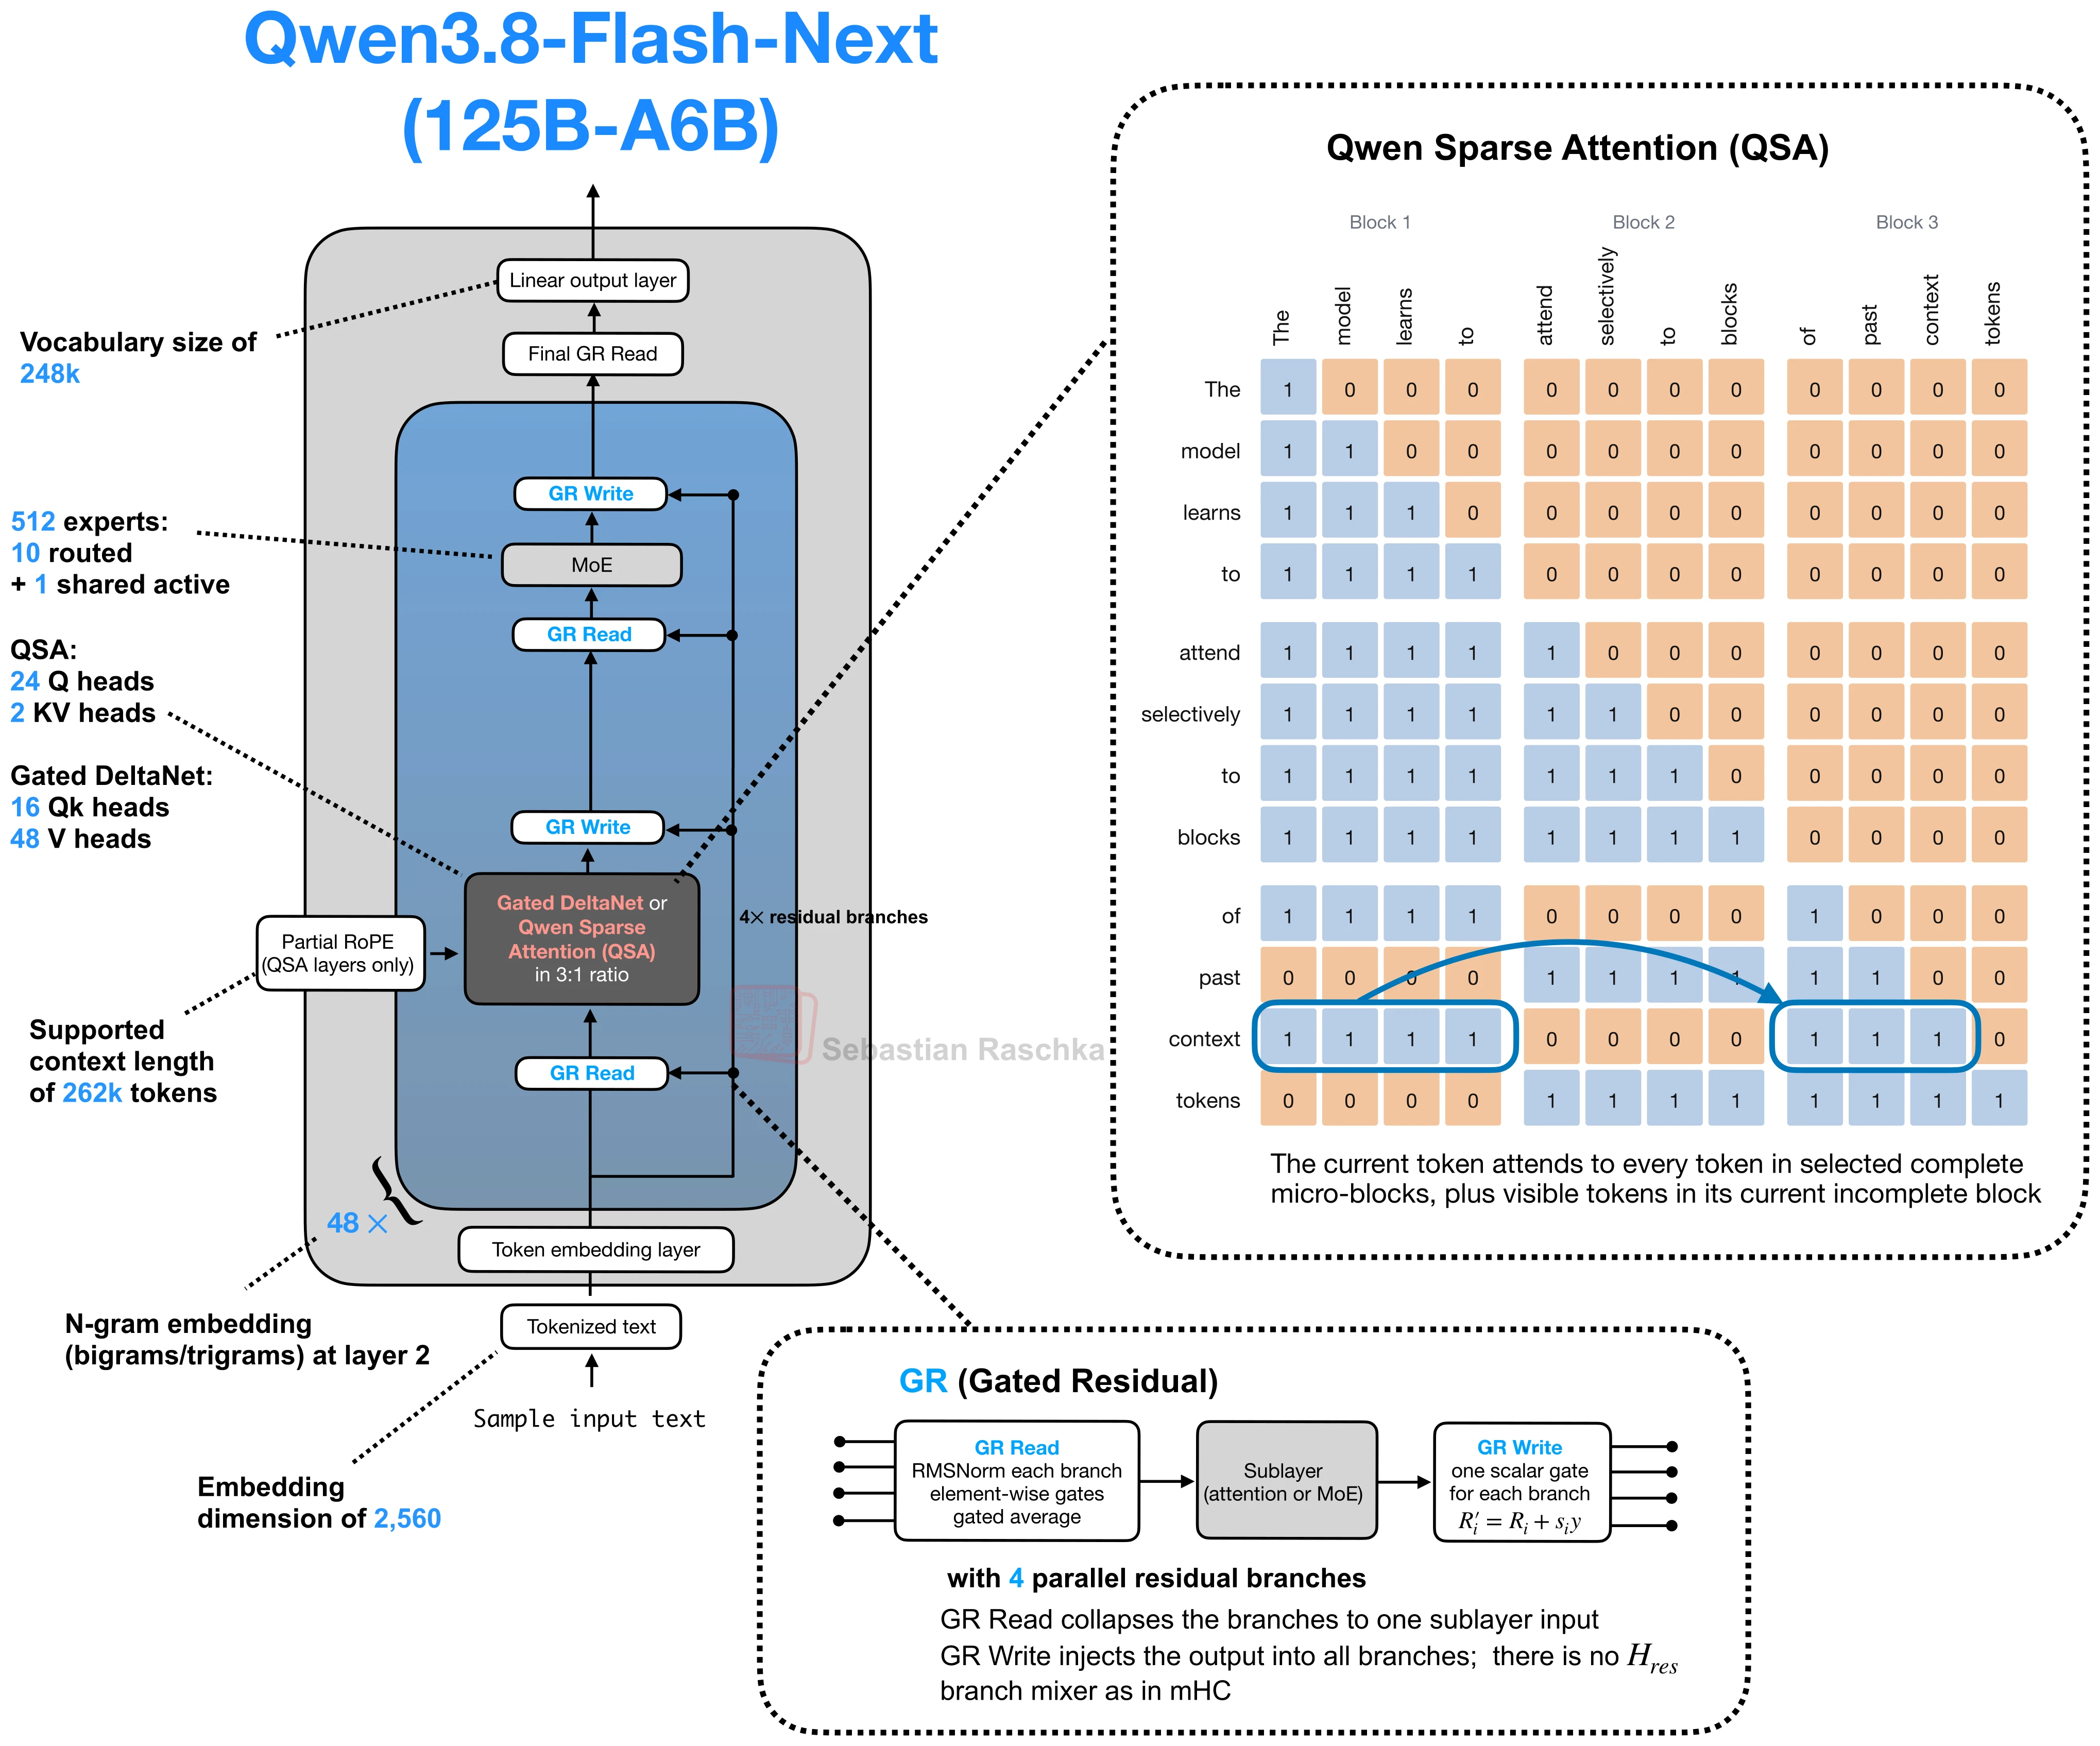
Experimental vision-language MoE whose text backbone combines Gated DeltaNet, micro-block QSA, four-branch gated residuals, and n-gram embeddings; the figure omits the vision encoder and MTP head.
Architecture and specifications
- Scale
- 125B core, 6B active (4.8% active); plus 51B n-gram embeddings and 4B MTP
- Context (tokens)
- 262,144 native (1,000,000 with YaRN)
- Vocabulary
- 248,320 (~248k)
- License
- Qwen Community License 1.0
- Date
- 2026-08-26
- Decoder type
- Sparse hybrid
- Attention
- 3:1 Gated DeltaNet and Qwen Sparse Attention (QSA)
- Layer mix
- 12 QSA + 36 DeltaNet
- KV cache / token (bf16) info
- 24 KiB · Very low
- Key detail
- Replaces full attention with micro-block QSA while using four gated residual branches and a 20M-entry n-gram embedding at layer 2.
Training and benchmarks
- Pretraining data
- Not disclosed The architecture report gives proxy training budgets and relative savings, but no full-model token total. Architecture report
- Post-training methods
- Not disclosed The model card confirms post-training without specifying its methods. Model card
- AA Intelligence Index v5.0 info
- Total score N/A Knowledge Work N/A Coding N/A Science N/A General 26.6