
Muse Spark Open 816B-A42B Architecture
Back to Muse Spark Open 816B-A42B in the gallery
Meta
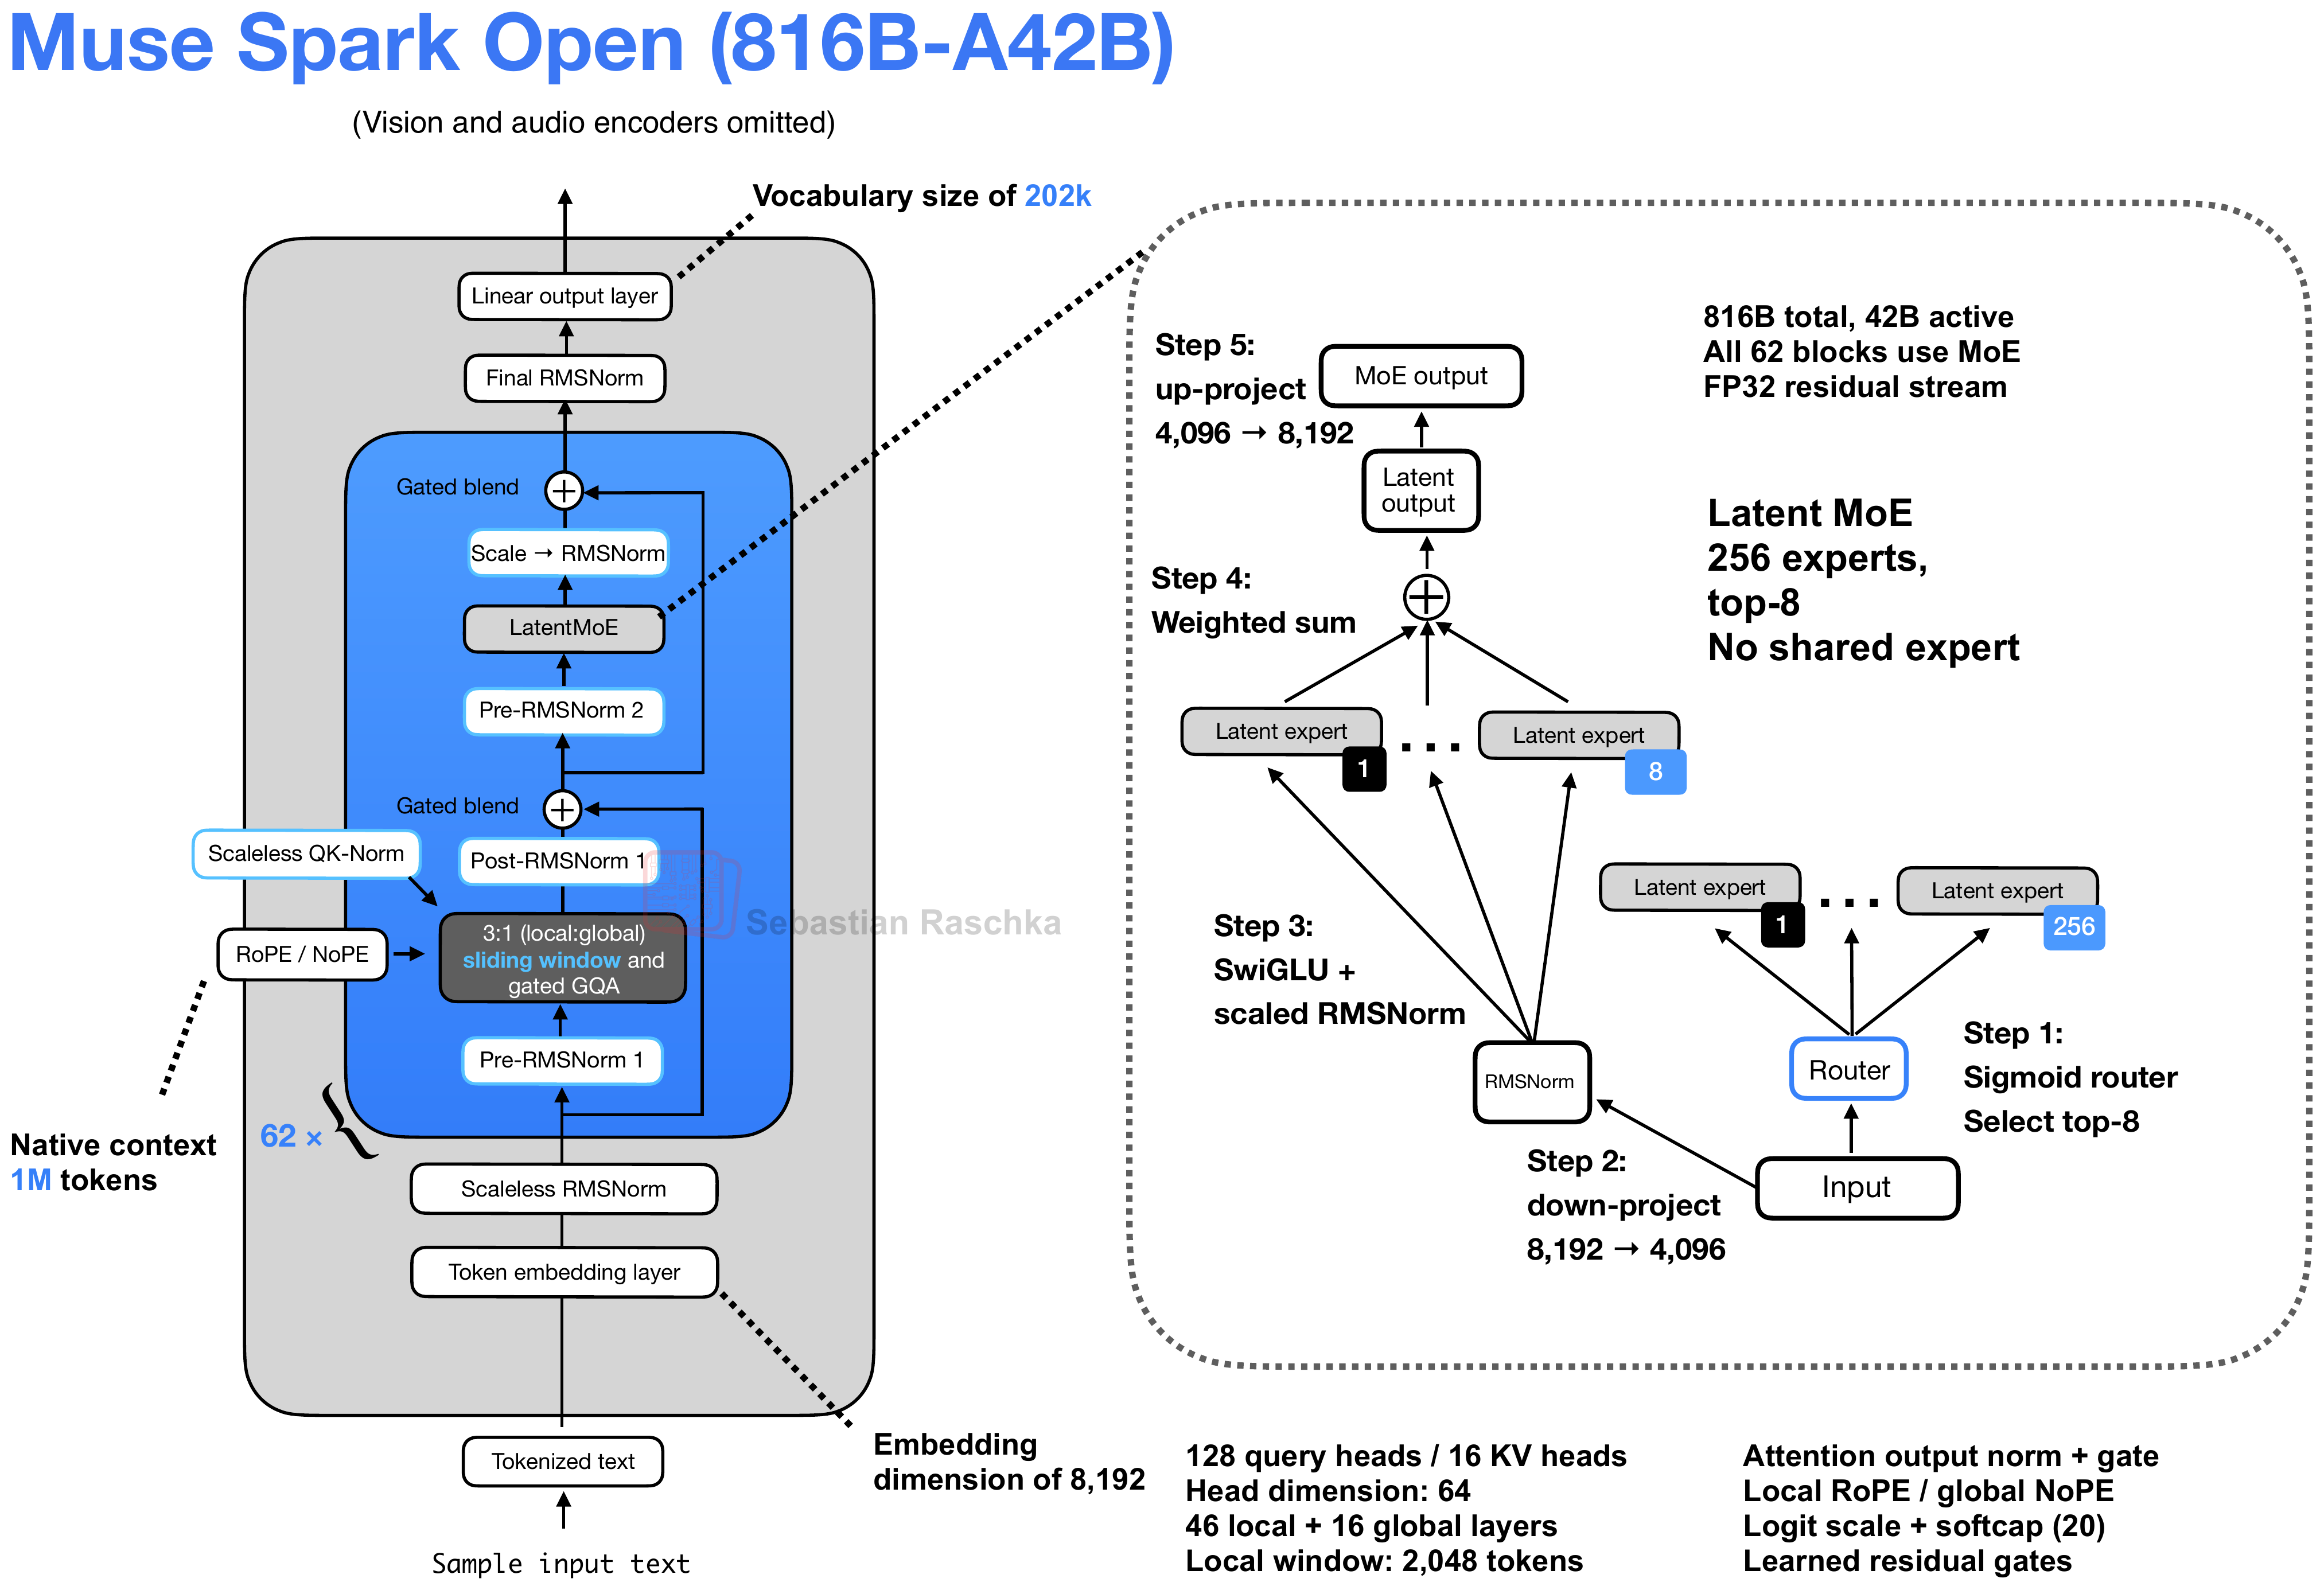
Meta's multimodal MoE model combines 62 latent-expert blocks with gated GQA, local-only RoPE, global NoPE, and learned residual gates; the figure focuses on the text decoder.
Architecture and specifications
- Scale
- 816B total, 42B active (5.1% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 202,048 (~202k)
- License
- Muse Model License
- Date
- 2026-10-15
- Decoder type
- Sparse MoE
- Attention
- Gated GQA with scaleless QK-Norm, local-only RoPE, global NoPE, and 3:1 sliding-window/global attention
- Layer mix
- 46 sliding-window + 16 global gated GQA
- KV cache / token (bf16) info
- 248 KiB · High
- Key detail
- Selects 8 of 256 experts, compresses the expert path from 8,192 to 4,096 dimensions, normalizes each expert output before combining, and uses no shared expert.
Training and benchmarks
- Pretraining data
- Not disclosed The card lists multimodal data sources but does not provide a training-set size or token total. Muse Spark Open model card
- Post-training methods
- Not disclosed Additional safety post-training is confirmed, but the model card does not specify SFT, preference-optimization, or RL methods. Muse Spark Open model card