
Marin Mochi 535B-A23B Architecture
Back to Marin Mochi 535B-A23B in the gallery
Open Athena
Marin's base model combines latent MoE with gated grouped-query attention. Every fourth layer attends to the full context. The other layers use a 2,048-token window.
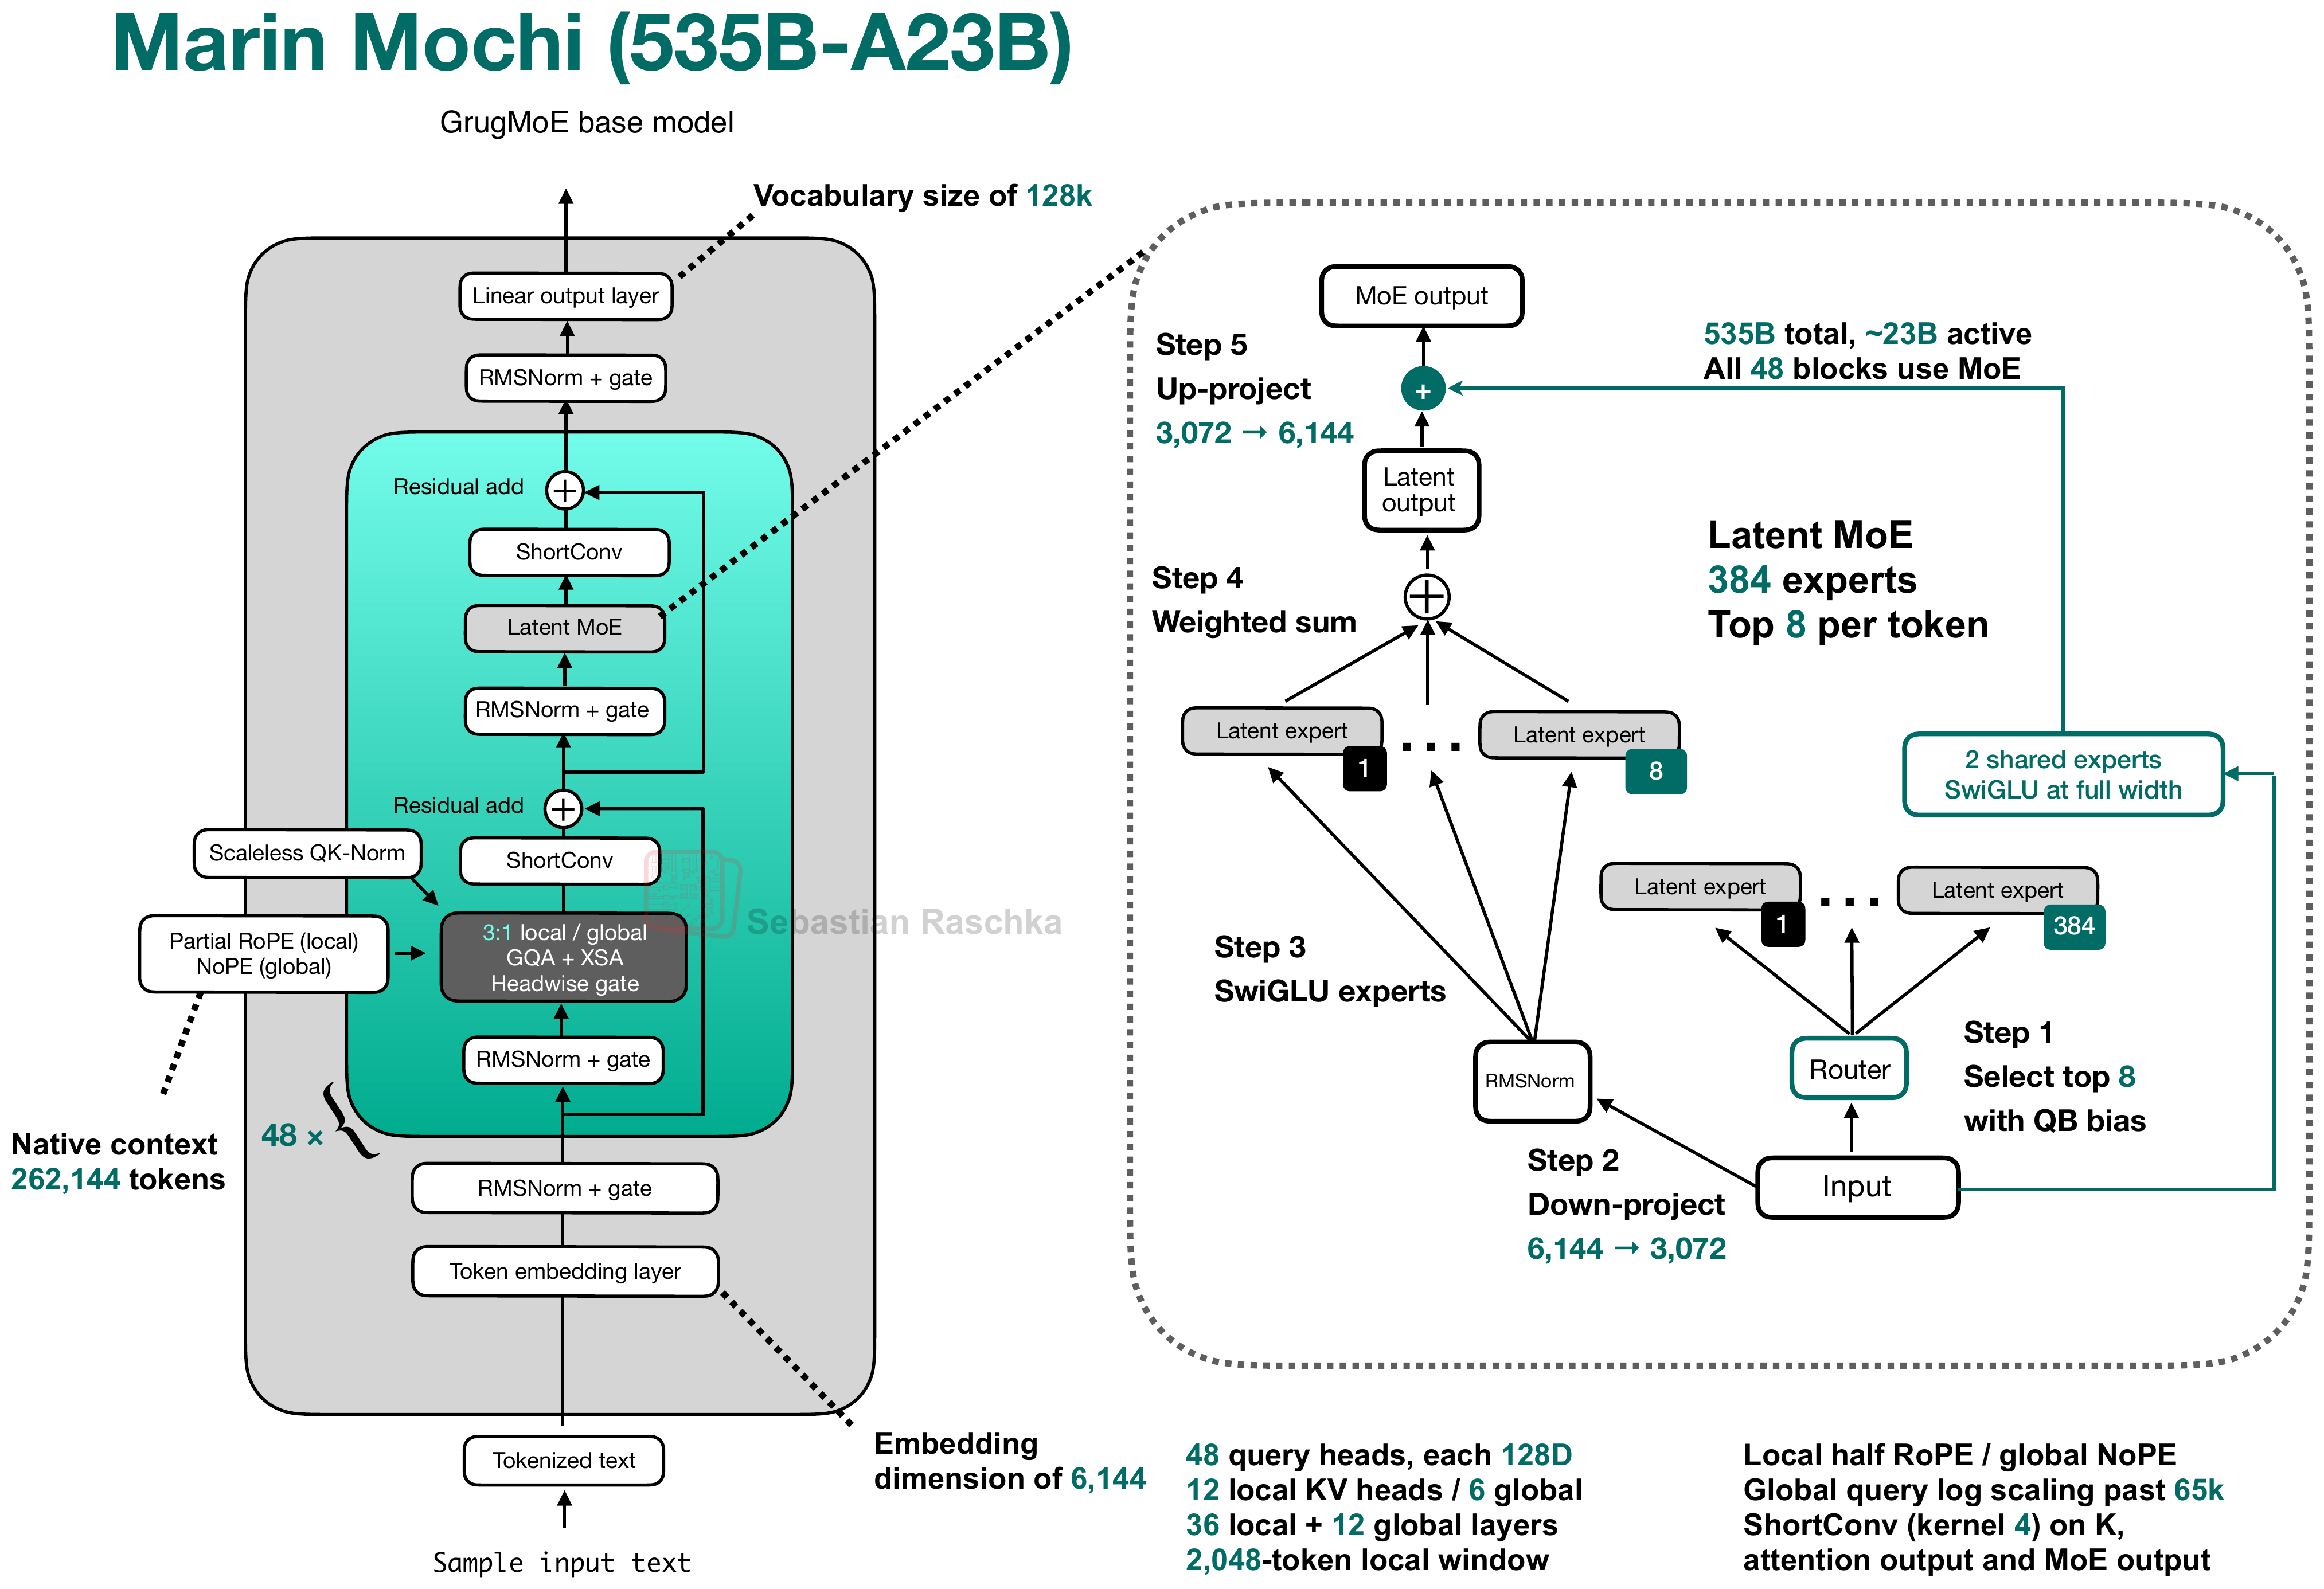
Architecture and specifications
- Scale
- 535.48B total, 22.76B active non-embedding (4.3% active)
- Context (tokens)
- 262,144
- Vocabulary
- 128,256 (~128k)
- License
- OpenMDW 1.1
- Date
- 2026-11-17
- Decoder type
- Sparse MoE
- Attention
- Gated GQA with exclusive self-attention (XSA). Local layers apply RoPE to half of each head, and global layers use NoPE.
- Layer mix
- 36 sliding-window + 12 global GQA
- KV cache / token (bf16) info
- 252 KiB · High
- Key detail
- Each token uses 8 of 384 routed SwiGLU experts at half width (3,072 dimensions) and 2 shared experts at full width (6,144). Kernel-4 short convolutions act on the keys, the attention output, and the MoE output.
Training and benchmarks
- Pretraining data
- 18.2T tokens The pretraining run extended context from 4k to 16k, then 65k and 262k tokens. The final checkpoint is step 393,491. Open Athena checkpoint release · Marin Mochi model card
- Post-training methods
- None (base model) All 57 released checkpoints are base models from the pretraining run. Open Athena checkpoint release