
GLM-5.3-Flash Architecture
Back to GLM-5.3-Flash in the gallery
Z.ai
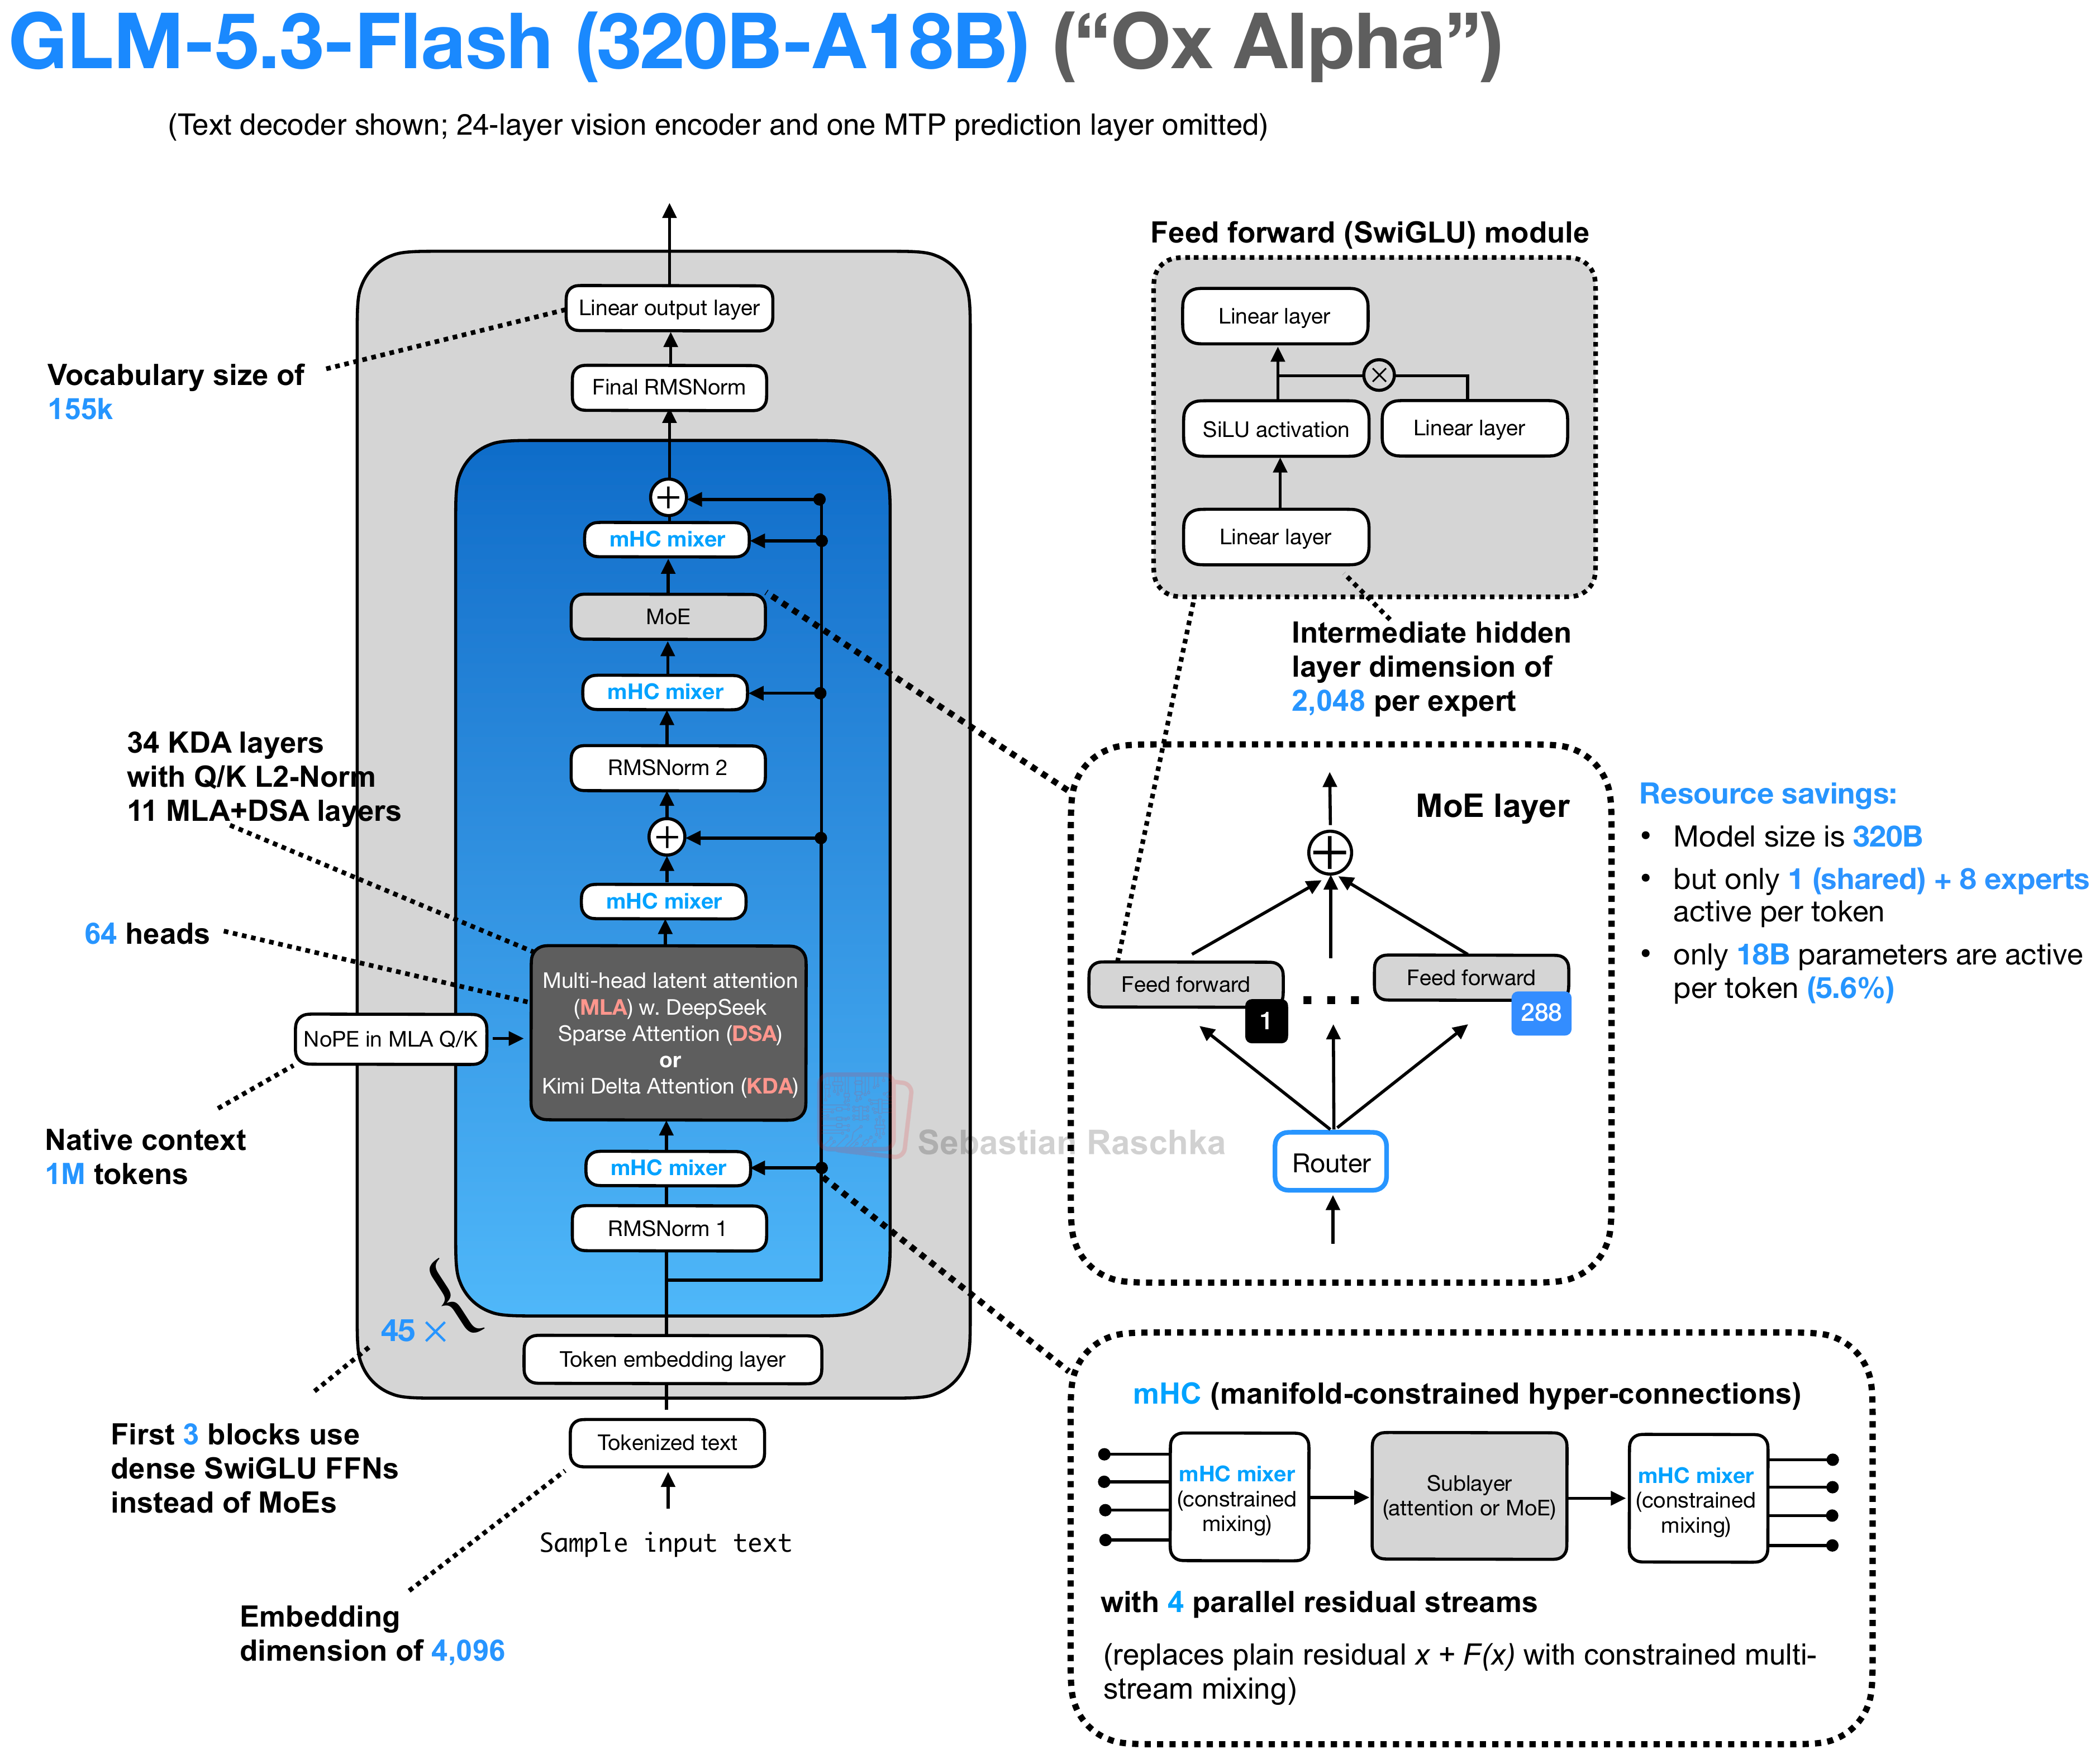
Natively multimodal GLM refresh, previously previewed as Ox Alpha, that replaces most MLA/DSA layers with Kimi Delta Attention and adds four-stream mHC.
Architecture and specifications
- Scale
- 320B total, 18B active (5.6% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 154,880 (~155k)
- License
- MIT License
- Date
- 2026-08-26
- Decoder type
- Sparse hybrid
- Attention
- 3:1 Kimi Delta Attention (Q/K L2 normalization) and MLA with DeepSeek Sparse Attention
- Layer mix
- 34 KDA + 11 MLA/DSA + 1 MTP layer
- KV cache / token (bf16) info
- 11.6875 KiB · Very low
- Key detail
- Mixes 34 Kimi Delta Attention layers with 11 MLA/DSA layers and routes residuals through four mHC streams.
Training and benchmarks
- Pretraining data
- 30T-token multimodal corpus Reported corpus size for a newly trained base; a separate tokens-seen total is not given. GLM-5.3 Flash release
- Post-training methods
- RL The release describes frontend-coding RL with environment feedback; other alignment stages are not itemized. GLM-5.3 Flash release