
ERNIE 5.5 Flash Base Architecture
Back to ERNIE 5.5 Flash Base in the gallery
Baidu
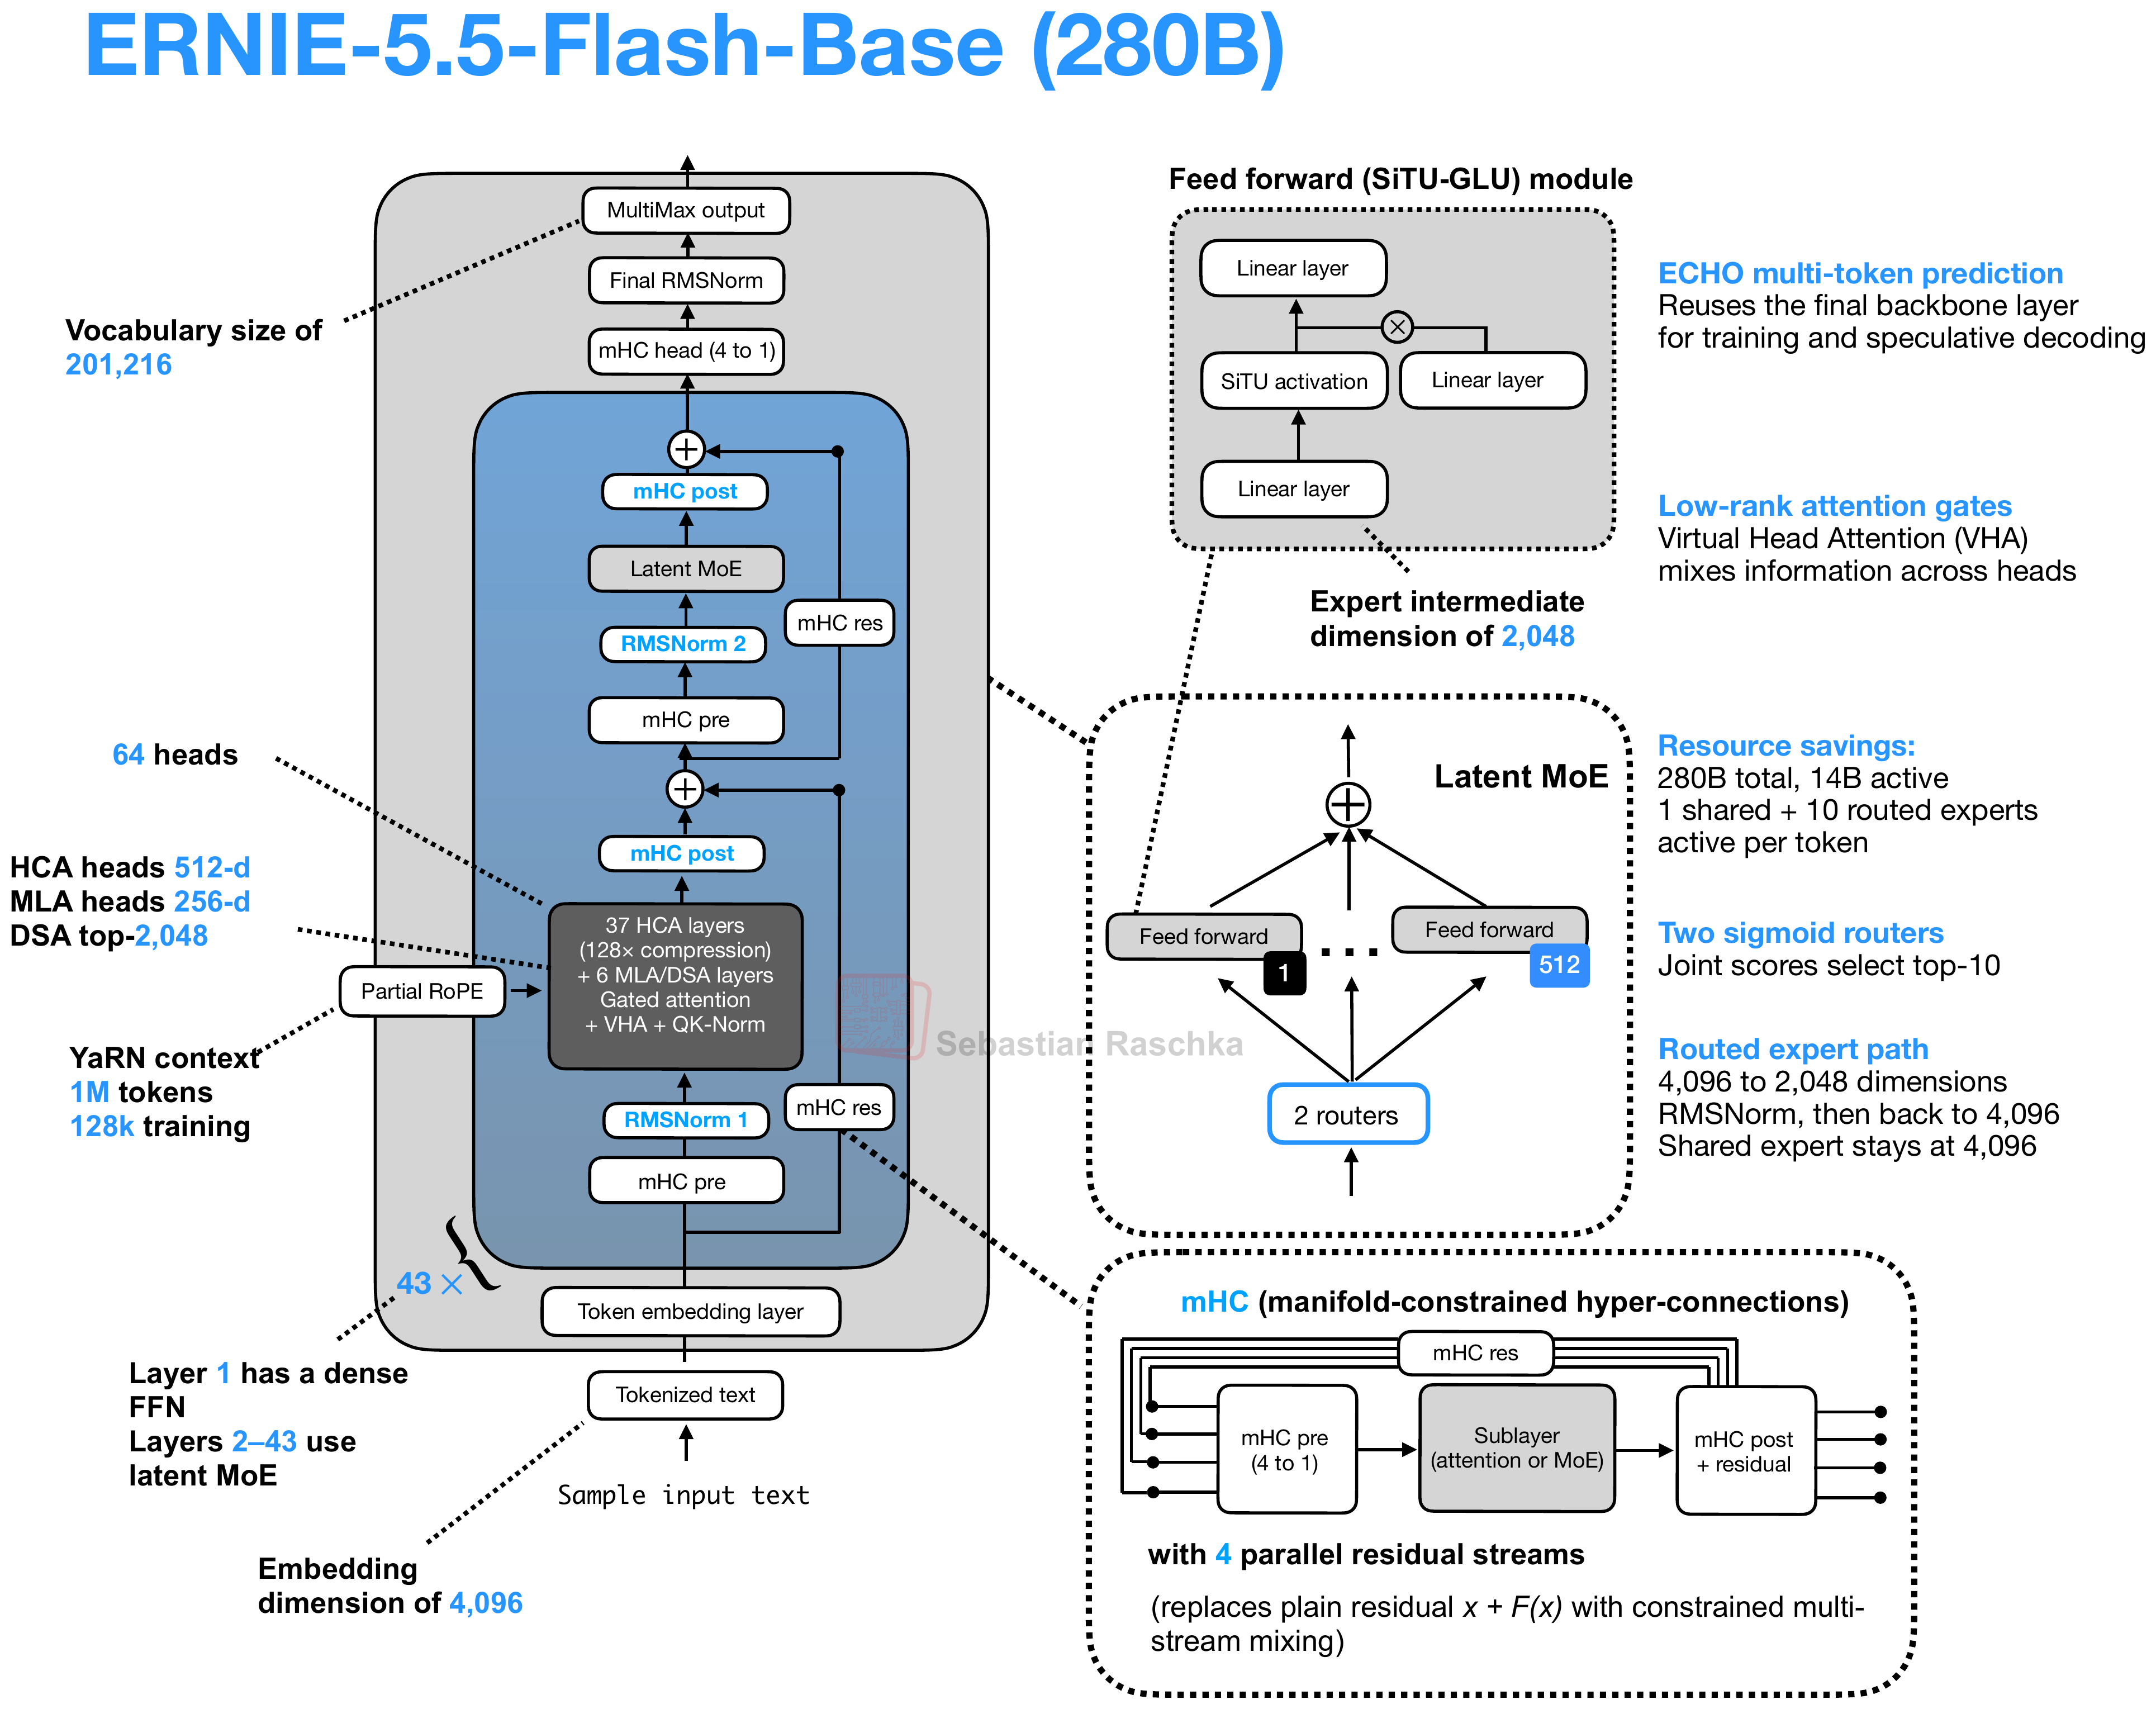
Text-only base model with 37 heavily compressed attention layers and 6 MLA/DSA layers. Pretrained with up to 128K tokens of context; fine-tuning and inference support 1M tokens.
Architecture and specifications
- Scale
- 280B total, 14B active (5.0% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 201,216 (~201k)
- License
- ERNIE 5.5 Flash Base Model License Agreement v1.0
- Date
- 2026-11-05
- Decoder type
- Sparse MoE
- Attention
- Gated HCA and MLA with DeepSeek Sparse Attention, VHA, and QK-Norm
- Layer mix
- 37 HCA + 6 MLA/DSA; 1 dense FFN + 42 latent MoE
- KV cache / token (bf16) info
- 8.54 KiB (growing global cache only) · Very low
- Key detail
- Four-stream mHC surrounds attention and latent MoE. Two sigmoid routers select 10 of 512 routed experts, alongside one always-active shared expert. ECHO reuses the final backbone layer for multi-token prediction.
Training and benchmarks
- Pretraining data
- 33.5T tokens Text-only pretraining from scratch. ERNIE 5.5 Flash Base model card
- Post-training methods
- None (base model) Released at the end of pretraining, before any mid-training or post-training. ERNIE 5.5 Flash Base model card