
Step-5 Preview 600B Architecture
Back to Step-5 Preview 600B in the gallery
StepFun
StepFun's 92-layer MoE pairs 512-token sliding-window attention with sparse GQA for a 1M-token context window; the figure shows the text decoder.
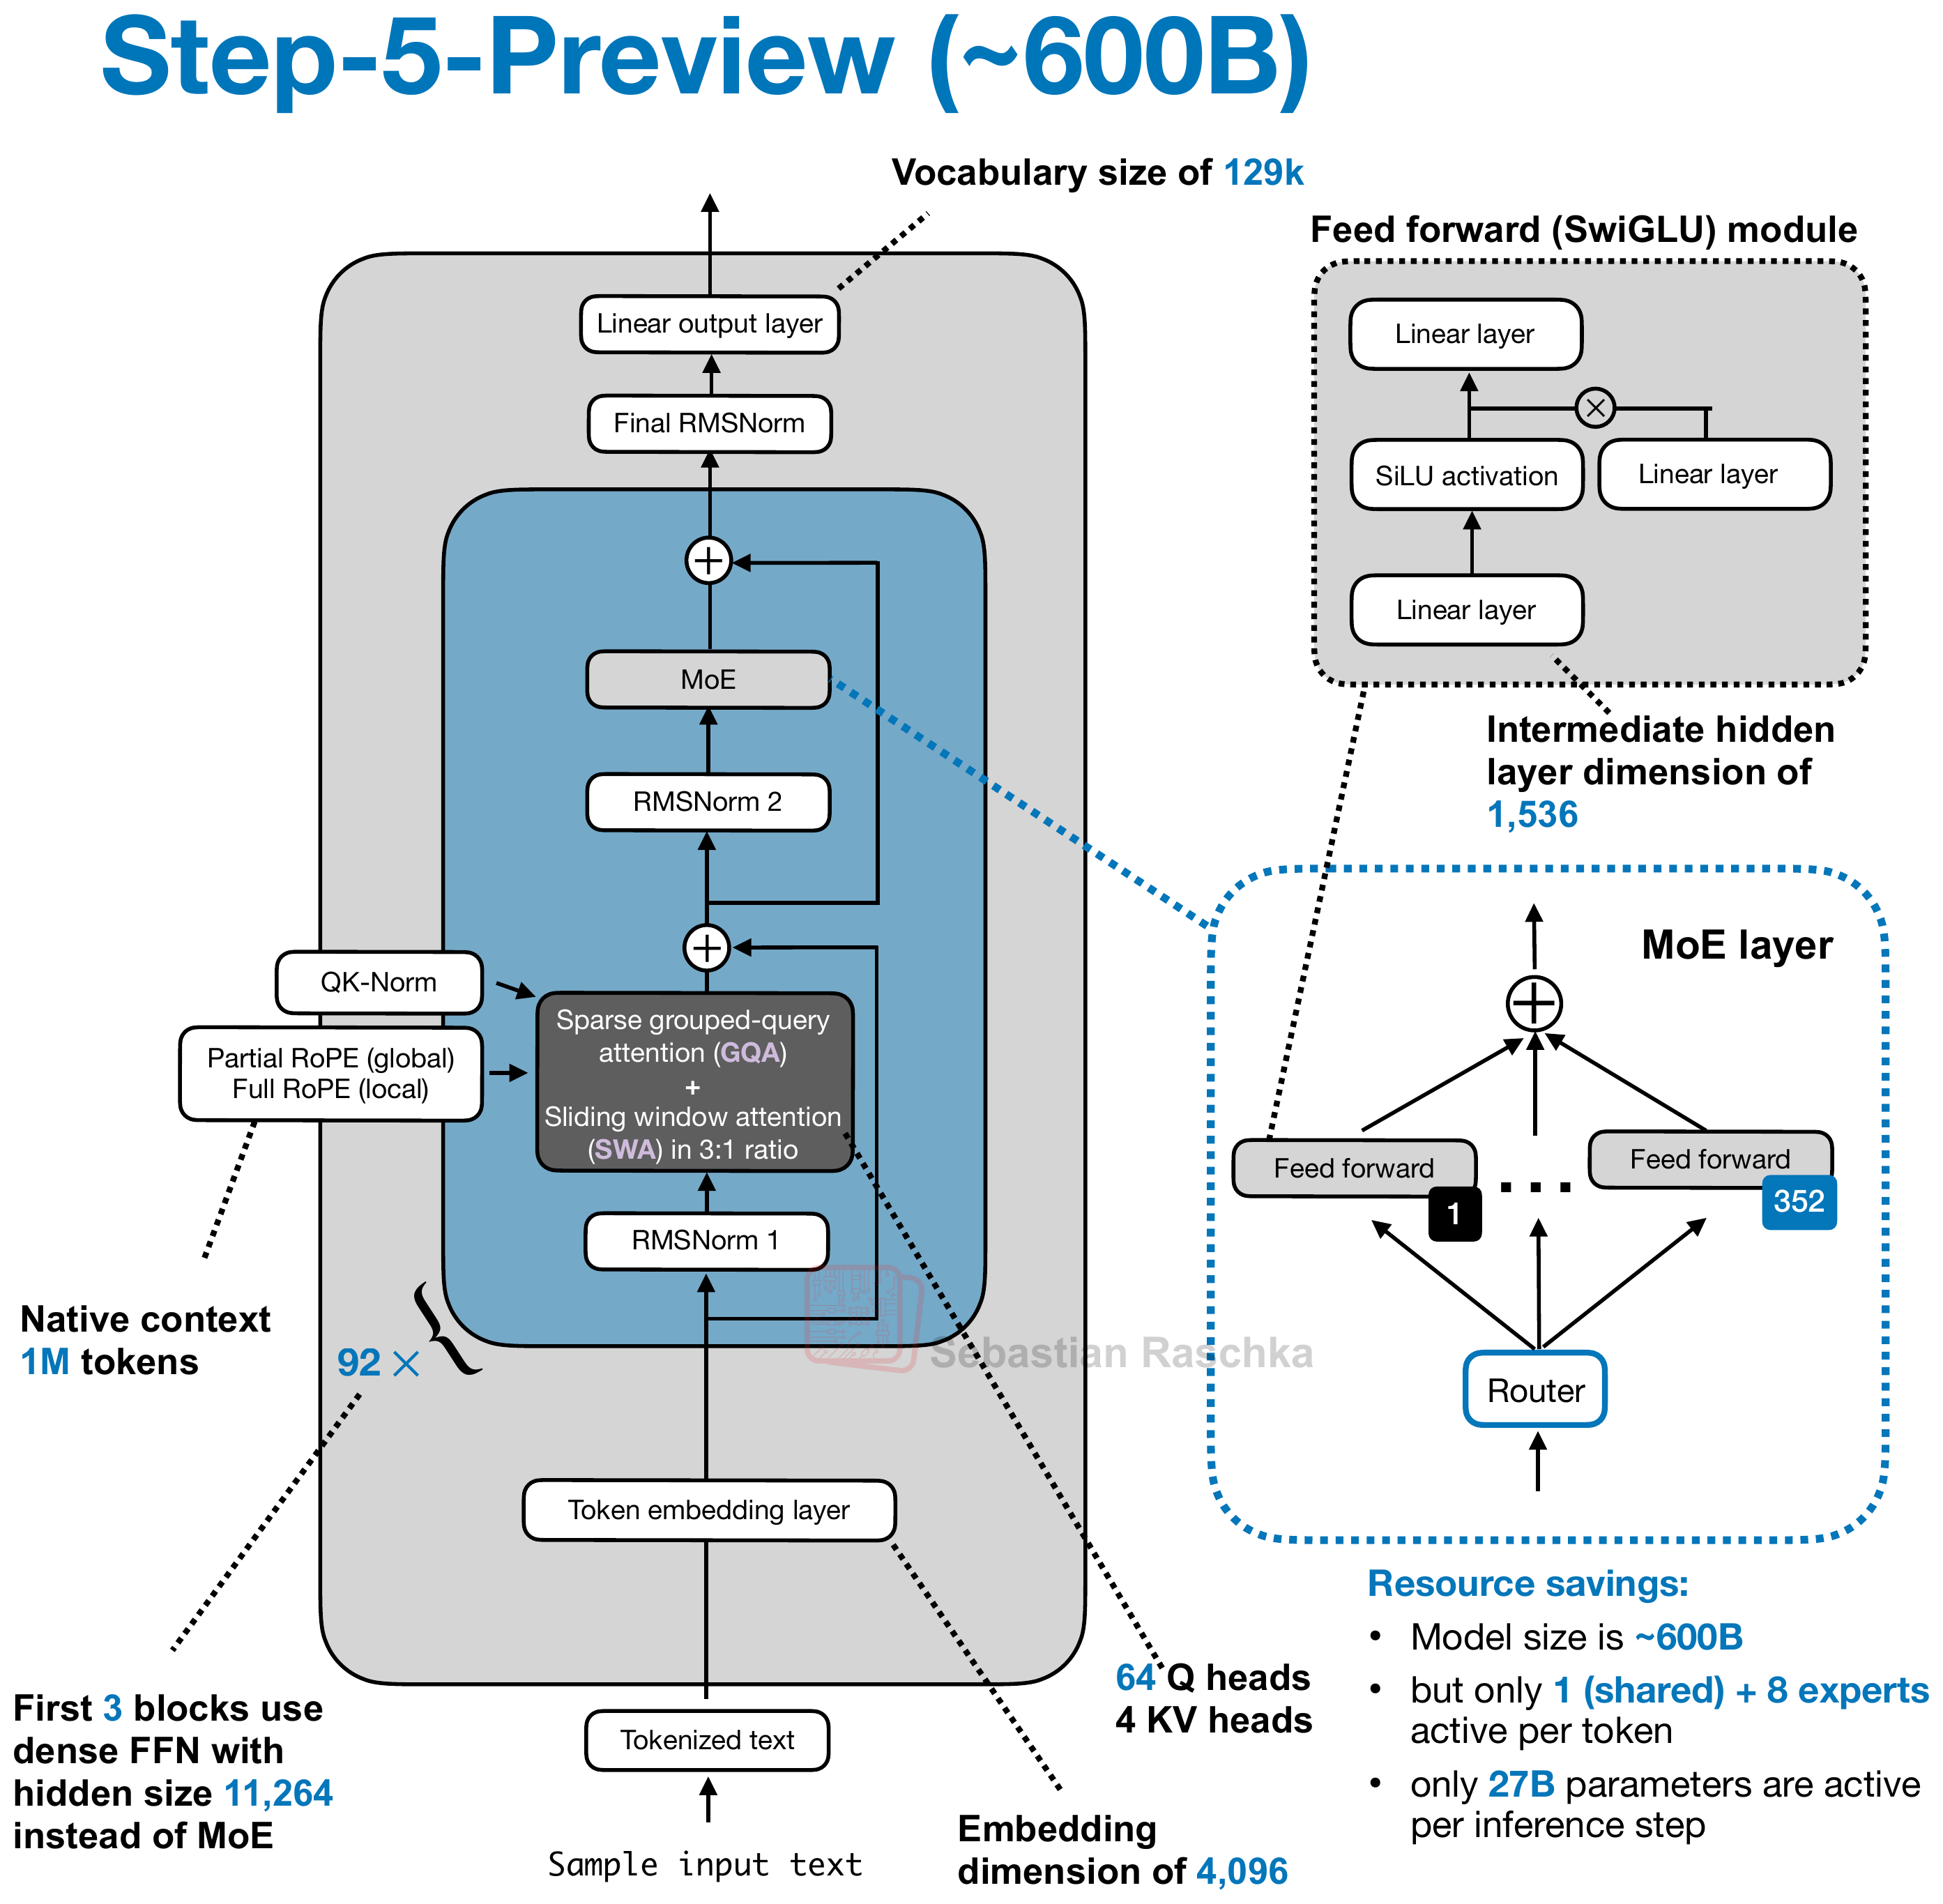
Architecture and specifications
- Scale
- 600B total, 27B active (4.5% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 128,896 (~129k)
- License
- N/A
- Date
- 2026-09-20
- Decoder type
- Sparse MoE
- Attention
- Gated GQA with QK-Norm and 3:1 sliding-window/sparse attention
- Layer mix
- 69 sliding-window + 23 sparse GQA + 3 MTP layers
- KV cache / token (bf16) info
- N/A
- Key detail
- Uses top-512 sparse indexing with block size 8, 352 routed experts with 8 active plus one shared expert, and MTP-3. The first three and final backbone layers use dense FFNs with intermediate size 13,824.
Training and benchmarks
- Pretraining data
- Not disclosed The official training overview does not report a pretraining token count. Training overview
- Post-training methods
- SFT, RLVR The overview identifies SFT and agentic RL with verifiable environments, outcome rewards, and a learned critic. Training overview