
Reflection Beam 501B Architecture
Back to Reflection Beam 501B in the gallery
Reflection
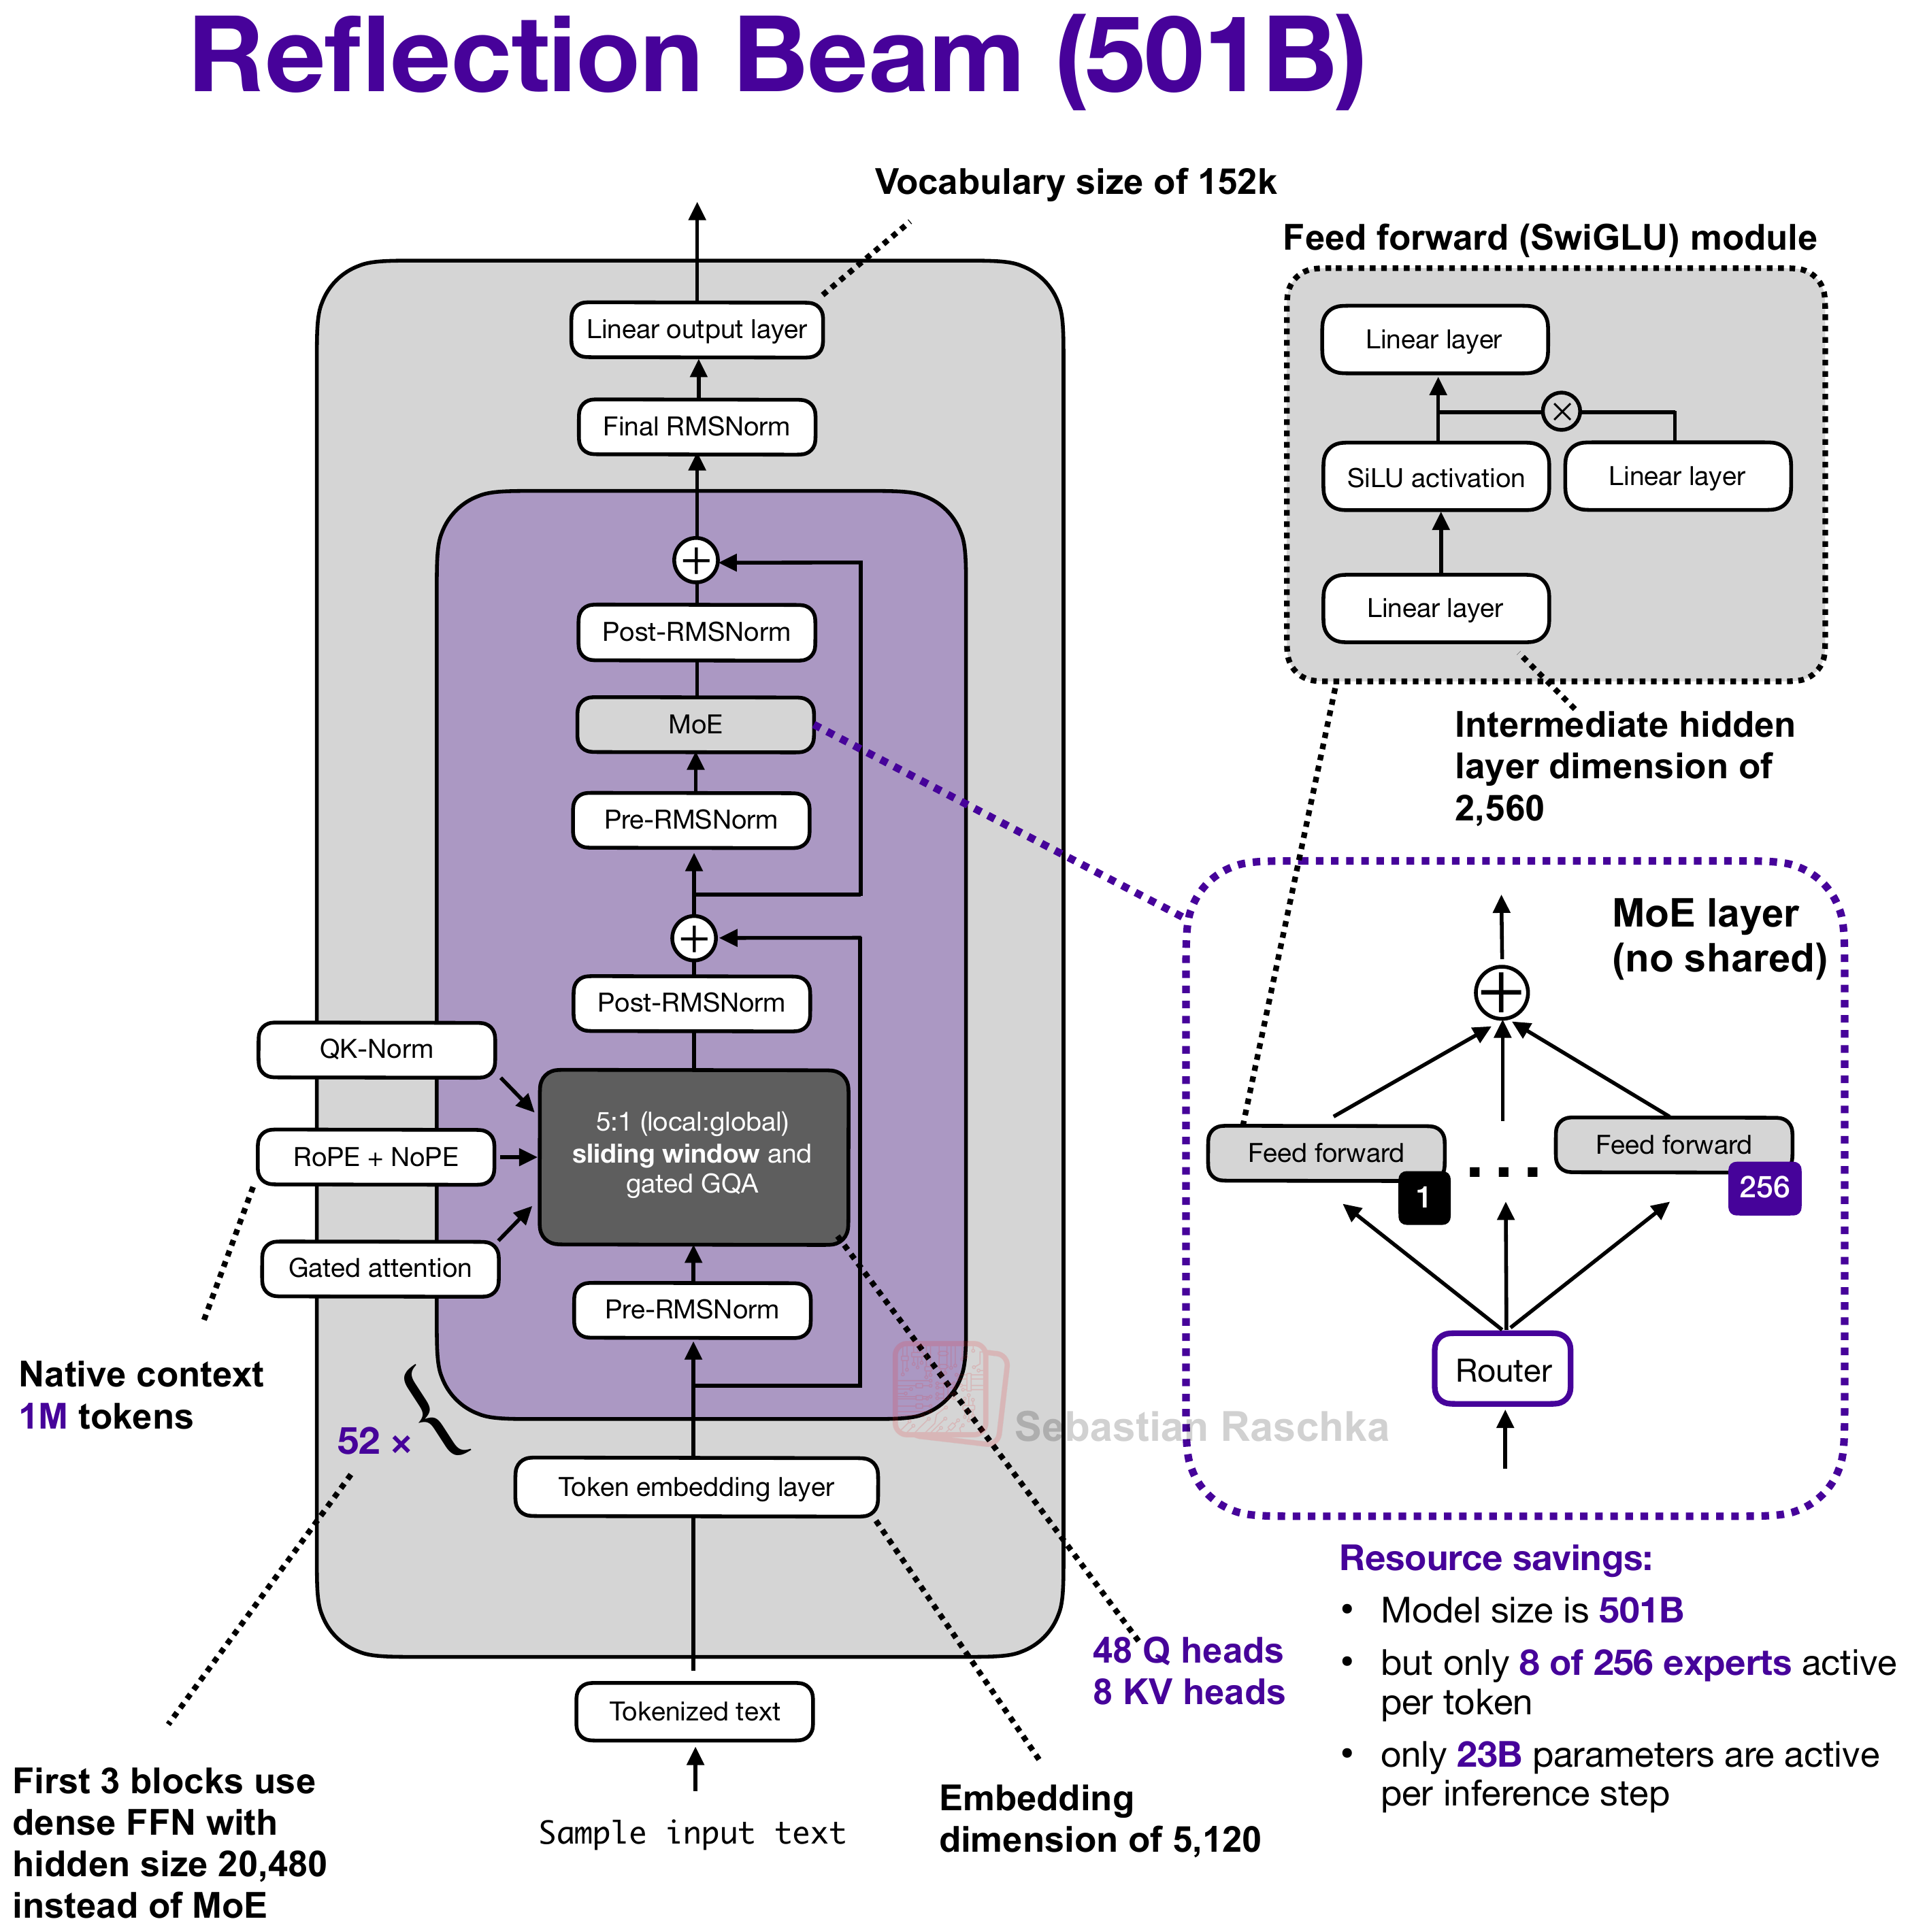
Text-only MoE decoder with three dense FFN layers followed by 49 expert layers. Each MoE layer activates 8 of 256 experts without a shared expert.
Architecture and specifications
- Scale
- 501.3B total, 23.4B active (4.7% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 151,936 (~152k)
- License
- Apache License 2.0
- Date
- 2026-10-16
- Decoder type
- Sparse MoE
- Attention
- Gated GQA with QK-Norm and sliding-window/global attention
- Layer mix
- 43 sliding-window + 9 global GQA
- KV cache / token (bf16) info
- 208 KiB · High
- Key detail
- Combines 512-token local RoPE attention with global NoPE and query scaling. Uses sandwich RMSNorm, depth-scaled residuals, and a final logit softcap of 30.
Training and benchmarks
- Pretraining data
- Not disclosed The card describes the text/code corpus and mid-training sources without a token count. Model card
- Post-training methods
- RL RL environments cover coding, agentic tasks, and STEM; the full recipe is not disclosed. Model card