
Ornith 1.5 35B-A3B Architecture
Back to Ornith 1.5 35B-A3B in the gallery
Ornith
Uses the same sparse-hybrid decoder geometry as Qwen3.6 35B-A3B, paired with Ornith's self-improvement training recipe.
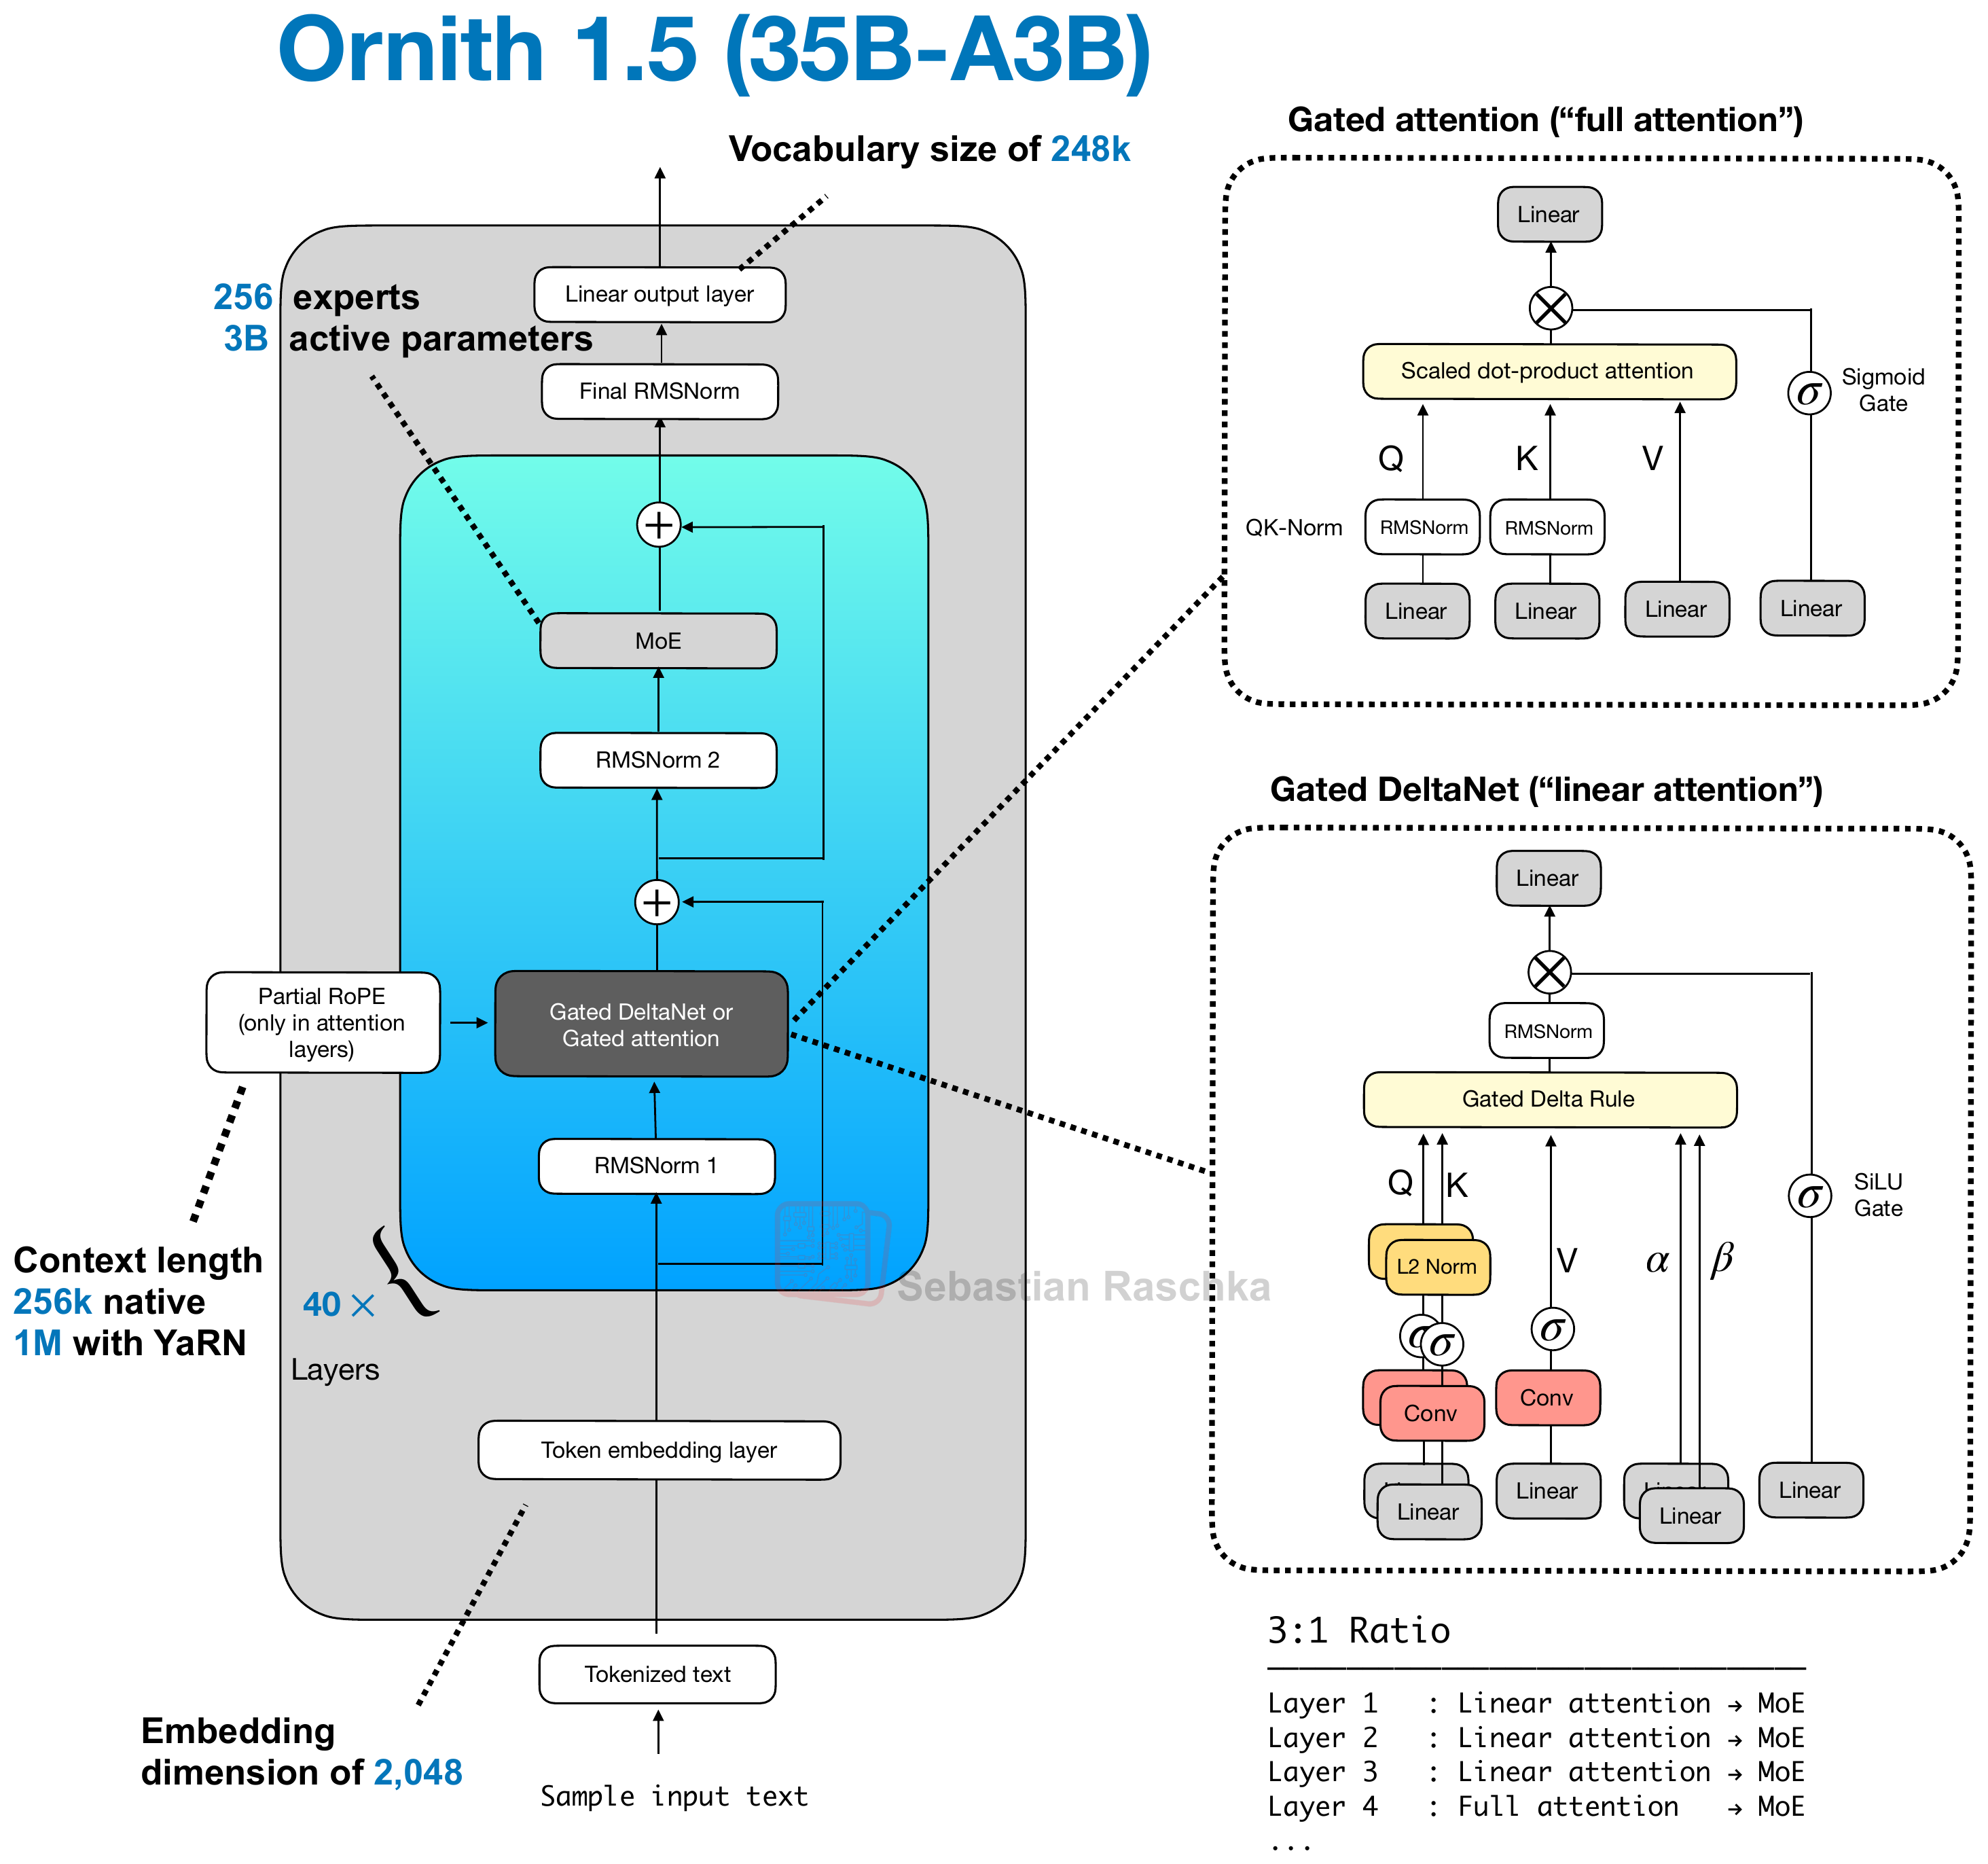
Architecture and specifications
- Scale
- 35B total, 3B active (8.6% active)
- Context (tokens)
- 262,144 native (1,000,000 with YaRN)
- Vocabulary
- 248,320 (~248k)
- License
- MIT License
- Date
- 2026-08-23
- Decoder type
- Sparse hybrid
- Attention
- 3:1 Gated DeltaNet and Gated Attention
- Layer mix
- 10 gated attention + 30 DeltaNet
- KV cache / token (bf16) info
- 20 KiB · Very low
- Key detail
- Matches Qwen3.6 35B-A3B's 40-layer decoder geometry, with 256 routed experts, top-8 routing, and one shared expert.
Training and benchmarks
- Pretraining data
- Not disclosed The card describes its Ornith 1.0 lineage but provides no inherited or additional pretraining-token total. Ornith 1.5 model card
- Post-training methods
- RL GRPO-based self-improvement trains on generated tasks, scaffolds, and agent rollouts. Rewards include correctness on verifiable tasks and broader completion criteria. Ornith 1.5 training details