
Inkling 2 Small Architecture
Back to Inkling 2 Small in the gallery
Thinking Machines Lab
Multimodal sparse MoE with a 48-layer decoder, 8-of-384 expert routing, and block attention residuals.
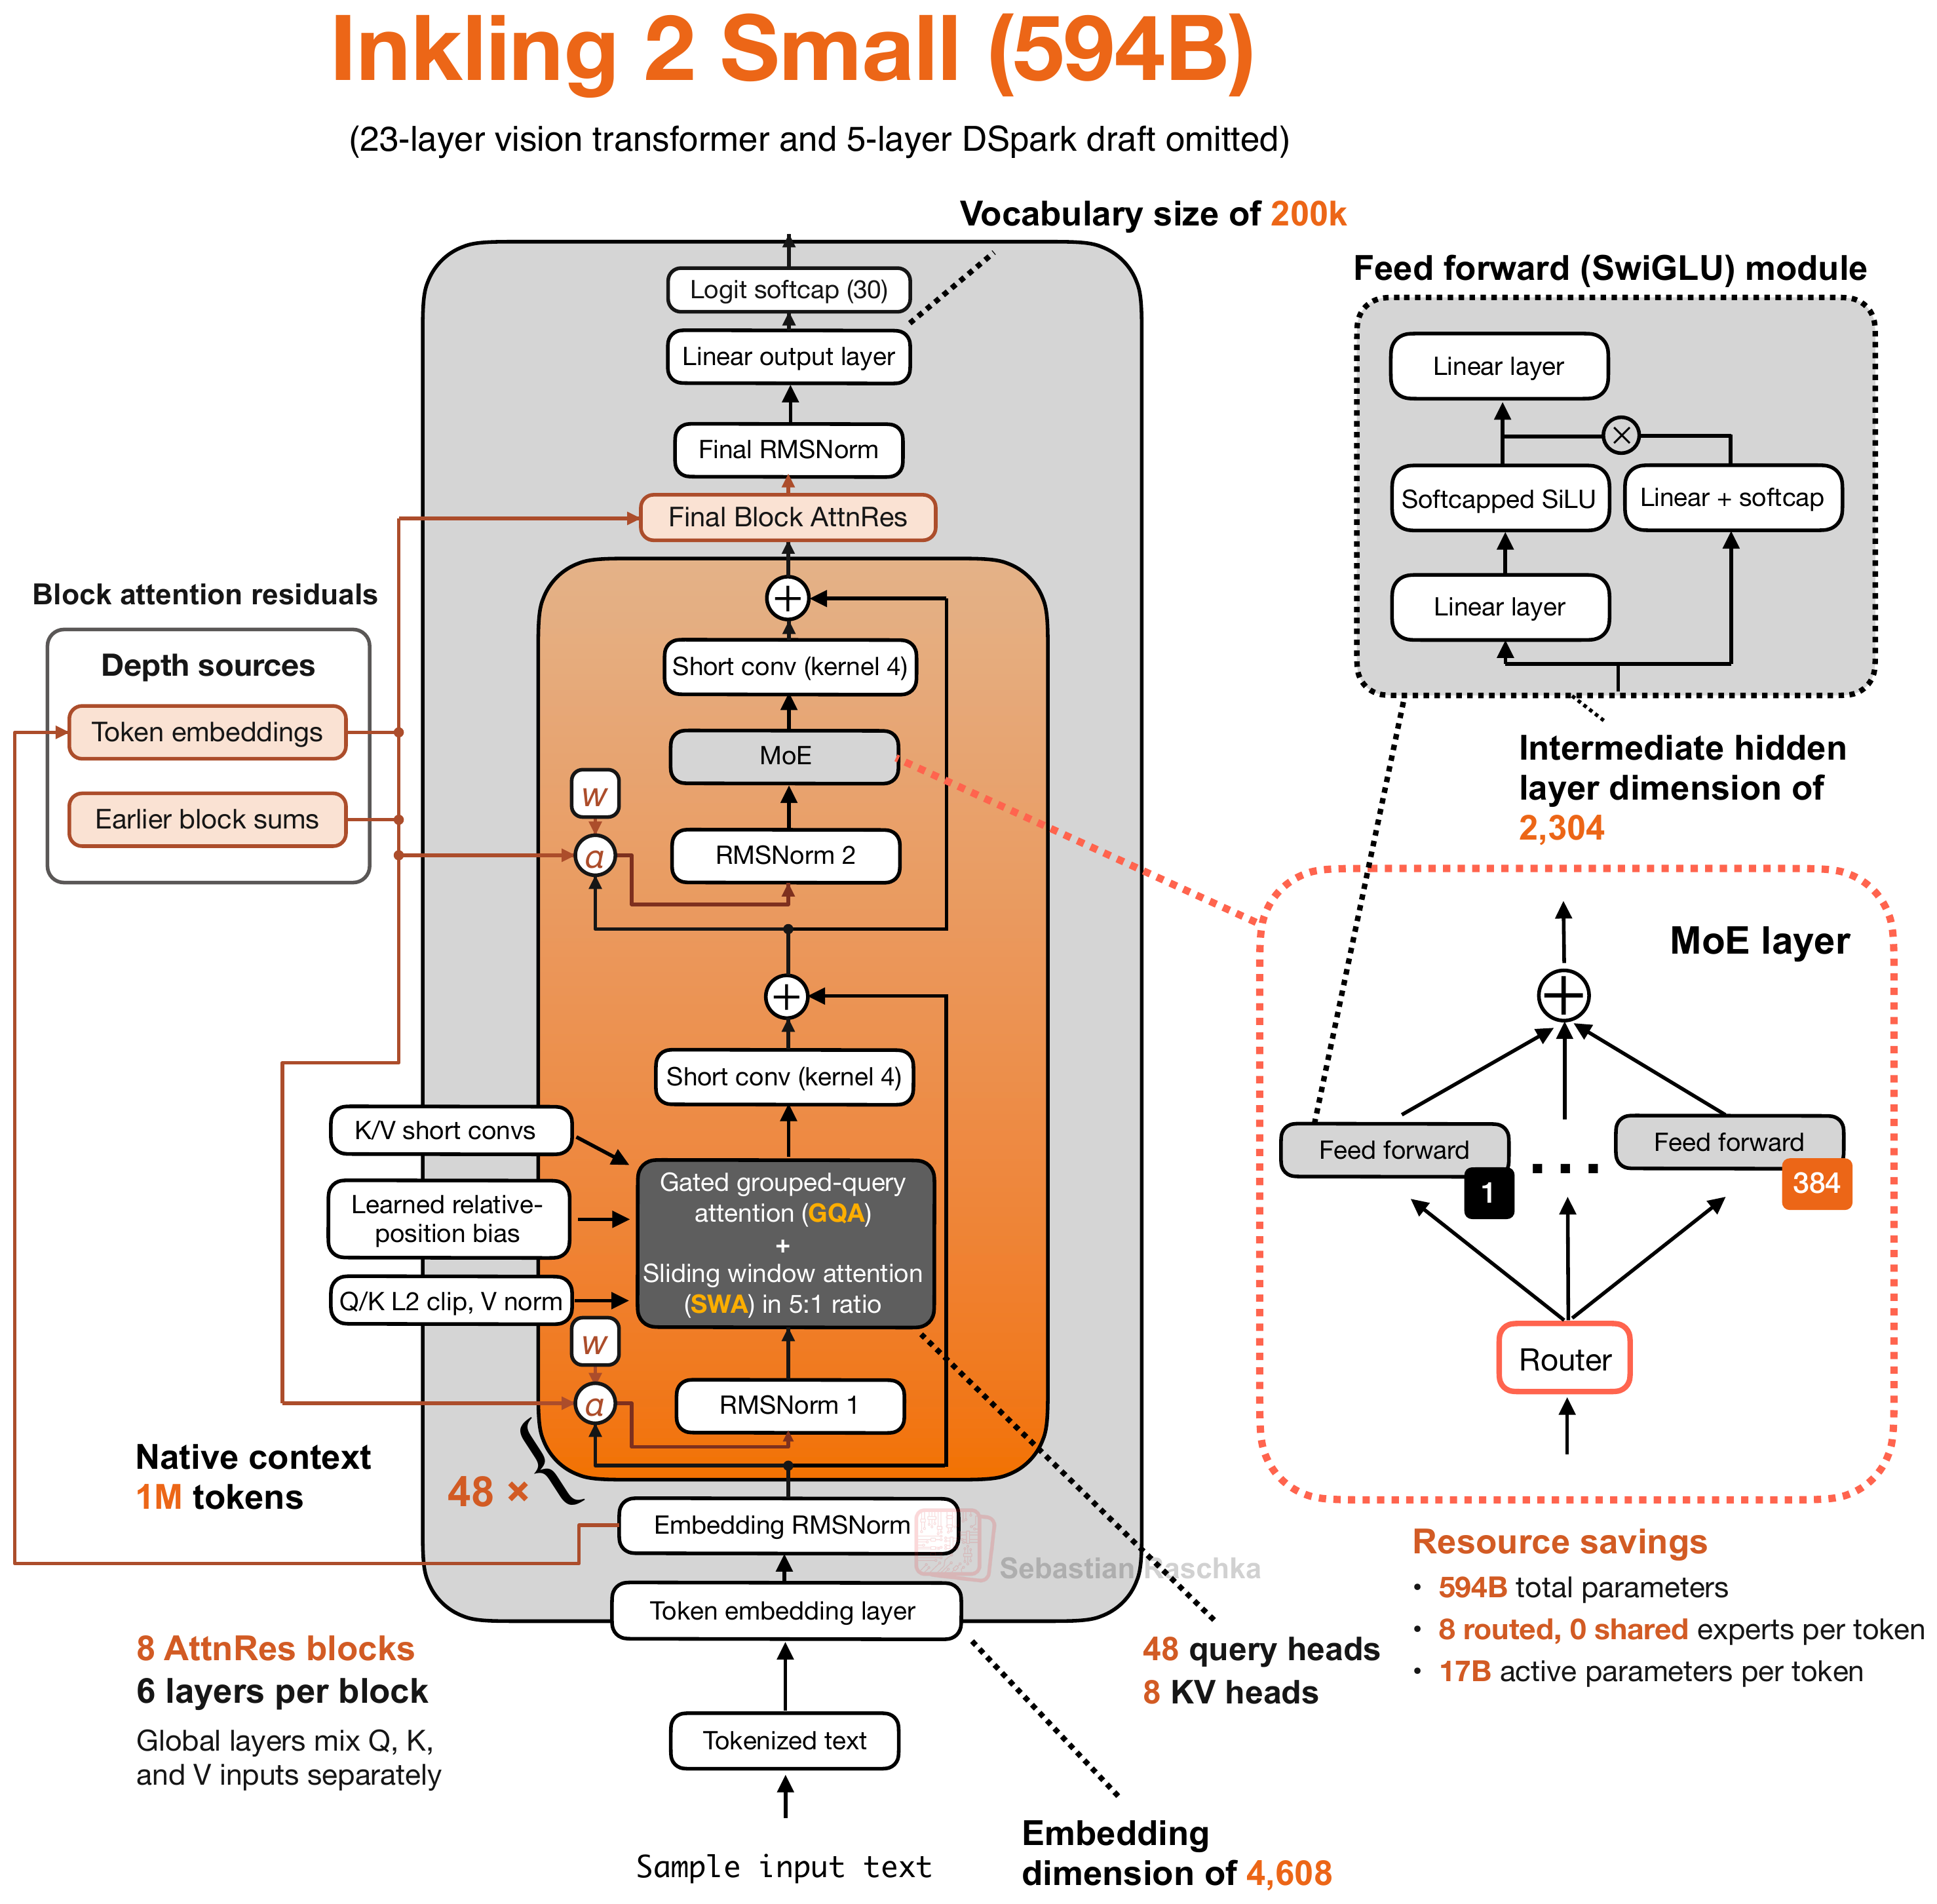
Architecture and specifications
- Scale
- 594B total, 17B active (2.9% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 200,058 (~200k; padded to 201,024)
- License
- Apache License 2.0
- Date
- 2026-11-12
- Decoder type
- Sparse MoE
- Attention
- Gated GQA with Q/K L2 clipping and learned relative-position bias in a 5:1 sliding-window/global pattern
- Layer mix
- 40 sliding-window + 8 global GQA
- KV cache / token (bf16) info
- 192 KiB · High
- Key detail
- Groups the decoder into eight 6-layer AttnRes blocks and adds kernel-4 short convolutions. The figure omits the vision encoder and 5-layer DSpark draft.
Training and benchmarks
- Pretraining data
- 8.4T + 3.8T tokens (H1 + H2) H1 covers natural language, code, and images; H2 uses newer, higher-quality data at 512K context. H3 uses about 320B tokens of reasoning and agent trajectories alongside pretraining replay, and H4 uses about 34B agent-trajectory tokens. Training overview
- Post-training methods
- RL Joint asynchronous RL with StableReinforce across 1,075 steps, over 17M rollouts, and over 3T tokens. Task-specific graders include unit tests, reference answers, LLM judges, and pairwise reward models. Training overview