
Ember-1 Architecture
Back to Ember-1 in the gallery
Fireworks AI
Fireworks' Kimi K3 derivative, post-trained for shorter reasoning traces. Architecture details follow the published Kimi K3 base model; the diagram focuses on its text backbone.
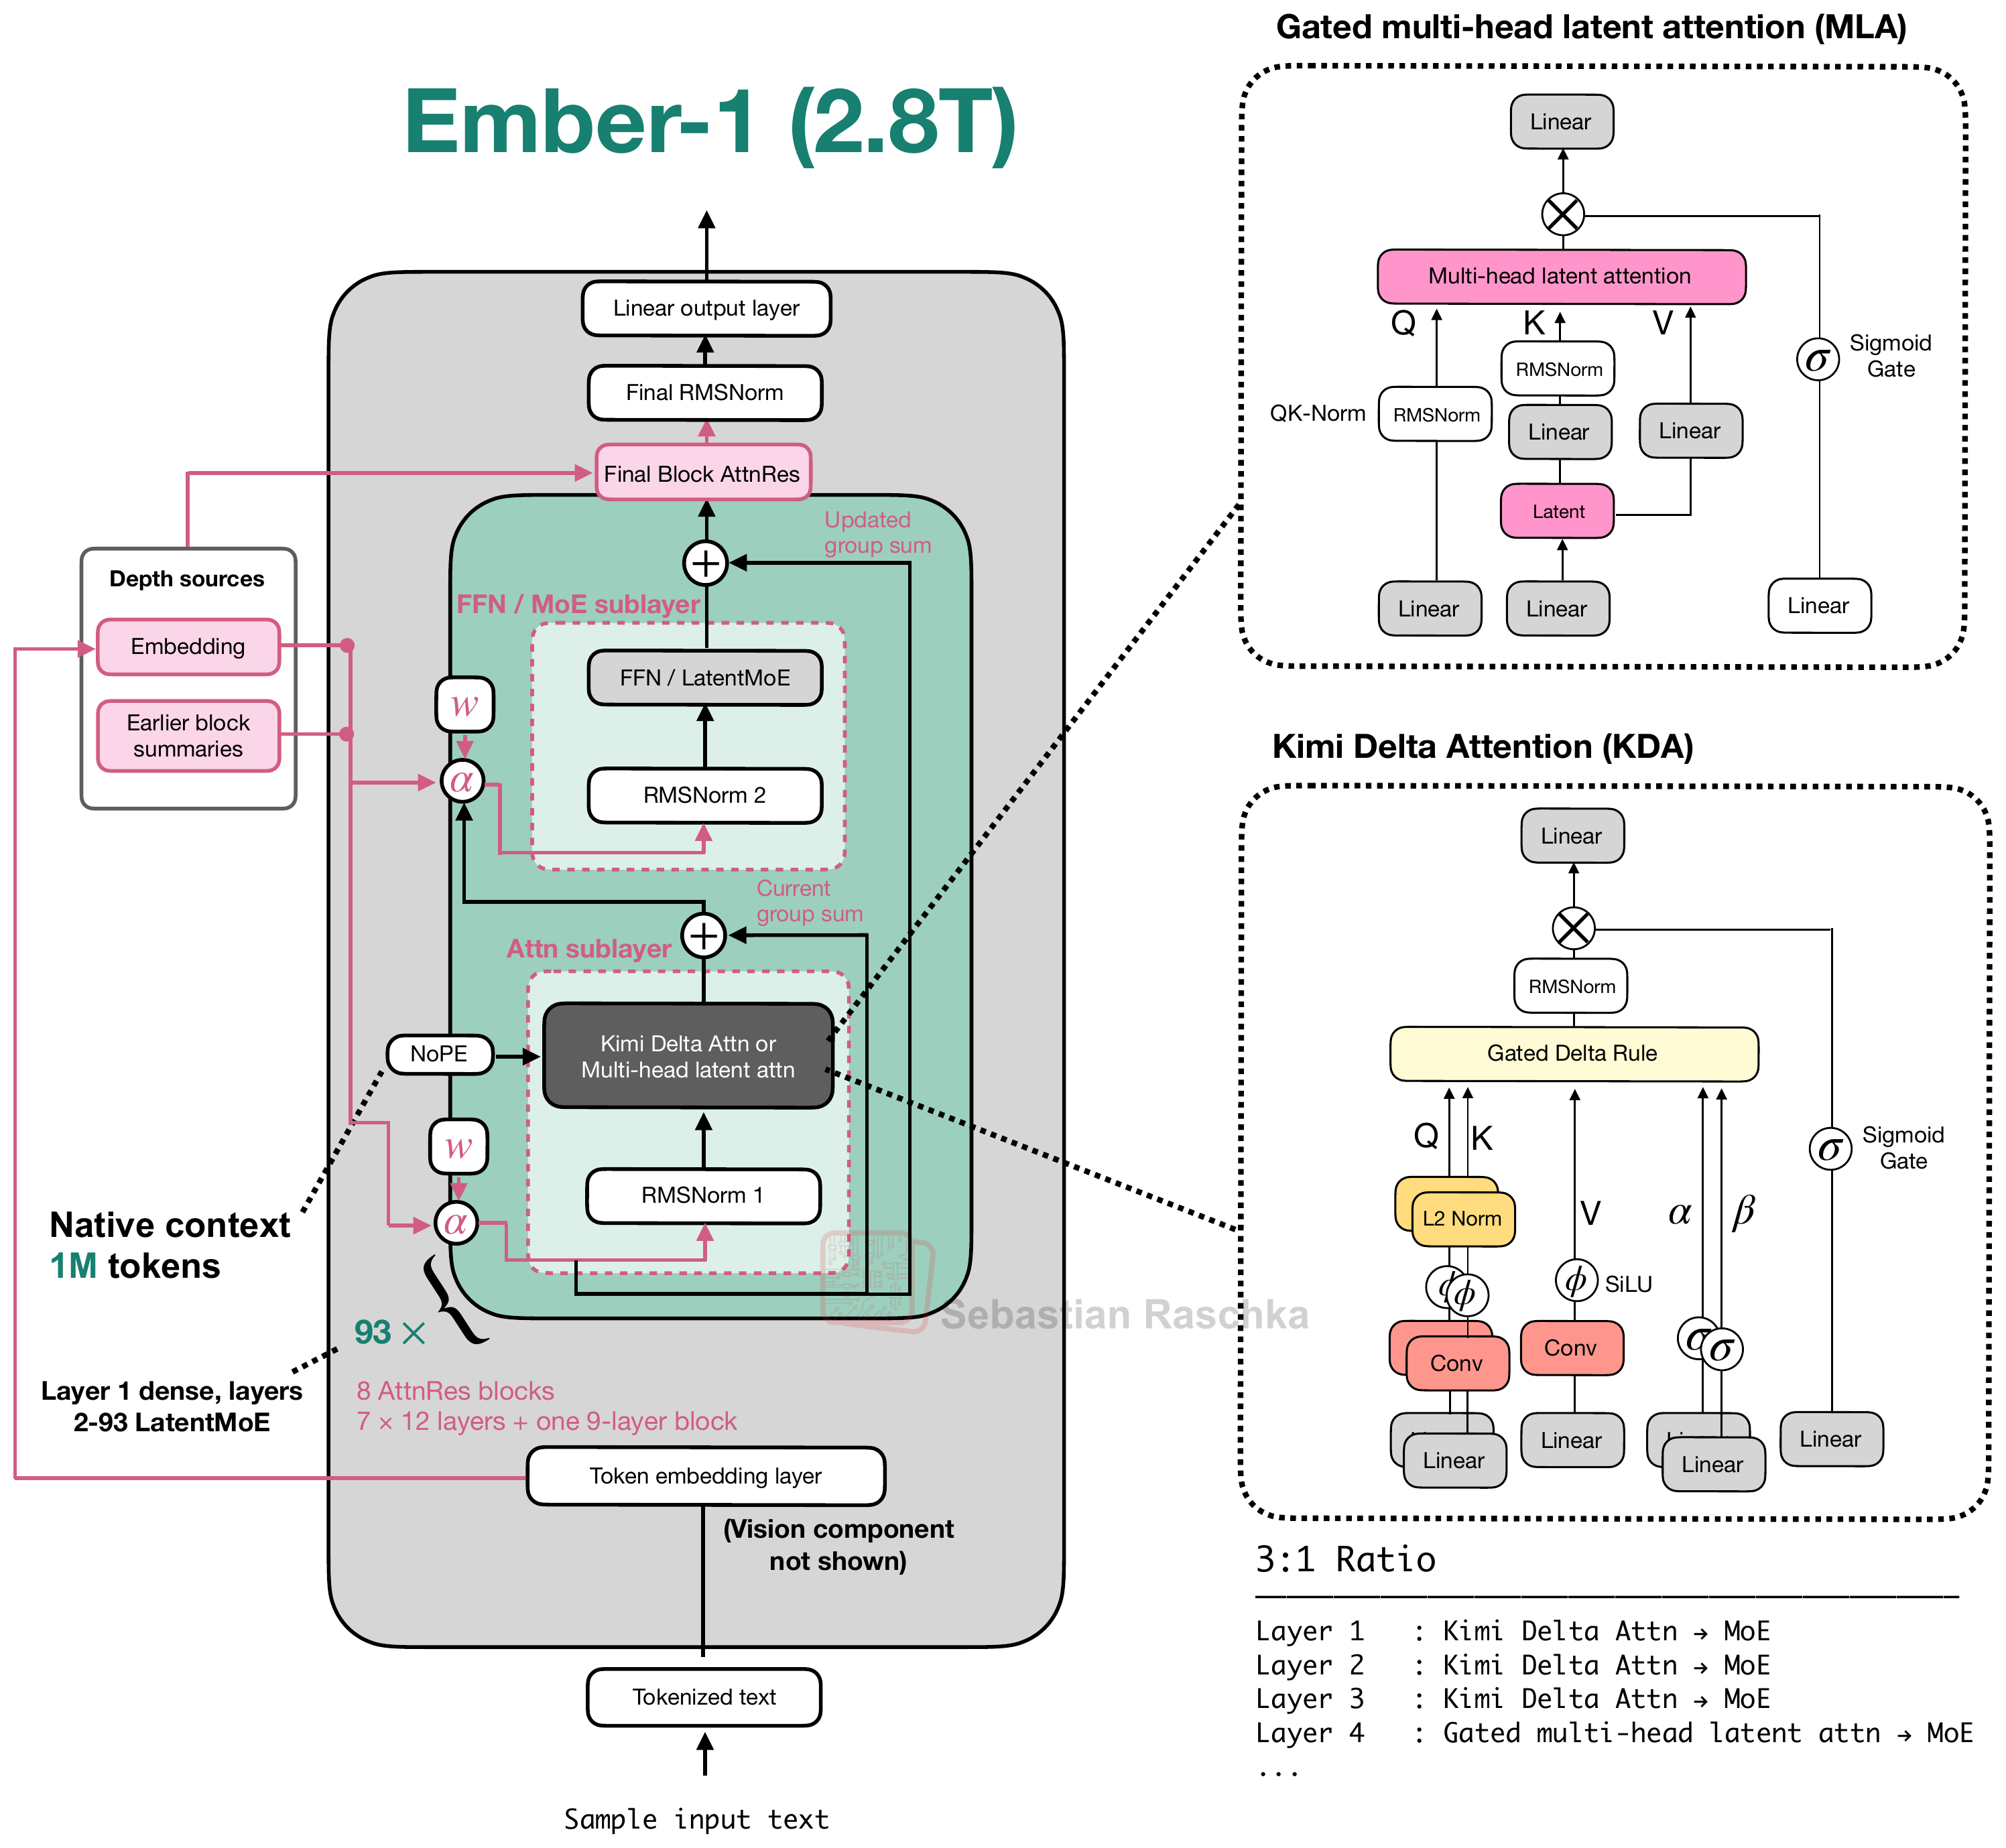
Architecture and specifications
- Scale
- 2.8T total, 104B active (3.7% active)
- Context (tokens)
- 1,048,576
- License
- N/A
- Date
- 2026-09-23
- Decoder type
- Sparse hybrid
- Attention
- 3:1 Kimi Delta Attention and Gated MLA with NoPE
- Layer mix
- 69 KDA + 24 Gated MLA
- KV cache / token (bf16) info
- 27 KiB · Low
- Key detail
- Inherits Kimi K3's eight Block Attention Residual groups and Stable LatentMoE, with one dense layer followed by 92 MoE layers.
Training and benchmarks
- Pretraining data
- Not disclosed Derived from Kimi K3; the release does not disclose a pretraining-token total. Ember-1 release
- Post-training methods
- Not disclosed The release describes additional training to shorten reasoning but does not name its training stages. Ember-1 release