
Qwen3.8 27B Architecture
Back to Qwen3.8 27B in the gallery
Alibaba Cloud
Dense 27B native vision-language model with a 64-layer Gated DeltaNet and Gated Attention language backbone; the figure omits the vision encoder and MTP head.
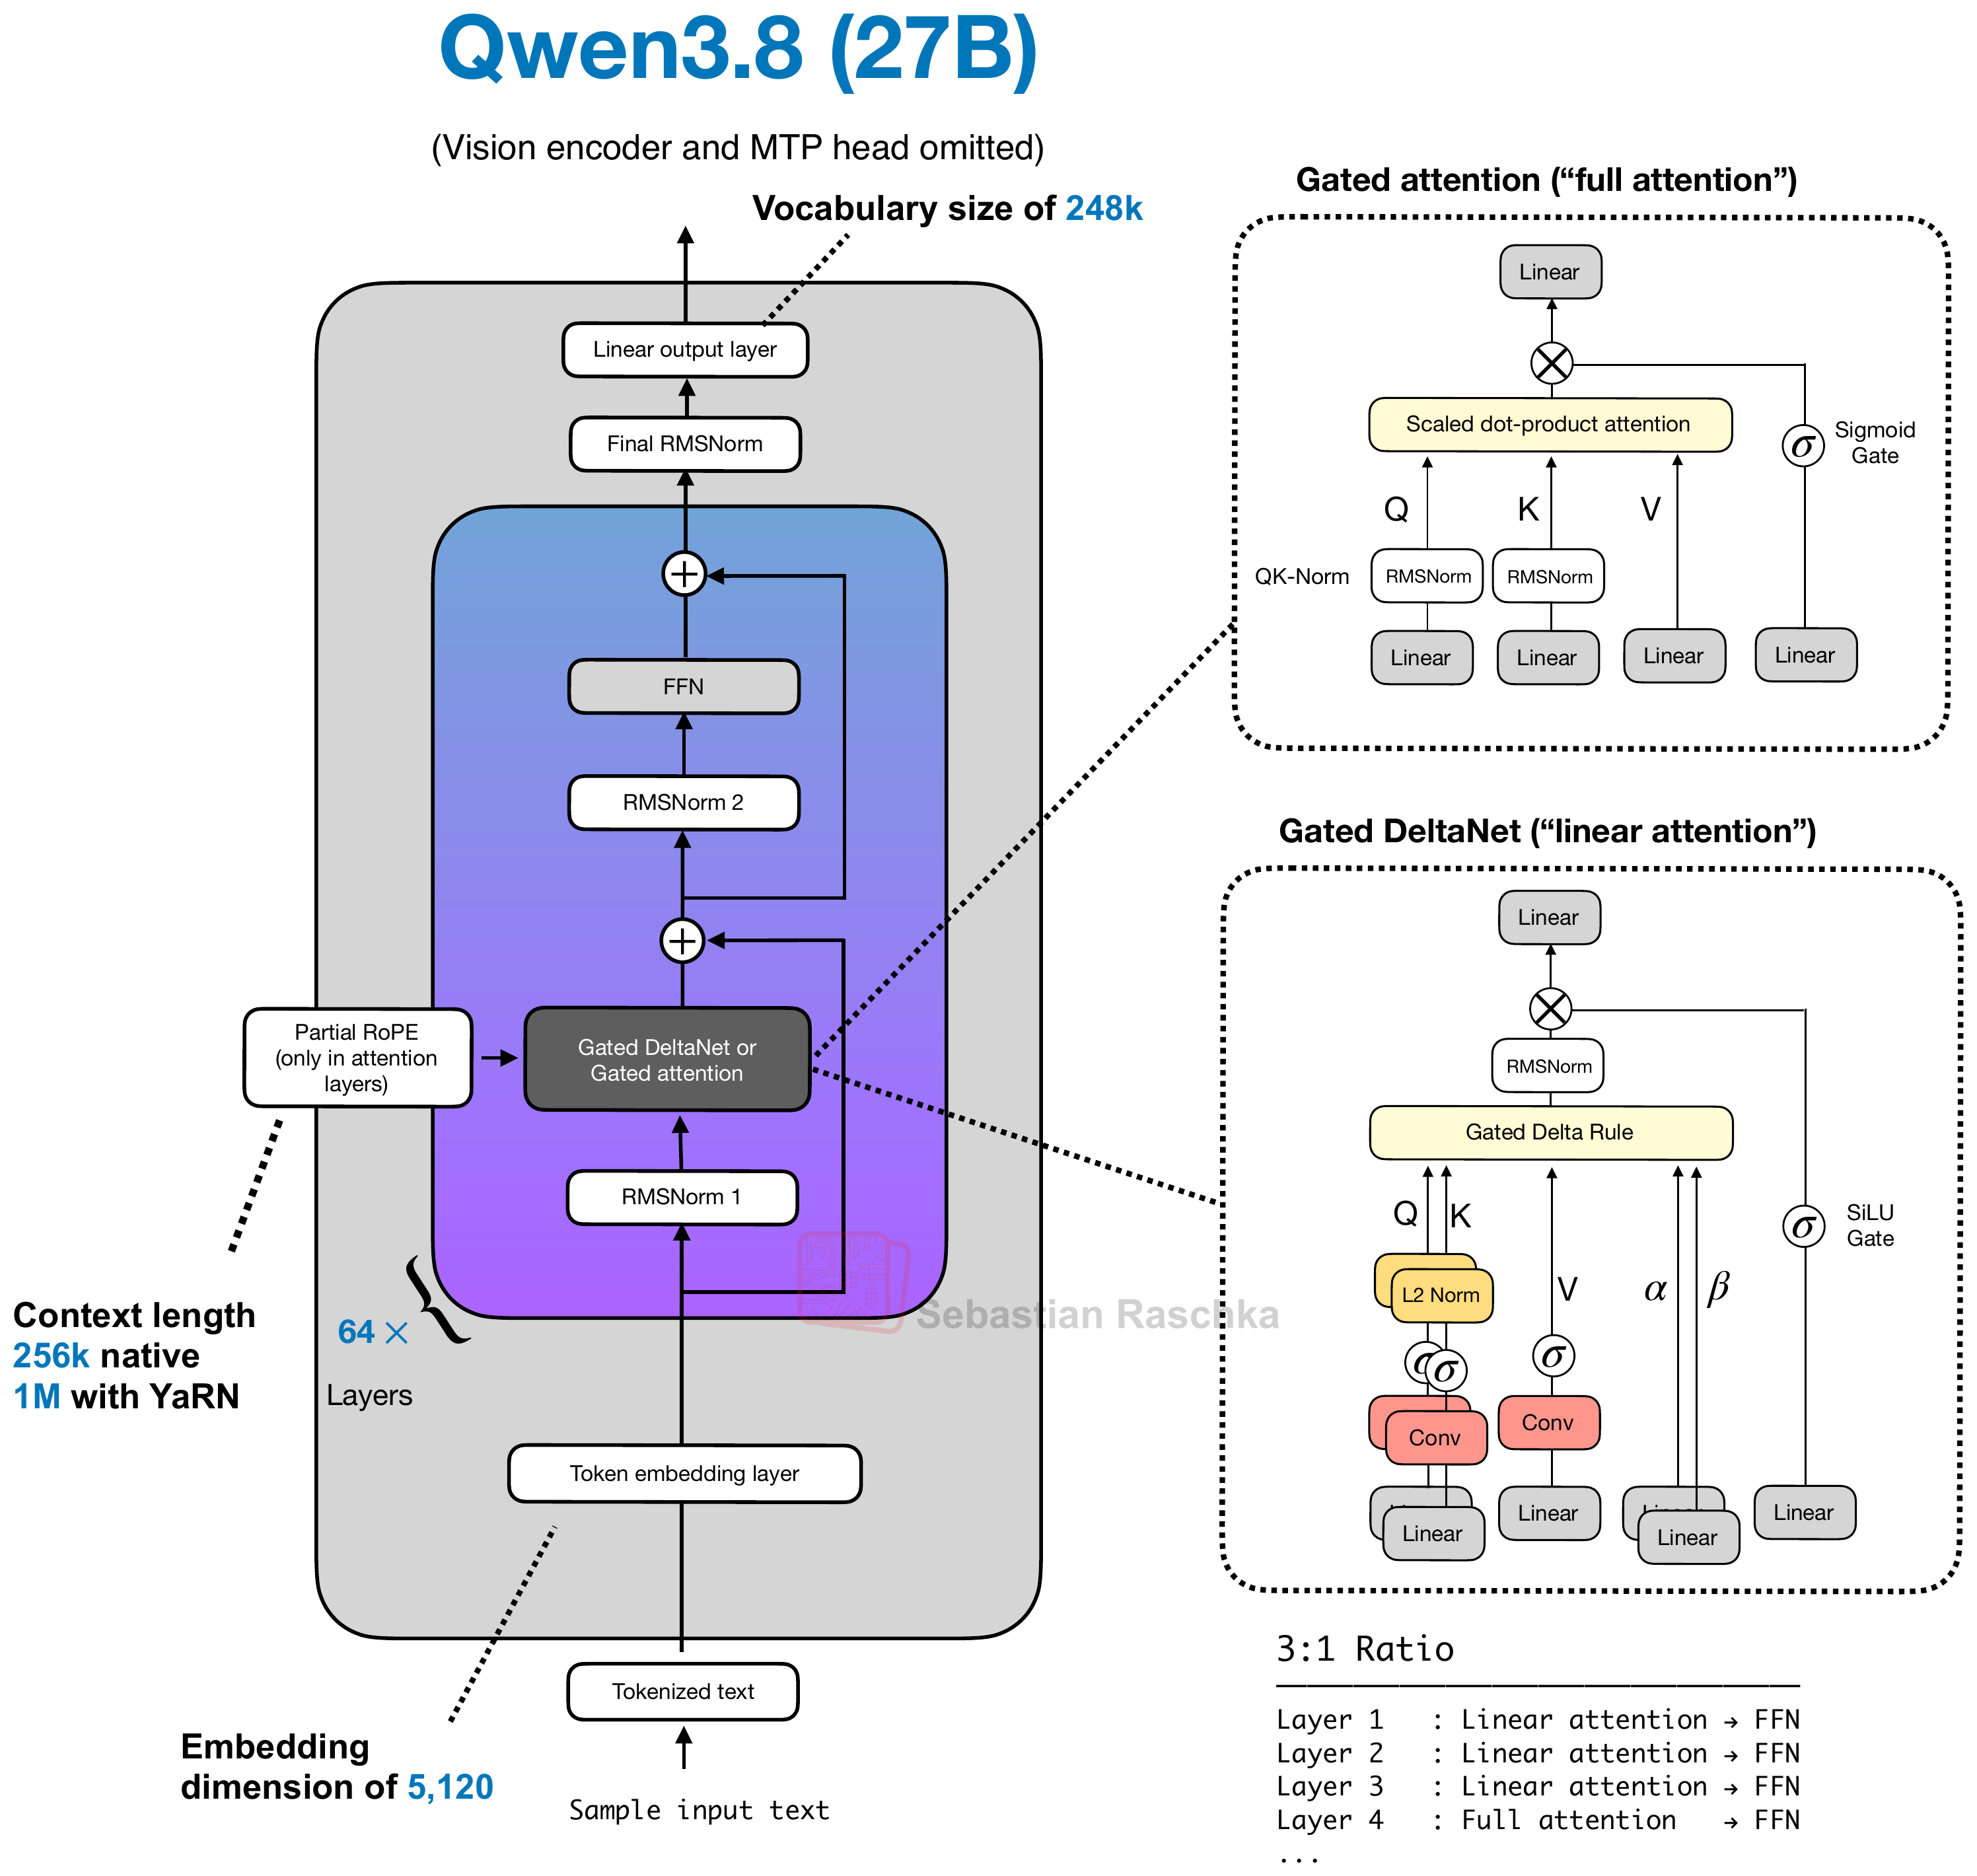
Architecture and specifications
- Scale
- 27B parameters
- Context (tokens)
- 262,144 native (1,000,000 with YaRN)
- Vocabulary
- 248,320 (~248k)
- License
- Apache License 2.0
- Date
- 2026-08-14
- Decoder type
- Dense hybrid
- Attention
- 3:1 Gated DeltaNet and gated attention with GQA
- Layer mix
- 16 gated attention + 48 DeltaNet
- KV cache / token (bf16) info
- 64 KiB · Low
- Key detail
- Uses a 64-layer 3:1 Gated DeltaNet/Gated Attention decoder with partial RoPE and one MTP layer.
Training and benchmarks
- Pretraining data
- Not disclosed The model card does not report the pretraining token count. Model card
- Post-training methods
- Not disclosed The card identifies a post-trained checkpoint without naming the methods. Model card