
Nemotron 3.5 Super VL 120B-A12B Architecture
Back to Nemotron 3.5 Super VL 120B-A12B in the gallery
NVIDIA
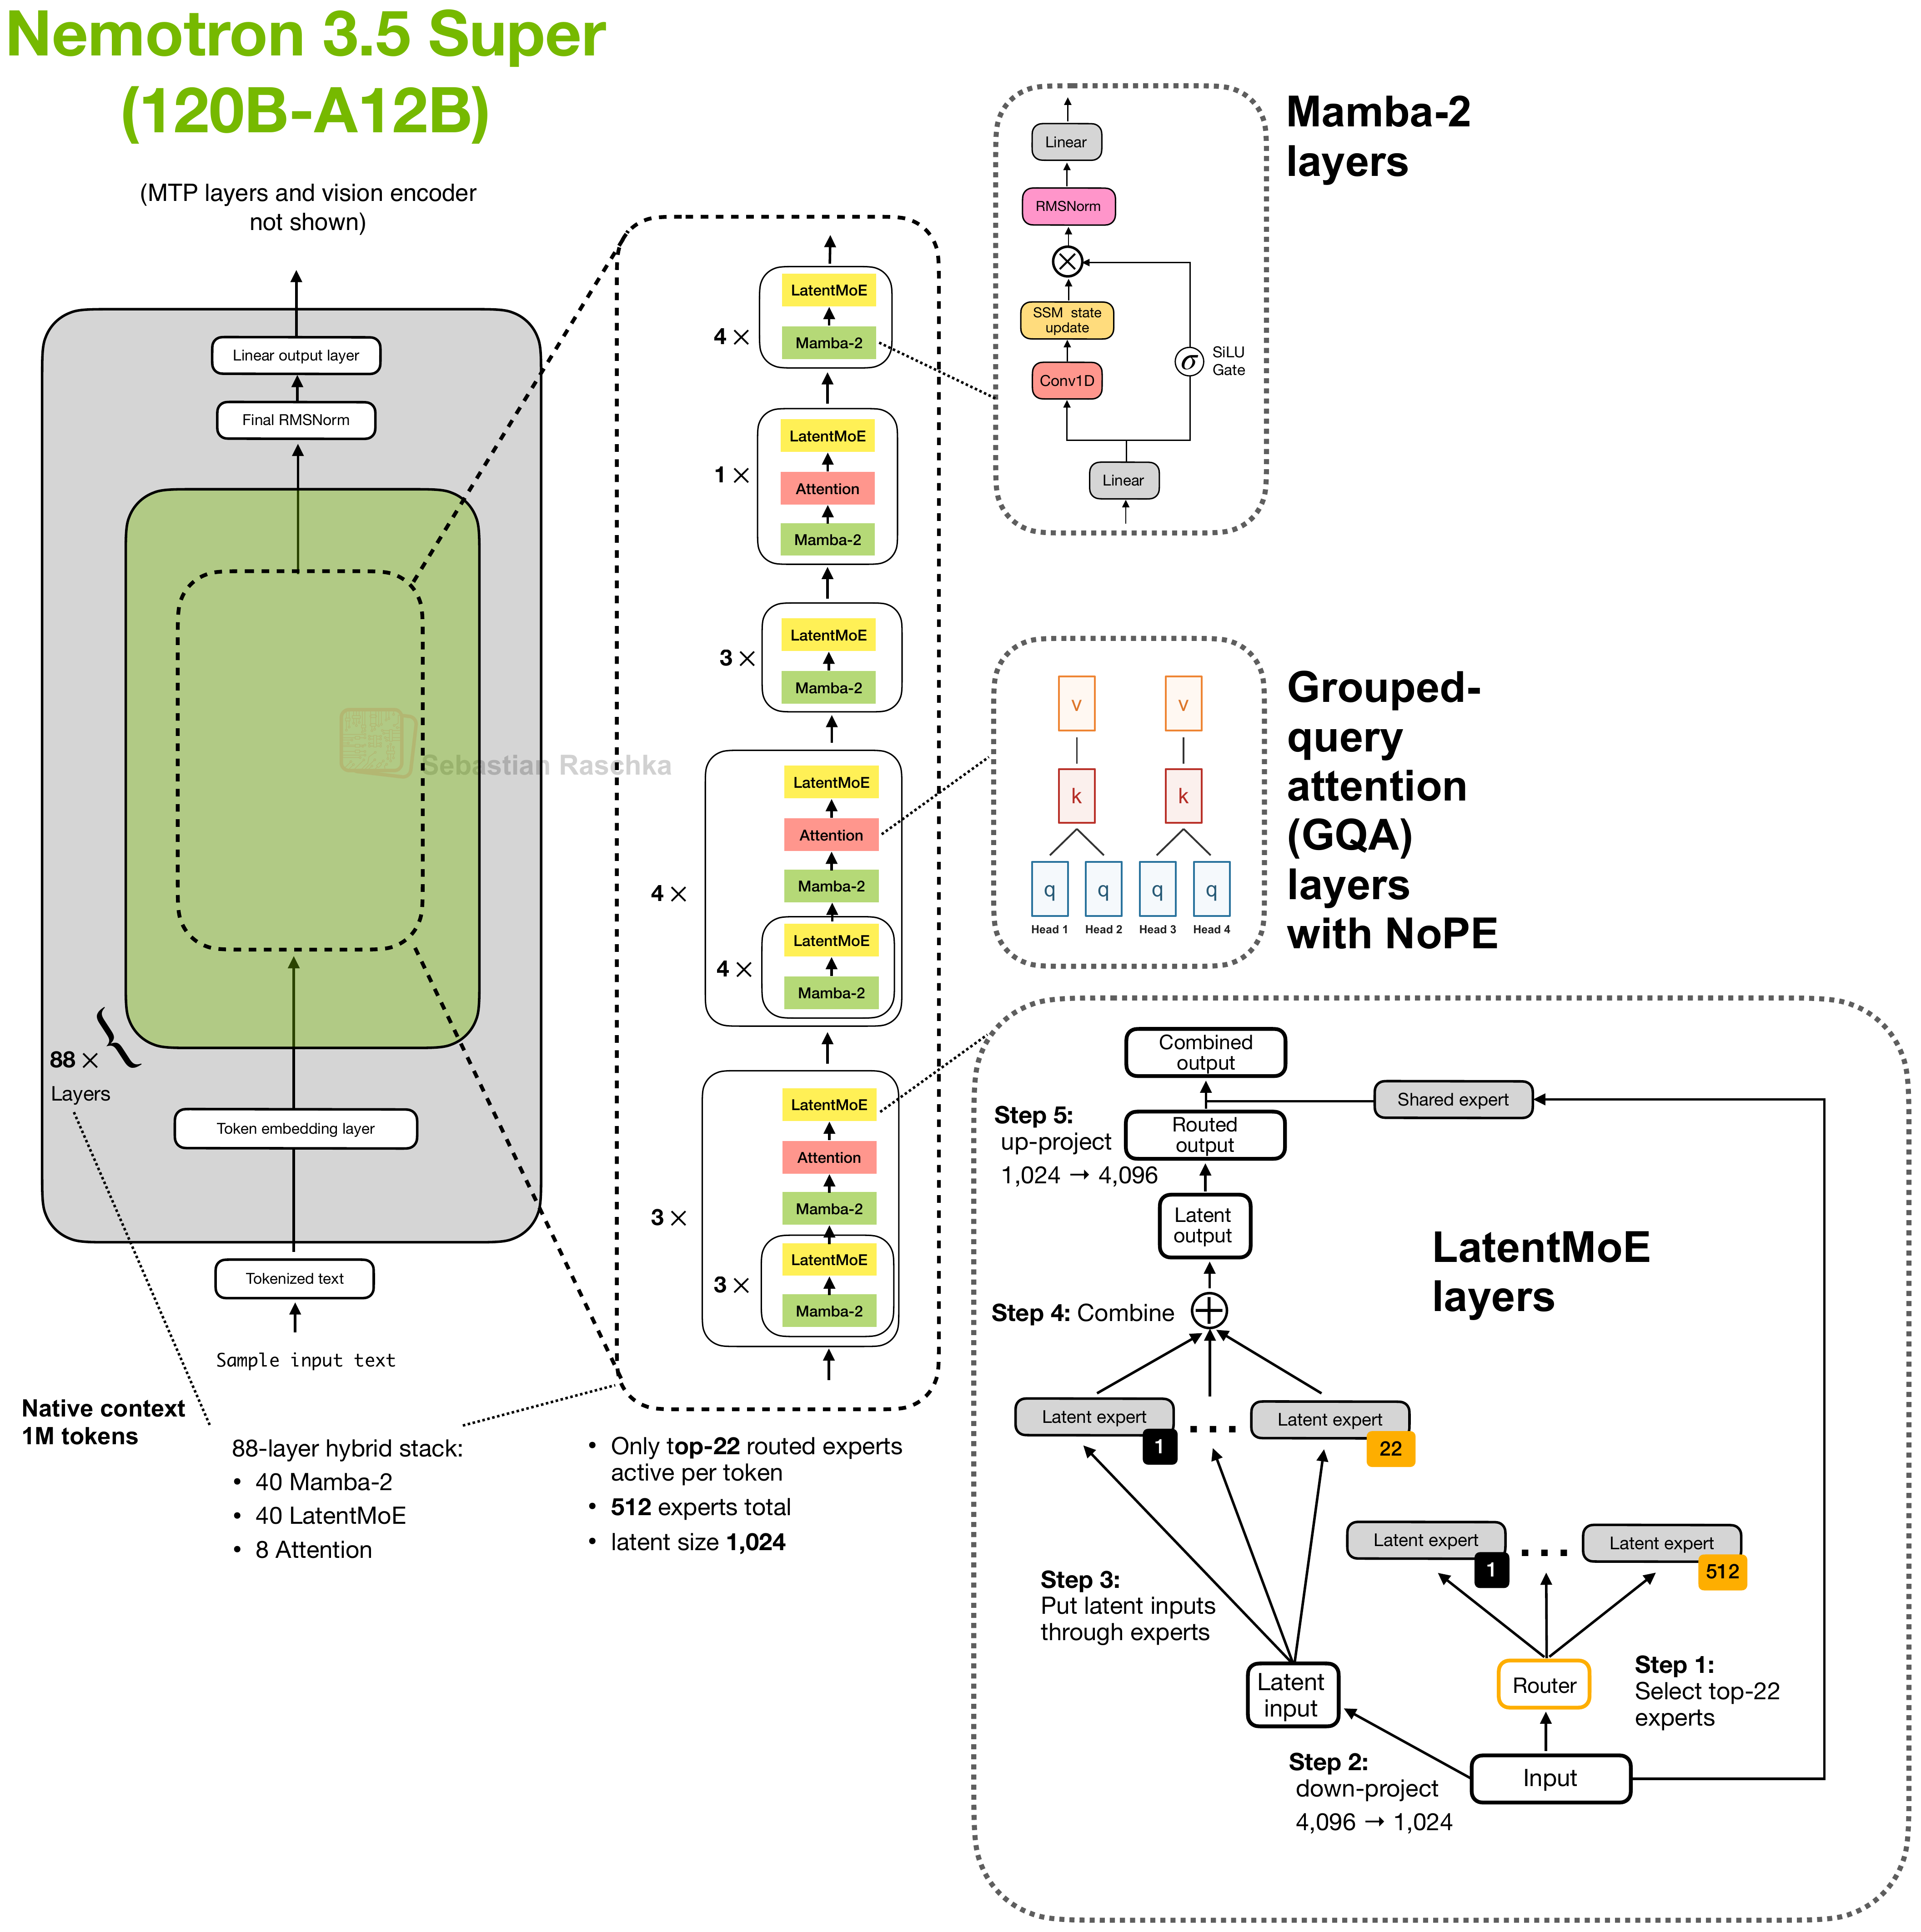
NVIDIA's vision-language model extends the Nemotron 3 Super backbone with C-RADIO vision encoding and shared-weight multi-token prediction. The figure shows the language backbone, with the vision encoder and MTP omitted.
Architecture and specifications
- Scale
- 120B total, 12B active (10% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 131,072
- License
- OpenMDW 1.1
- Date
- 2026-10-15
- Decoder type
- Hybrid MoE
- Attention
- Mostly Mamba-2 with eight GQA layers using NoPE
- Layer mix
- 8 GQA + 40 Mamba-2 + 40 LatentMoE; GQA + MoE MTP predictor
- KV cache / token (bf16) info
- 8 KiB · Very low
- Key detail
- Routes each token to 22 of 512 experts in a 1,024-dimensional latent space, alongside one shared expert at the full 4,096-dimensional width.
Training and benchmarks
- Pretraining data
- 1.2094T additional tokens Continued from Nemotron 3 Super Base with 1T distillation, 100B Indic, 35B context-extension, 65.4B agentic mid-training, and 9B context-recovery tokens. Separate 100B MTP-head warmup freezes the backbone. Nemotron 3.5 technical report
- Post-training methods
- SFT, RLVR, RLHF, Distillation Vision-language SFT, verifiable-reward RL, human-feedback RL, and multi-teacher on-policy distillation. Nemotron 3.5 technical report