
Muse Glimmer 30B Architecture
Back to Muse Glimmer 30B in the gallery
Meta
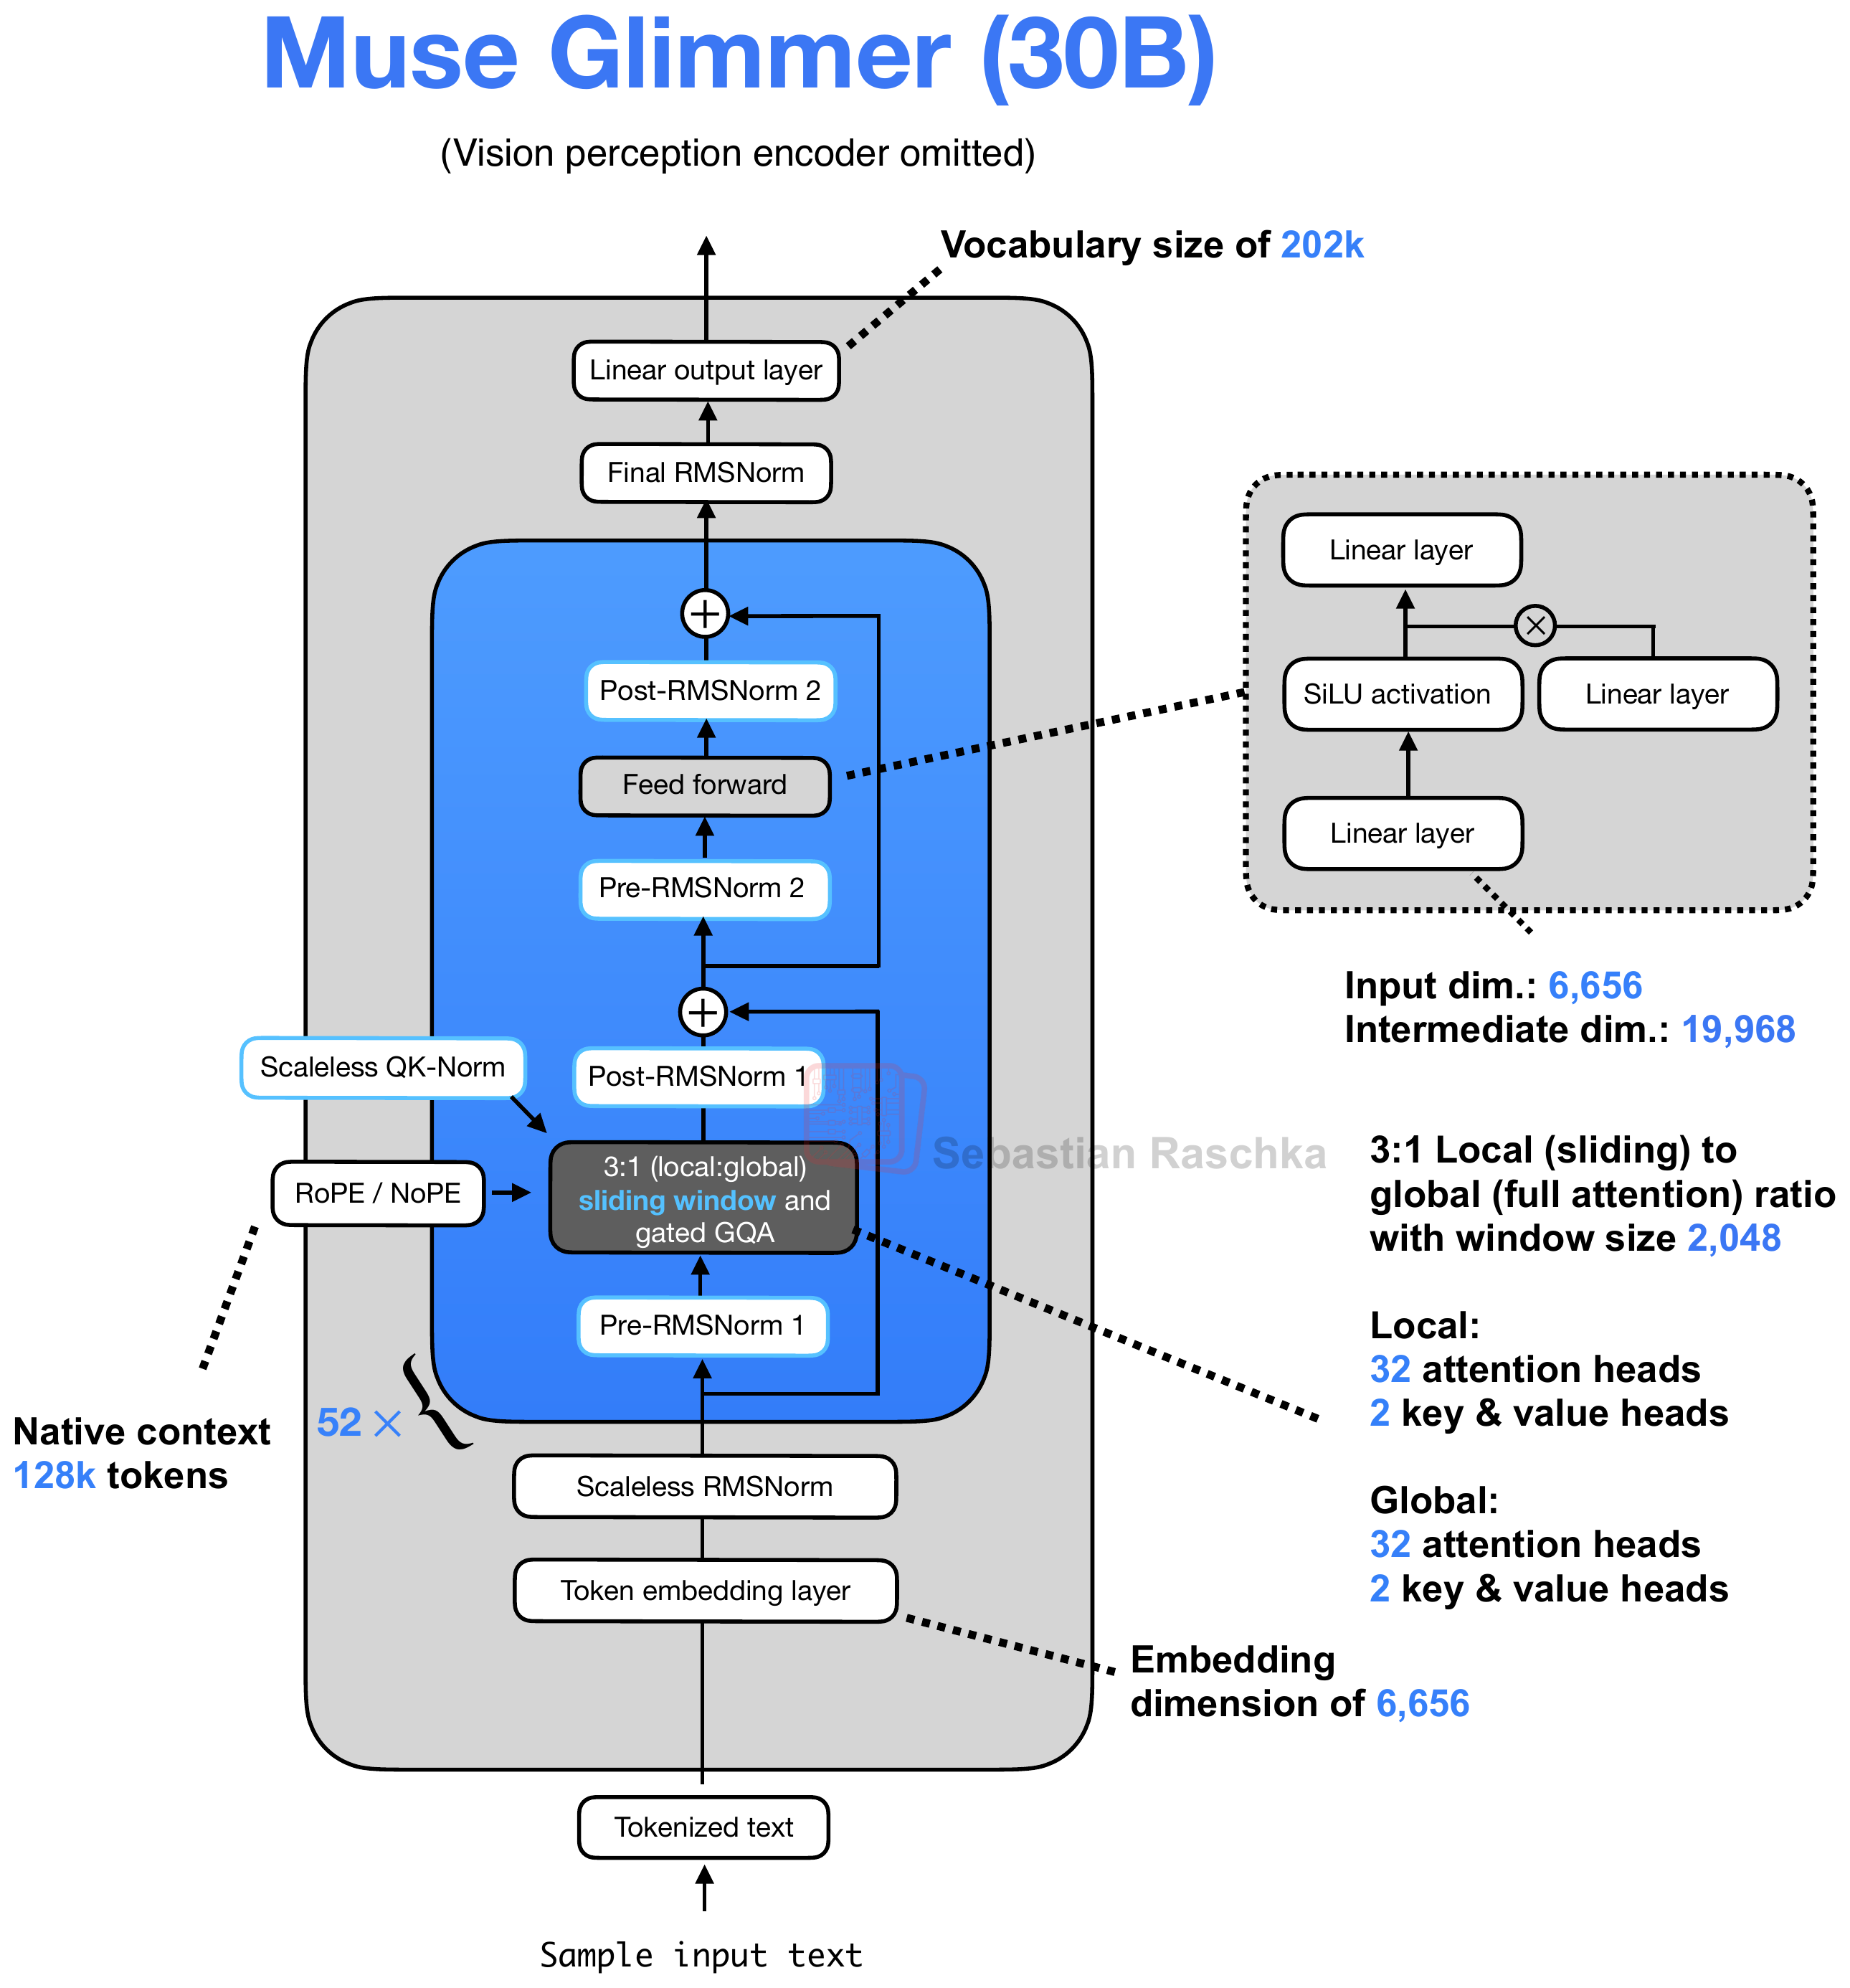
Meta's dense 29.6B multimodal model combines a 52-layer sandwich-norm decoder with gated GQA and a separate perception encoder; the figure focuses on the text backbone.
Architecture and specifications
- Scale
- 29.6B parameters (including perception encoder)
- Context (tokens)
- 131,072+
- Vocabulary
- 202,048 (~202k)
- License
- Apache License 2.0
- Date
- 2026-08-10
- Decoder type
- Dense
- Attention
- Gated GQA with scaleless QK-Norm, local-only RoPE, global NoPE, and 3:1 sliding-window/global attention
- Layer mix
- 39 sliding-window + 13 global gated GQA
- KV cache / token (bf16) info
- 52 KiB · Low
- Key detail
- Applies RoPE only in 2,048-token local layers, uses NoPE in global layers, and gates the attention output before projection.
Training and benchmarks
- Pretraining data
- Not disclosed The report describes pretraining through logit co-distillation and later mid-training, but does not report total training tokens. Muse Glimmer technical report
- Post-training methods
- SFT, Distillation, RL Supervised fine-tuning, on-policy distillation from Muse Spark, and reinforcement learning. Muse Glimmer technical report