
Mistral Large 4 Architecture
Back to Mistral Large 4 in the gallery
Mistral AI
Mistral's trillion-parameter multimodal MoE combines MLA with sparse token selection and cross-layer KV sharing.
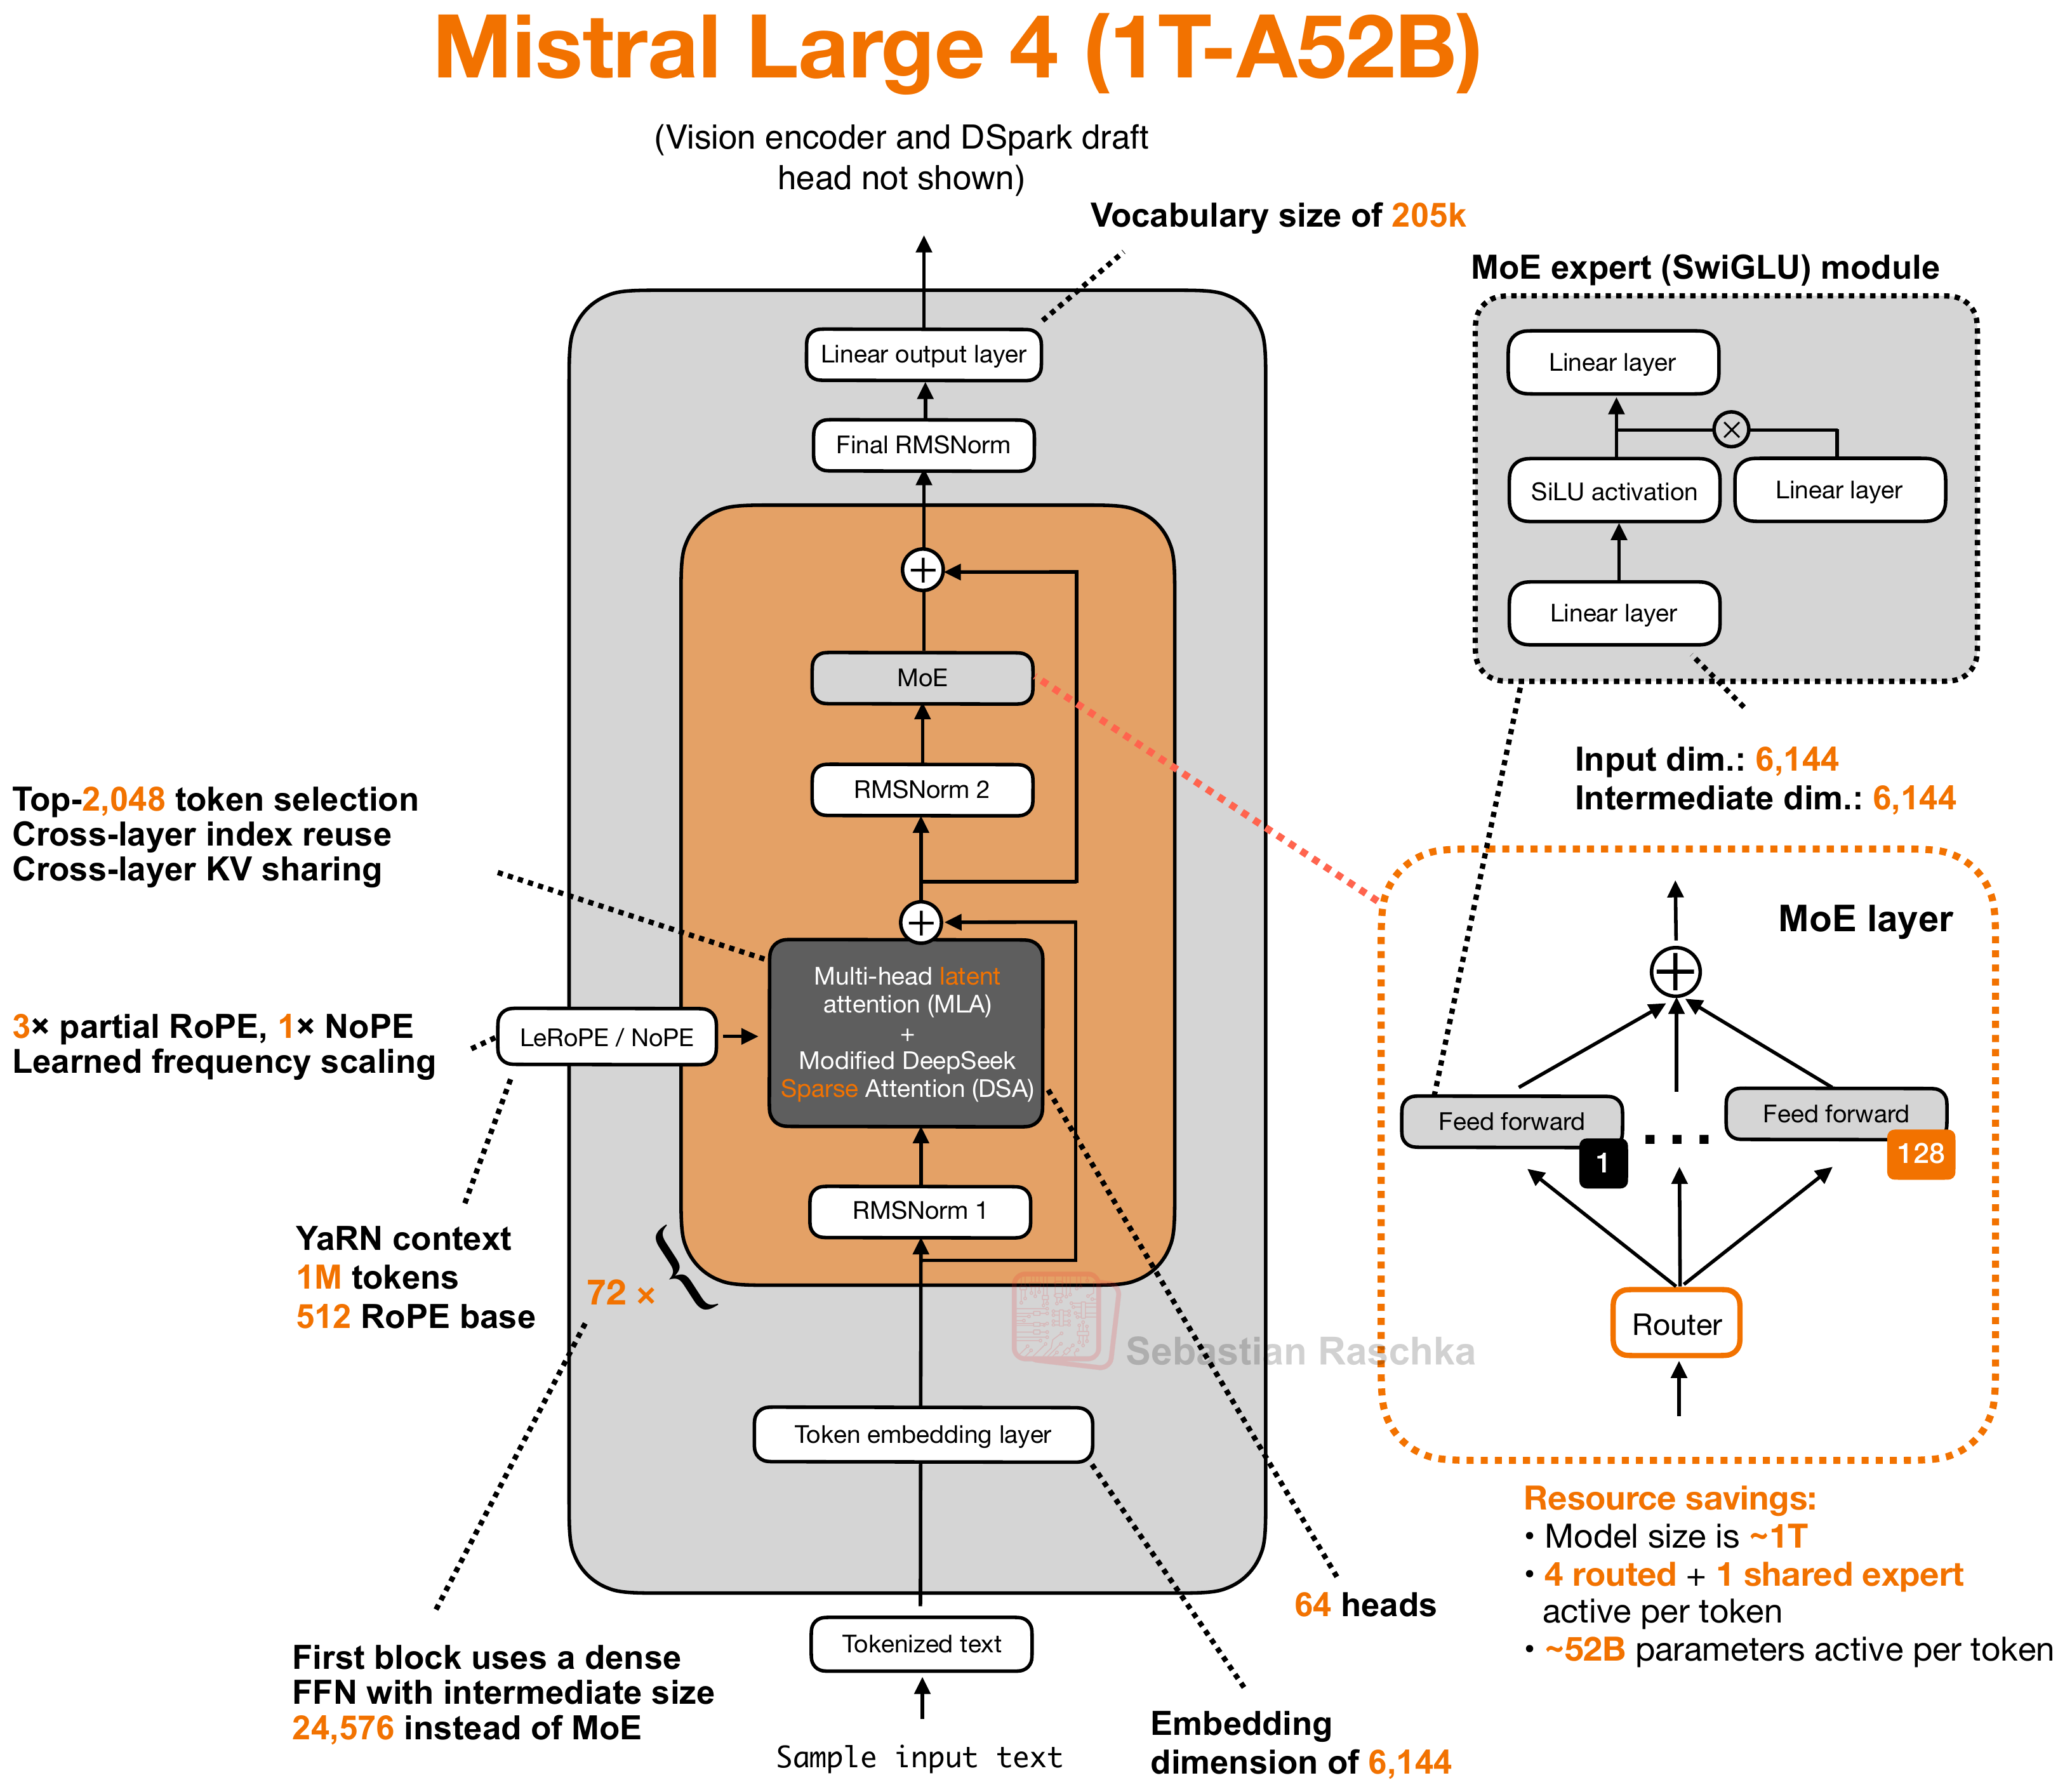
Architecture and specifications
- Scale
- 1T total, 52B active (5.2% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 204,800
- License
- Mistral Ecosystem Open-Weight License
- Date
- 2026-10-29
- Decoder type
- Sparse MoE
- Attention
- MLA with modified DeepSeek Sparse Attention, index reuse, and KV sharing
- Layer mix
- 72 MLA/DSA
- KV cache / token (bf16) info
- 80.75 KiB · Moderate
- Key detail
- Selects the top 2,048 tokens, reuses sparse indices across layers, and alternates three LeRoPE layers with one NoPE layer.
Training and benchmarks
- Pretraining data
- Not disclosed The technical report describes two multilingual multimodal pretraining phases but gives no total token count. Mistral Large 4 technical report
- Post-training methods
- SFT, RLVR Supervised fine-tuning followed by RL using executable task verification, alongside learned and model-judged rewards. Mistral Large 4 technical report