
Ling 3.1 Flash Architecture
Back to Ling 3.1 Flash in the gallery
InclusionAI
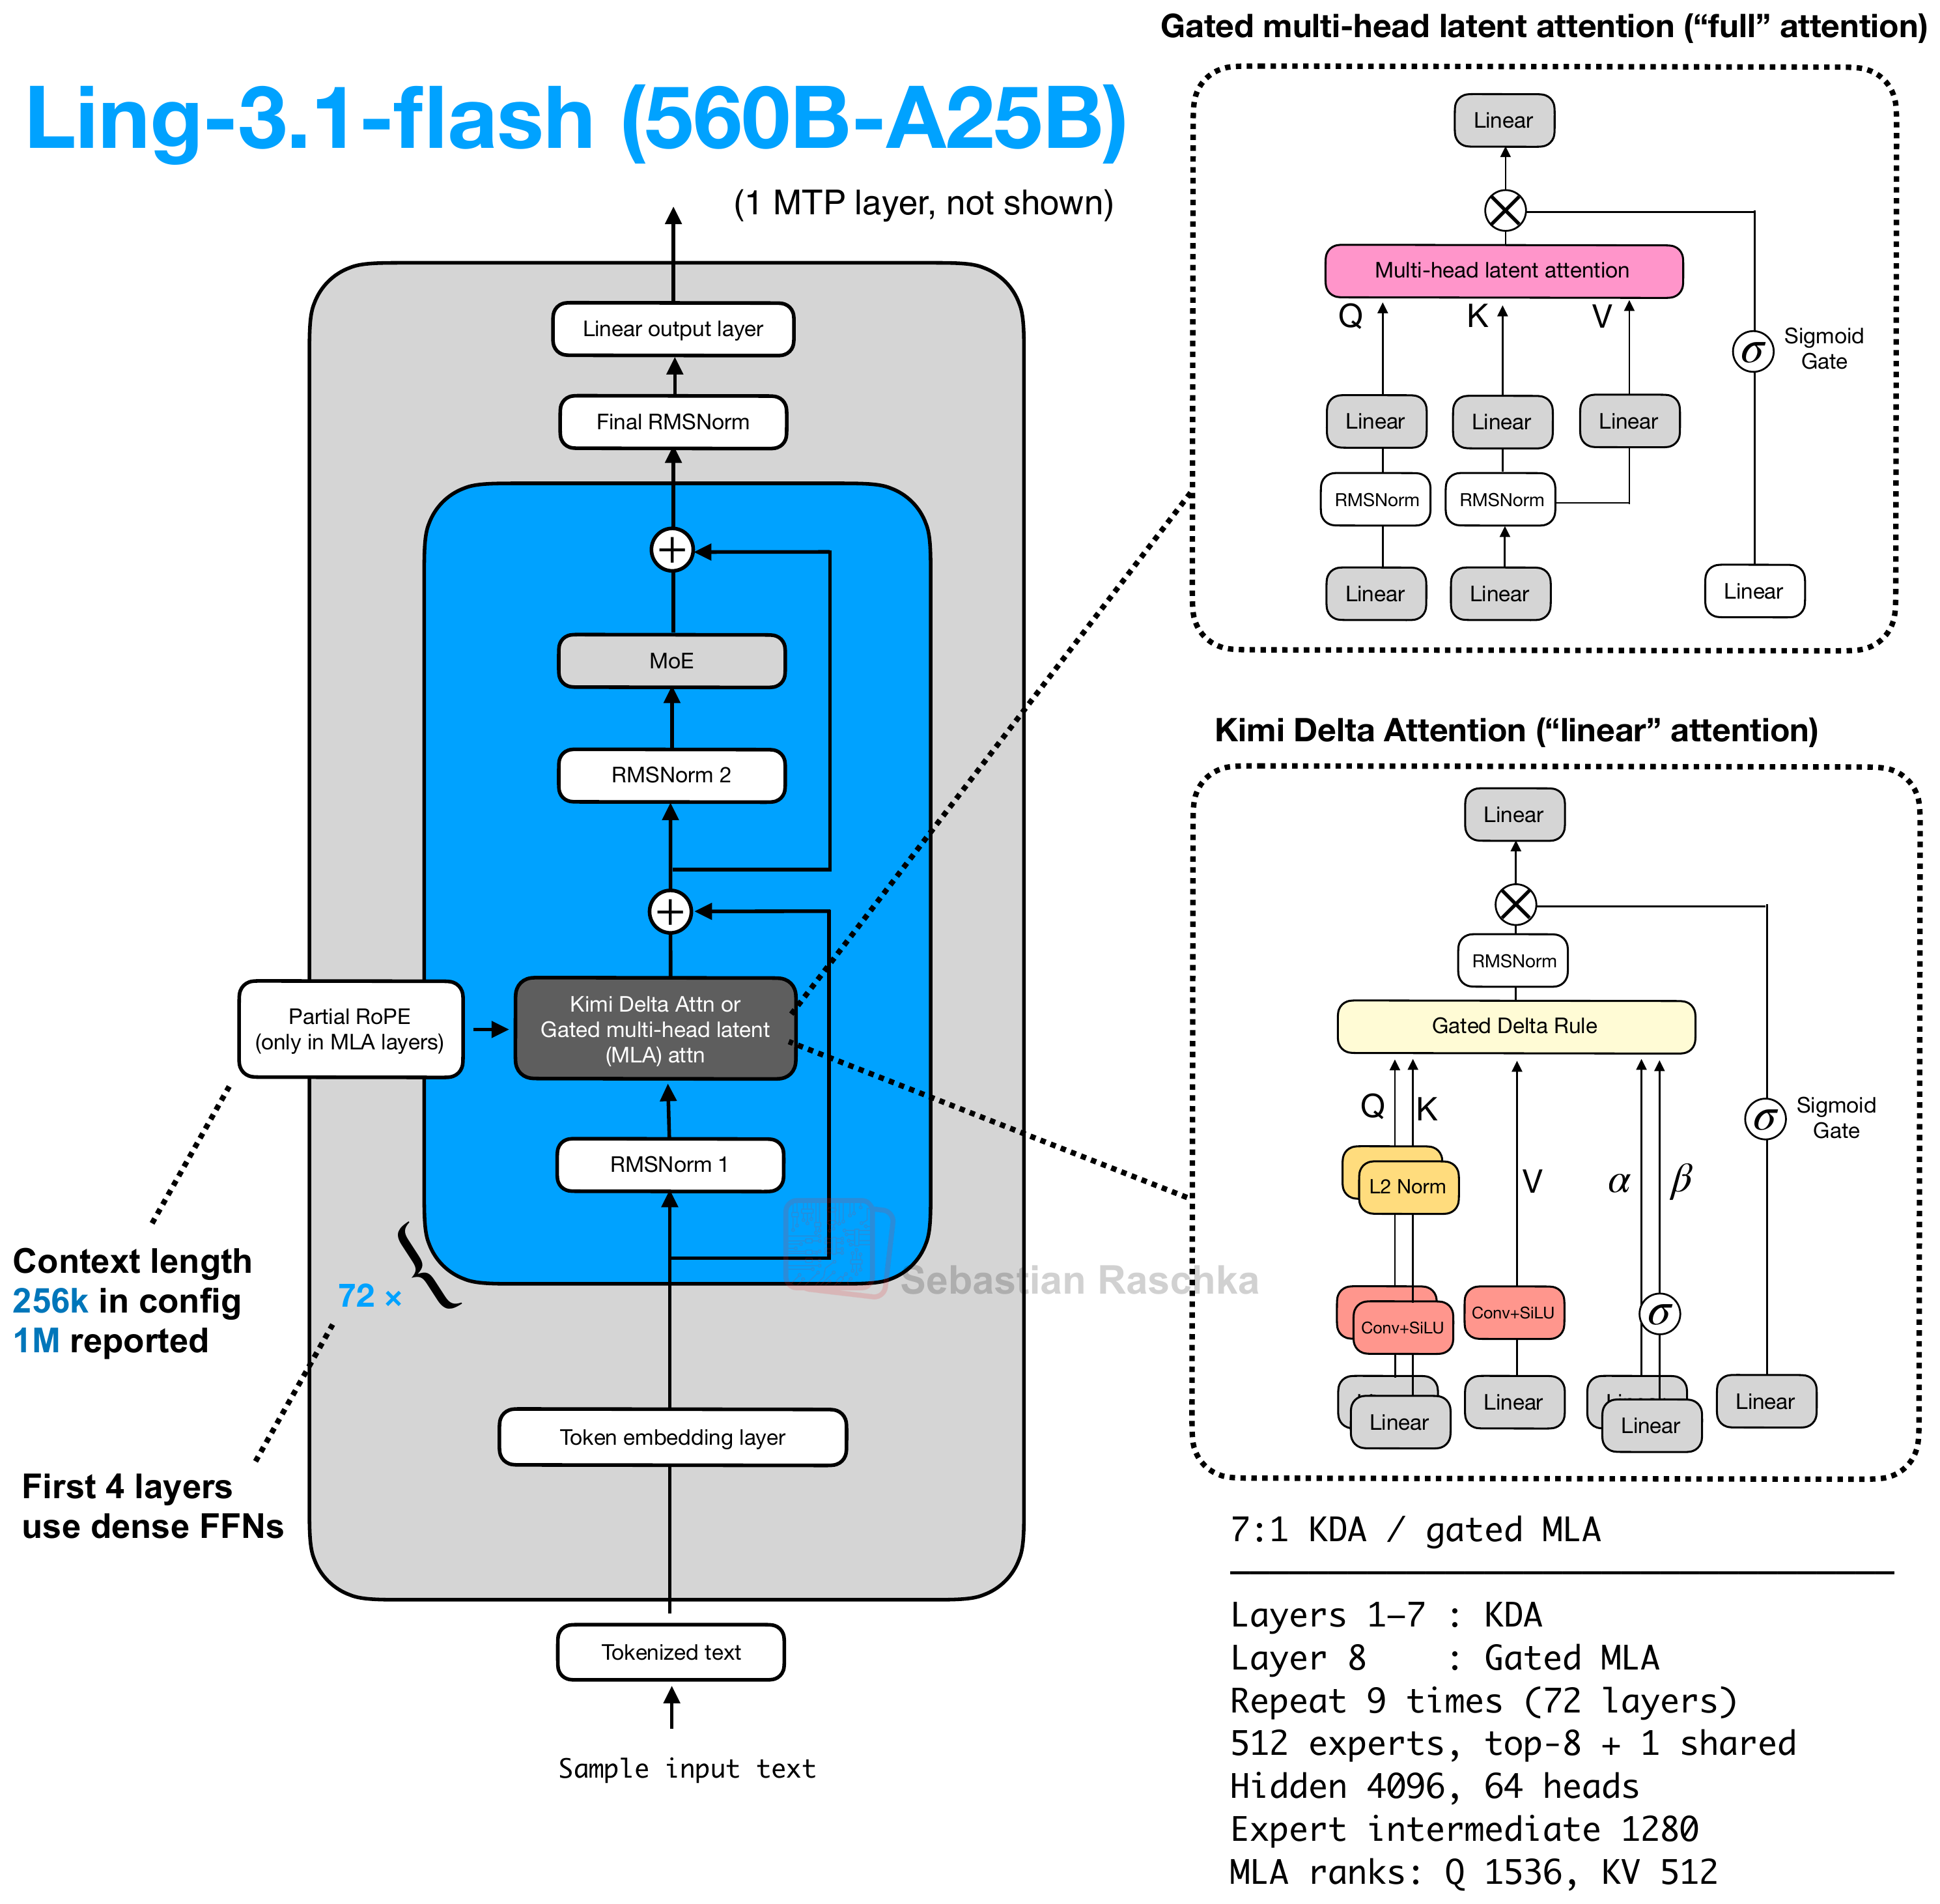
Hybrid MoE that extends Ling 3.0 Flash to 72 layers, with seven Kimi Delta Attention layers for every gated MLA layer.
Architecture and specifications
- Scale
- 560B total, 25B active (4.5% active)
- Context (tokens)
- 1M reported; 262,144 in config
- Vocabulary
- 157,184 (~157k)
- License
- MIT License
- Date
- 2026-10-13
- Decoder type
- Sparse hybrid
- Attention
- 7:1 Kimi Delta Attention and gated MLA
- Layer mix
- 63 Kimi Delta Attention + 9 gated MLA + 1 MTP layer
- KV cache / token (bf16) info
- 10.1 KiB · Very low
- Key detail
- Uses four initial dense FFN layers, top-8 routing over 512 experts plus one shared expert, and MLA with a 1,536-dimensional query bottleneck and 512-dimensional KV latent.
Training and benchmarks
- Pretraining data
- >10T tokens (training corpus) The official disclosure gives a lower bound on the preprocessed text corpus for Ling 3.1 Flash. It does not give tokens seen during pretraining. Training data summary
- Post-training methods
- RL The release post confirms reinforcement learning improved task performance while increasing reasoning length and interaction rounds. It does not specify the reward types or full recipe. Release post