
Ling 3.0 Flash Architecture
Back to Ling 3.0 Flash in the gallery
InclusionAI
Hybrid MoE that alternates five Kimi Delta Attention layers with one gated MLA layer.
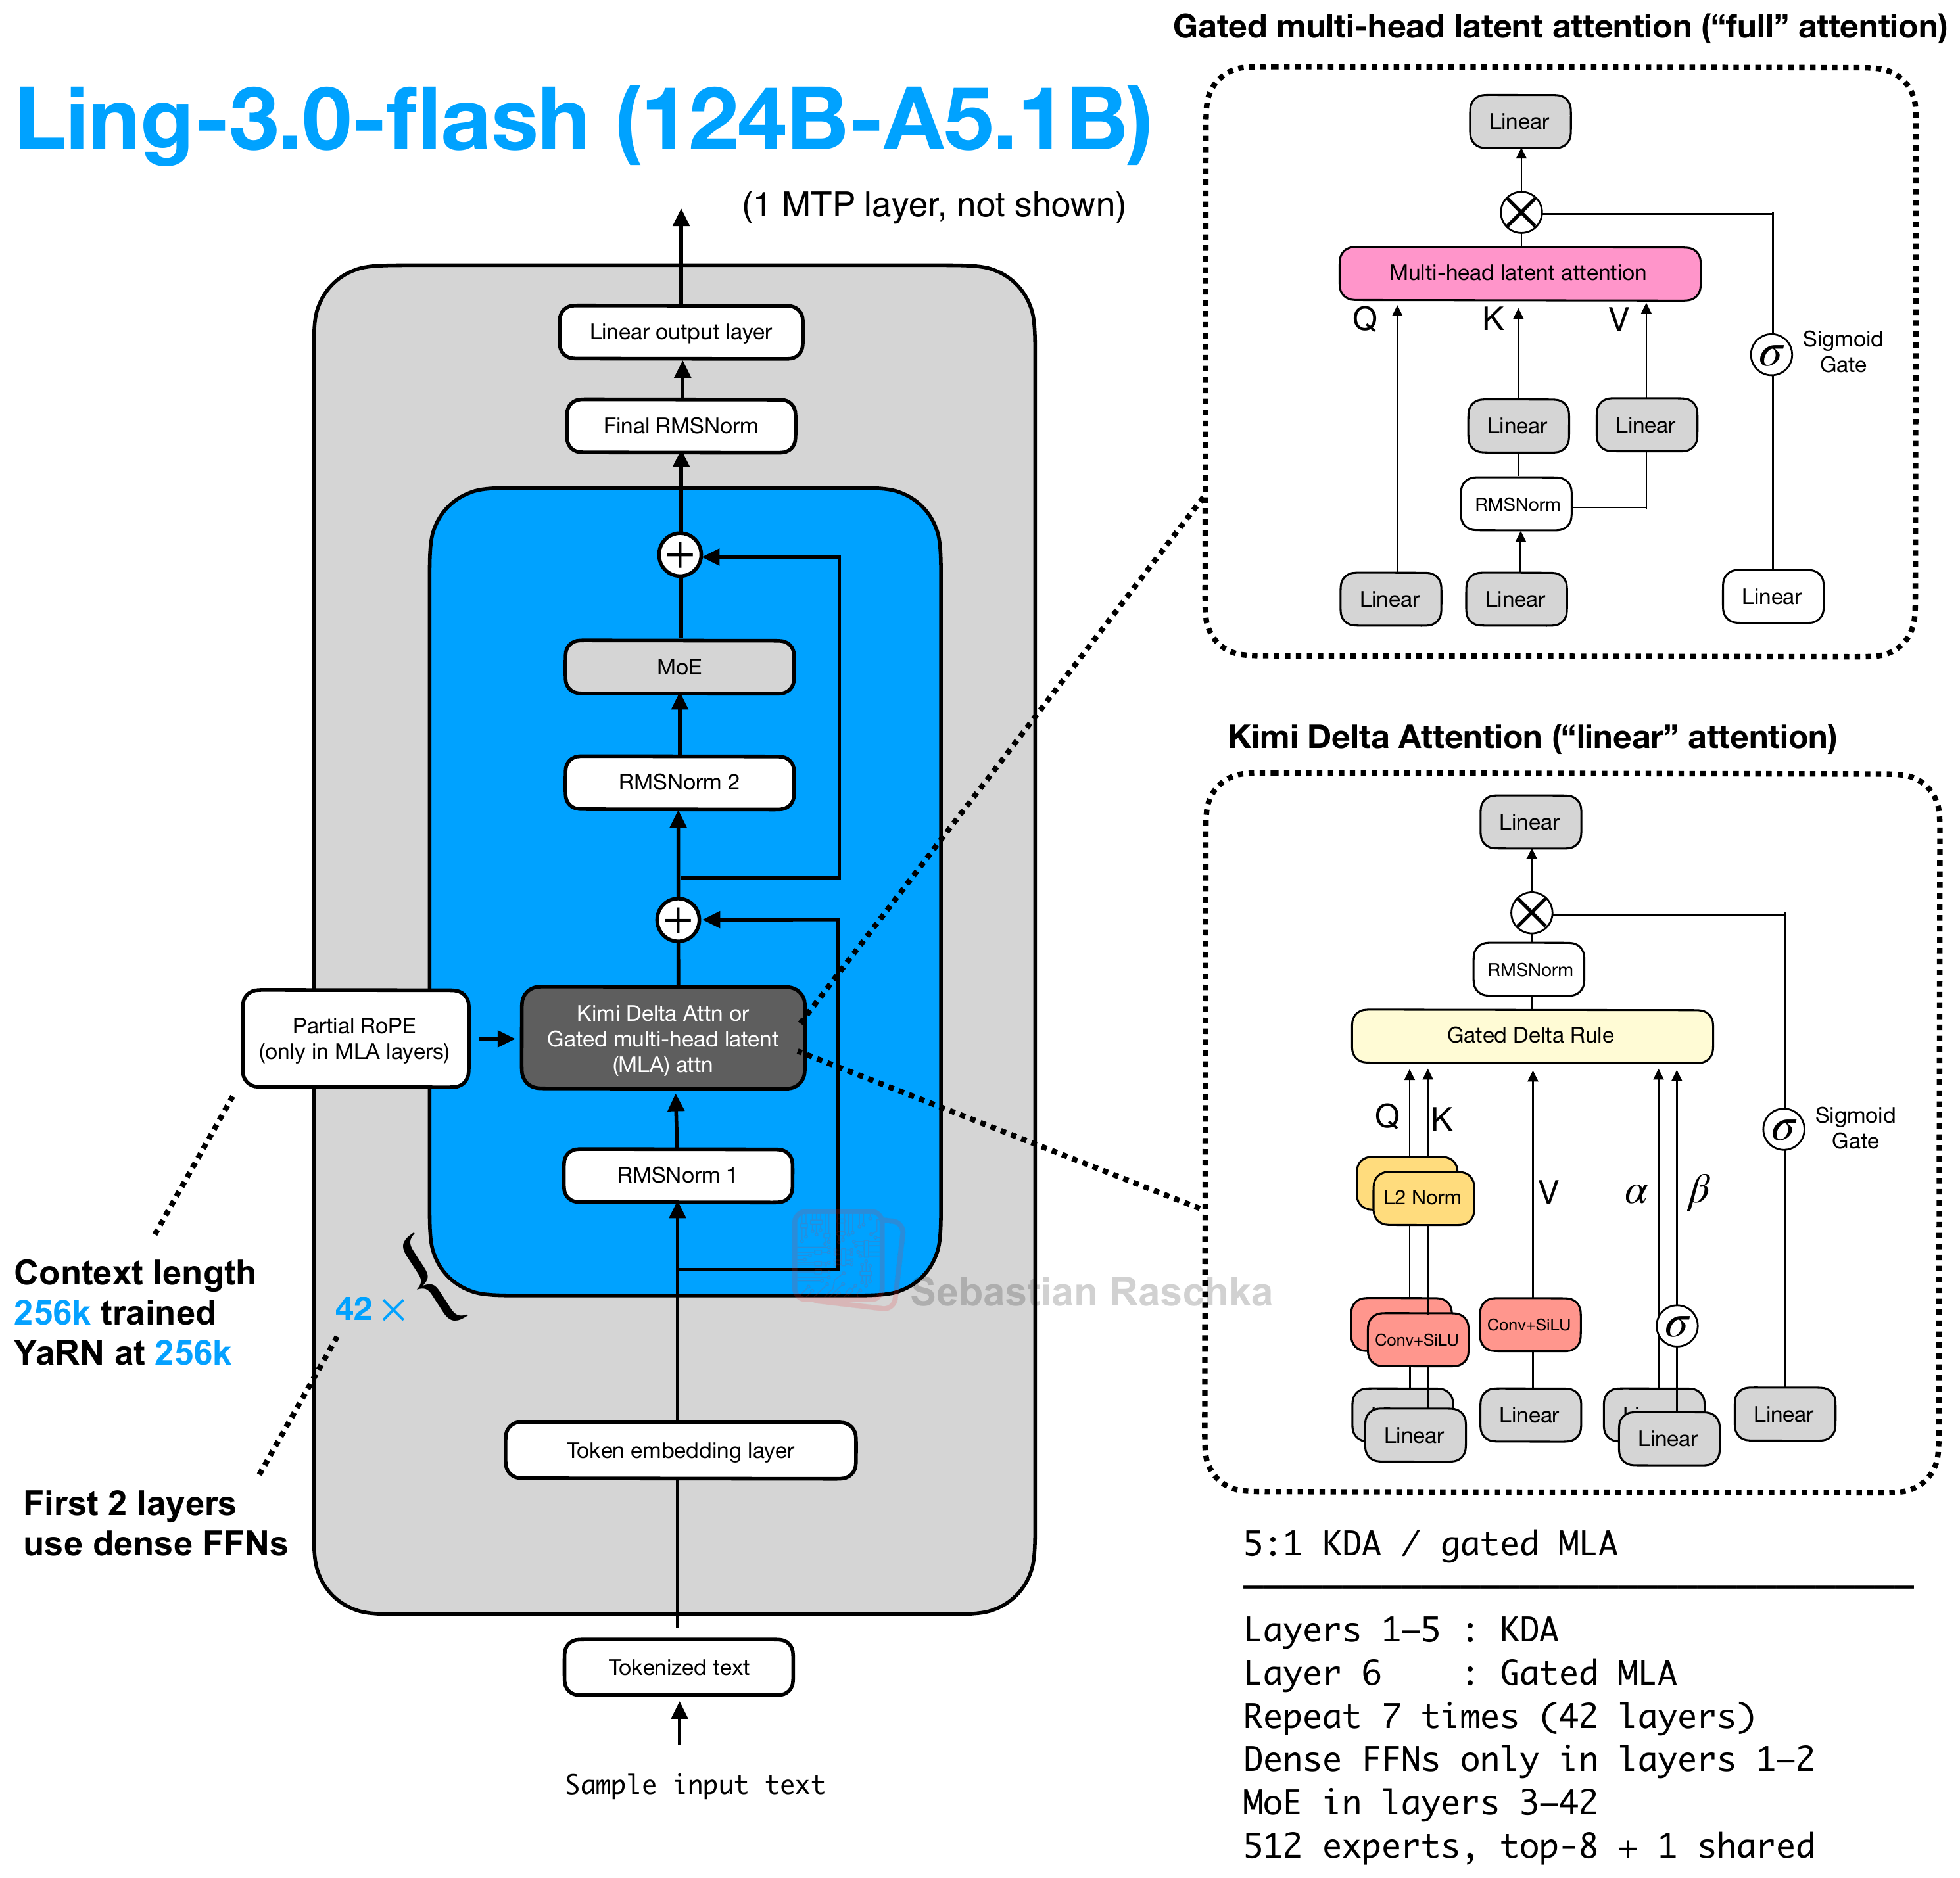
Architecture and specifications
- Scale
- 124B total, 5.1B active (4.1% active)
- Context (tokens)
- 262,144
- Vocabulary
- 157,184 (~157k)
- License
- MIT License
- Date
- 2026-08-04
- Decoder type
- Sparse hybrid
- Attention
- 5:1 Kimi Delta Attention and gated MLA
- Layer mix
- 35 Kimi Delta Attention + 7 gated MLA + 1 MTP layer
- KV cache / token (bf16) info
- 7.9 KiB · Very low
- Key detail
- Uses fine-grained diagonal KDA gating, top-8 routing over 512 experts plus one shared expert, and one MTP layer.
Training and benchmarks
- Pretraining data
- >10T tokens (training corpus) The official disclosure gives a lower bound on the preprocessed text corpus for the Ling 3.0 family, including Flash. It does not give tokens seen during pretraining. Training data summary
- Post-training methods
- RL Ant's developer documentation attributes improved long-horizon tool calling to reinforcement learning with stronger checks. The full alignment recipe is not disclosed. Developer documentation