
LFM3 1.7B Architecture
Back to LFM3 1.7B in the gallery
Liquid AI
Liquid AI's 1.73B dense hybrid combines short convolutions with sliding-window and global GQA in a 24-layer stack.
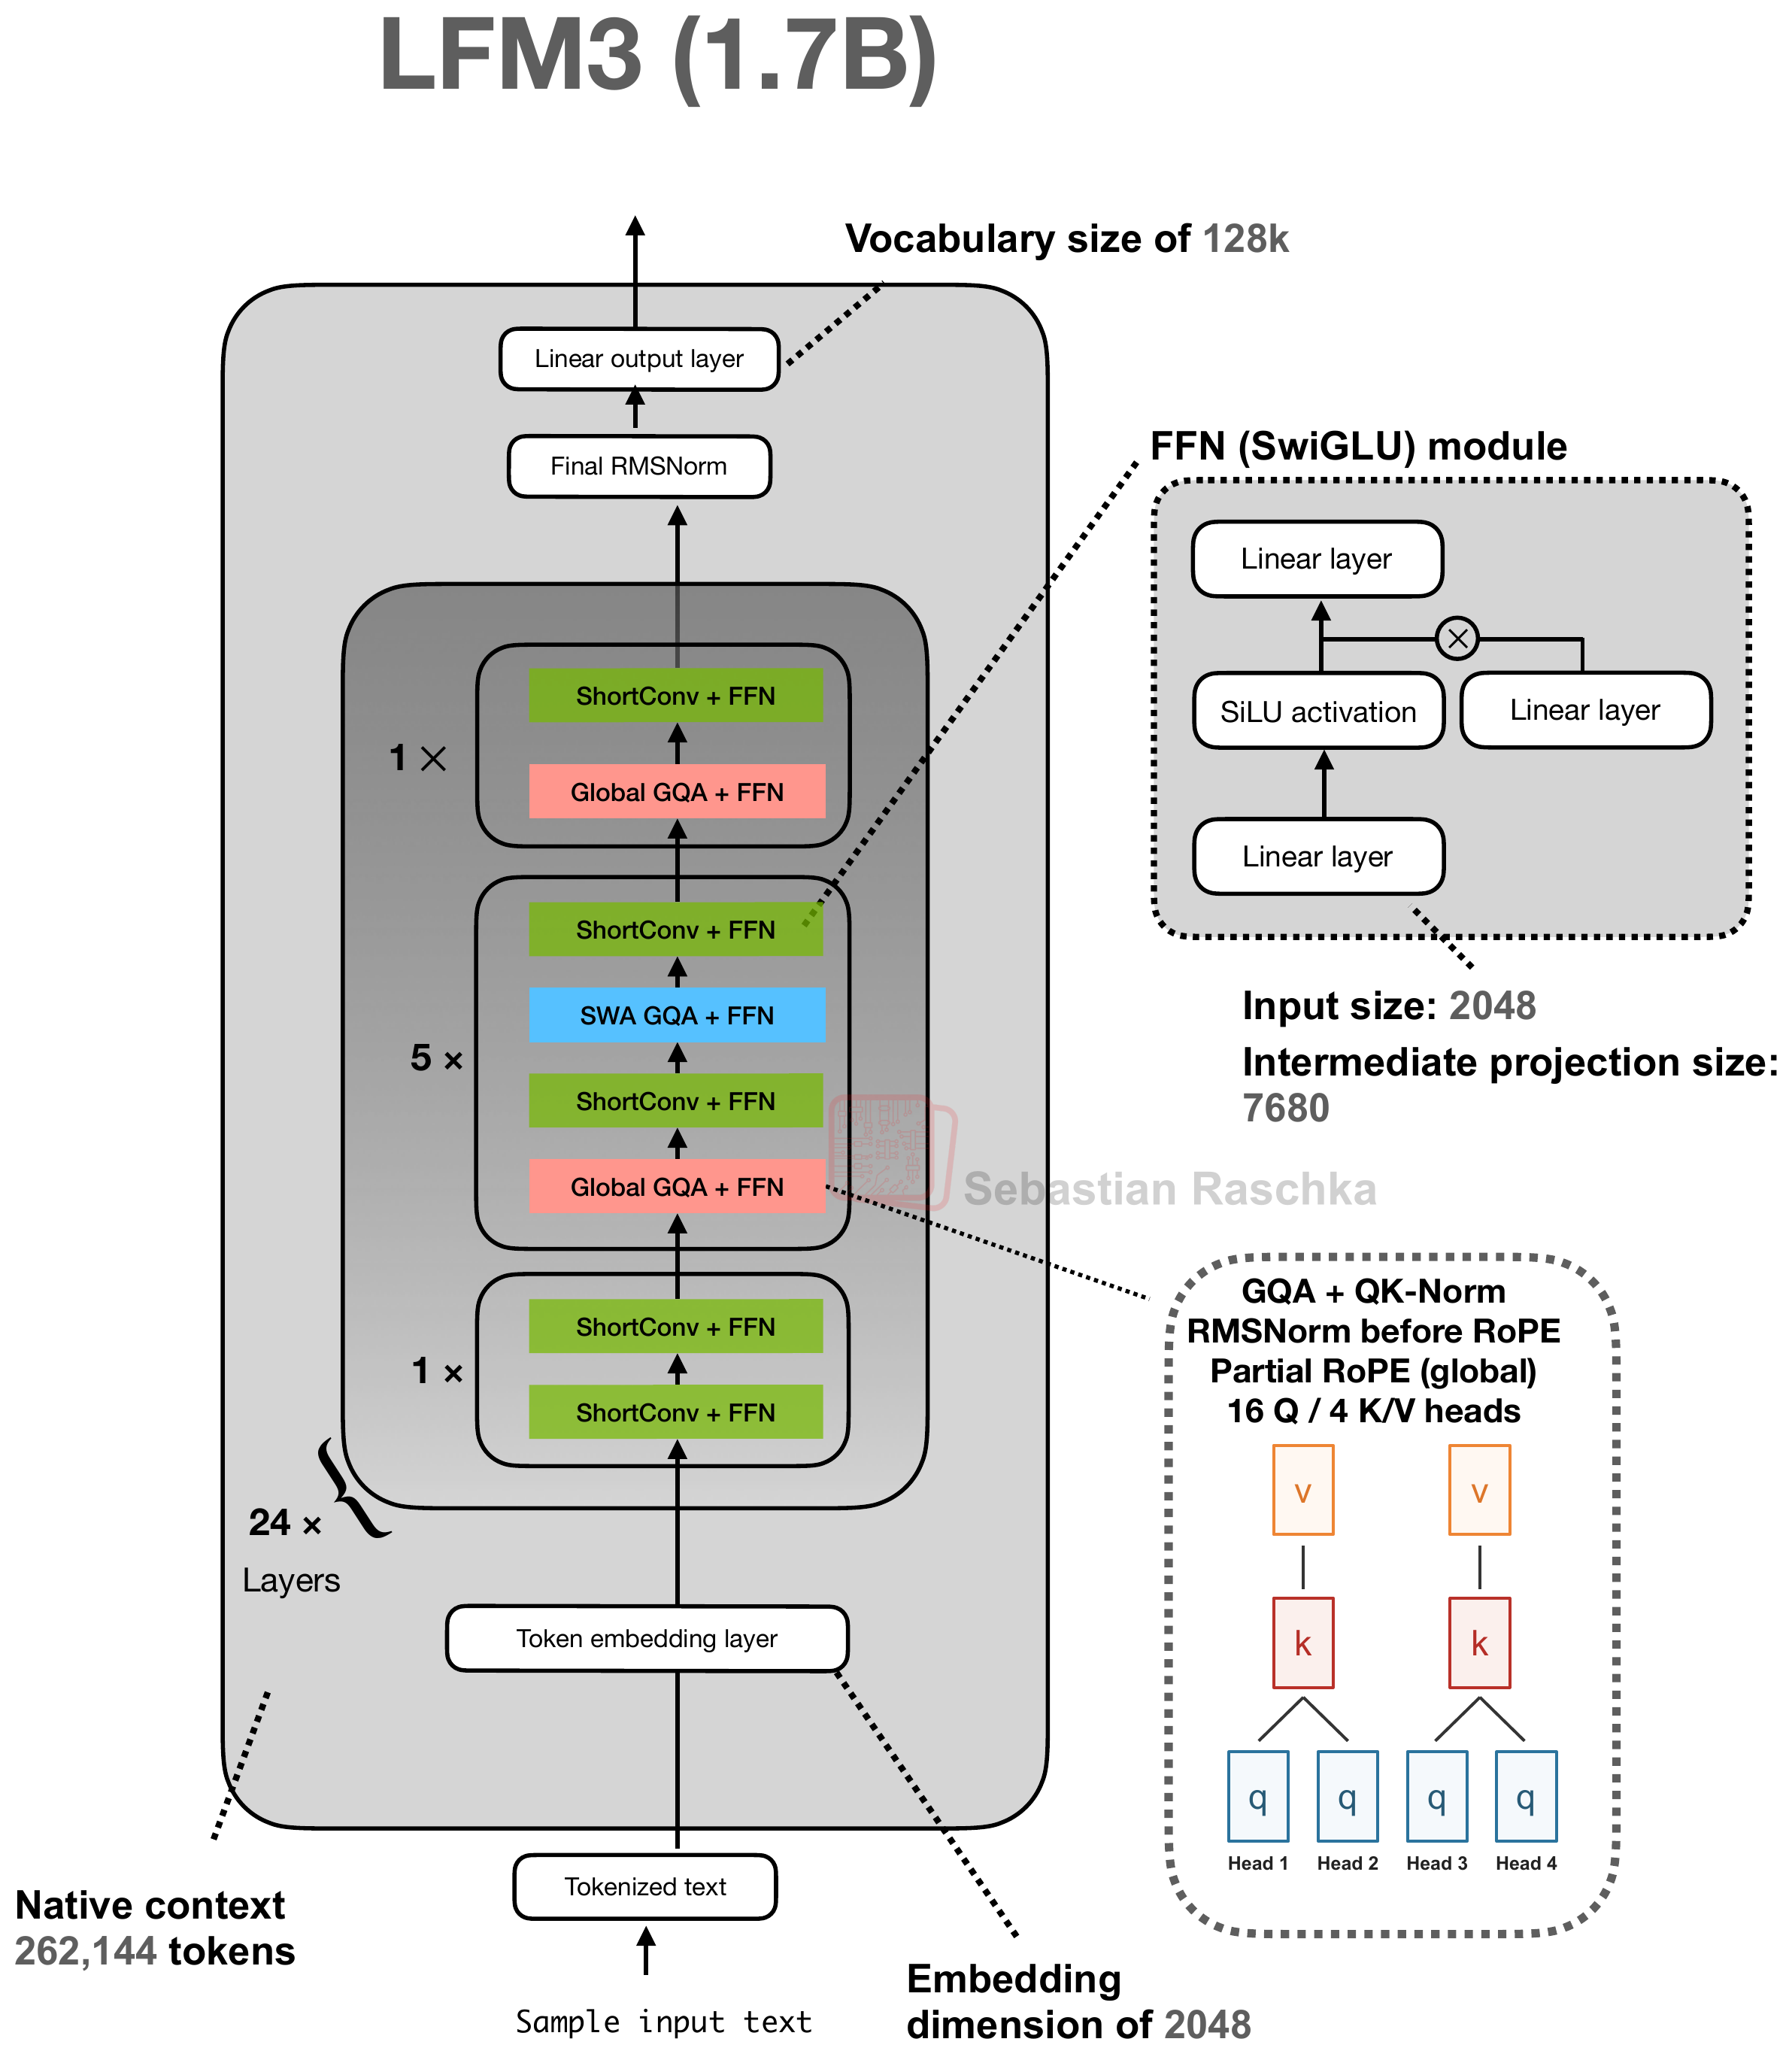
Architecture and specifications
- Scale
- 1.73B parameters
- Context (tokens)
- 262,144
- Vocabulary
- 128,000
- License
- LFM Open License v1.0
- Date
- 2026-10-27
- Decoder type
- Dense hybrid
- Attention
- ShortConv plus gated GQA with QK-Norm and sliding-window/global attention
- Layer mix
- 13 ShortConv + 5 sliding-window + 6 global GQA
- KV cache / token (bf16) info
- 22 KiB · Very low
- Key detail
- Uses kernel-7 ShortConv, a 256-token attention window, per-head sigmoid gates, and sandwich RMSNorm. Global attention uses 50% partial RoPE.
Training and benchmarks
- Pretraining data
- 22T tokens Includes the last 3.5T tokens of midtraining and context extension; the separate SFT budget is excluded. Model card
- Post-training methods
- SFT, RL, Distillation SFT is followed by mixed-domain RL, on-policy distillation from six specialist RL teachers, and a final agentic RL stage. Model card