
Inkling Architecture
Back to Inkling in the gallery
Thinking Machines Lab
Thinking Machines Lab's native multimodal model combines a 66-layer sparse MoE decoder with a 5:1 mix of local and global GQA.
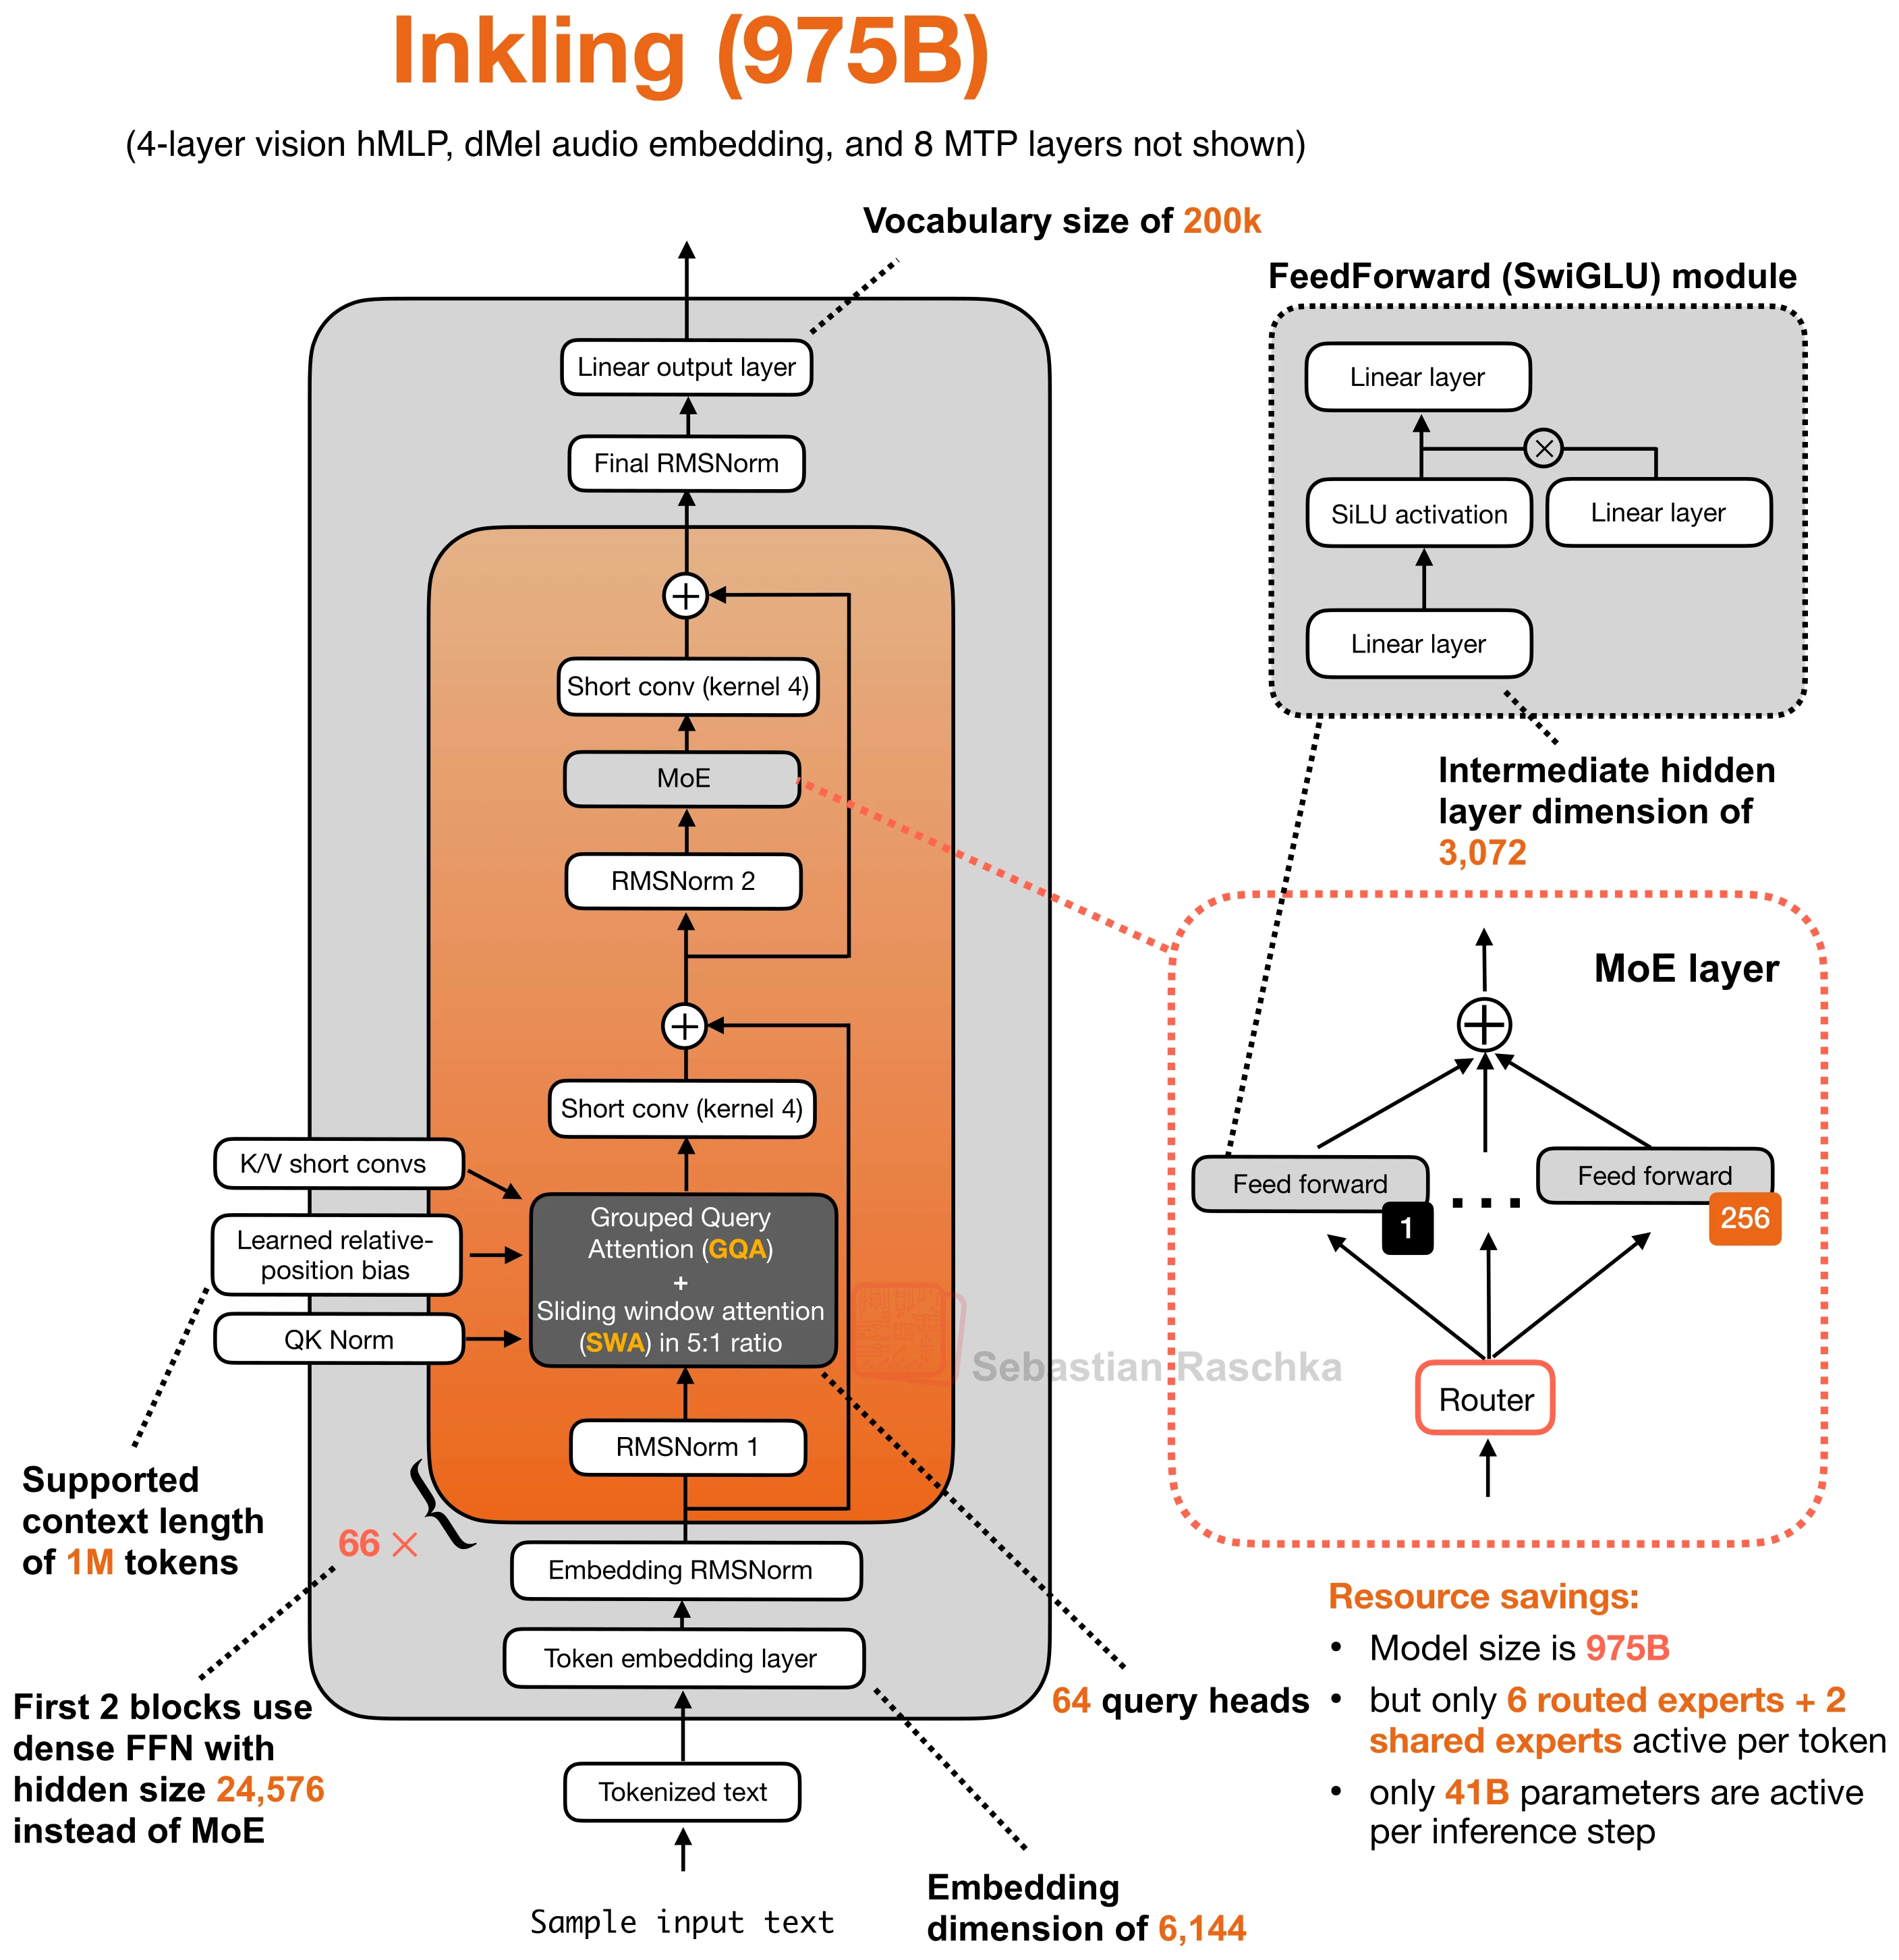
Architecture and specifications
- Scale
- 975B total, 41B active (4.2% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 200,058 (~200k)
- License
- Apache License 2.0
- Date
- 2026-07-15
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm and learned relative-position bias in a 5:1 sliding-window/global pattern
- Layer mix
- 55 sliding-window + 11 global GQA
- KV cache / token (bf16) info
- 484 KiB · Very high
- Key detail
- Uses learned relative-position bias instead of RoPE and adds four short convolutions to each decoder layer.
Training and benchmarks
- Pretraining data
- 45T tokens Multimodal pretraining on text, images, audio, and video. Training overview
- Post-training methods
- SFT, RL Synthetic-data SFT bootstrap followed by large-scale asynchronous RL across multiple domains. Training overview