
DeepSeek V4-Pro Architecture
Back to DeepSeek V4-Pro in the gallery
DeepSeek
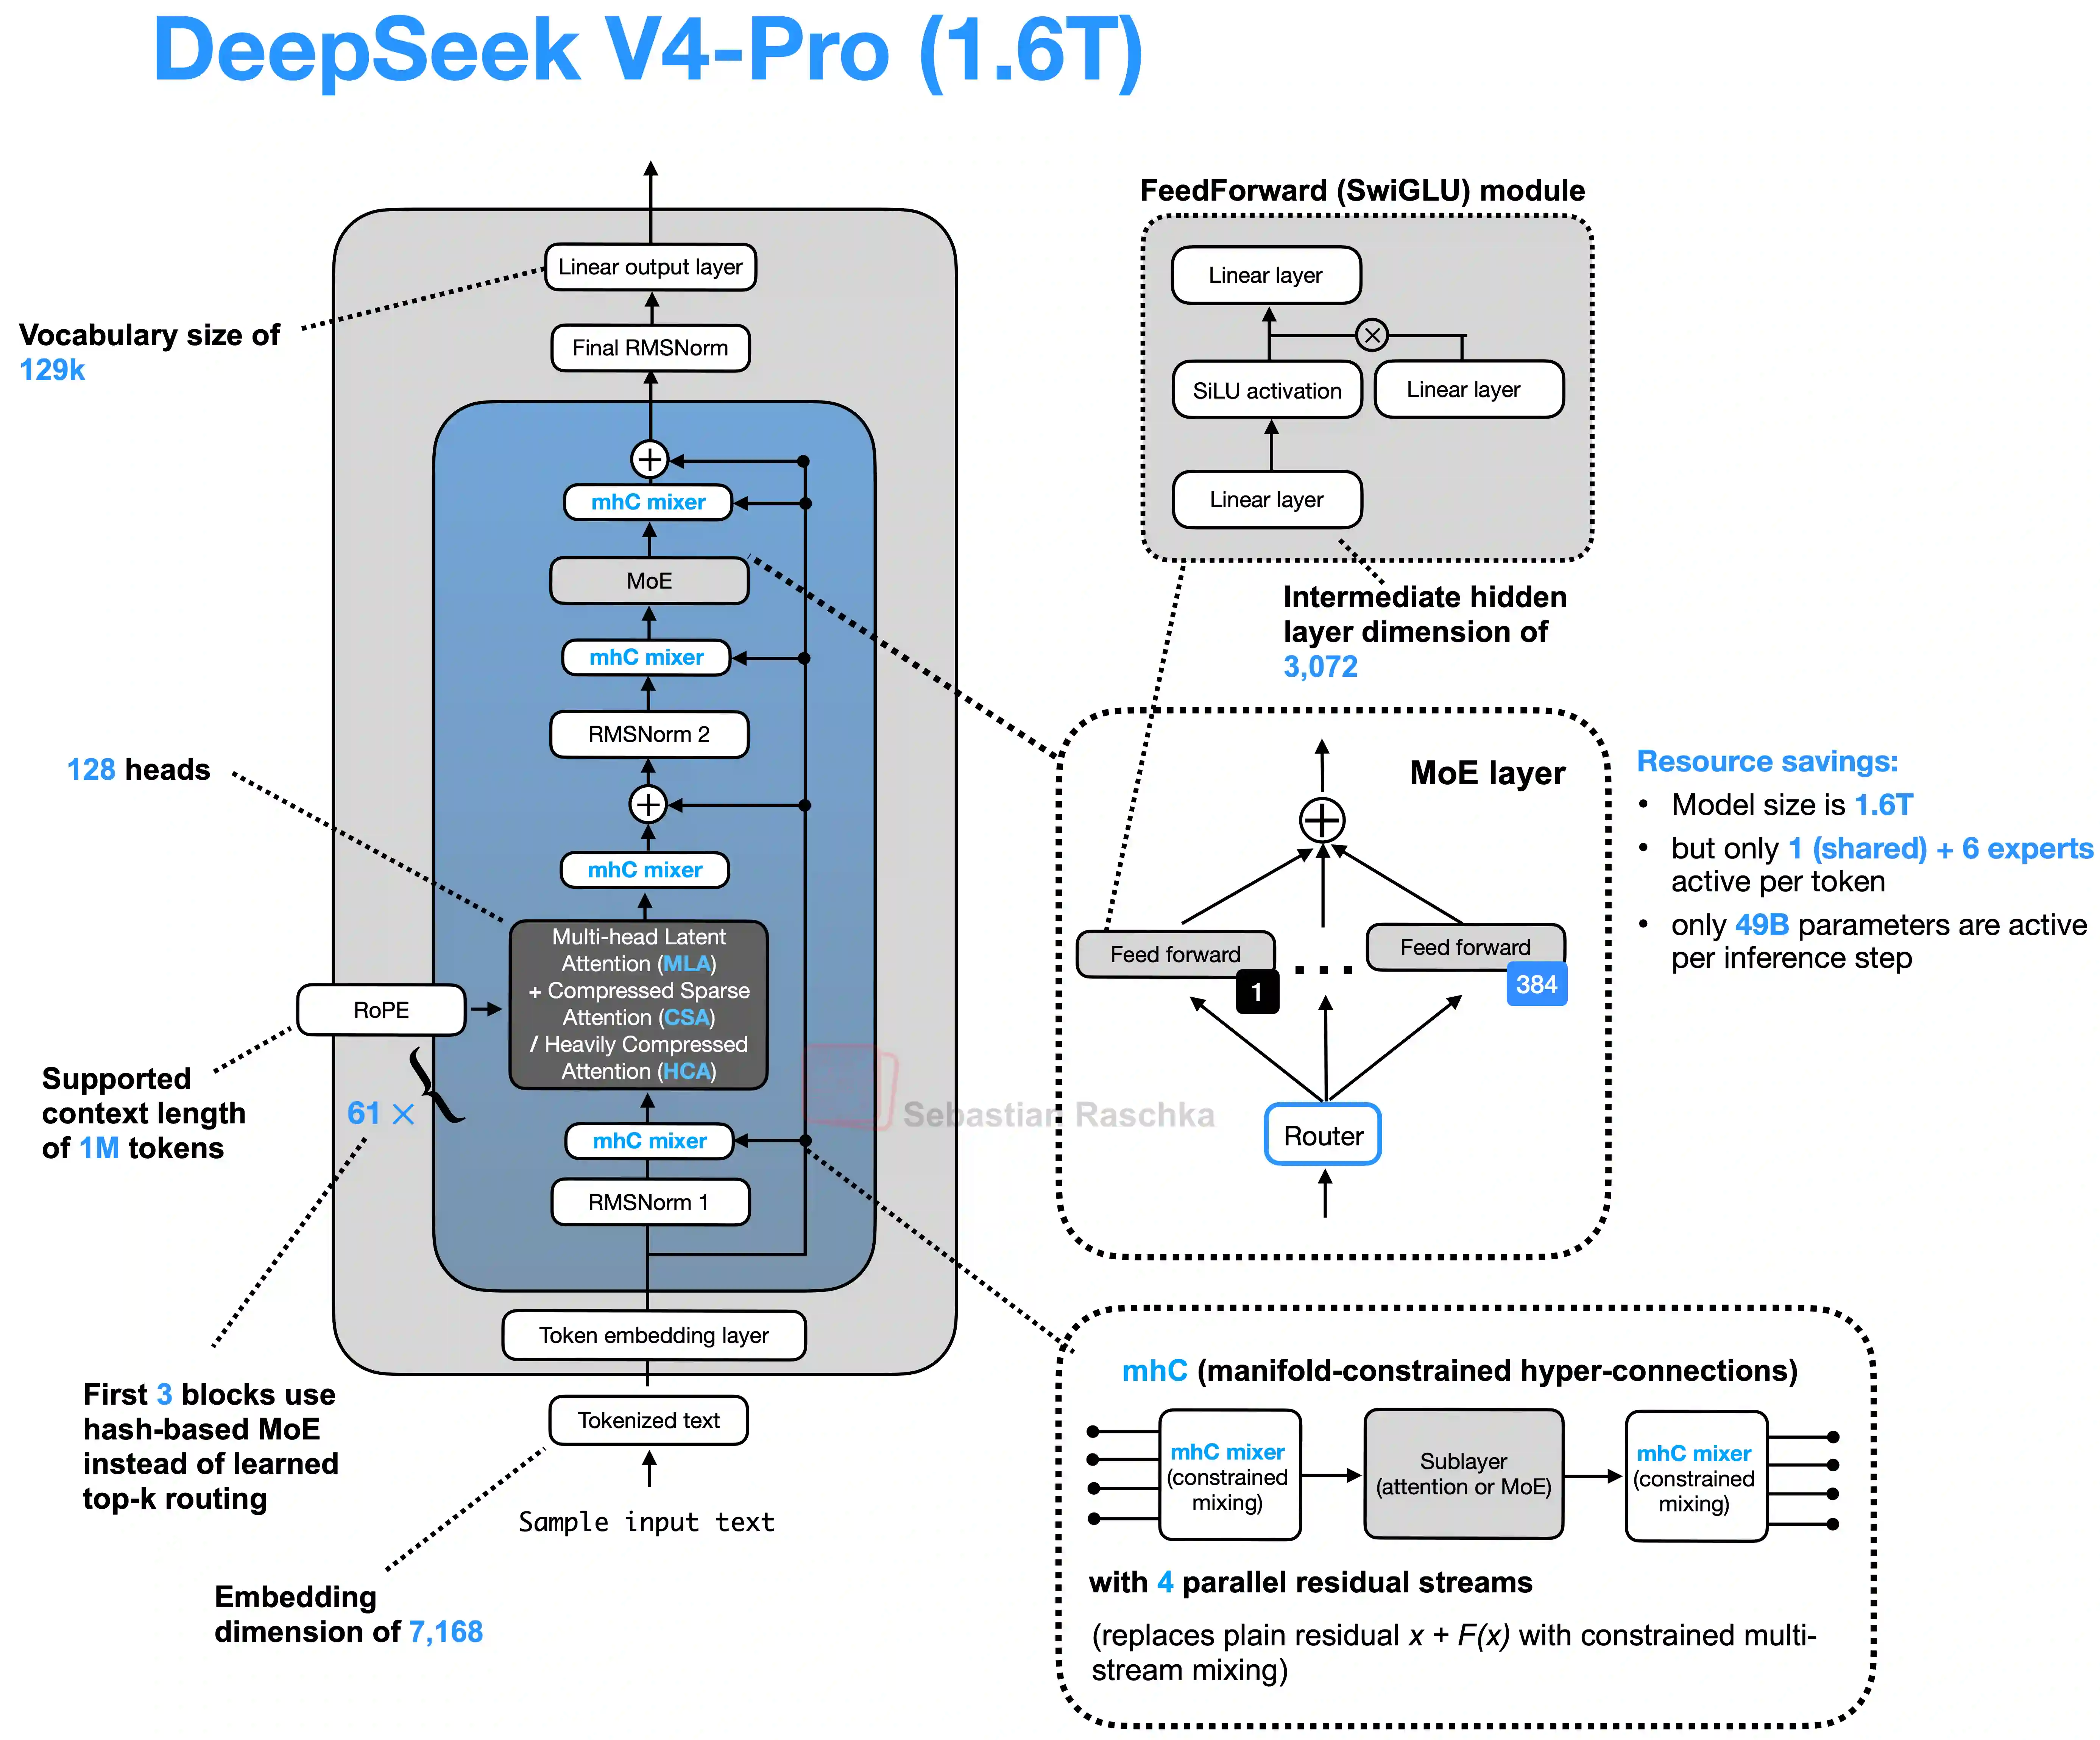
DeepSeek's flagship V4 preview scales to 1.6T parameters and introduces compressed sparse attention plus manifold-constrained hyper-connections for million-token contexts.
Architecture and specifications
- Scale
- 1.6T total, 49B active (3.1% active)
- Context (tokens)
- 1,048,576
- License
- MIT License
- Date
- 2026-04-24
- Decoder type
- Sparse MoE
- Attention
- MLA-style CSA/HCA with mHC
- Layer mix
- 61 CSA/HCA
- KV cache / token (bf16) info
- 9.62 KiB (growing global cache only) · Very low
- Key detail
- Uses 384 experts, 6 routed plus 1 shared expert per token, hash-based routing, compressed attention caches, and the V4 MTP path.
Training and benchmarks
- Pretraining data
- 33T tokens Includes staged context extension to 1M tokens. DeepSeek V4 report
- Post-training methods
- SFT, RLVR, RL, Distillation Domain experts receive SFT and GRPO, using verifiers and generative rewards, then are combined through on-policy distillation. DeepSeek V4 report