
Xiaomi MiMo-V2.6-Pro-RL 1.02T Architecture
Back to Xiaomi MiMo-V2.6-Pro-RL 1.02T in the gallery
Xiaomi
Omnimodal sparse MoE model with the MiMo-V2.5-Pro text backbone, mixed-domain reinforcement learning, and a five-layer DFlash speculative decoder.
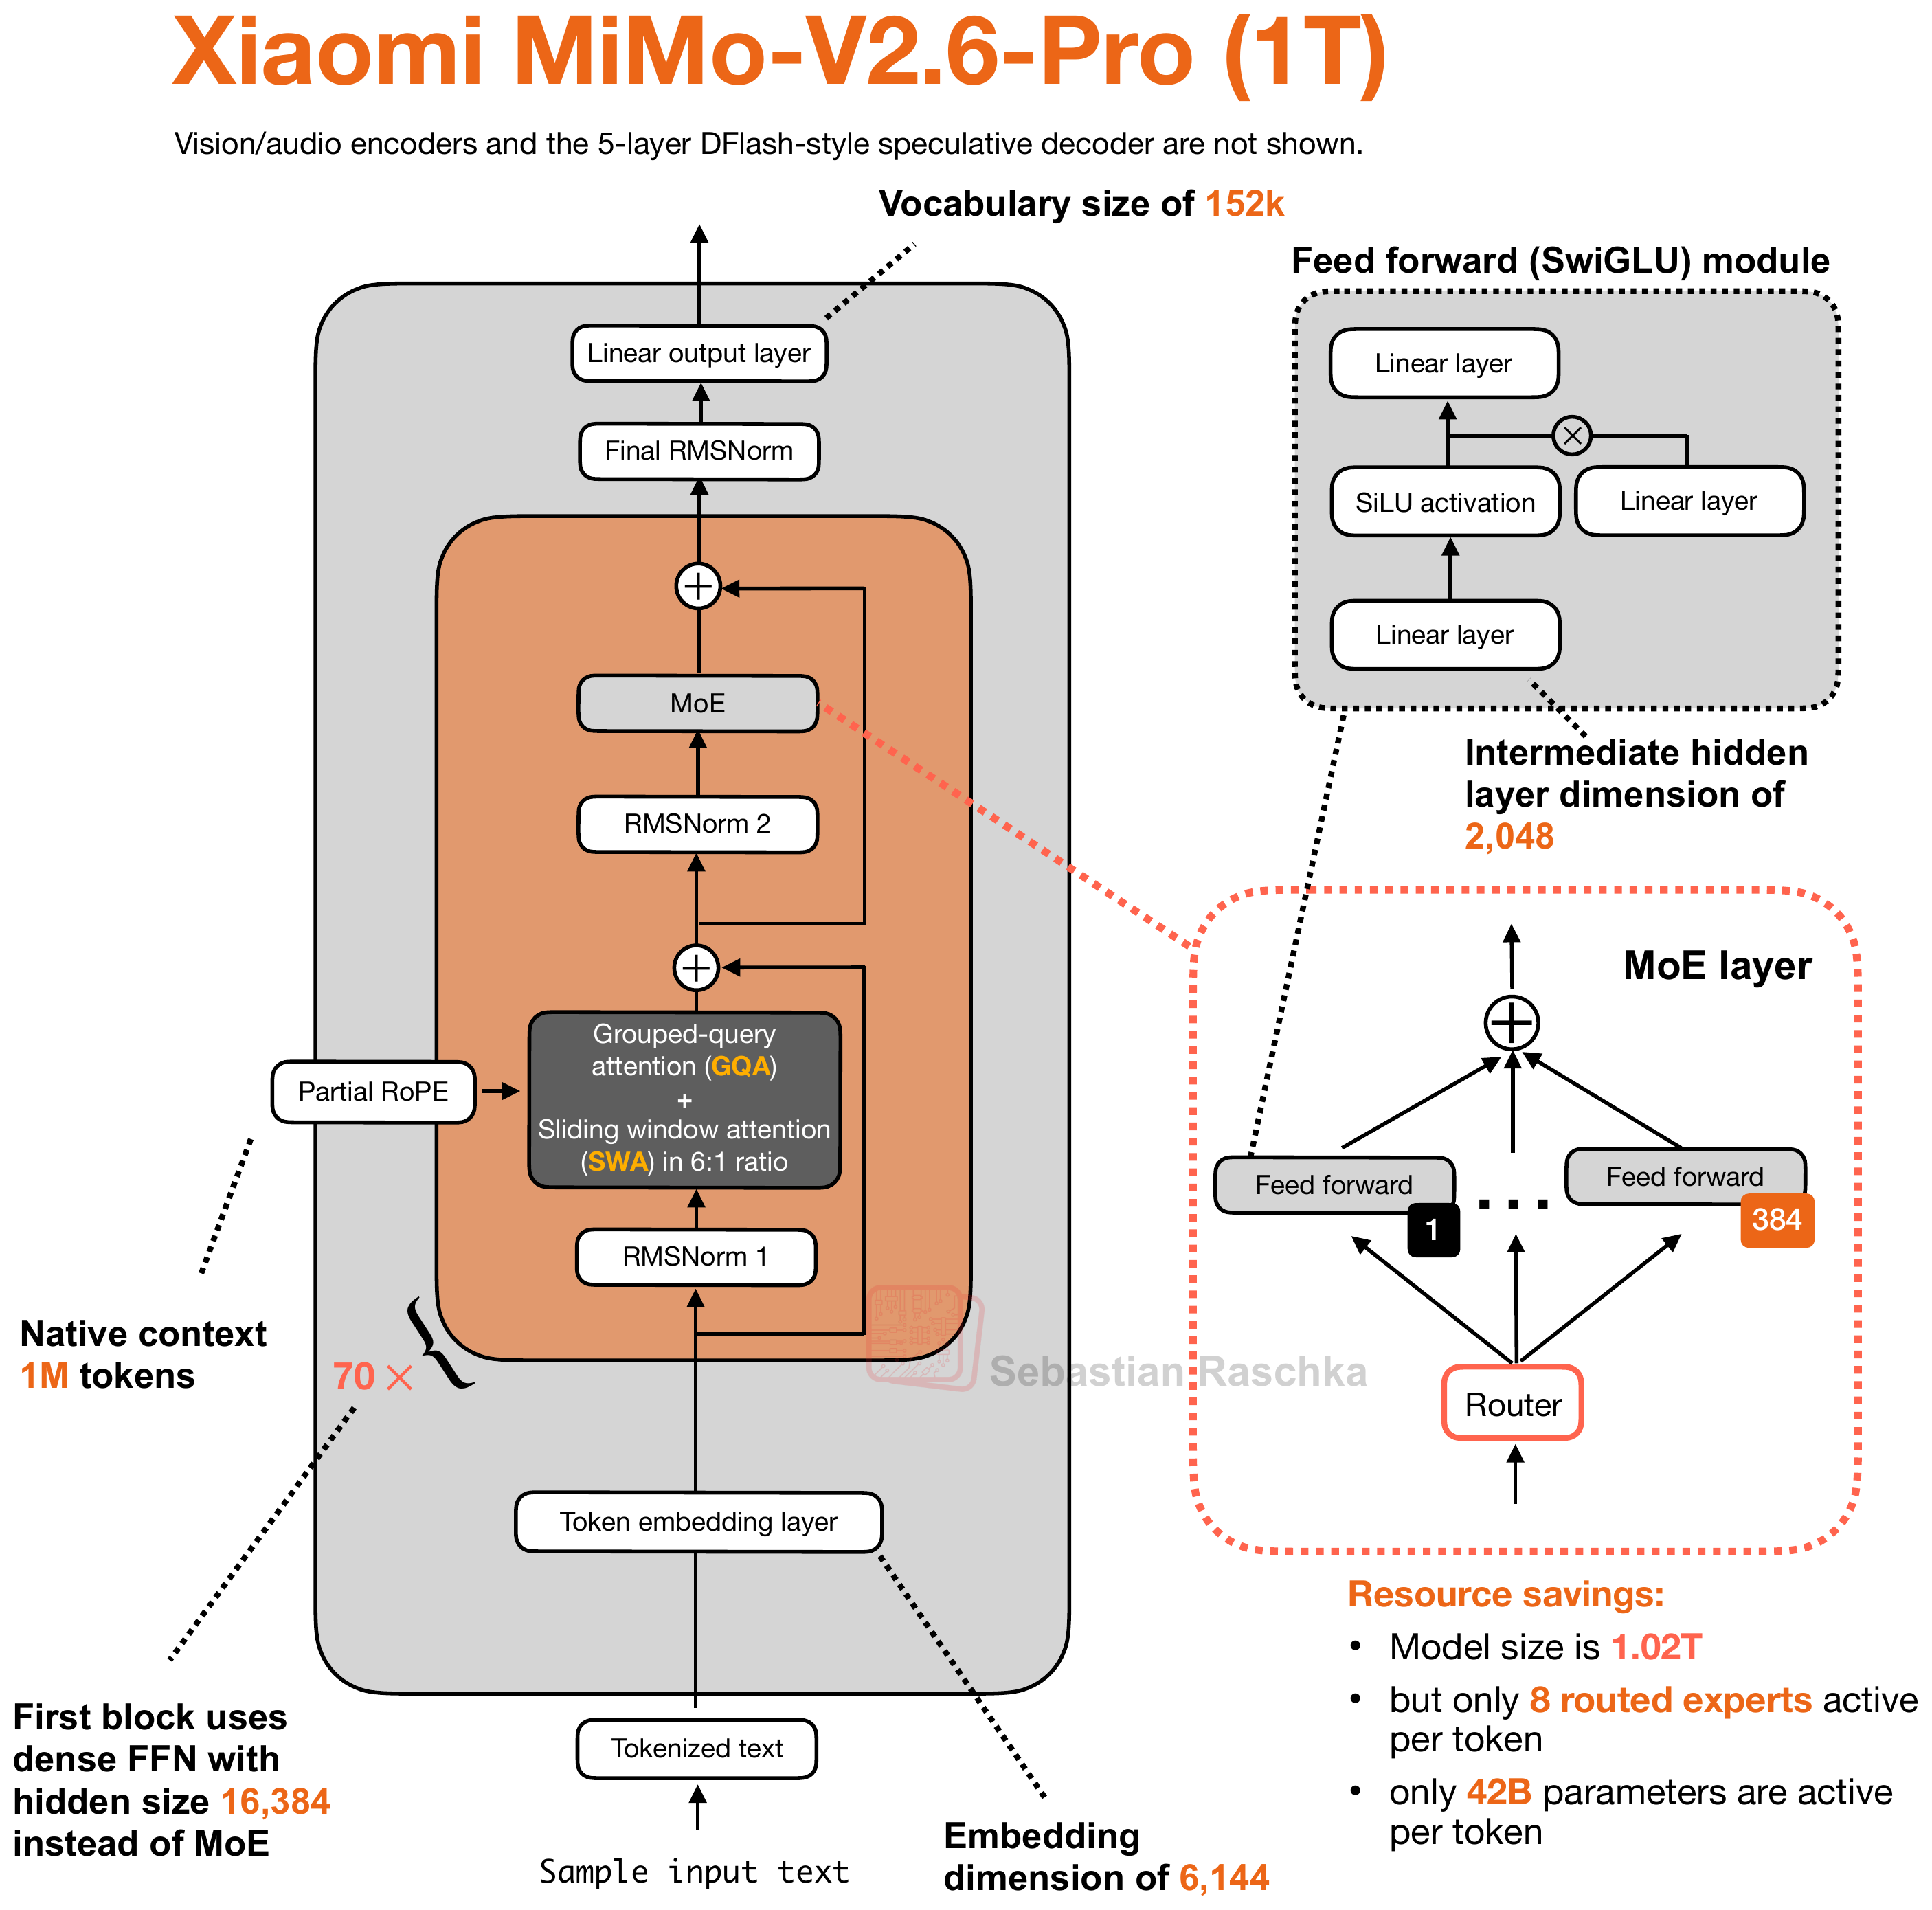
Architecture and specifications
- Scale
- 1.02T total, 42B active (4.1% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 152,576 (~152k)
- License
- MIT License
- Date
- 2026-09-21
- Decoder type
- Sparse omnimodal MoE
- Attention
- GQA with 6:1 sliding-window/global attention
- Layer mix
- 60 sliding-window + 10 global
- KV cache / token (bf16) info
- 350 KiB · Very high
- Key detail
- Uses 384 routed experts with top-8 routing, one dense prefix layer, no shared experts, and a 128-token sliding window.
Training and benchmarks
- Pretraining data
- 30T tokens 27T text-stage tokens plus 3T omni-stage tokens. Technical report
- Post-training methods
- SFT, RLVR, Distillation Short SFT, mixed-task GRPO using tests and agentic graders, and MOPD2 distillation described in the series recipe. Technical report