
Recursive Flint 40B-A2.5B Architecture
Back to Recursive Flint 40B-A2.5B in the gallery
Recursive
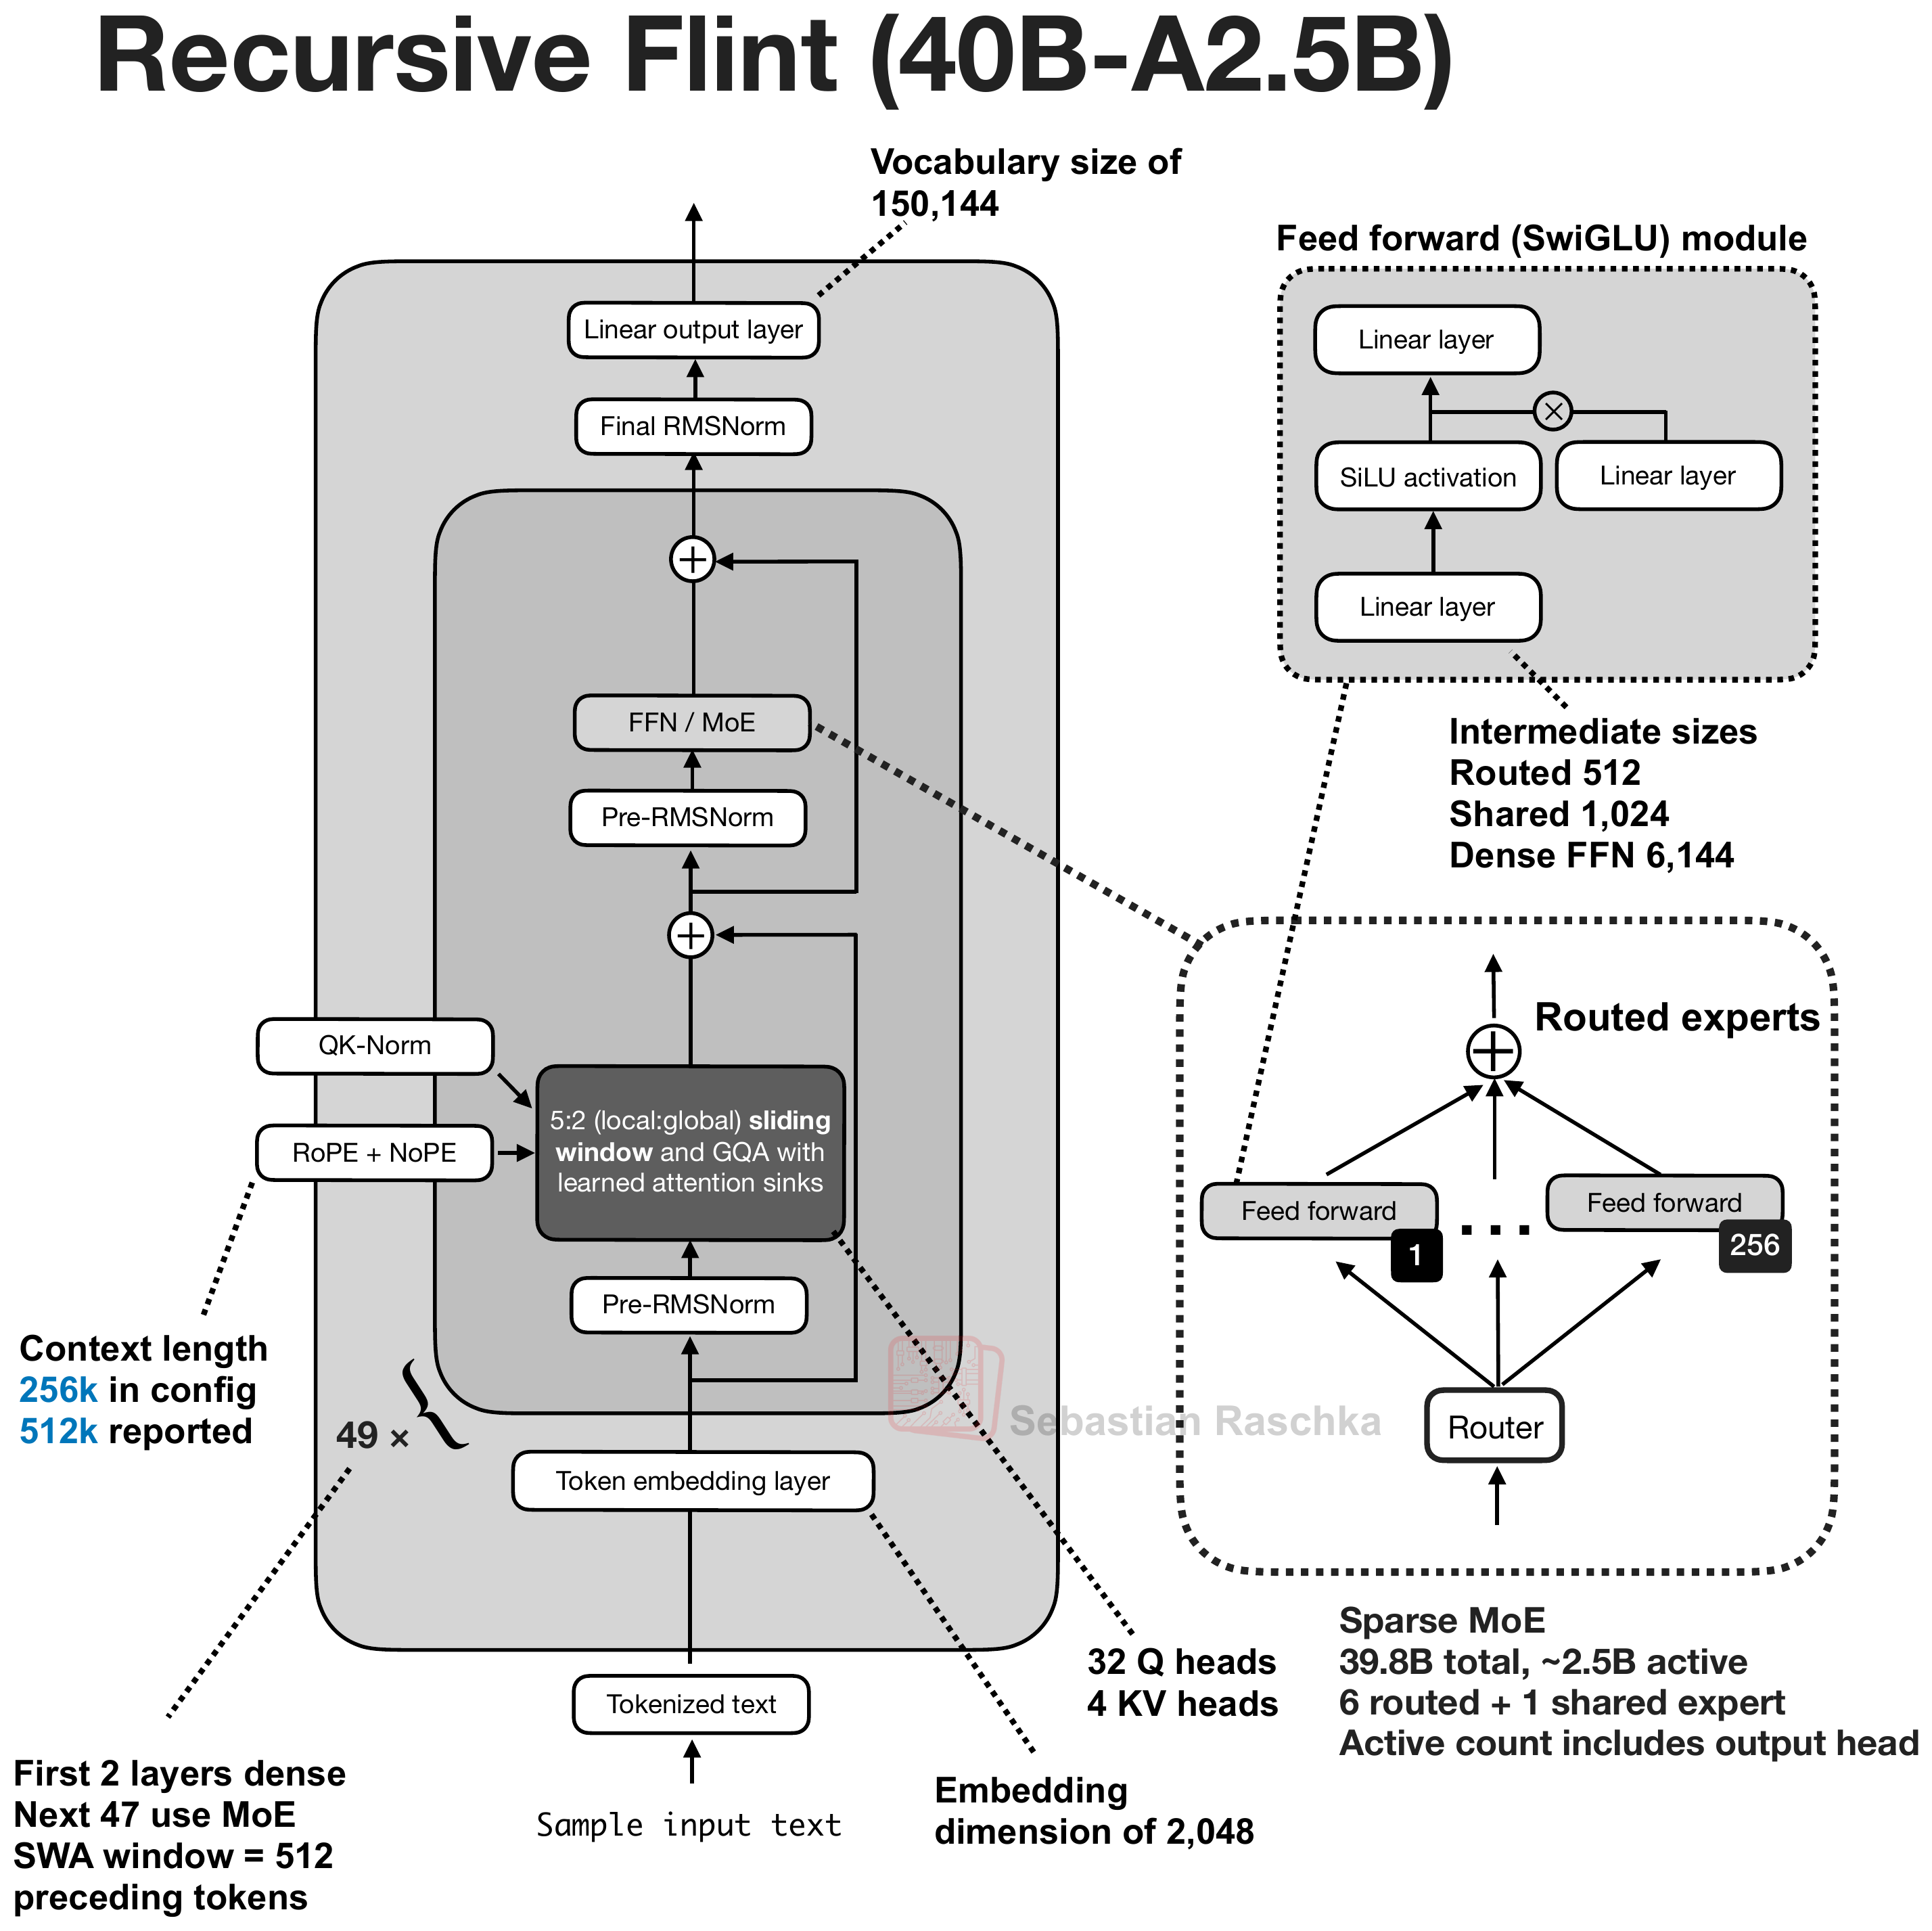
Recursive's coding model uses two dense FFN layers followed by 47 MoE layers. The active-parameter count includes the output head.
Architecture and specifications
- Scale
- 39.8B total, 2.5B active (6.3% active)
- Context (tokens)
- 262,144 configured; 512k supported
- Vocabulary
- 150,144
- License
- Apache License 2.0
- Date
- 2026-10-18
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm, learned attention sinks, and sliding-window/global attention
- Layer mix
- 35 sliding-window + 14 global GQA
- KV cache / token (bf16) info
- 98 KiB · Moderate
- Key detail
- Uses top-6 routing over 256 experts plus one shared expert, with RoPE in local layers, NoPE in global layers, and a local window covering the current token and 512 preceding tokens.
Training and benchmarks
- Pretraining data
- Not disclosed The card describes training from scratch but omits the token count. Model card
- Post-training methods
- SFT, RL The card explicitly lists supervised fine-tuning and reinforcement learning after pretraining and mid-training. Model card