
North Mini Code 30B-A3B Architecture
Back to North Mini Code 30B-A3B in the gallery
Cohere
Cohere's compact agentic coding MoE adapts the parallel Cohere2-MoE block to a 30B total, 3B active model.
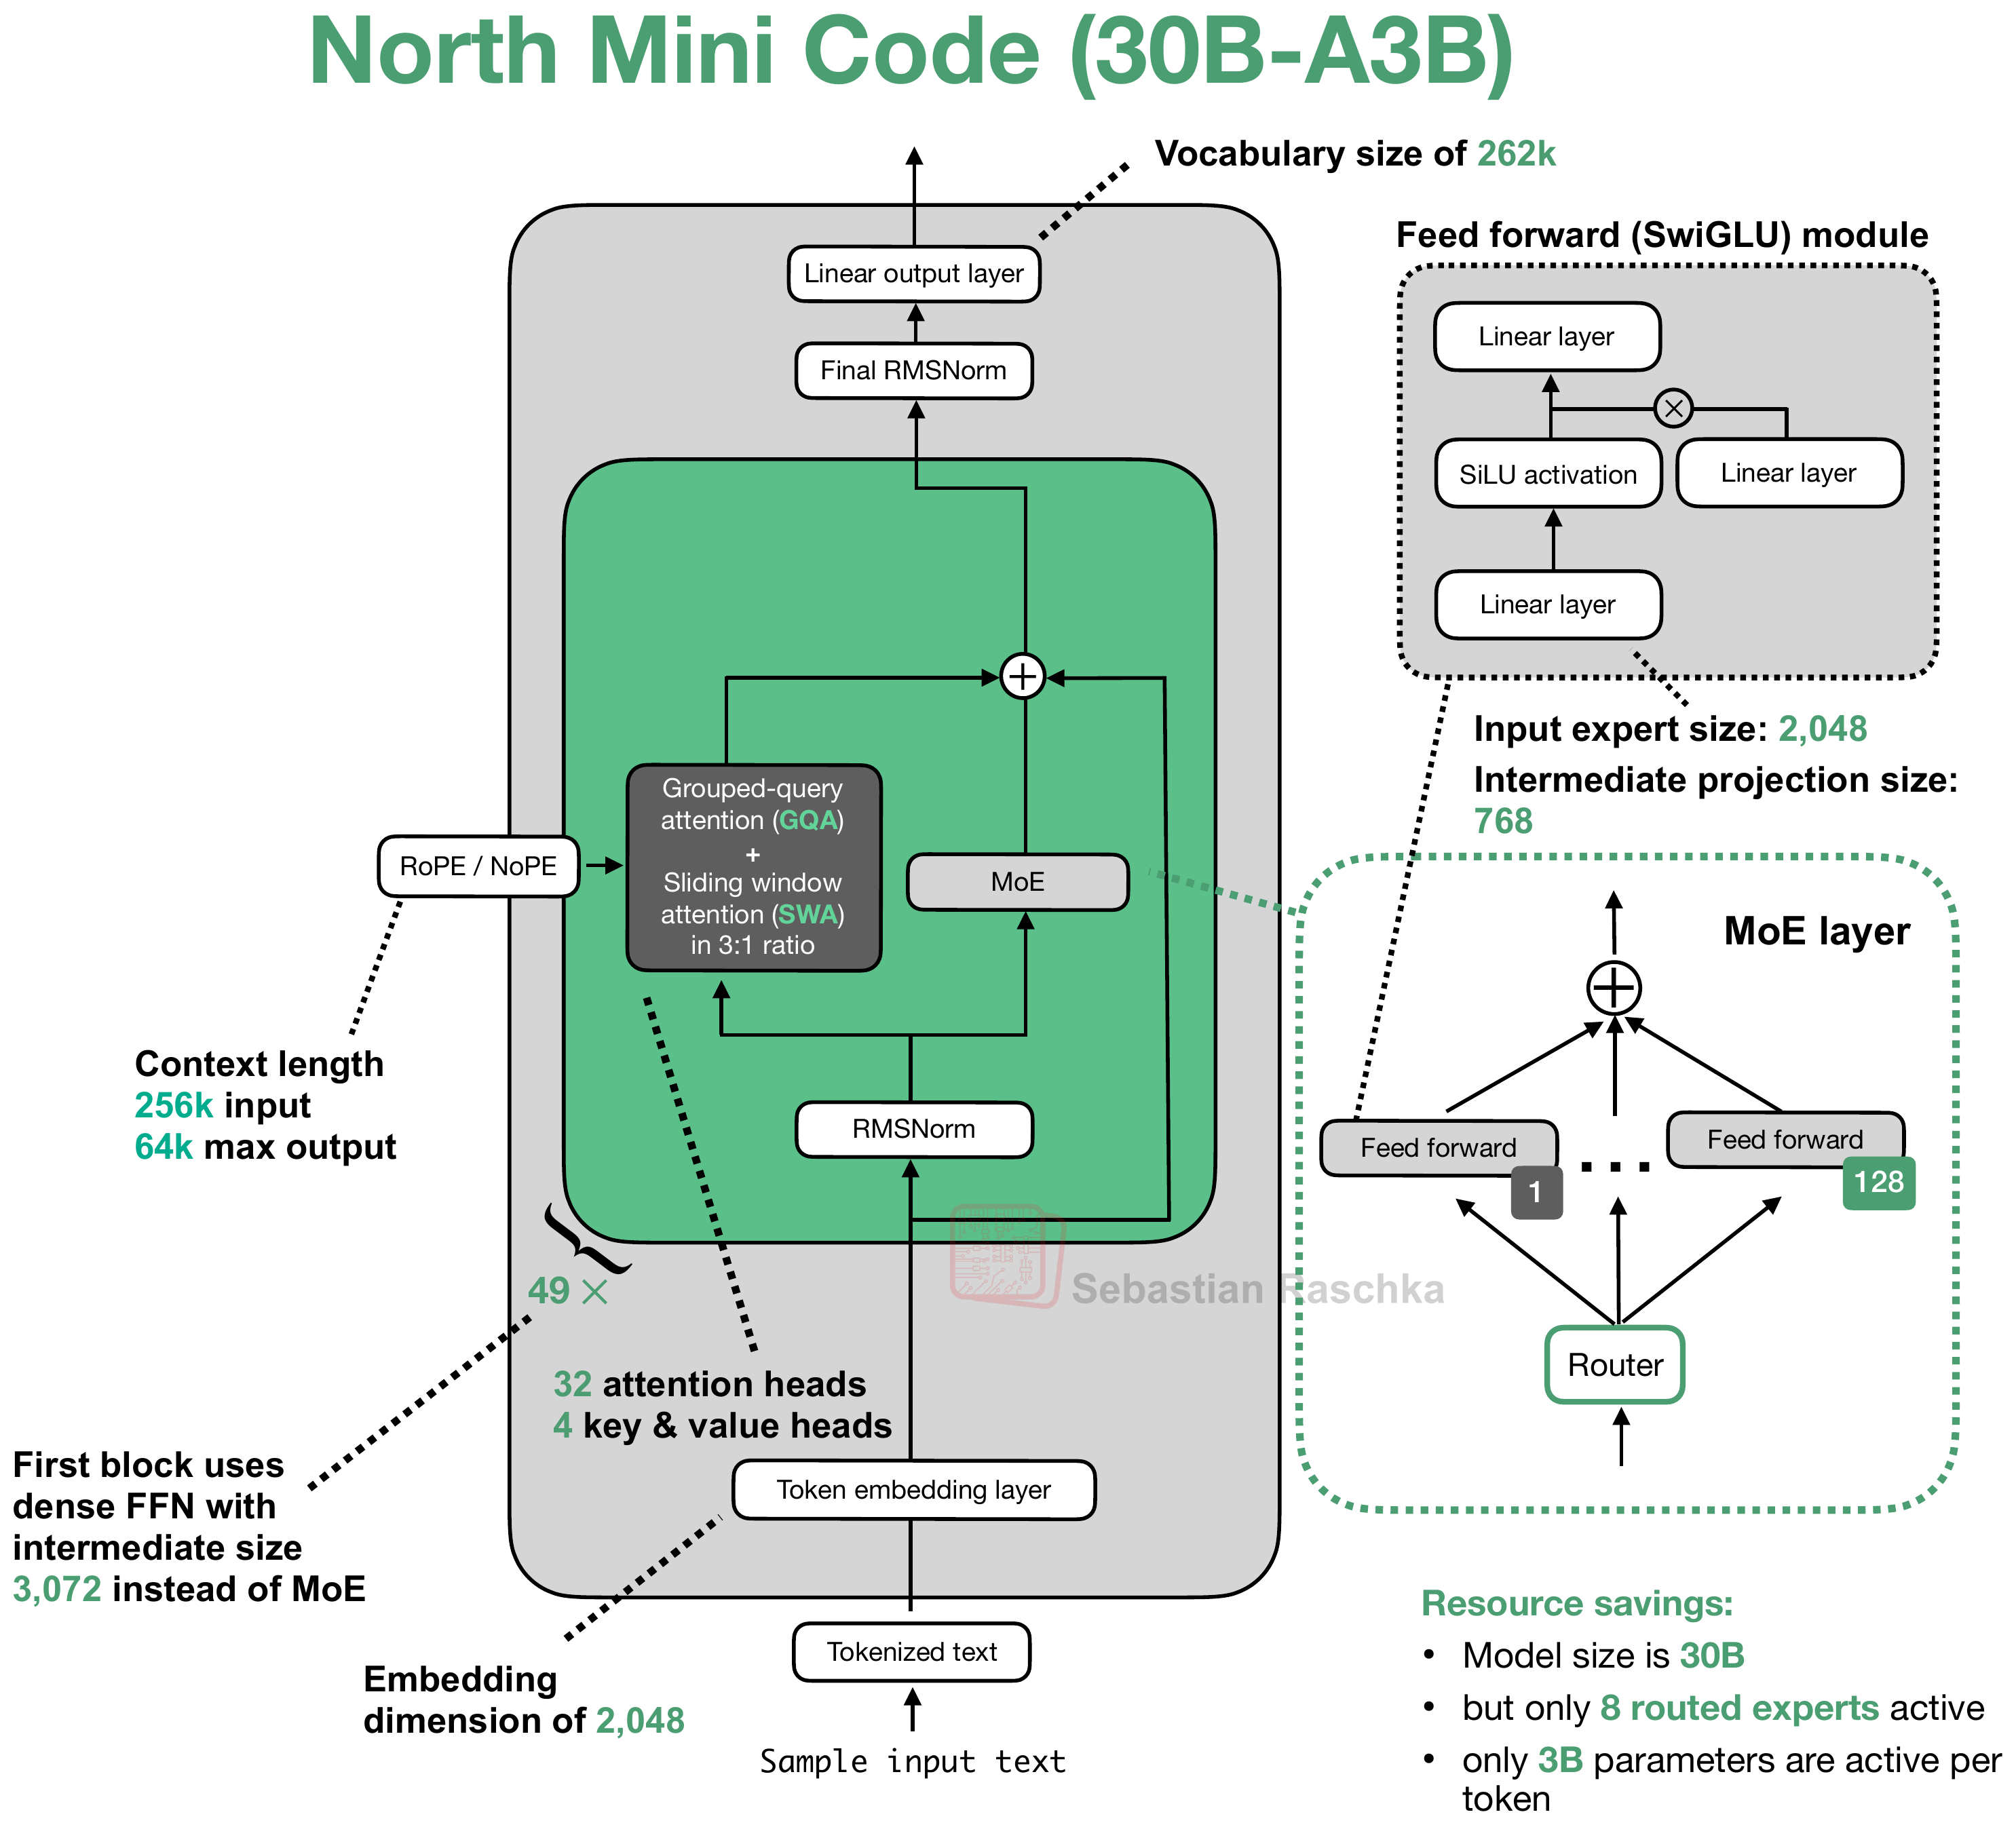
Architecture and specifications
- Scale
- 30B total, 3B active (10% active)
- Context (tokens)
- 256K input, 64K output
- Vocabulary
- 262,144
- License
- Apache License 2.0
- Date
- 2026-06-05
- Decoder type
- Sparse MoE
- Attention
- 8:1 GQA with 3:1 sliding-window/global attention
- Layer mix
- 36 sliding-window + 13 global GQA/MoE
- KV cache / token (bf16) info
- 98 KiB · Moderate
- Key detail
- Runs attention and MoE in parallel, with RoPE in sliding-window layers, NoPE in global layers, and top-8 routing over 128 experts.
Training and benchmarks
- Pretraining data
- Not disclosed The model card and release article do not report a pretraining token count. Training overview
- Post-training methods
- SFT, RLVR Two-stage cascaded SFT followed by asynchronous RL with verifiable rewards for coding agents. Training overview