
Kolibri-1 78B Architecture
Back to Kolibri-1 78B in the gallery
Aleph Alpha
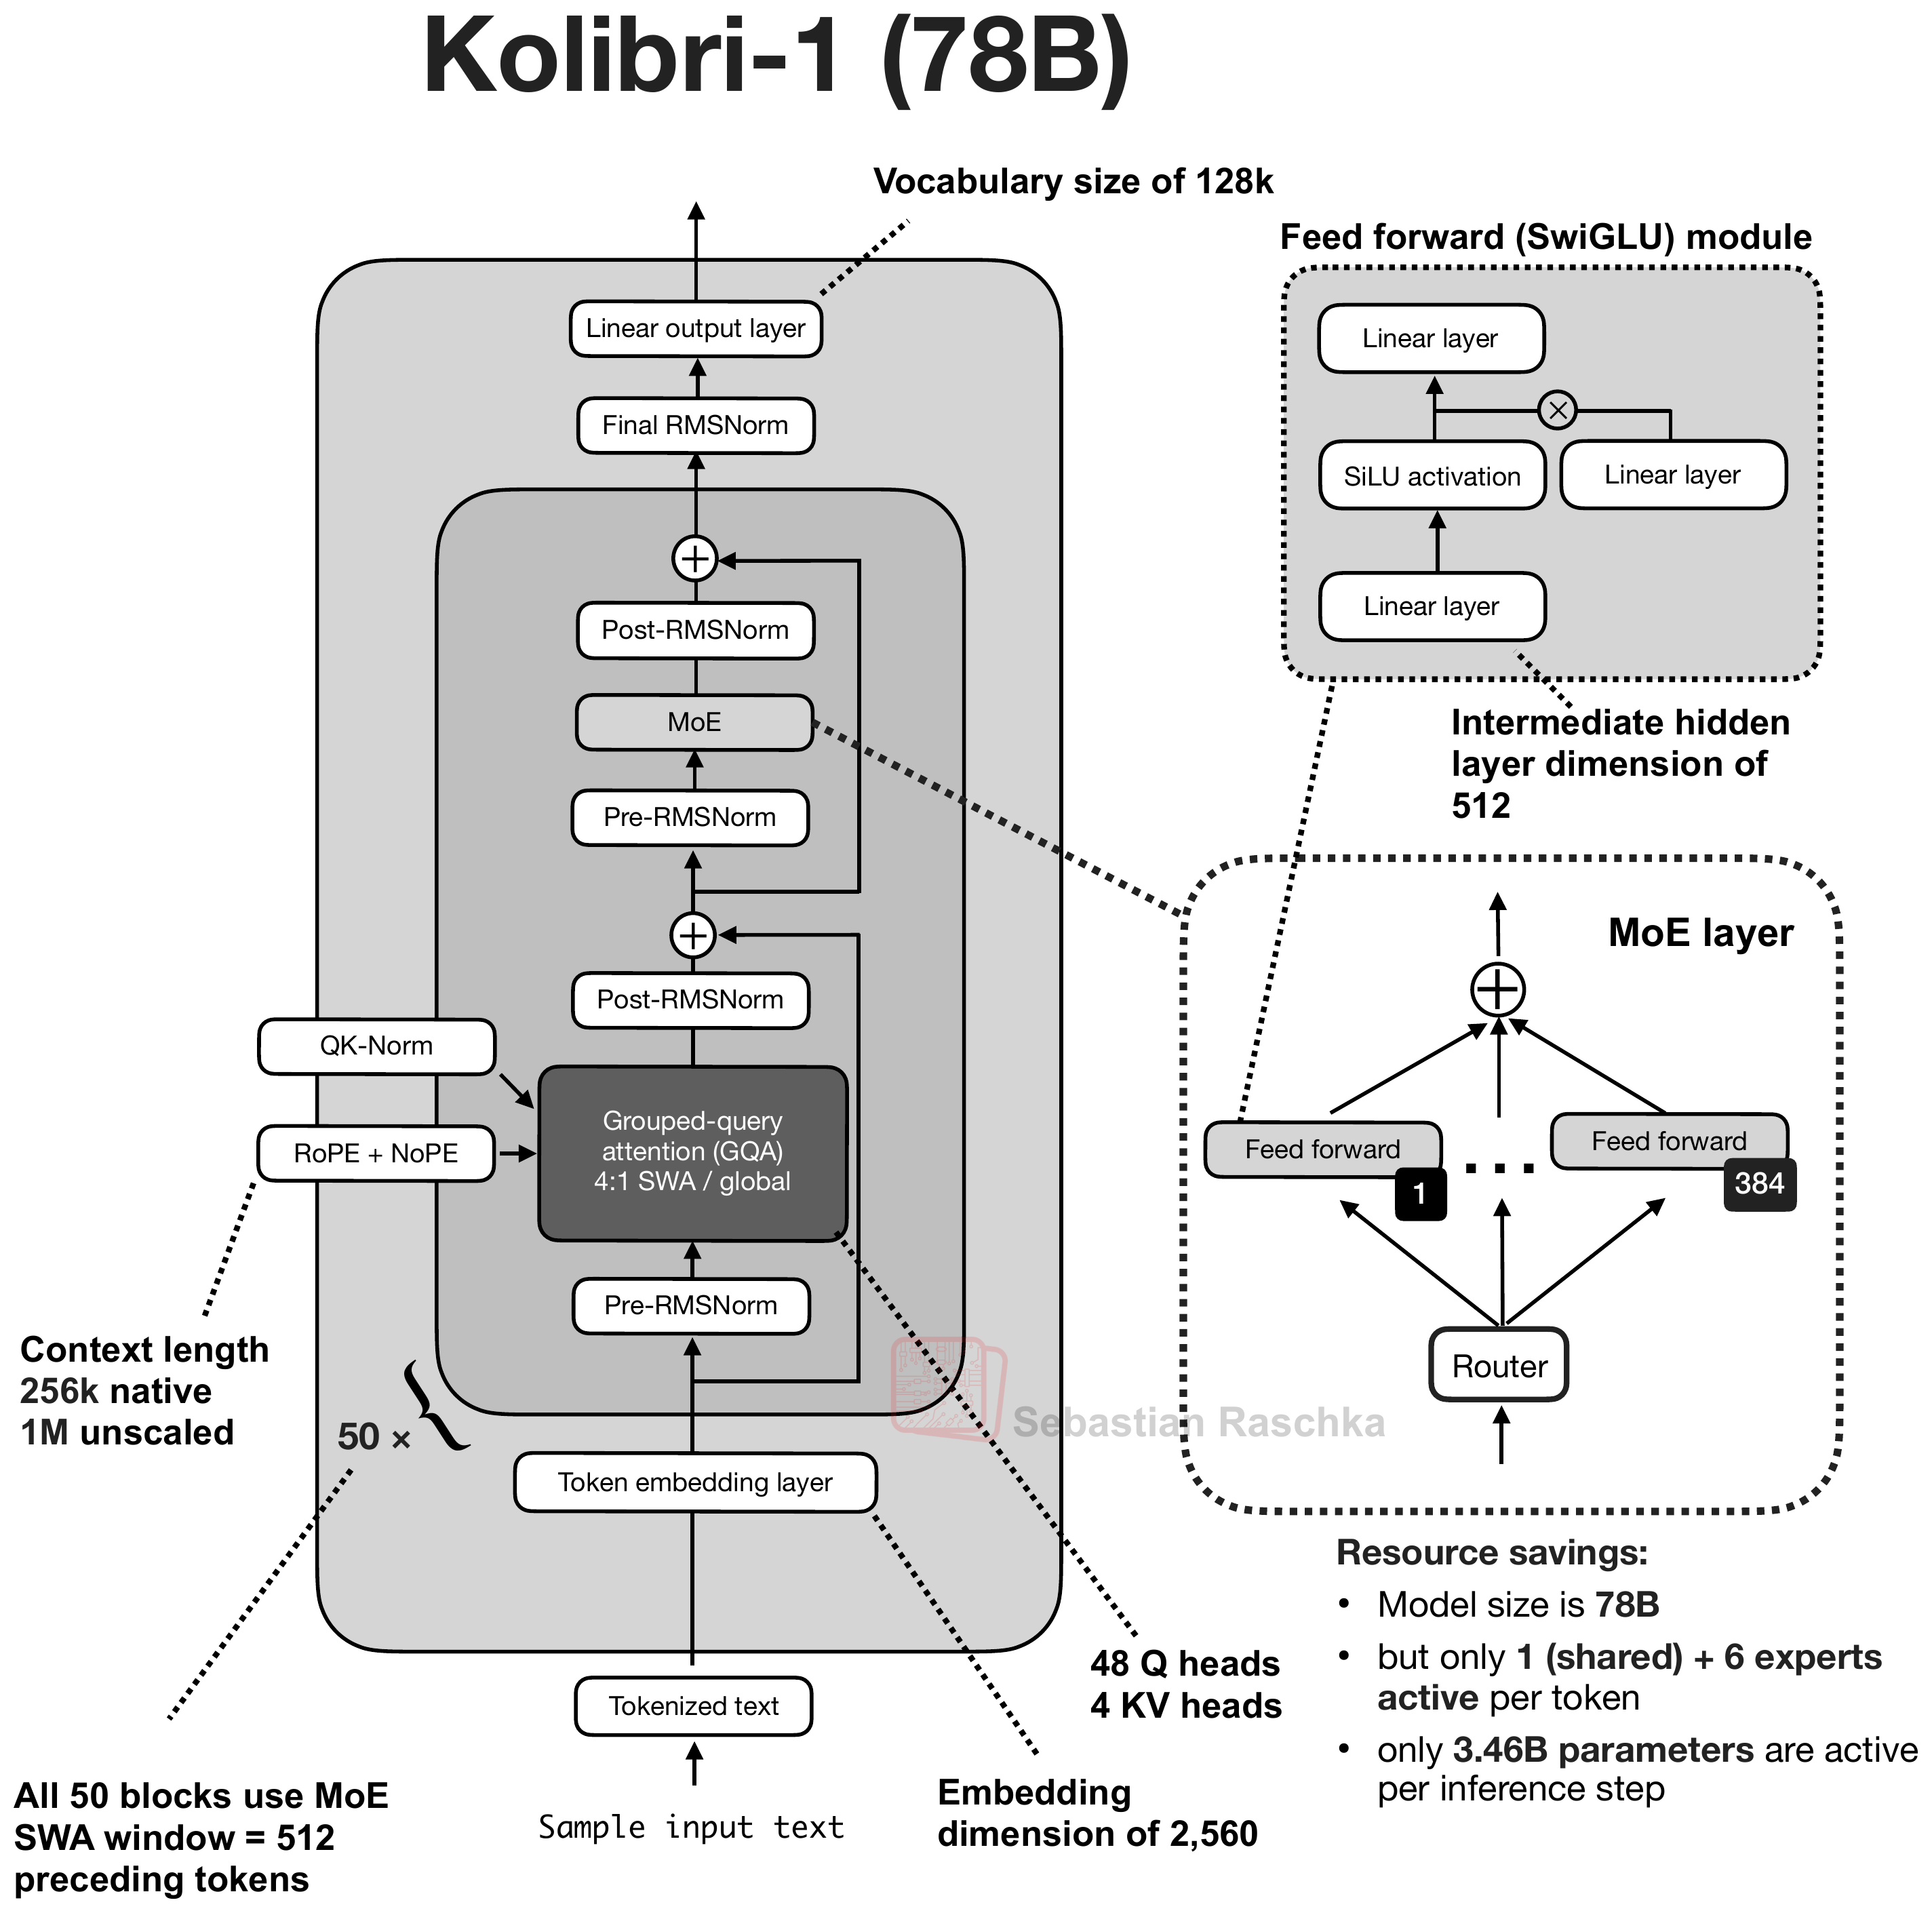
Aleph Alpha's German-English reasoning model uses 50 MoE blocks with a 4:1 mix of sliding-window and global GQA.
Architecture and specifications
- Scale
- 78B total, 3.46B active (4.4% active)
- Context (tokens)
- 262,144 native; 1,048,576 extrapolated
- Vocabulary
- 128,000
- License
- Apache License 2.0
- Date
- 2026-10-03
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm and 4:1 sliding-window/global attention
- Layer mix
- 40 sliding-window + 10 global GQA
- KV cache / token (bf16) info
- 100 KiB · Moderate
- Key detail
- Uses top-6 routing over 384 experts plus one shared expert, with sandwich RMSNorm, RoPE in local layers, and NoPE in global layers.
Training and benchmarks
- Pretraining data
- ~24T tokens Includes 20T pretraining, 3.4T midtraining, and 200B context-extension tokens; the report rounds the combined budget to 24T. Technical report
- Post-training methods
- SFT, RLVR, Distillation SFT is followed by RL with verifiable rewards across 38 environments, with targeted on-policy self-distillation for low-reward groups. Technical report