
DeepSeek V4.1-Flash Architecture
Back to DeepSeek V4.1-Flash in the gallery
DeepSeek
Causal encoder-decoder MoE with CSA2 cache sharing, Engram memory, and a million-token context. The figure shows the text backbone.
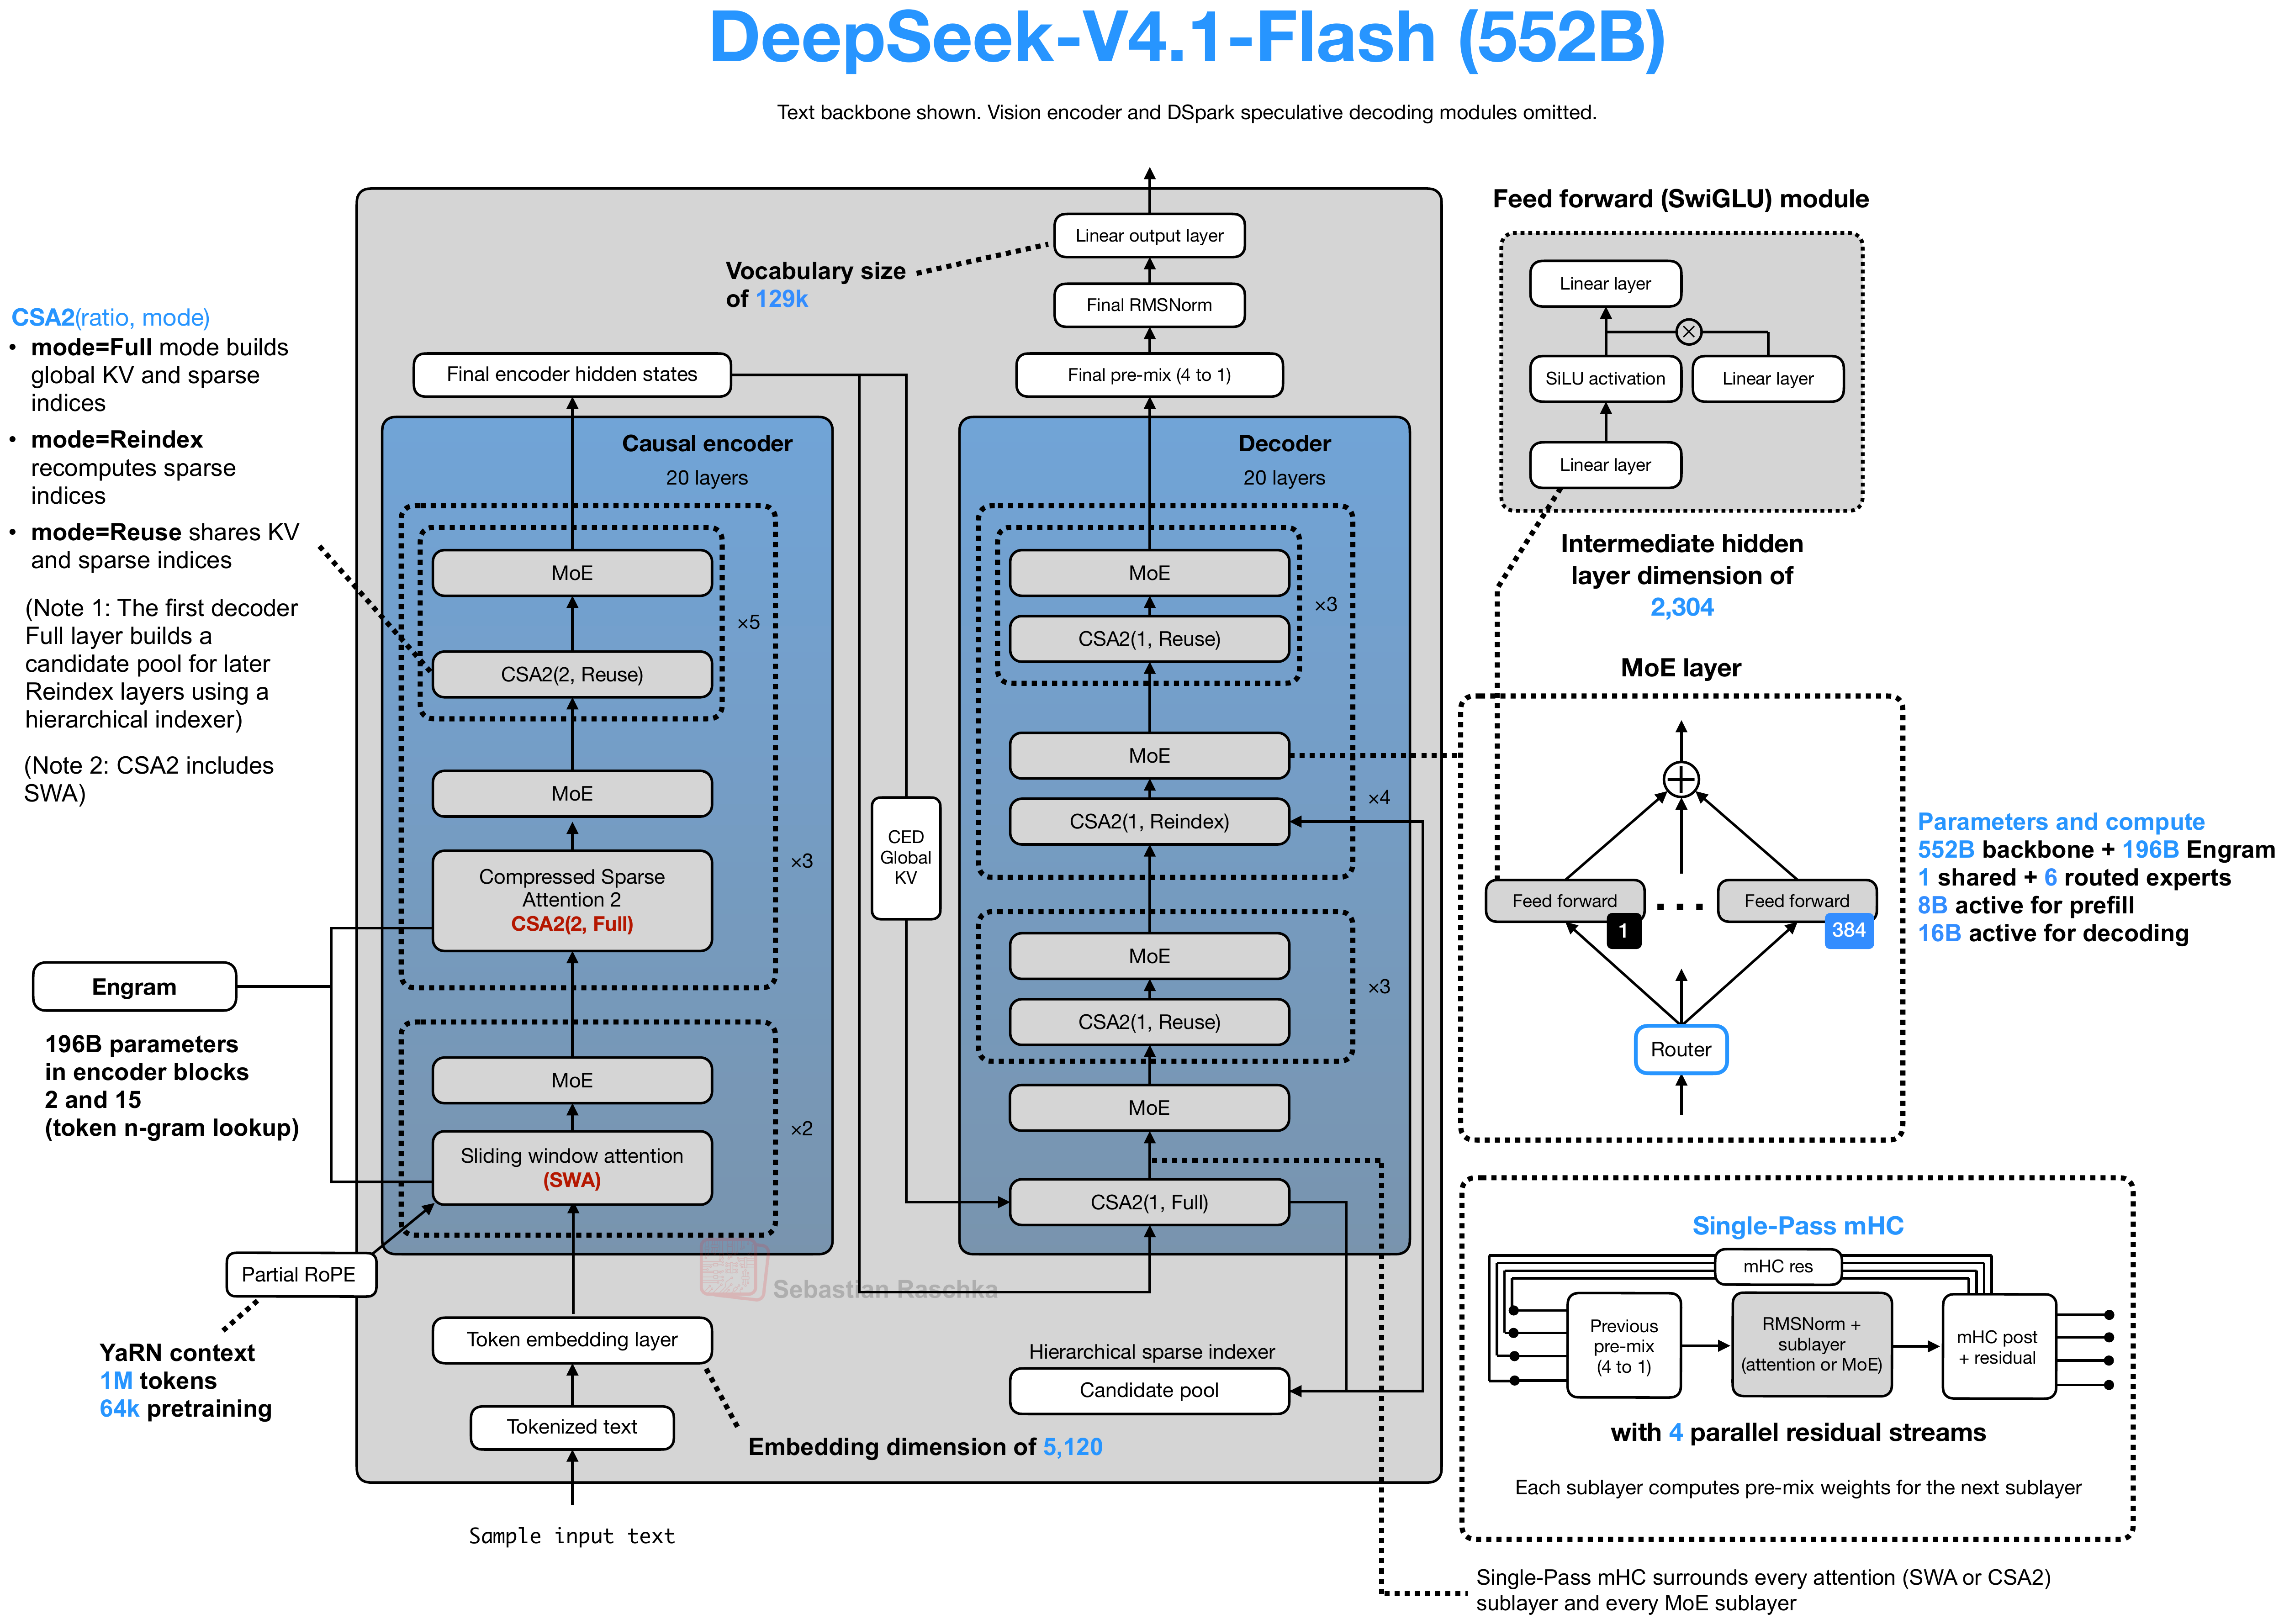
Architecture and specifications
- Scale
- 552B backbone + 196B Engram; 8B active prefill, 16B active decode (2.9% of backbone)
- Context (tokens)
- 1,048,576
- Vocabulary
- 129,280
- License
- MIT License
- Date
- 2026-09-10
- Decoder type
- Sparse MoE (causal encoder-decoder)
- Attention
- MLA-style CSA2 + SWA with cross-layer KV and sparse-index reuse
- Layer mix
- 20 encoder + 20 decoder layers; 2 SWA-only + 38 CSA2/SWA
- KV cache / token (bf16) info
- 3.125 KiB (growing global cache only) · Very low
- Key detail
- Decoder global KV comes from final encoder states. Single-Pass mHC mixes four residual streams around each attention and MoE sublayer.
Training and benchmarks
- Pretraining data
- 45T tokens Multimodal pretraining from scratch, including long-context training. DeepSeek V4.1 Flash model card
- Post-training methods
- SFT, RL, Distillation SFT, RL, then on-policy distillation; agent-task and environment synthesis expands the training data. DeepSeek V4.1 Flash model card