
Nemotron 3 Ultra 550B-A55B Architecture
Back to Nemotron 3 Ultra 550B-A55B in the gallery
NVIDIA
NVIDIA's Ultra model scales the Nemotron 3 hybrid stack to 550B total parameters while keeping 55B active per token.
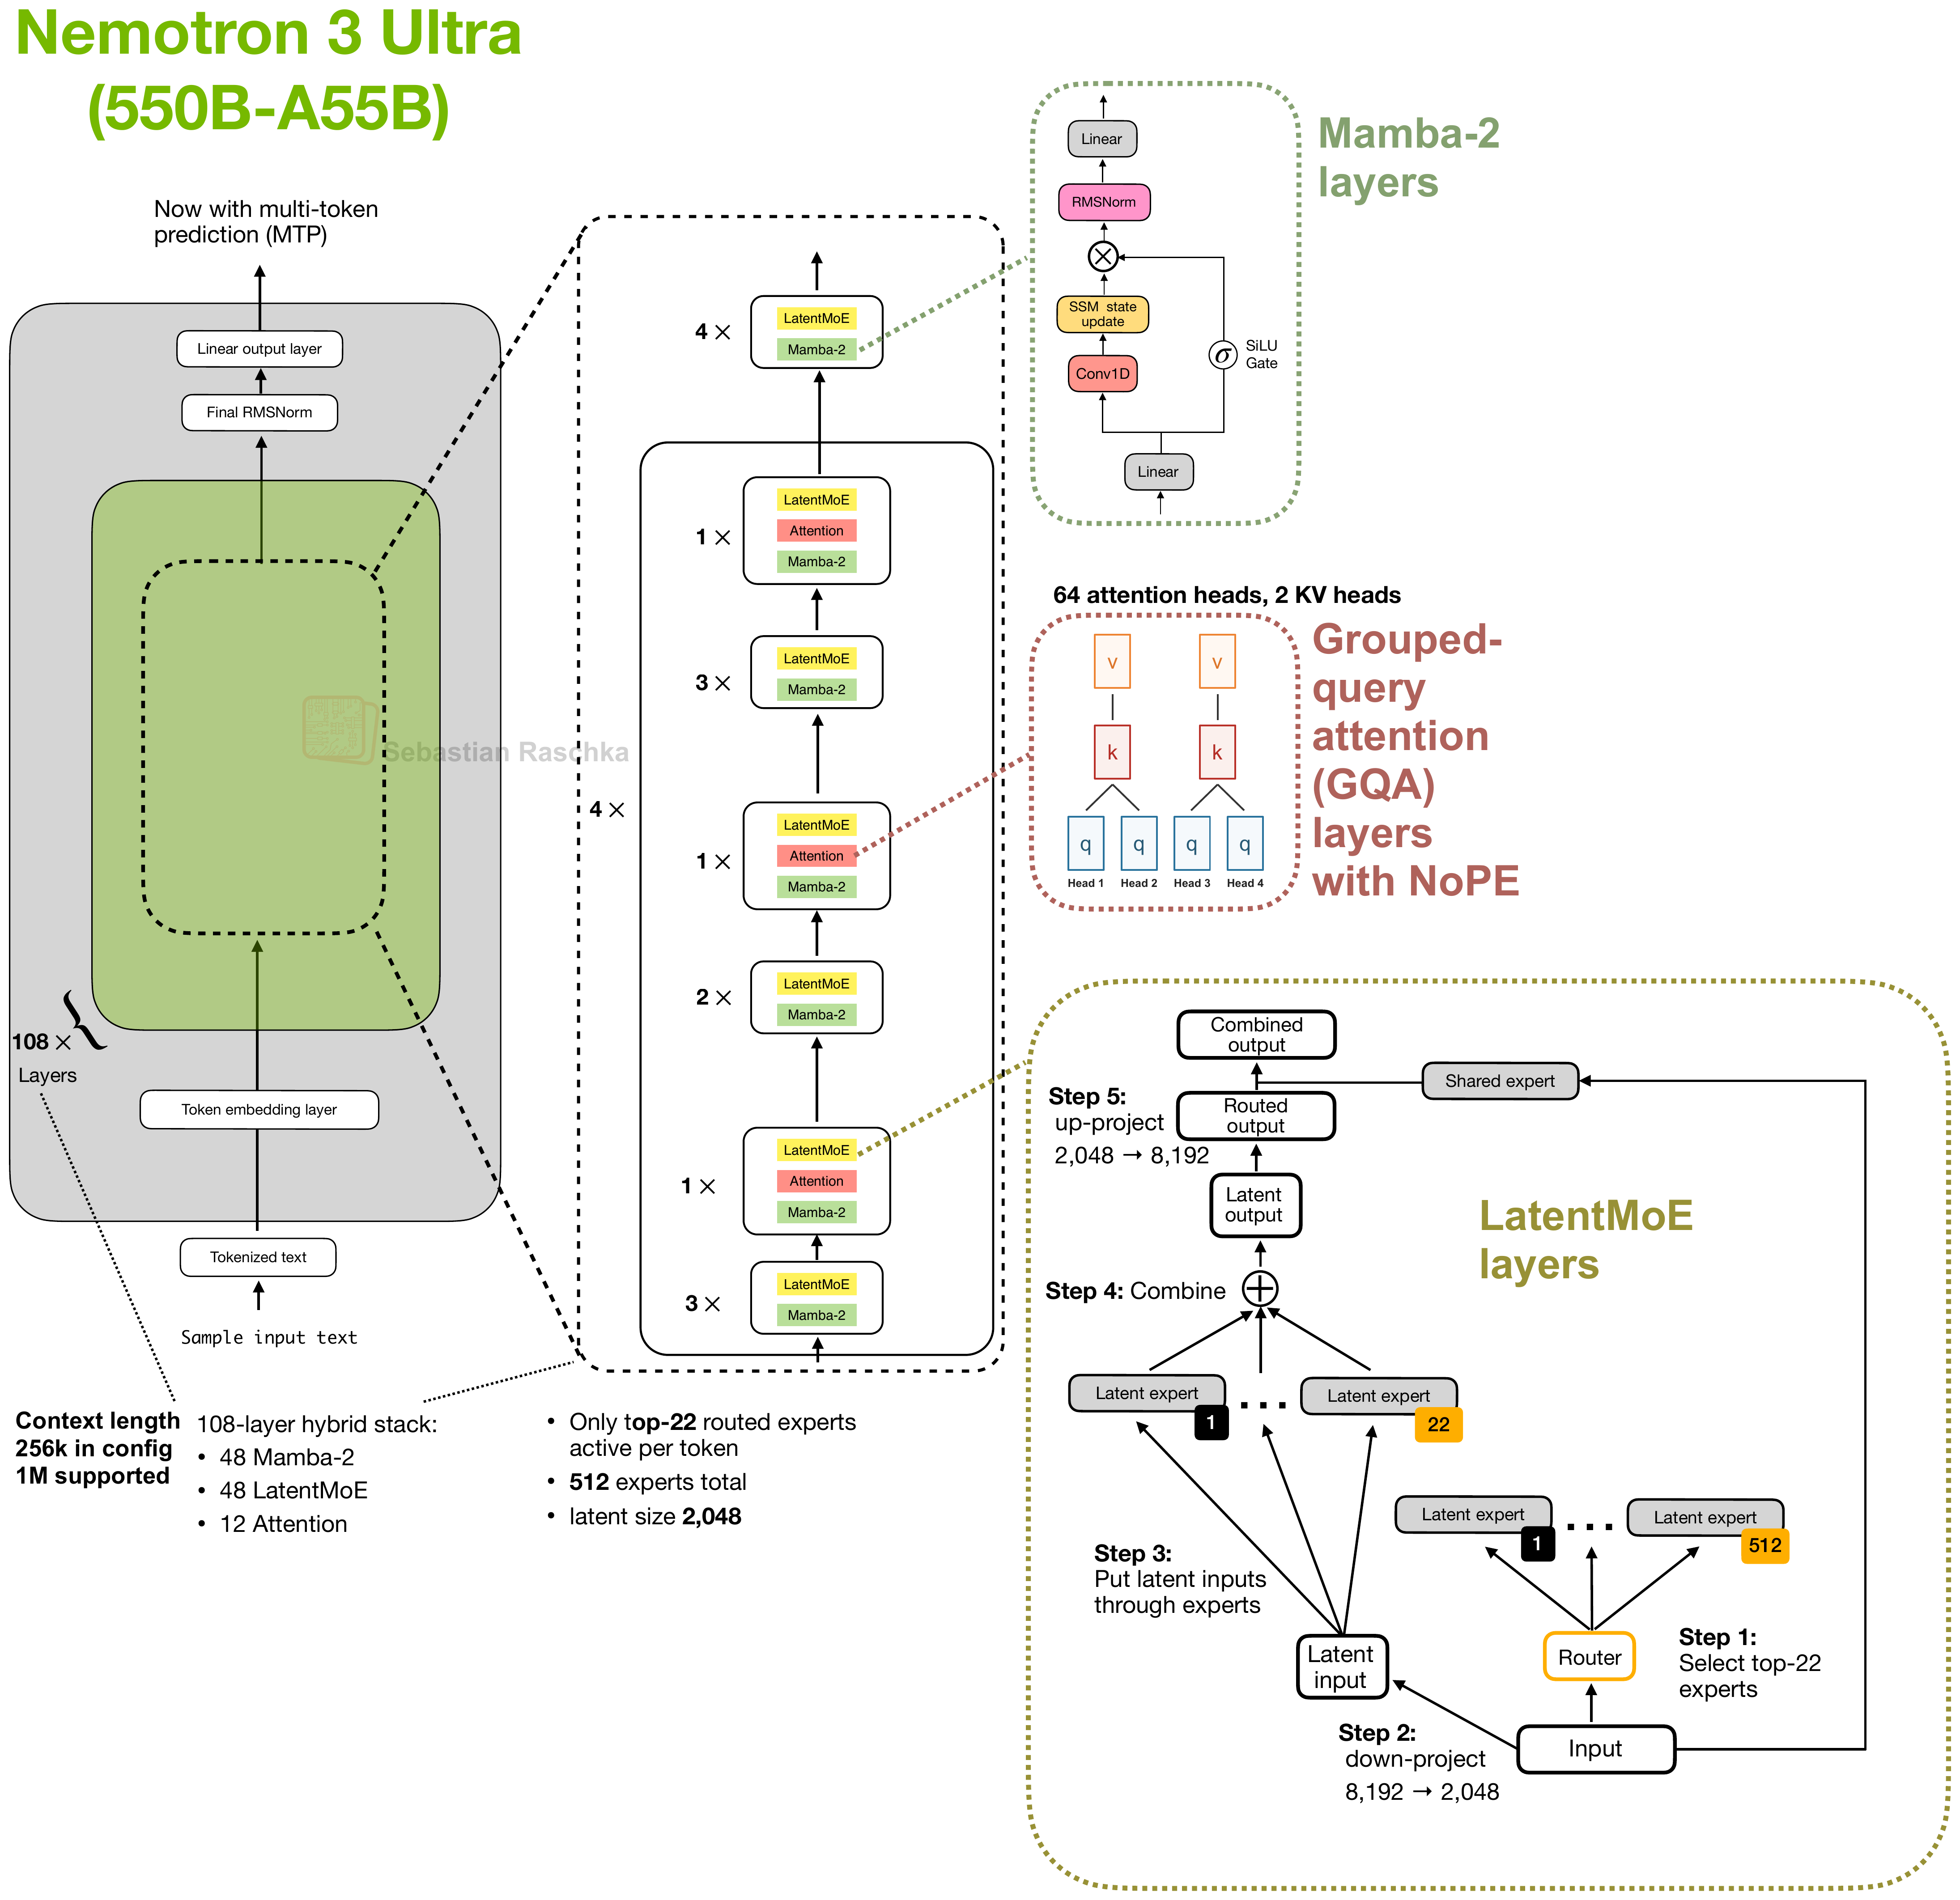
Architecture and specifications
- Scale
- 550B total, 55B active (10% active)
- Context (tokens)
- 1,000,000
- License
- NVIDIA Nemotron Open Model License
- Date
- 2026-06-04
- Decoder type
- Hybrid MoE
- Attention
- Mostly Mamba-2 with a few GQA layers using NoPE
- Layer mix
- 12 GQA + 48 Mamba-2 + 48 MoE
- KV cache / token (bf16) info
- 12 KiB · Very low
- Key detail
- Scales the latent-MoE hybrid to 108 layers with 48 Mamba-2, 48 latent MoE, and 12 GQA layers.
Training and benchmarks
- Pretraining data
- 20T + 33B long-context tokens The main pretraining run uses 20T tokens, followed by 33B tokens of long-context continued pretraining. Nemotron 3 Ultra technical report
- Post-training methods
- SFT, RLVR, RLHF, Distillation SFT and multi-environment RLVR train the student. Specialized teachers, including RLHF-trained chat and alignment teachers, are consolidated through multi-teacher on-policy distillation. Nemotron 3 Ultra technical report