
Naive-N0.5-Flash 309B Architecture
Back to Naive-N0.5-Flash 309B in the gallery
NaiveAI
MiMo-V2.5-derived sparse MoE that replaces its global attention layers with GQA-based DeepSeek Sparse Attention for a native 1M-token context.
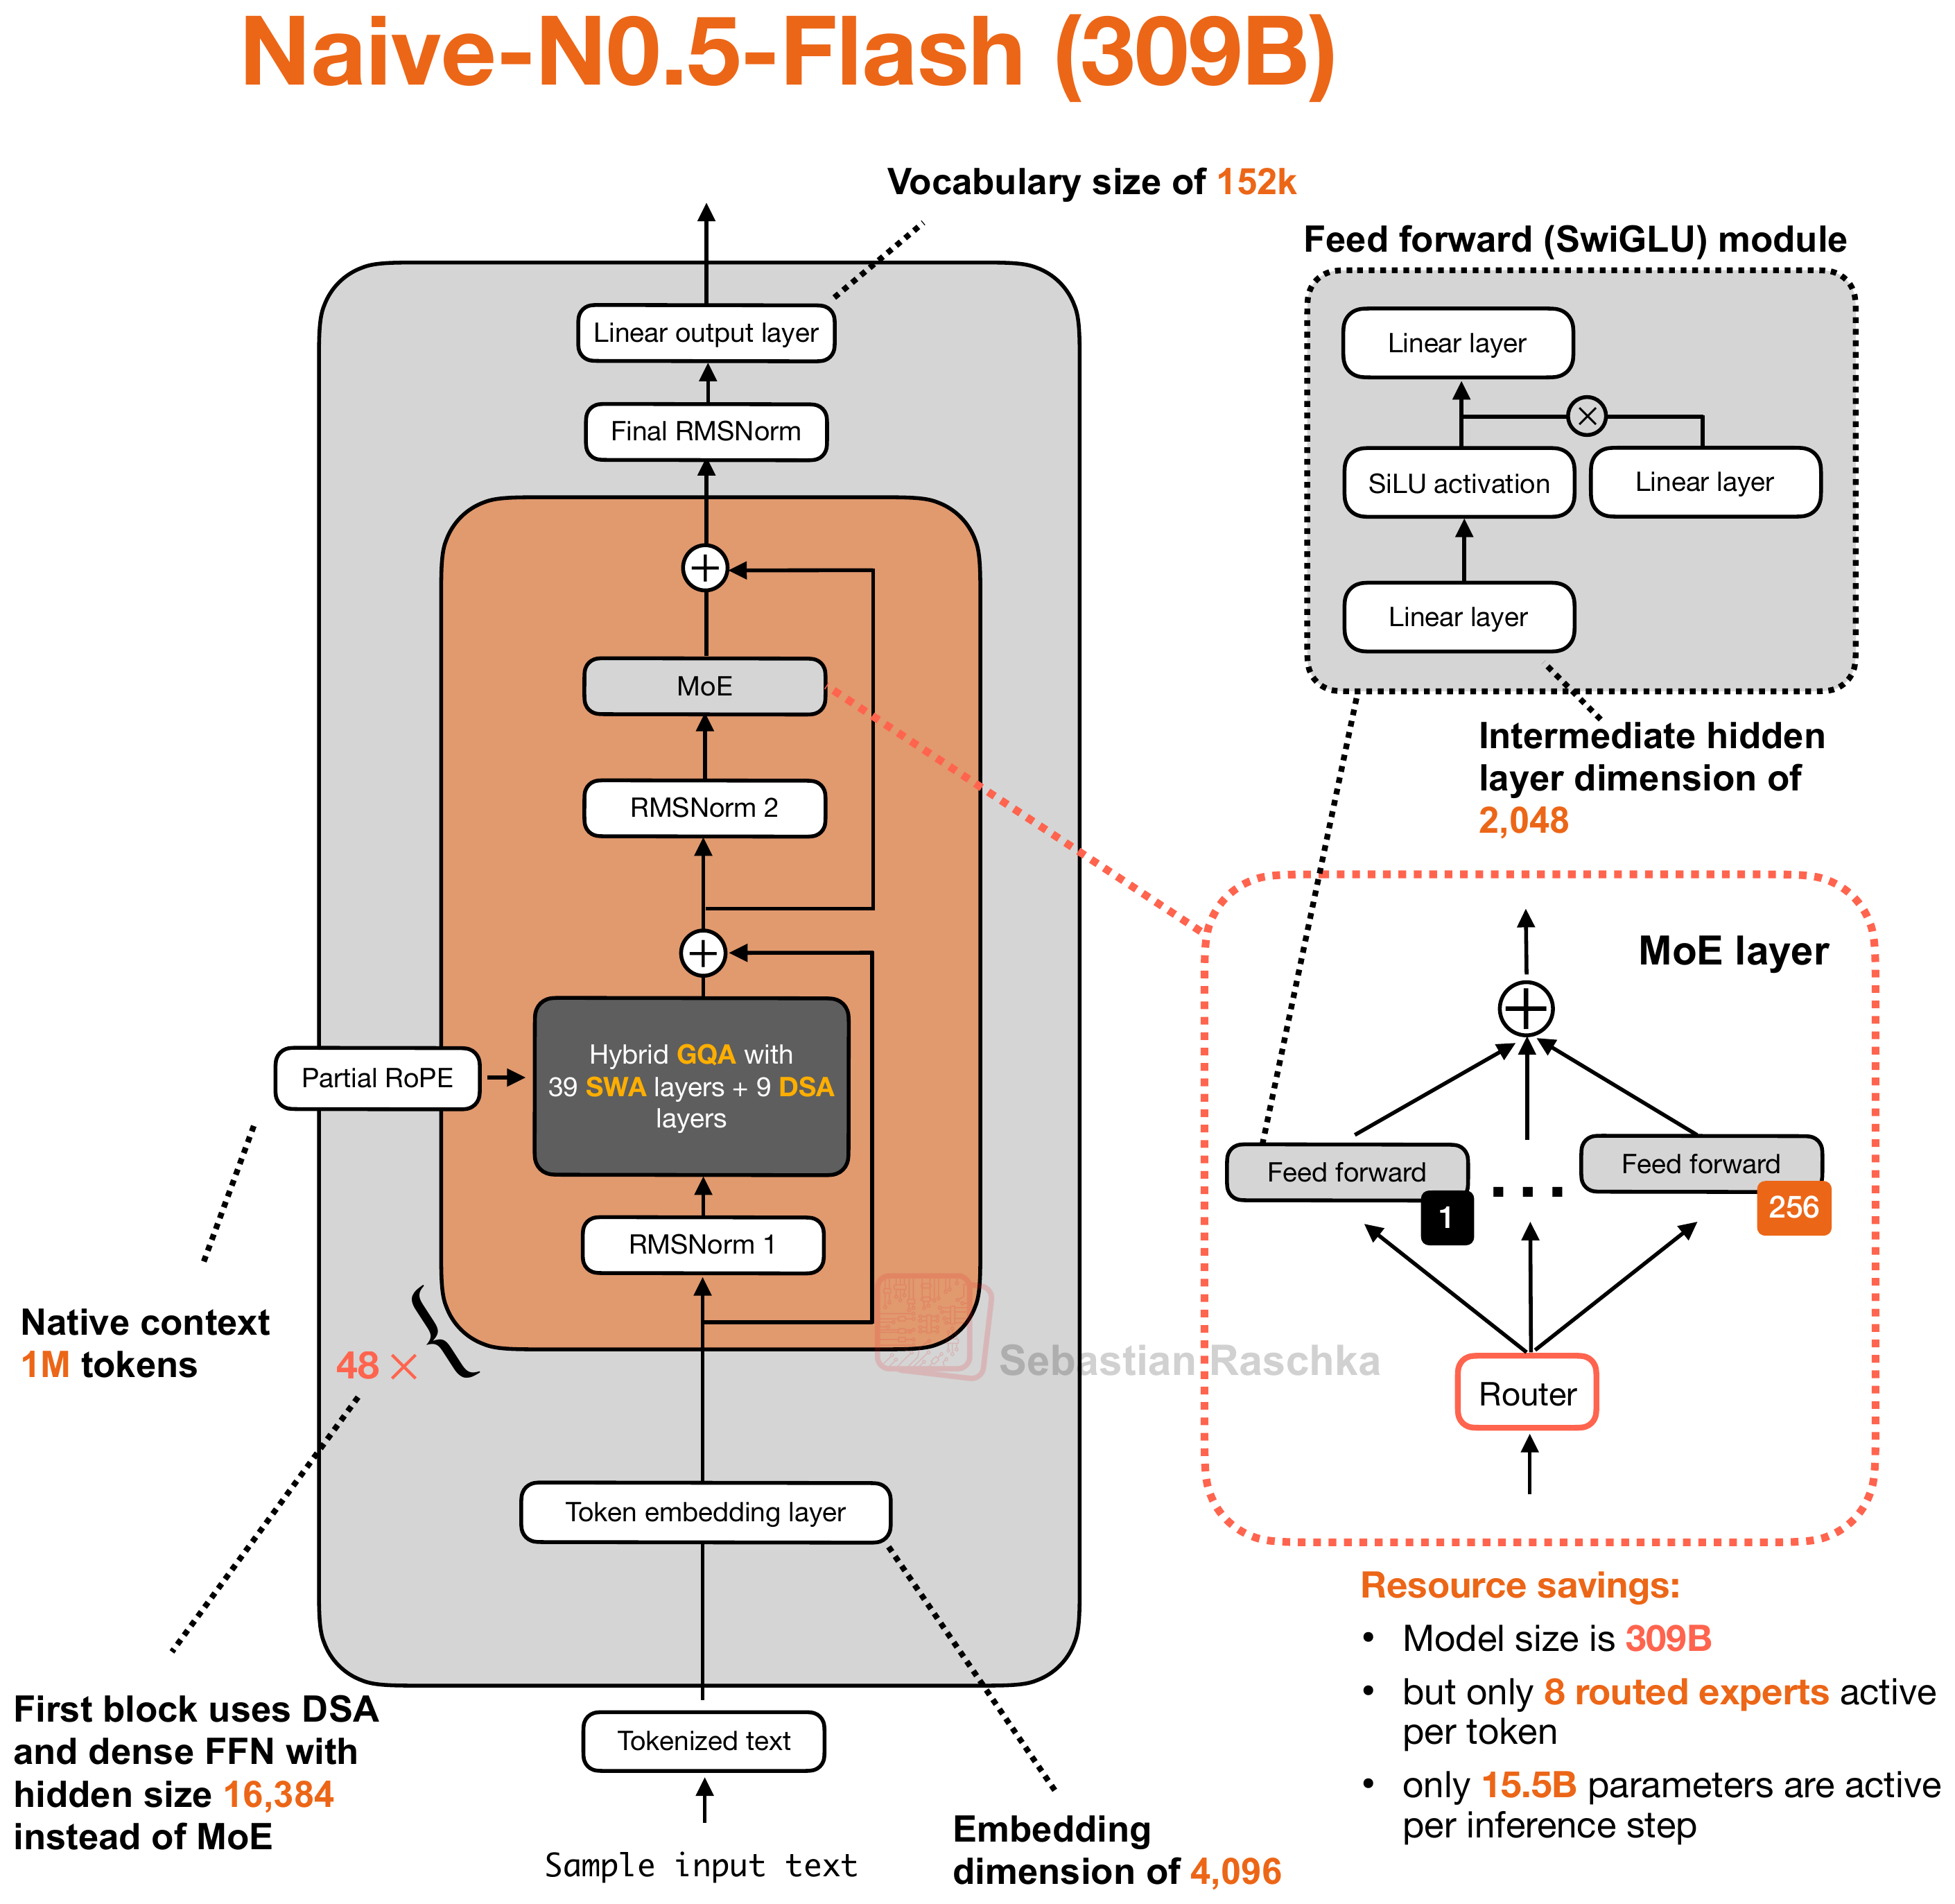
Architecture and specifications
- Scale
- 309B total, 15.5B active (5.0% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 152,576 (~152k)
- License
- MIT License
- Date
- 2026-09-27
- Decoder type
- Sparse MoE
- Attention
- GQA with sliding-window attention and DeepSeek Sparse Attention
- Layer mix
- 39 sliding-window + 9 GQA/DSA
- KV cache / token (bf16) info
- 219.75 KiB · High
- Key detail
- Pairs a 128-token local window with top-2,048 DSA selection, four DSA KV heads, and a 16-head indexer. Uses 256 routed experts with top-8 routing and no full-attention layers.
Training and benchmarks
- Pretraining data
- 3T additional pretraining tokens Continued from MiMo-V2.5. The reported 3.25T adaptation budget also includes 50B frozen-backbone indexer-warmup tokens and 200B SFT tokens; inherited base training is separate. NaiveAI training procedure
- Post-training methods
- SFT The final learning-rate decay stage uses supervised fine-tuning for 200B tokens. NaiveAI training procedure