
Motif 3 Beta Architecture
Back to Motif 3 Beta in the gallery
Motif Technologies
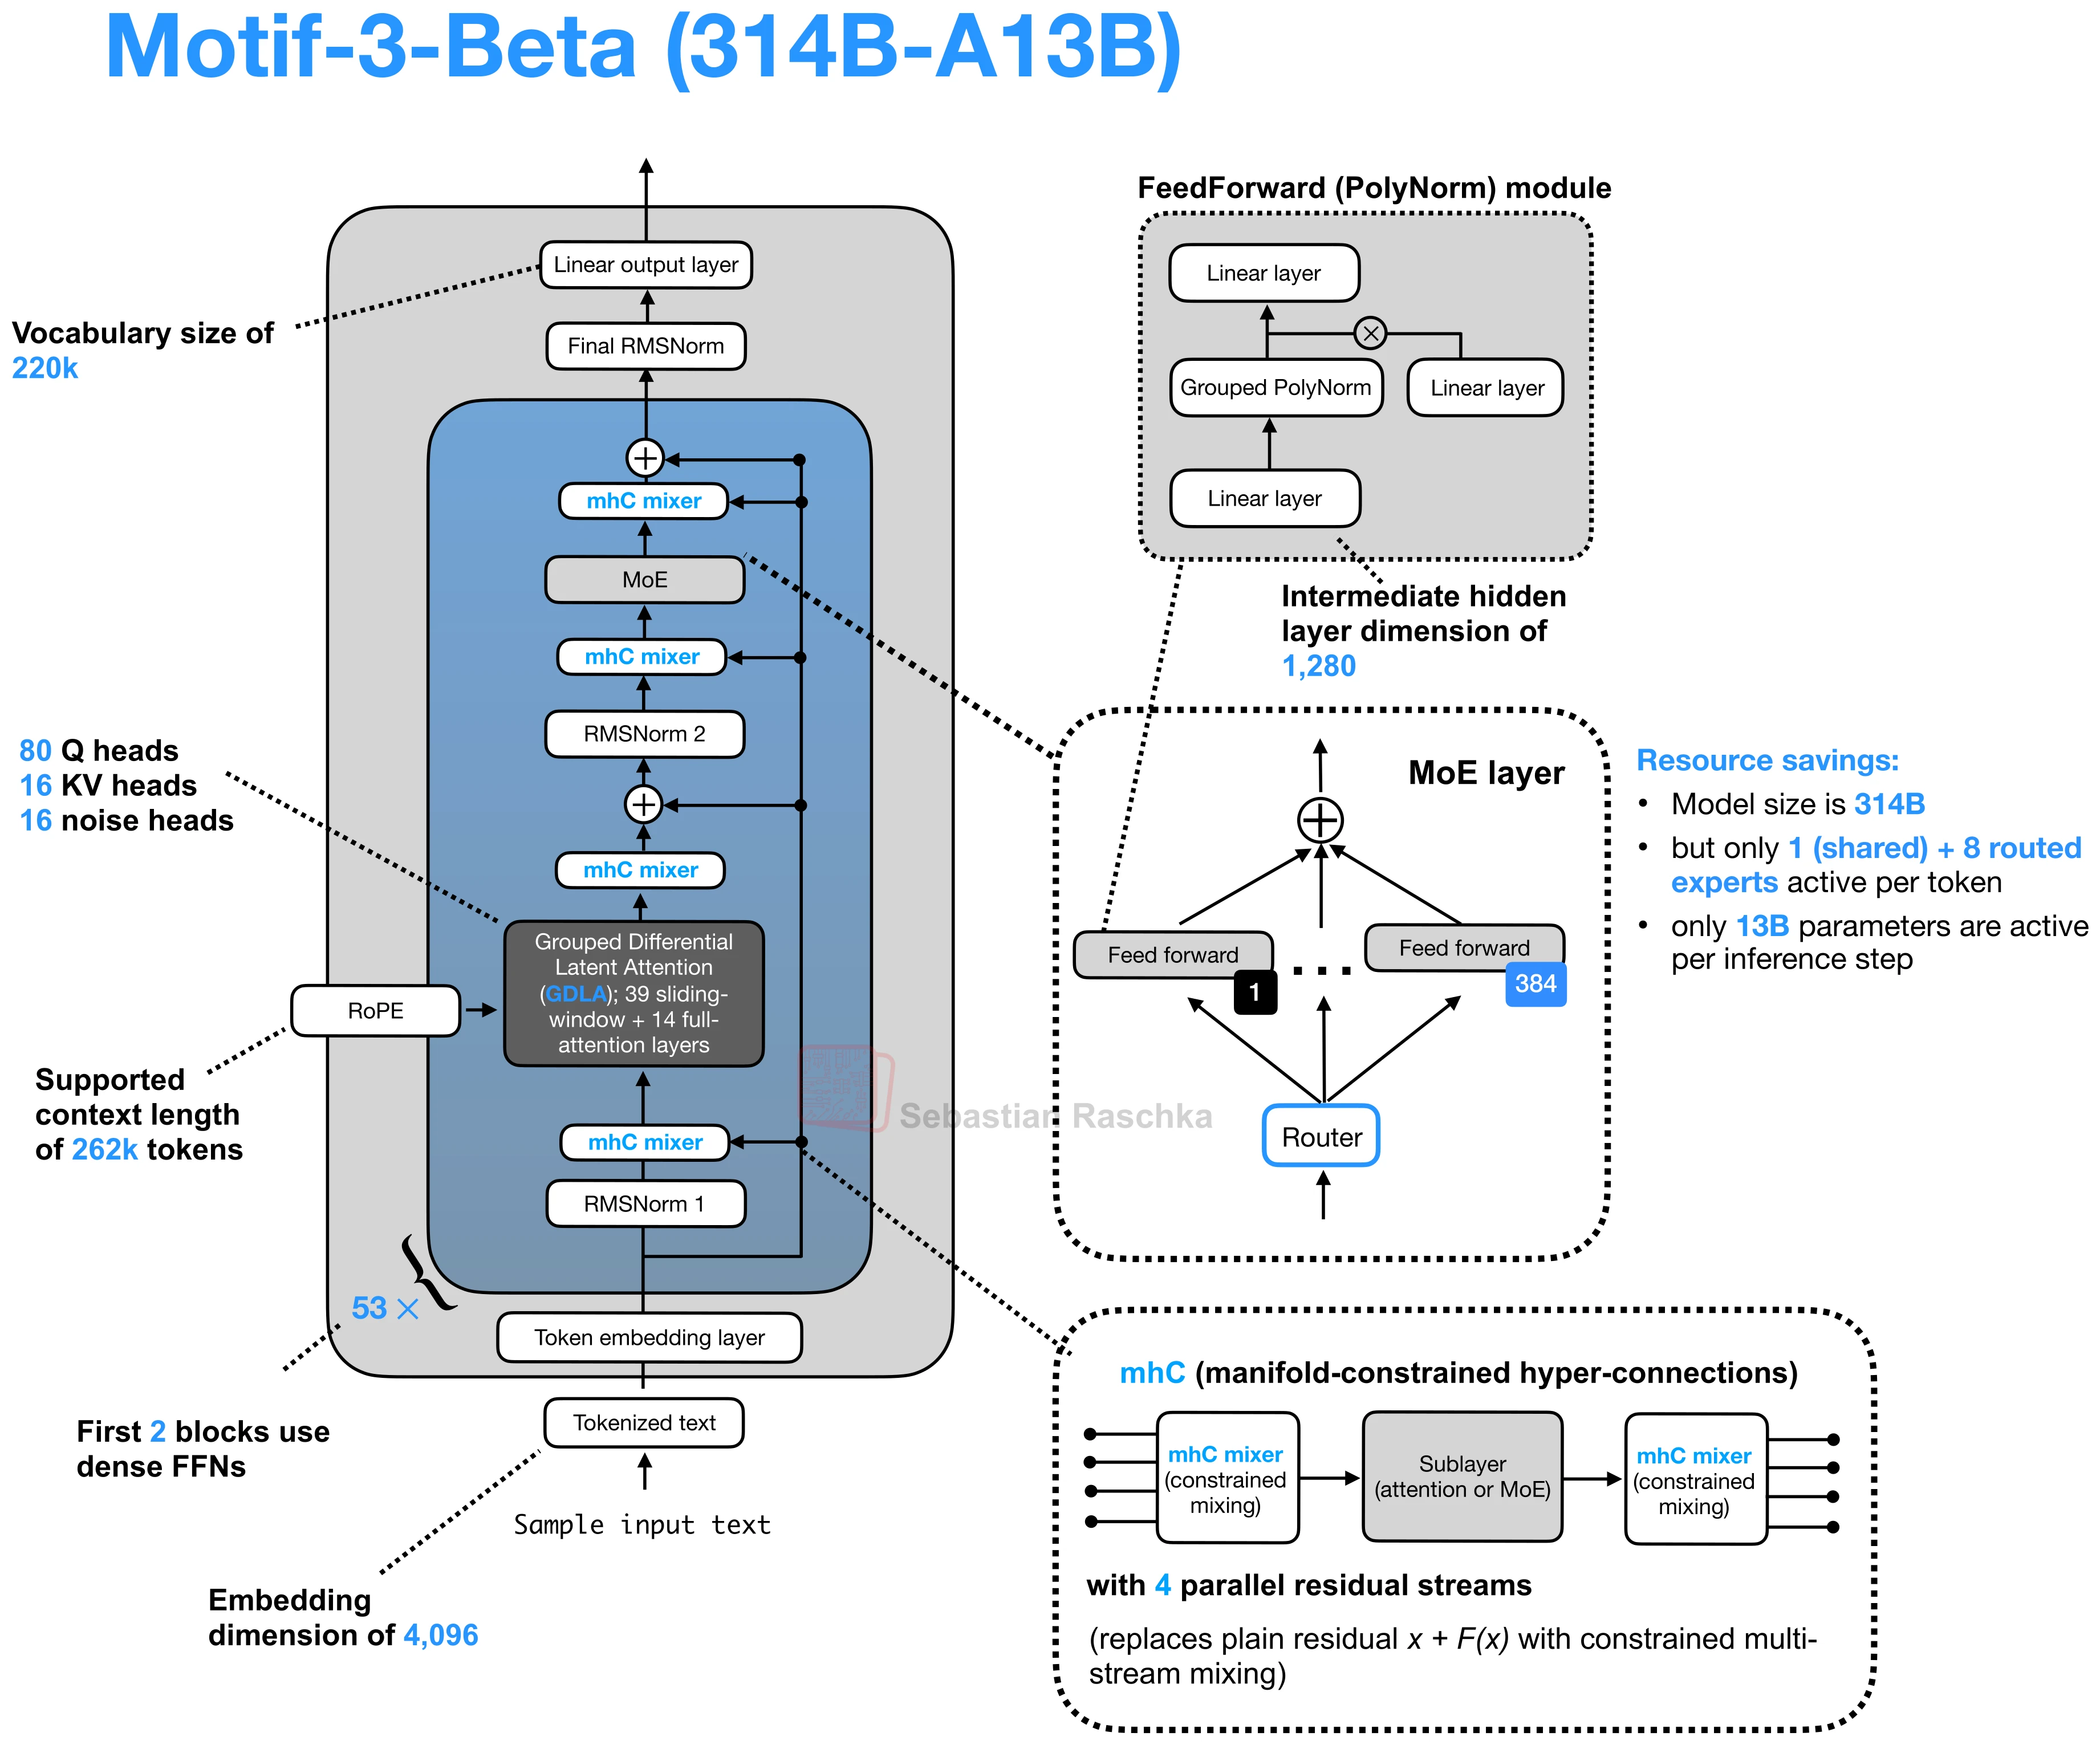
Large sparse MoE that combines Grouped Differential Latent Attention, per-expert PolyNorm, and modified mHC in a 53-layer decoder.
Architecture and specifications
- Scale
- 314B total, 13B active (4.1% active)
- Context (tokens)
- 262,144
- Vocabulary
- 220,160 (~220k)
- License
- Motif Technologies Non-Commercial License
- Date
- 2026-07-21
- Decoder type
- Sparse MoE
- Attention
- GDLA with MLA-style latent projections, RoPE, and 3:1 sliding-window/full attention
- Layer mix
- 39 sliding-window + 14 full GDLA
- KV cache / token (bf16) info
- 530 KiB · Very high
- Key detail
- Routes each token through 8 of 384 experts plus one shared expert, with per-expert PolyNorm and a 3:1 sliding-window/full GDLA pattern.
Training and benchmarks
- Pretraining data
- Not disclosed This is an intermediate beta checkpoint. The later Motif 3 report gives about 12.5T tokens for the final release, without a separate beta budget. Motif 3 Beta model card · Motif 3 final-release report
- Post-training methods
- Not disclosed The beta card gives no training recipe. The later final-release SFT and distillation pipeline is not explicitly attributed to this checkpoint. Motif 3 Beta model card · Motif 3 final-release report