
MiniMax M3.1-Flash 428B Architecture
Back to MiniMax M3.1-Flash 428B in the gallery
MiniMax
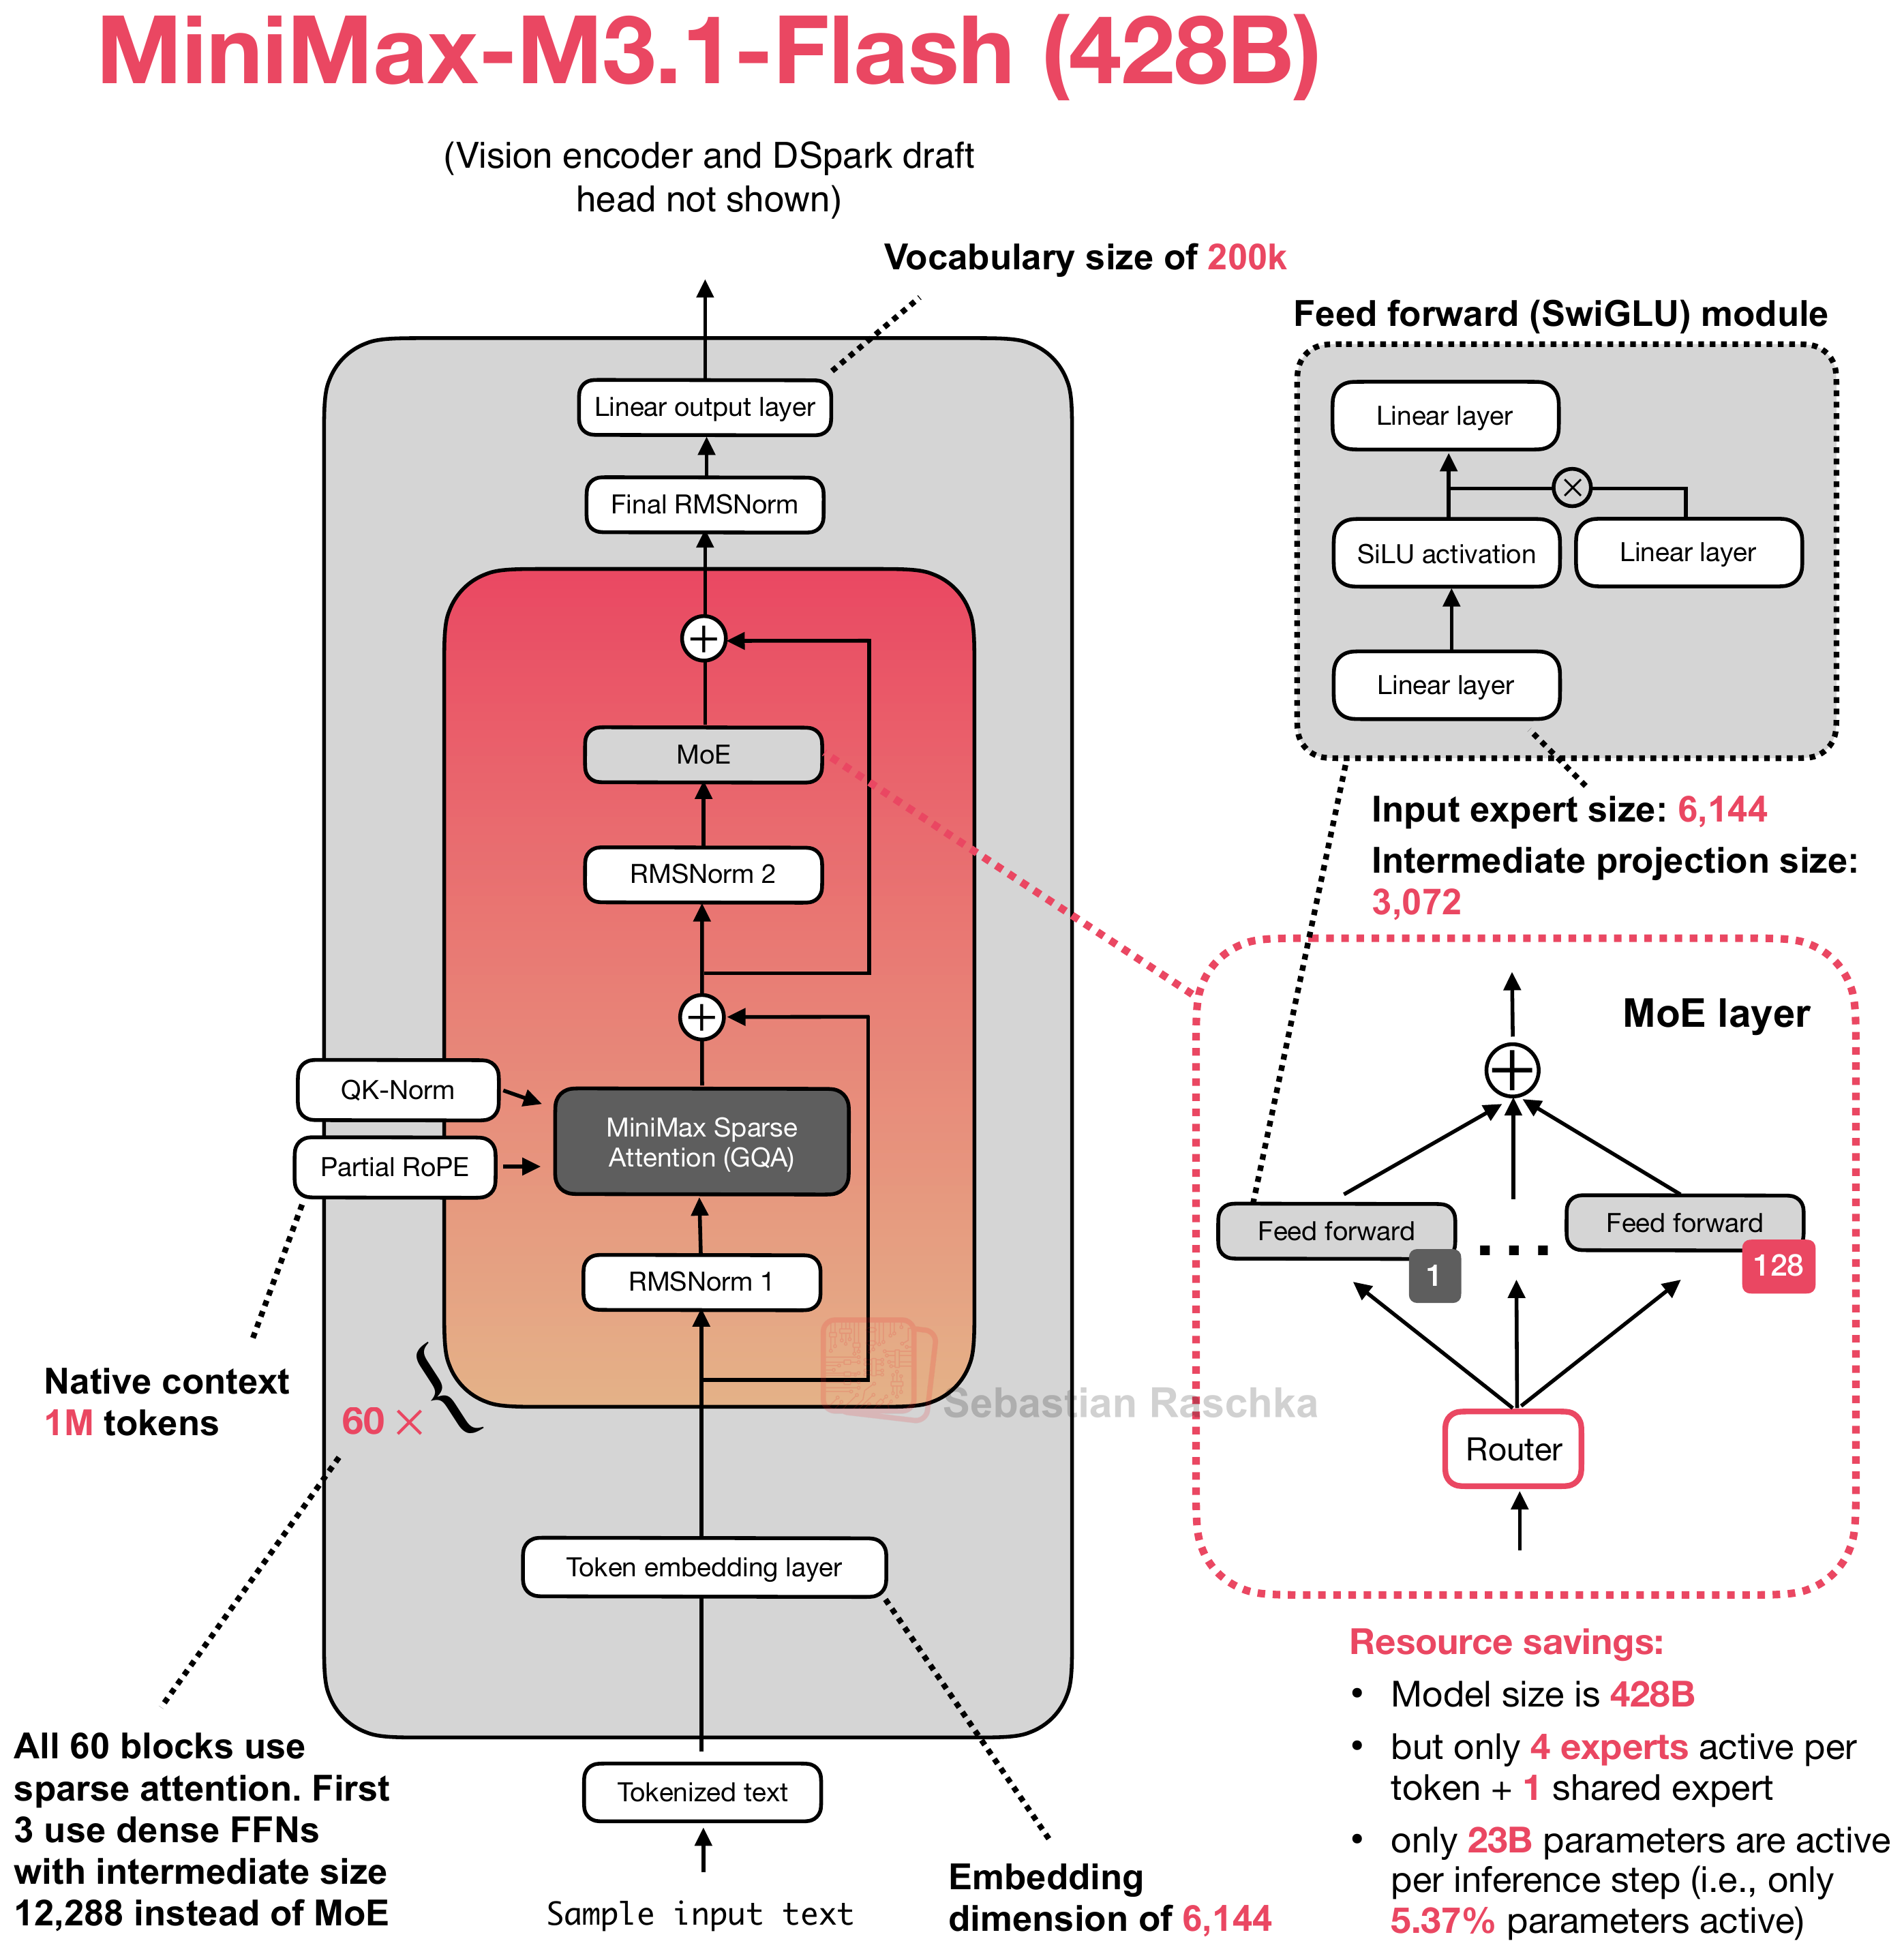
MiniMax M3 successor with sparse attention in all 60 decoder layers, quantization-aware training, and a DSpark draft head for speculative decoding.
Architecture and specifications
- Scale
- 428B total, 23B active (5.4% active)
- Context (tokens)
- 1,048,576
- License
- MiniMax Community License
- Date
- 2026-10-19
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm and MiniMax Sparse Attention
- Layer mix
- 60 MiniMax Sparse Attention; 3 dense FFN + 57 MoE
- KV cache / token (bf16) info
- 120 KiB · Moderate
- Key detail
- All 60 layers use sparse attention; the first 3 retain dense FFNs, while the remaining 57 route to 4 of 128 experts plus 1 shared expert per token.
Training and benchmarks
- Pretraining data
- Not disclosed No pretraining total is given. The release's 200T-token figure describes anonymous serving usage. MiniMax M3.1 Flash release · MiniMax M3.1 Flash model card
- Post-training methods
- Not disclosed The release and model card do not specify the instruction-tuning or reinforcement-learning recipe. MiniMax M3.1 Flash release · MiniMax M3.1 Flash model card