
Laguna XS 2.1 Architecture
Back to Laguna XS 2.1 in the gallery
Poolside
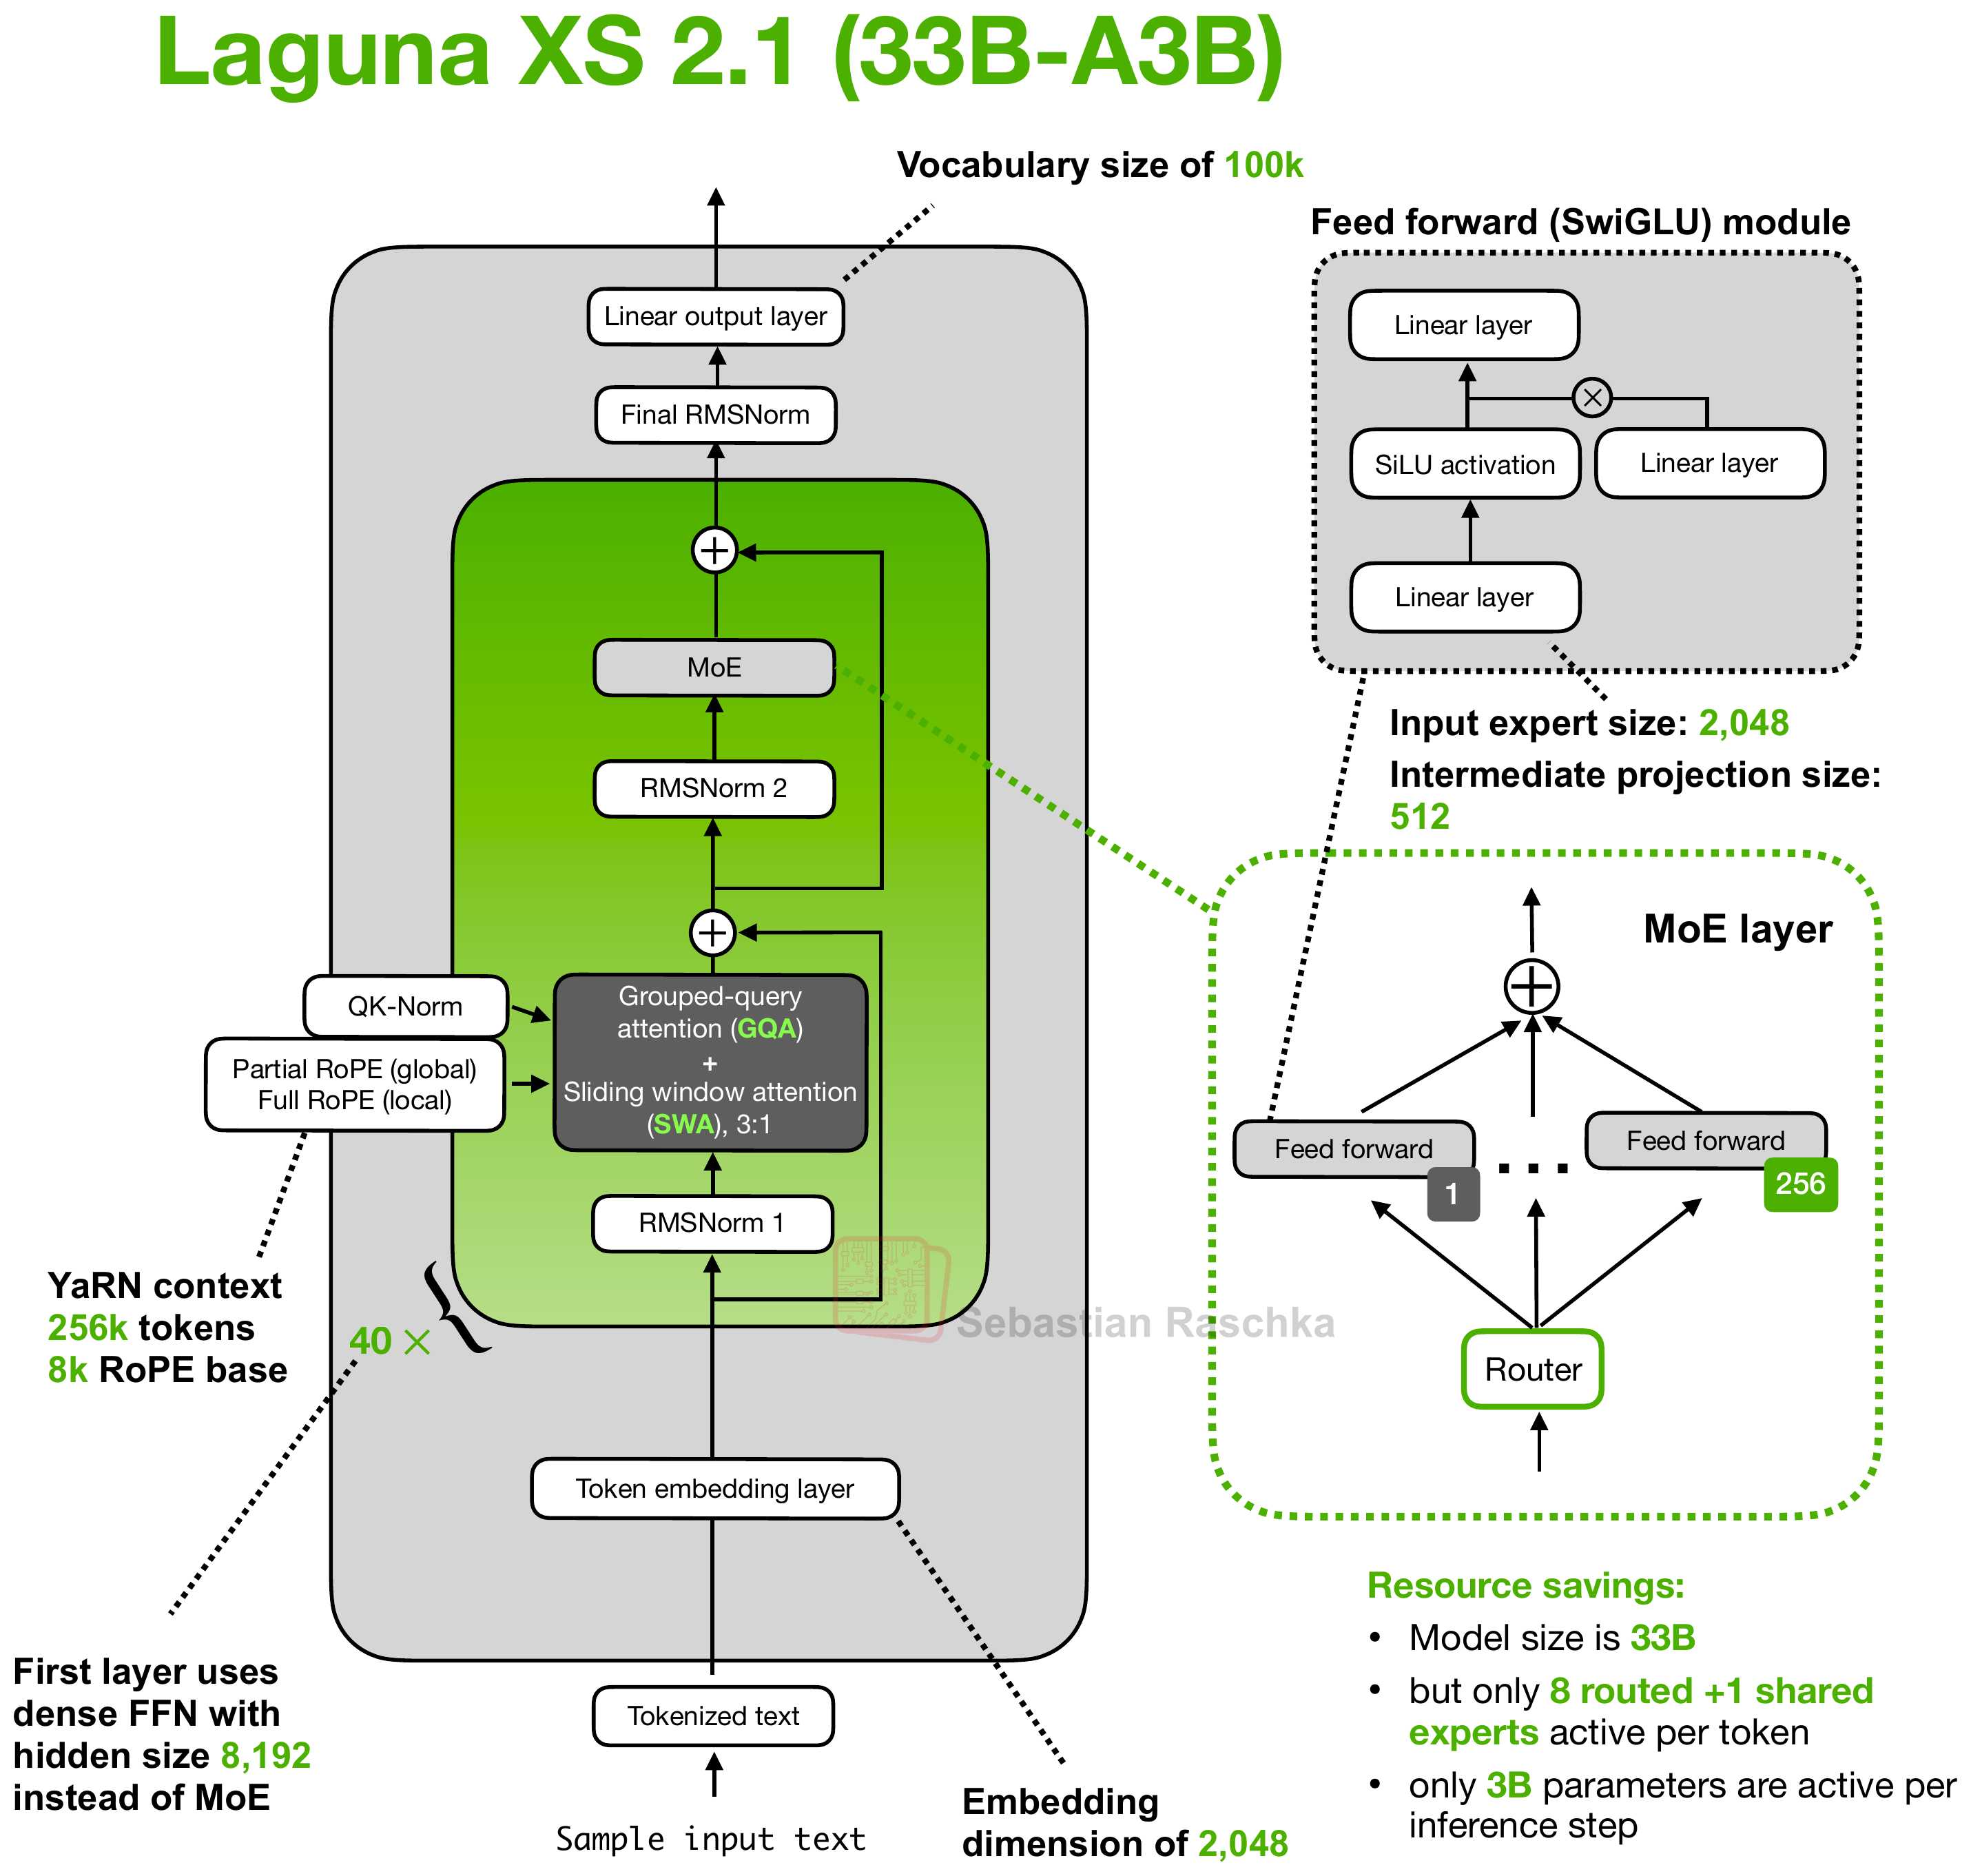
Poolside's 33B Laguna refresh extends the sparse MoE architecture to 262k context while keeping about 3B parameters active per token.
Architecture and specifications
- Scale
- 33B total, 3B active (9.1% active)
- Context (tokens)
- 262,144
- Vocabulary
- 100,352 (~100k)
- License
- OpenMDW License 1.1
- Date
- 2026-07-02
- Decoder type
- Sparse MoE
- Attention
- Gated GQA with QK-Norm and 3:1 sliding-window/global attention
- Layer mix
- 30 sliding-window + 10 global GQA
- KV cache / token (bf16) info
- 160 KiB · Moderate
- Key detail
- Uses 256 routed experts with top-8 routing plus one shared expert, a dense first layer, and per-layer query-head counts.
Training and benchmarks
- Pretraining data
- Not disclosed The version-specific release sources do not give a token total; the linked earlier report covers XS.2. Model card · Release post
- Post-training methods
- RL The model card confirms reinforcement learning but does not publish the complete version-specific post-training recipe. Model card