
Laguna S 2.1 Architecture
Back to Laguna S 2.1 in the gallery
Poolside
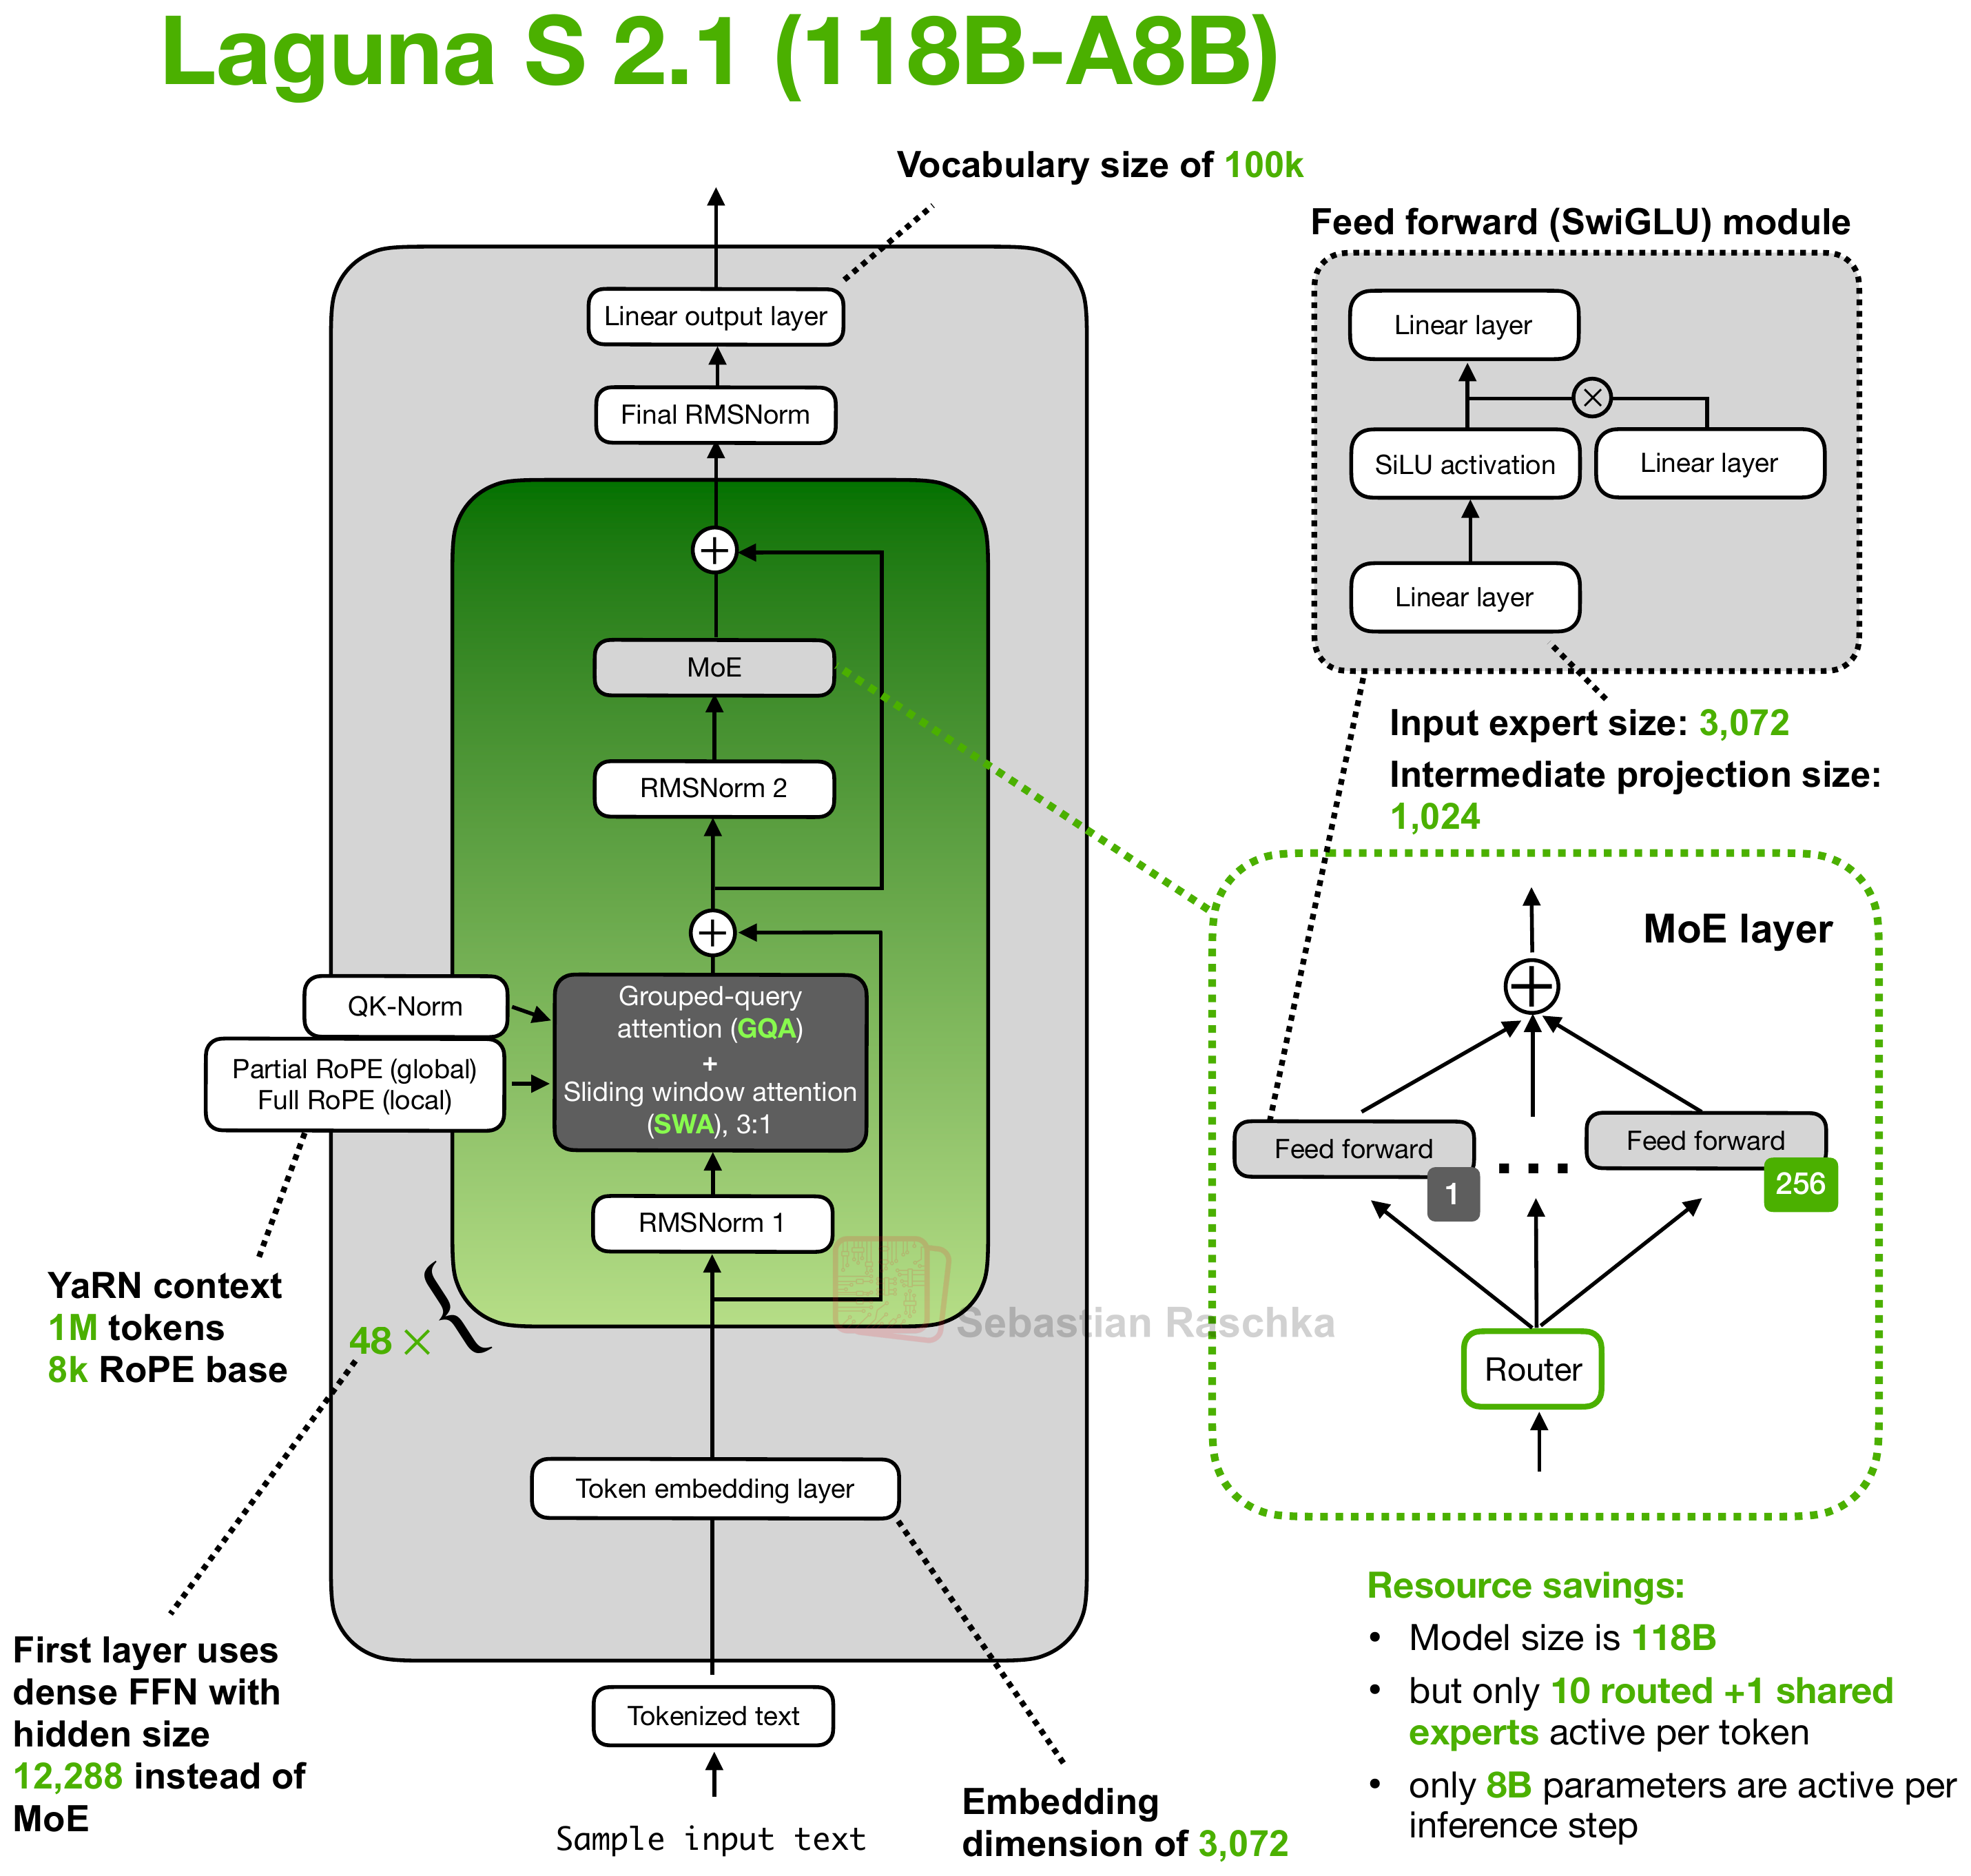
Poolside's 118B sparse MoE scales the Laguna XS recipe to 48 layers and 1M context while activating about 8B parameters per token.
Architecture and specifications
- Scale
- 118B total, 8B active (6.8% active)
- Context (tokens)
- 1,048,576
- Vocabulary
- 100,352 (~100k)
- License
- OpenMDW License 1.1
- Date
- 2026-07-21
- Decoder type
- Sparse MoE
- Attention
- Gated GQA with QK-Norm and 3:1 sliding-window/global attention
- Layer mix
- 36 sliding-window + 12 global GQA
- KV cache / token (bf16) info
- 192 KiB · High
- Key detail
- Uses 256 routed experts with top-10 routing plus one shared expert, a dense first layer, and per-layer query-head counts.
Training and benchmarks
- Pretraining data
- Not disclosed Uses the same pretraining data as XS 2.1, but the release post does not give a token count for either run. Release post
- Post-training methods
- SFT, RLVR SFT with partly synthetic data is followed by RL on harder tasks, including software changes checked against executable test suites. Release post