
Domyn Edge 3.93B Architecture
Back to Domyn Edge 3.93B in the gallery
Domyn
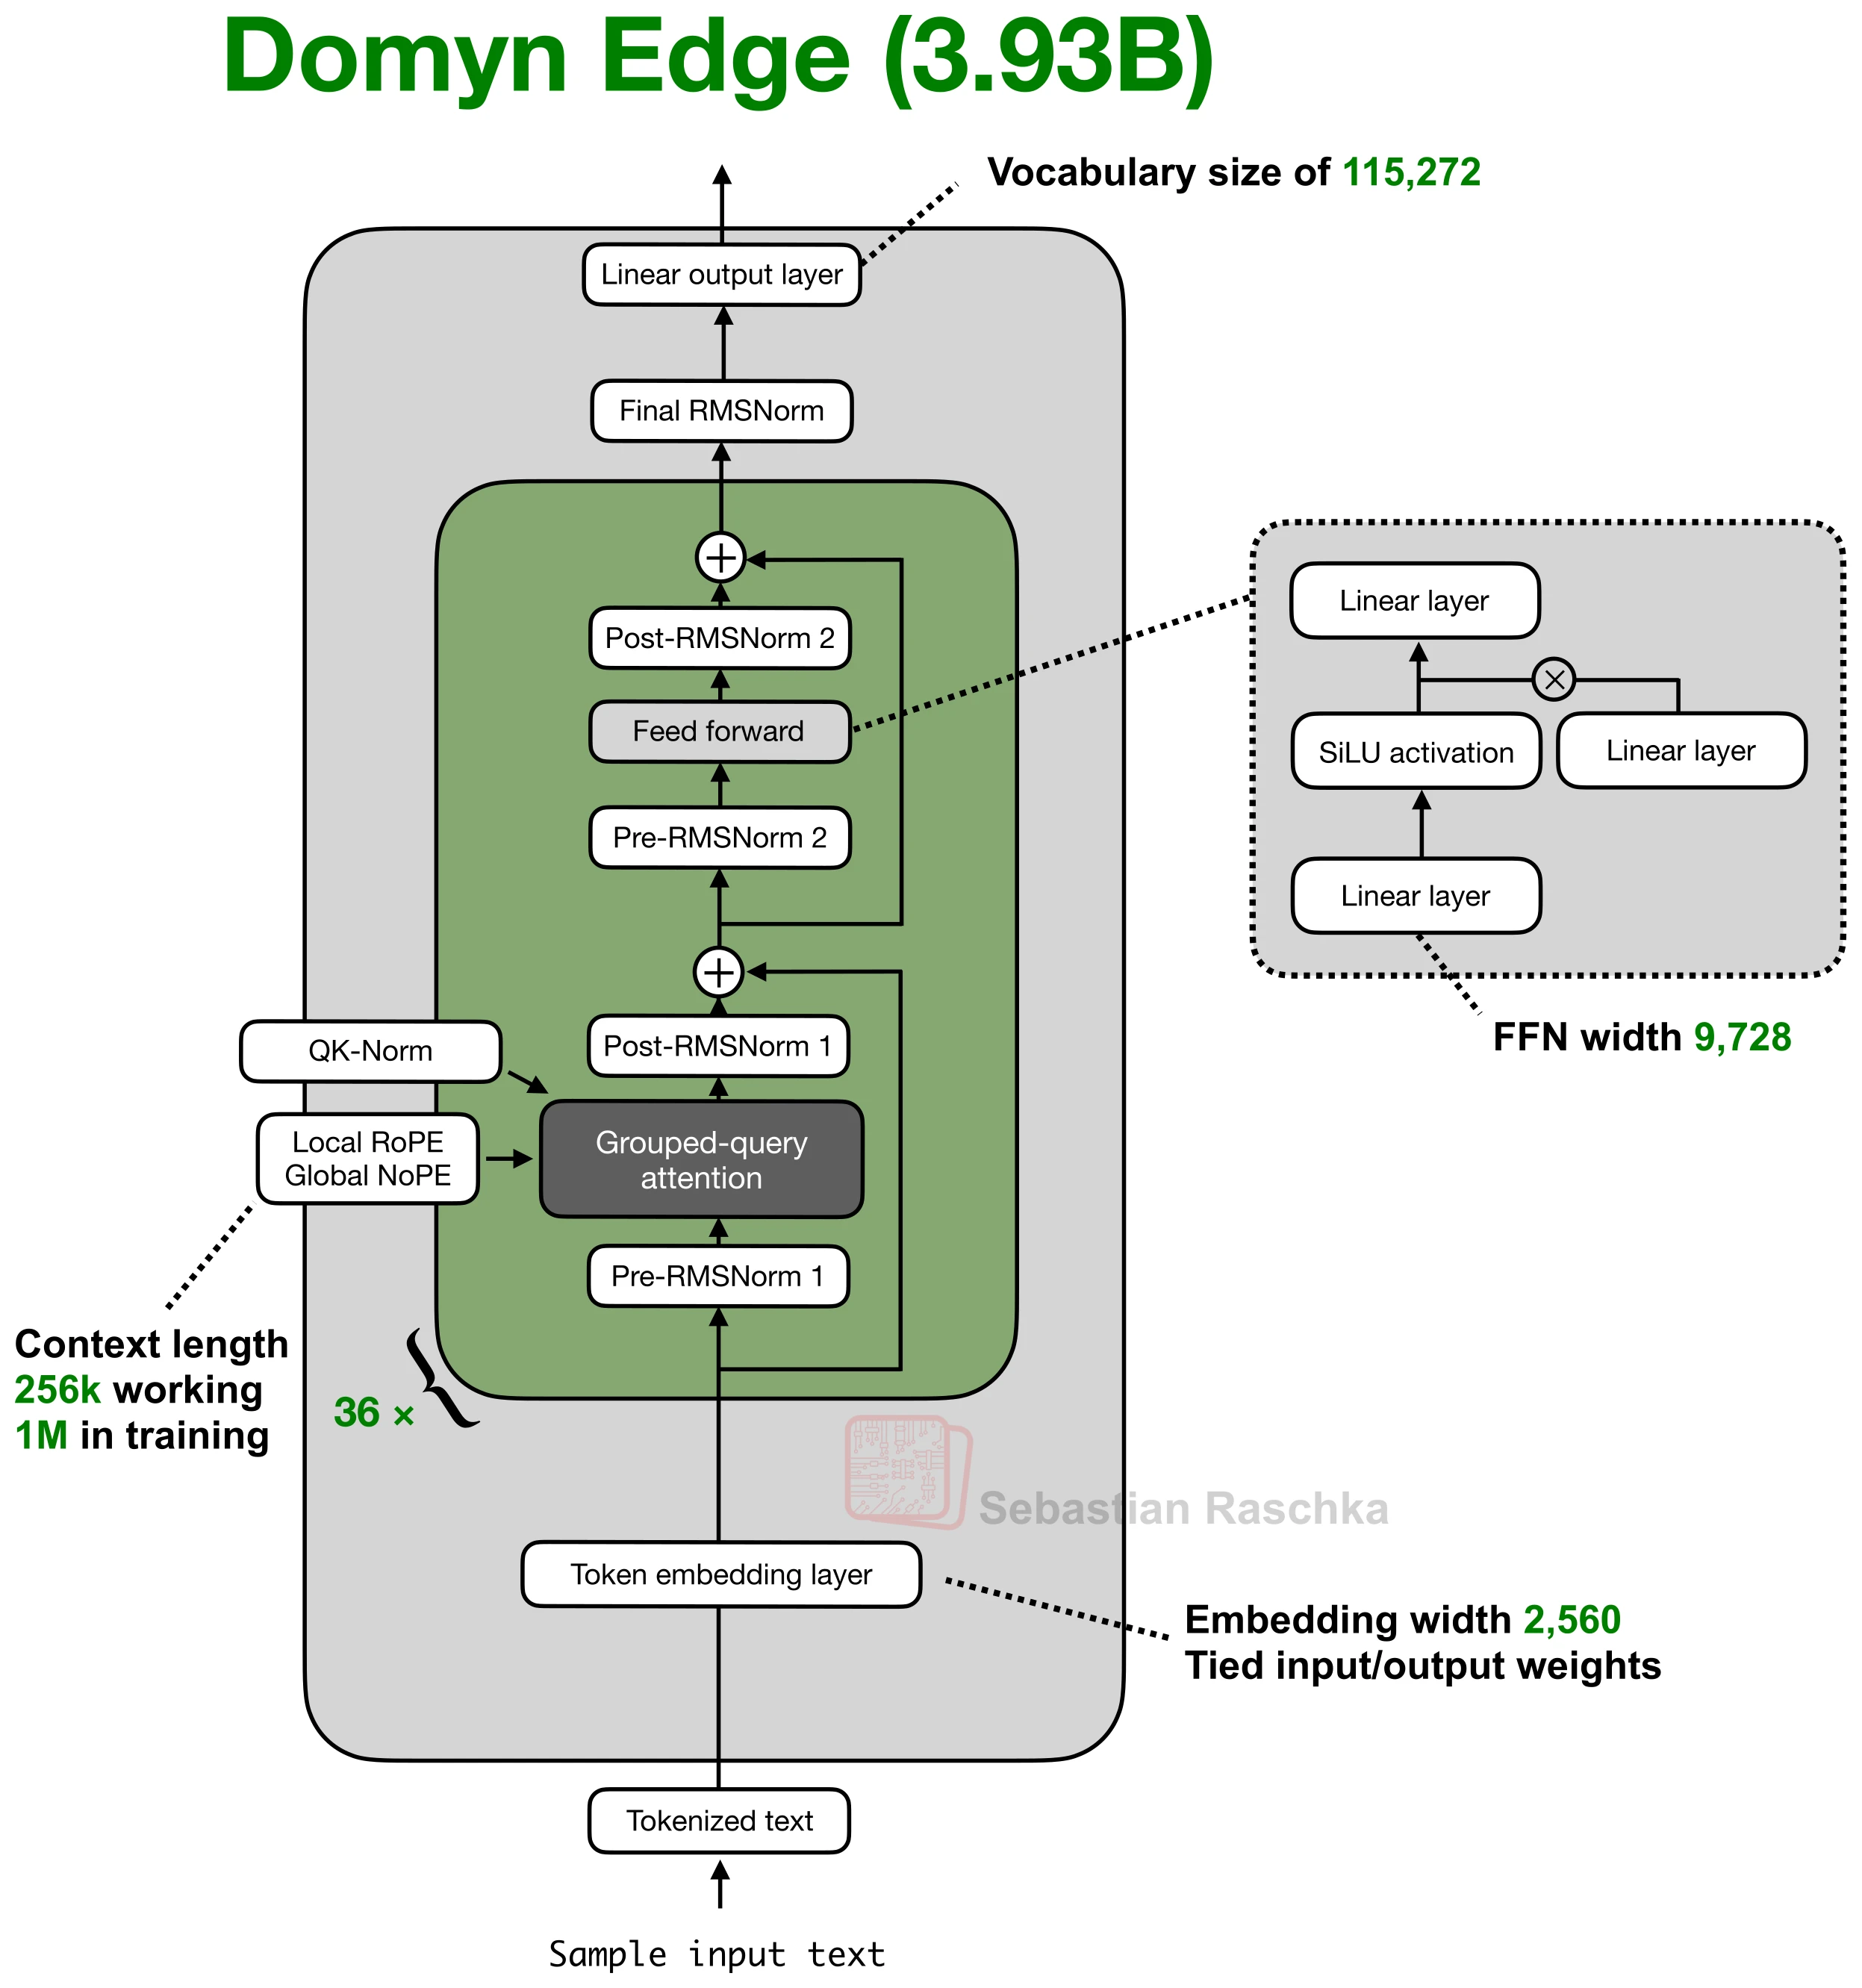
Domyn Edge uses wider heads in its global attention layers. Domyn trained it on sequences up to 1,048,576 tokens and recommends 262,144 for inference.
Architecture and specifications
- Scale
- 3.93B parameters
- Context (tokens)
- 262,144
- Vocabulary
- 115,272 (~115k)
- License
- Apache License 2.0
- Date
- 2026-10-20
- Decoder type
- Dense
- Attention
- GQA with 32 query heads and 8 KV heads. Local layers use 64-dimensional heads with RoPE and look back 1,024 tokens. Global layers use 256-dimensional heads and NoPE.
- Layer mix
- 24 sliding-window + 12 global GQA
- KV cache / token (bf16) info
- 144 KiB · Moderate
- Key detail
- The 2,560-wide decoder uses tied embeddings and a 9,728-wide SwiGLU feed-forward layer. Each block applies RMSNorm before and after both sublayers. QK-Norm learns a scale for keys only.
Training and benchmarks
- Pretraining data
- 13.03T tokens Domyn trained the base model from scratch in six stages on the Leonardo supercomputer. The first stage used an 8.44T-token mix of web, code, STEM, multilingual, and synthetic data. Domyn Edge base model card · Domyn Edge release announcement
- Post-training methods
- SFT Domyn fine-tuned the separate Domyn Edge SFT checkpoint on math, code, tool use, and instruction following. Its supervised training included conversations up to 512k tokens long. Domyn Edge SFT model card