
BTL-3 27B Architecture
Back to BTL-3 27B in the gallery
Bad Theory Labs
Agent-oriented Qwen3.6-27B derivative that adds a rank-32 LoRA adapter for coding, structured tool use, and long multi-turn execution.
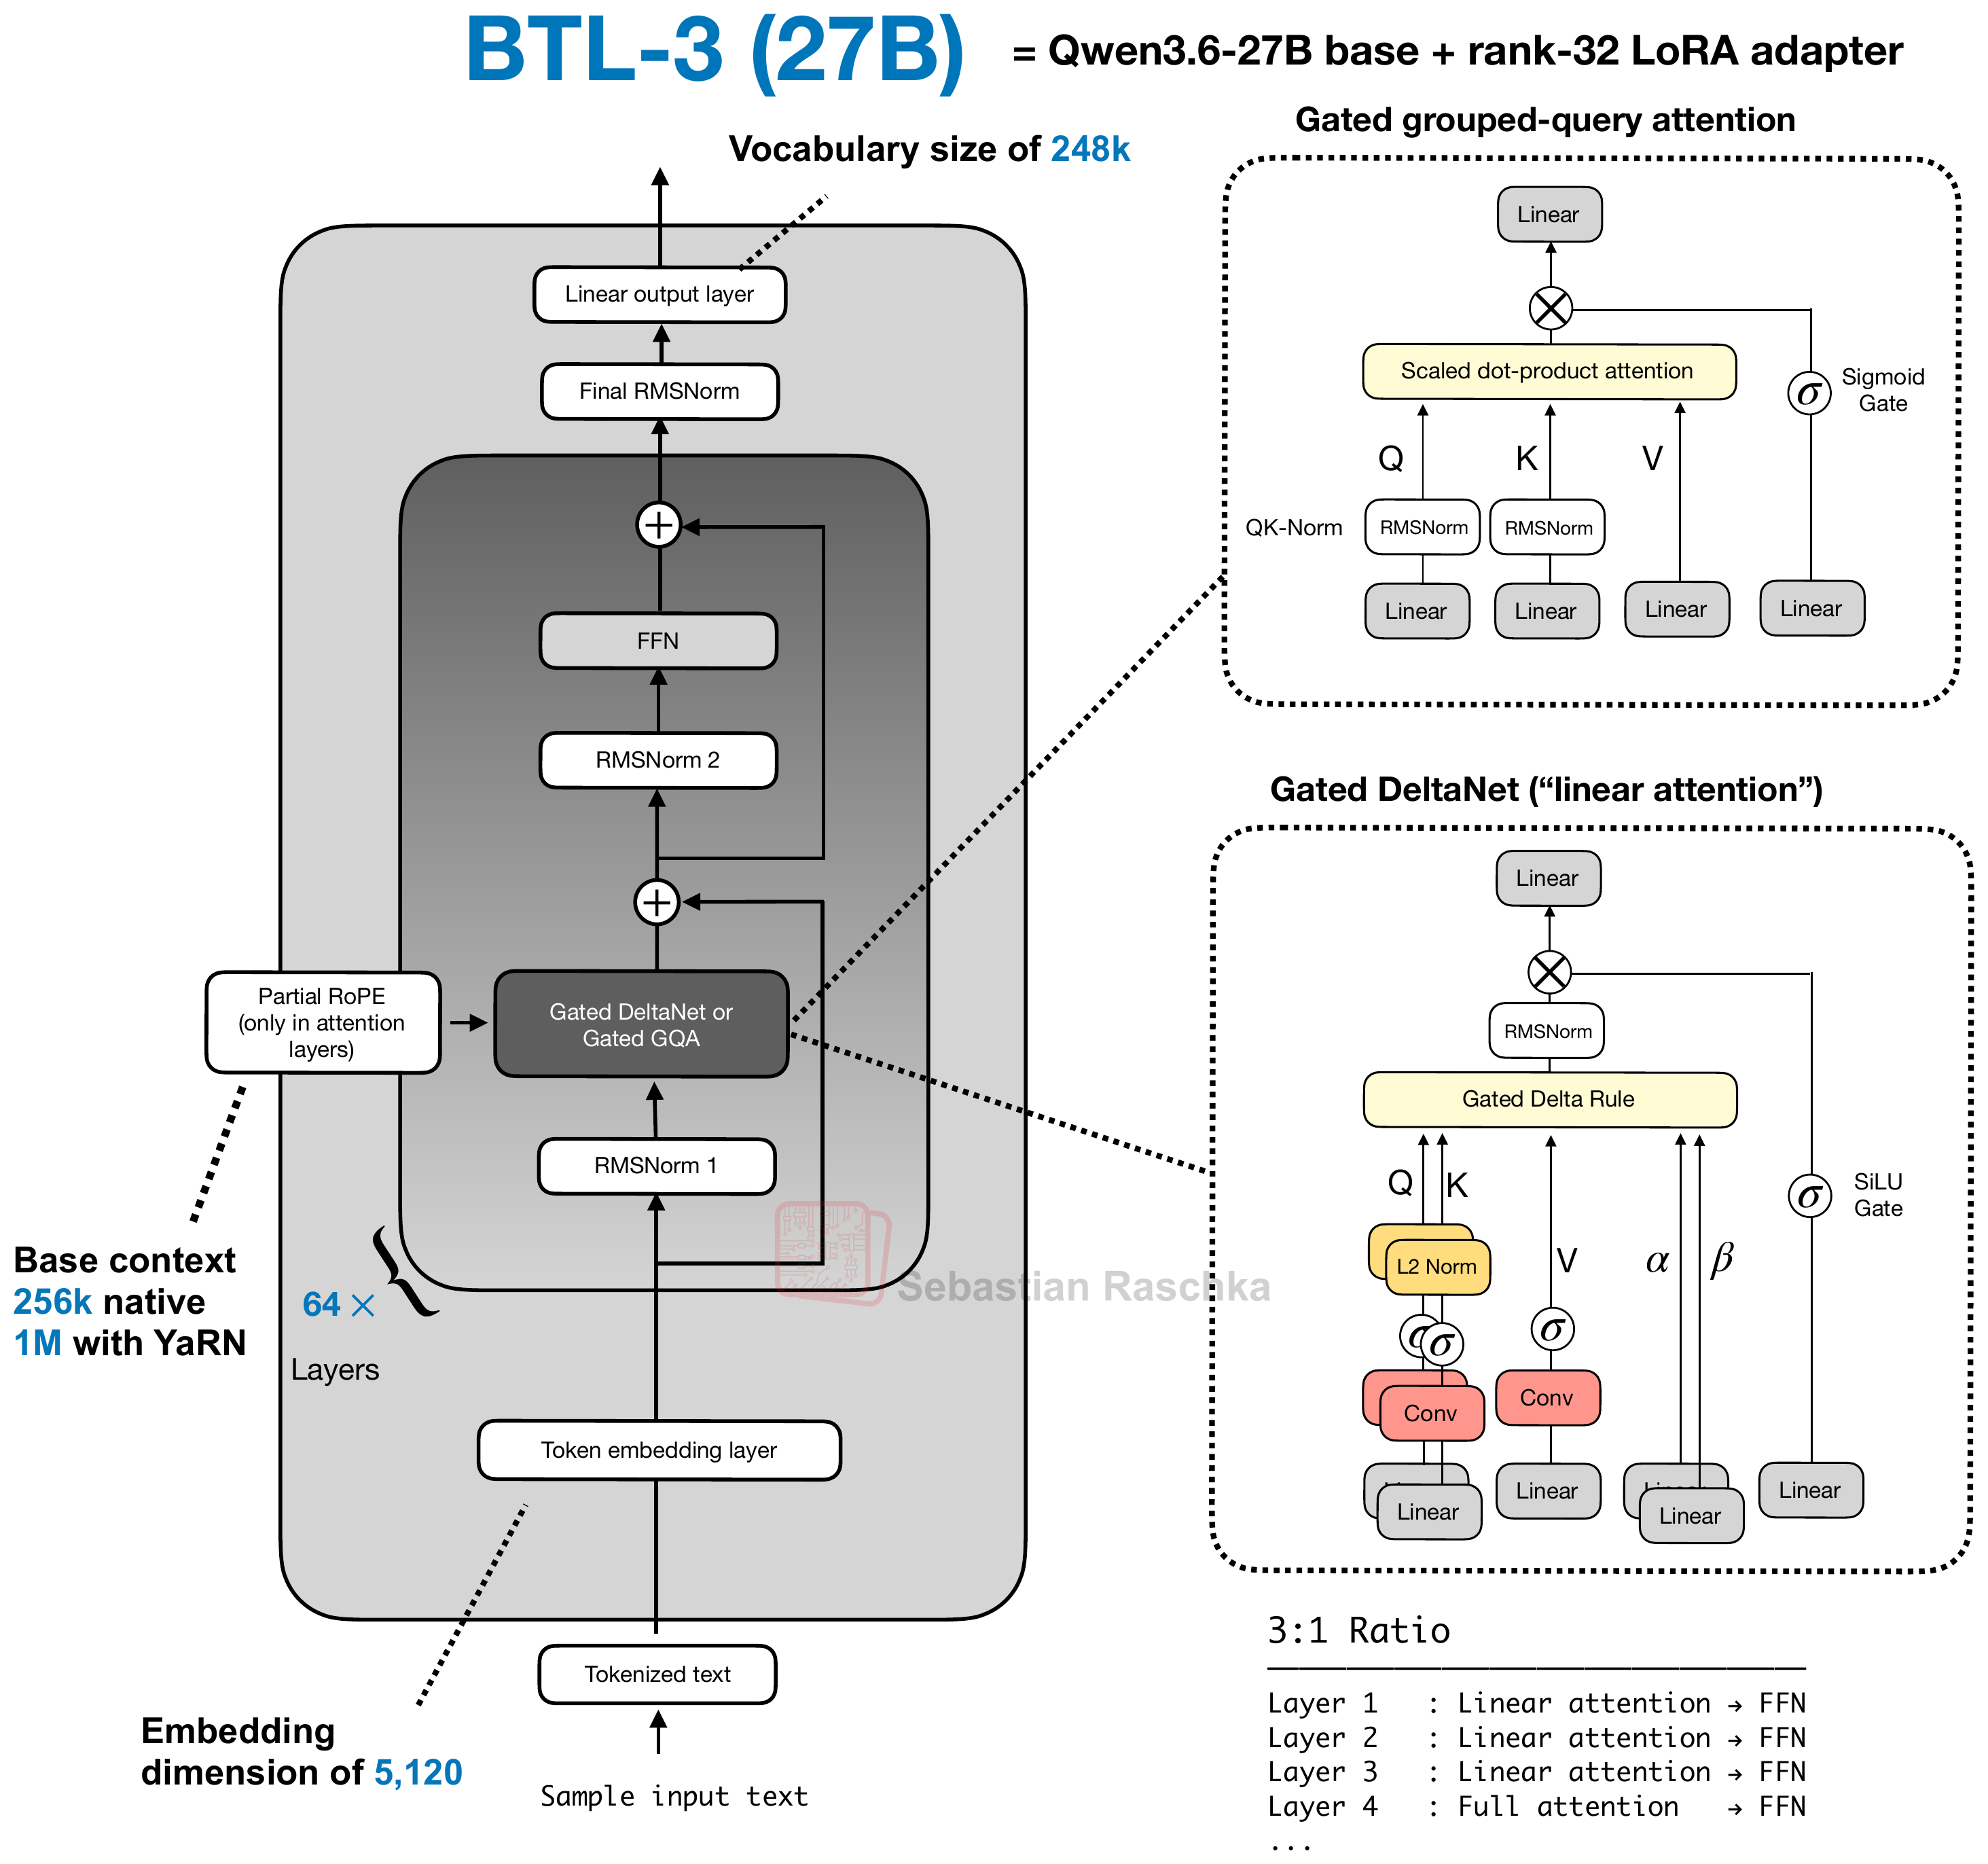
Architecture and specifications
- Scale
- 27B base + 934 MB LoRA adapter
- Context (tokens)
- 262,144
- Vocabulary
- 248,320 (~248k)
- License
- Apache License 2.0
- Date
- 2026-07-20
- Decoder type
- Dense hybrid
- Attention
- 3:1 Gated DeltaNet and gated attention with GQA
- Layer mix
- 16 gated attention + 48 DeltaNet
- KV cache / token (bf16) info
- 64 KiB · Low
- Key detail
- Retains Qwen3.6-27B's 64-layer hybrid stack while adapting its attention, DeltaNet, and FFN projections through rank-32 LoRA.
Training and benchmarks
- Pretraining data
- Not disclosed Qwen3.6-27B derivative; its model card does not disclose a pretraining token count. BTL-3 model card
- Post-training methods
- RL, LoRA Released as the RL-0013 rank-32 LoRA adapter. The card does not specify the reward source or a separate SFT stage. BTL-3 model card