
ZAYA1-8B Architecture
Back to ZAYA1-8B in the gallery
Zyphra
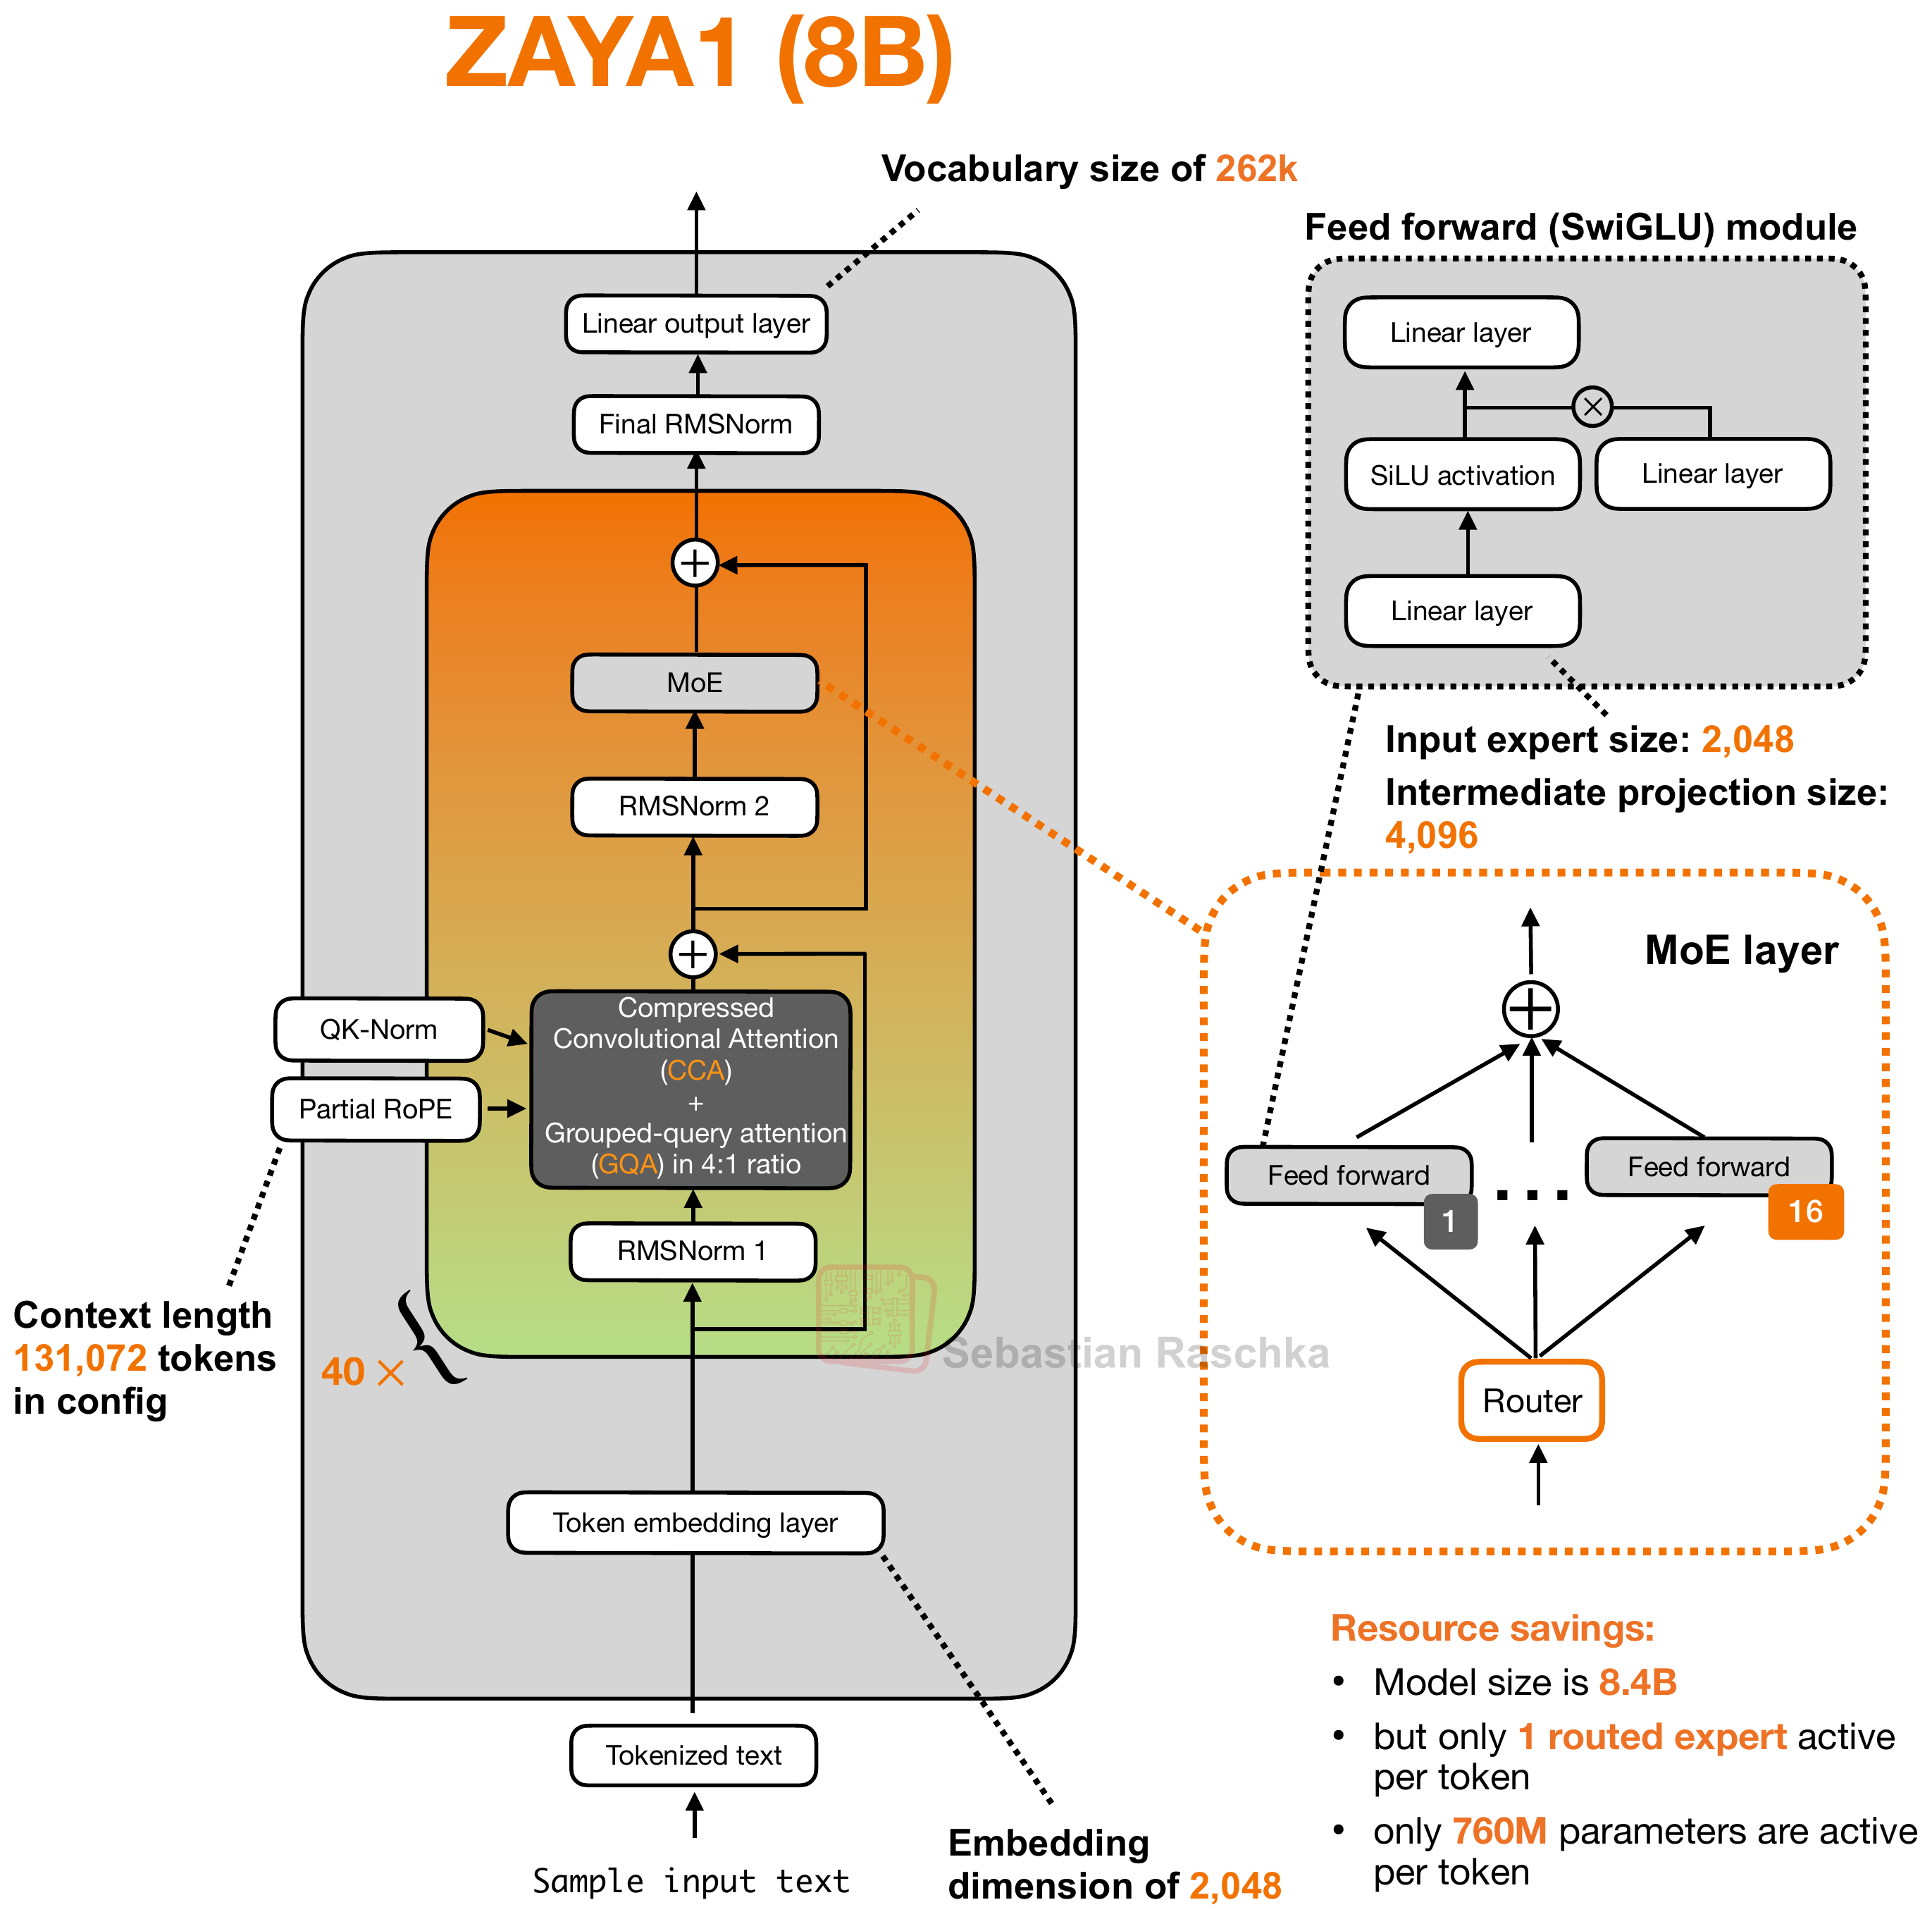
Zyphra's compact reasoning MoE pairs CCA/GQA attention updates with top-1 routed expert FFN updates to keep fewer than 1B parameters active per token.
Architecture and specifications
- Scale
- 8.4B total, 760M active/token (9% active)
- Context (tokens)
- 131,072
- Vocabulary
- 262,272
- License
- Apache License 2.0
- Date
- 2026-05-06
- Decoder type
- Sparse MoE
- Attention
- CCA with 4:1 GQA, RoPE, and Q/K L2 norm
- Layer mix
- 40 CCA/GQA attention + 40 top-1 MoE FFN entries
- KV cache / token (bf16) info
- 40 KiB · Low
- Key detail
- Key detail is CCA/GQA attention, which performs attention in a compressed latent space while keeping a 4:1 GQA layout. Sidenote: the config lists 80 alternating layer entries, equivalent to 40 CCA/GQA attention updates paired with 40 top-1 MoE FFN updates.
Training and benchmarks
- Pretraining data
- 12T tokens + 1.2T mid-training tokens Base phases consume 8T + 4T; 32K mid-training adds 1.2T. The separate SFT stage consumes 660B tokens. Technical report
- Post-training methods
- SFT, RLVR, RLHF SFT, three verifiable reasoning RL stages, then behavioral RLHF for chat and instruction following. Technical report