
MiniMax M3 428B Architecture
Back to MiniMax M3 428B in the gallery
MiniMax
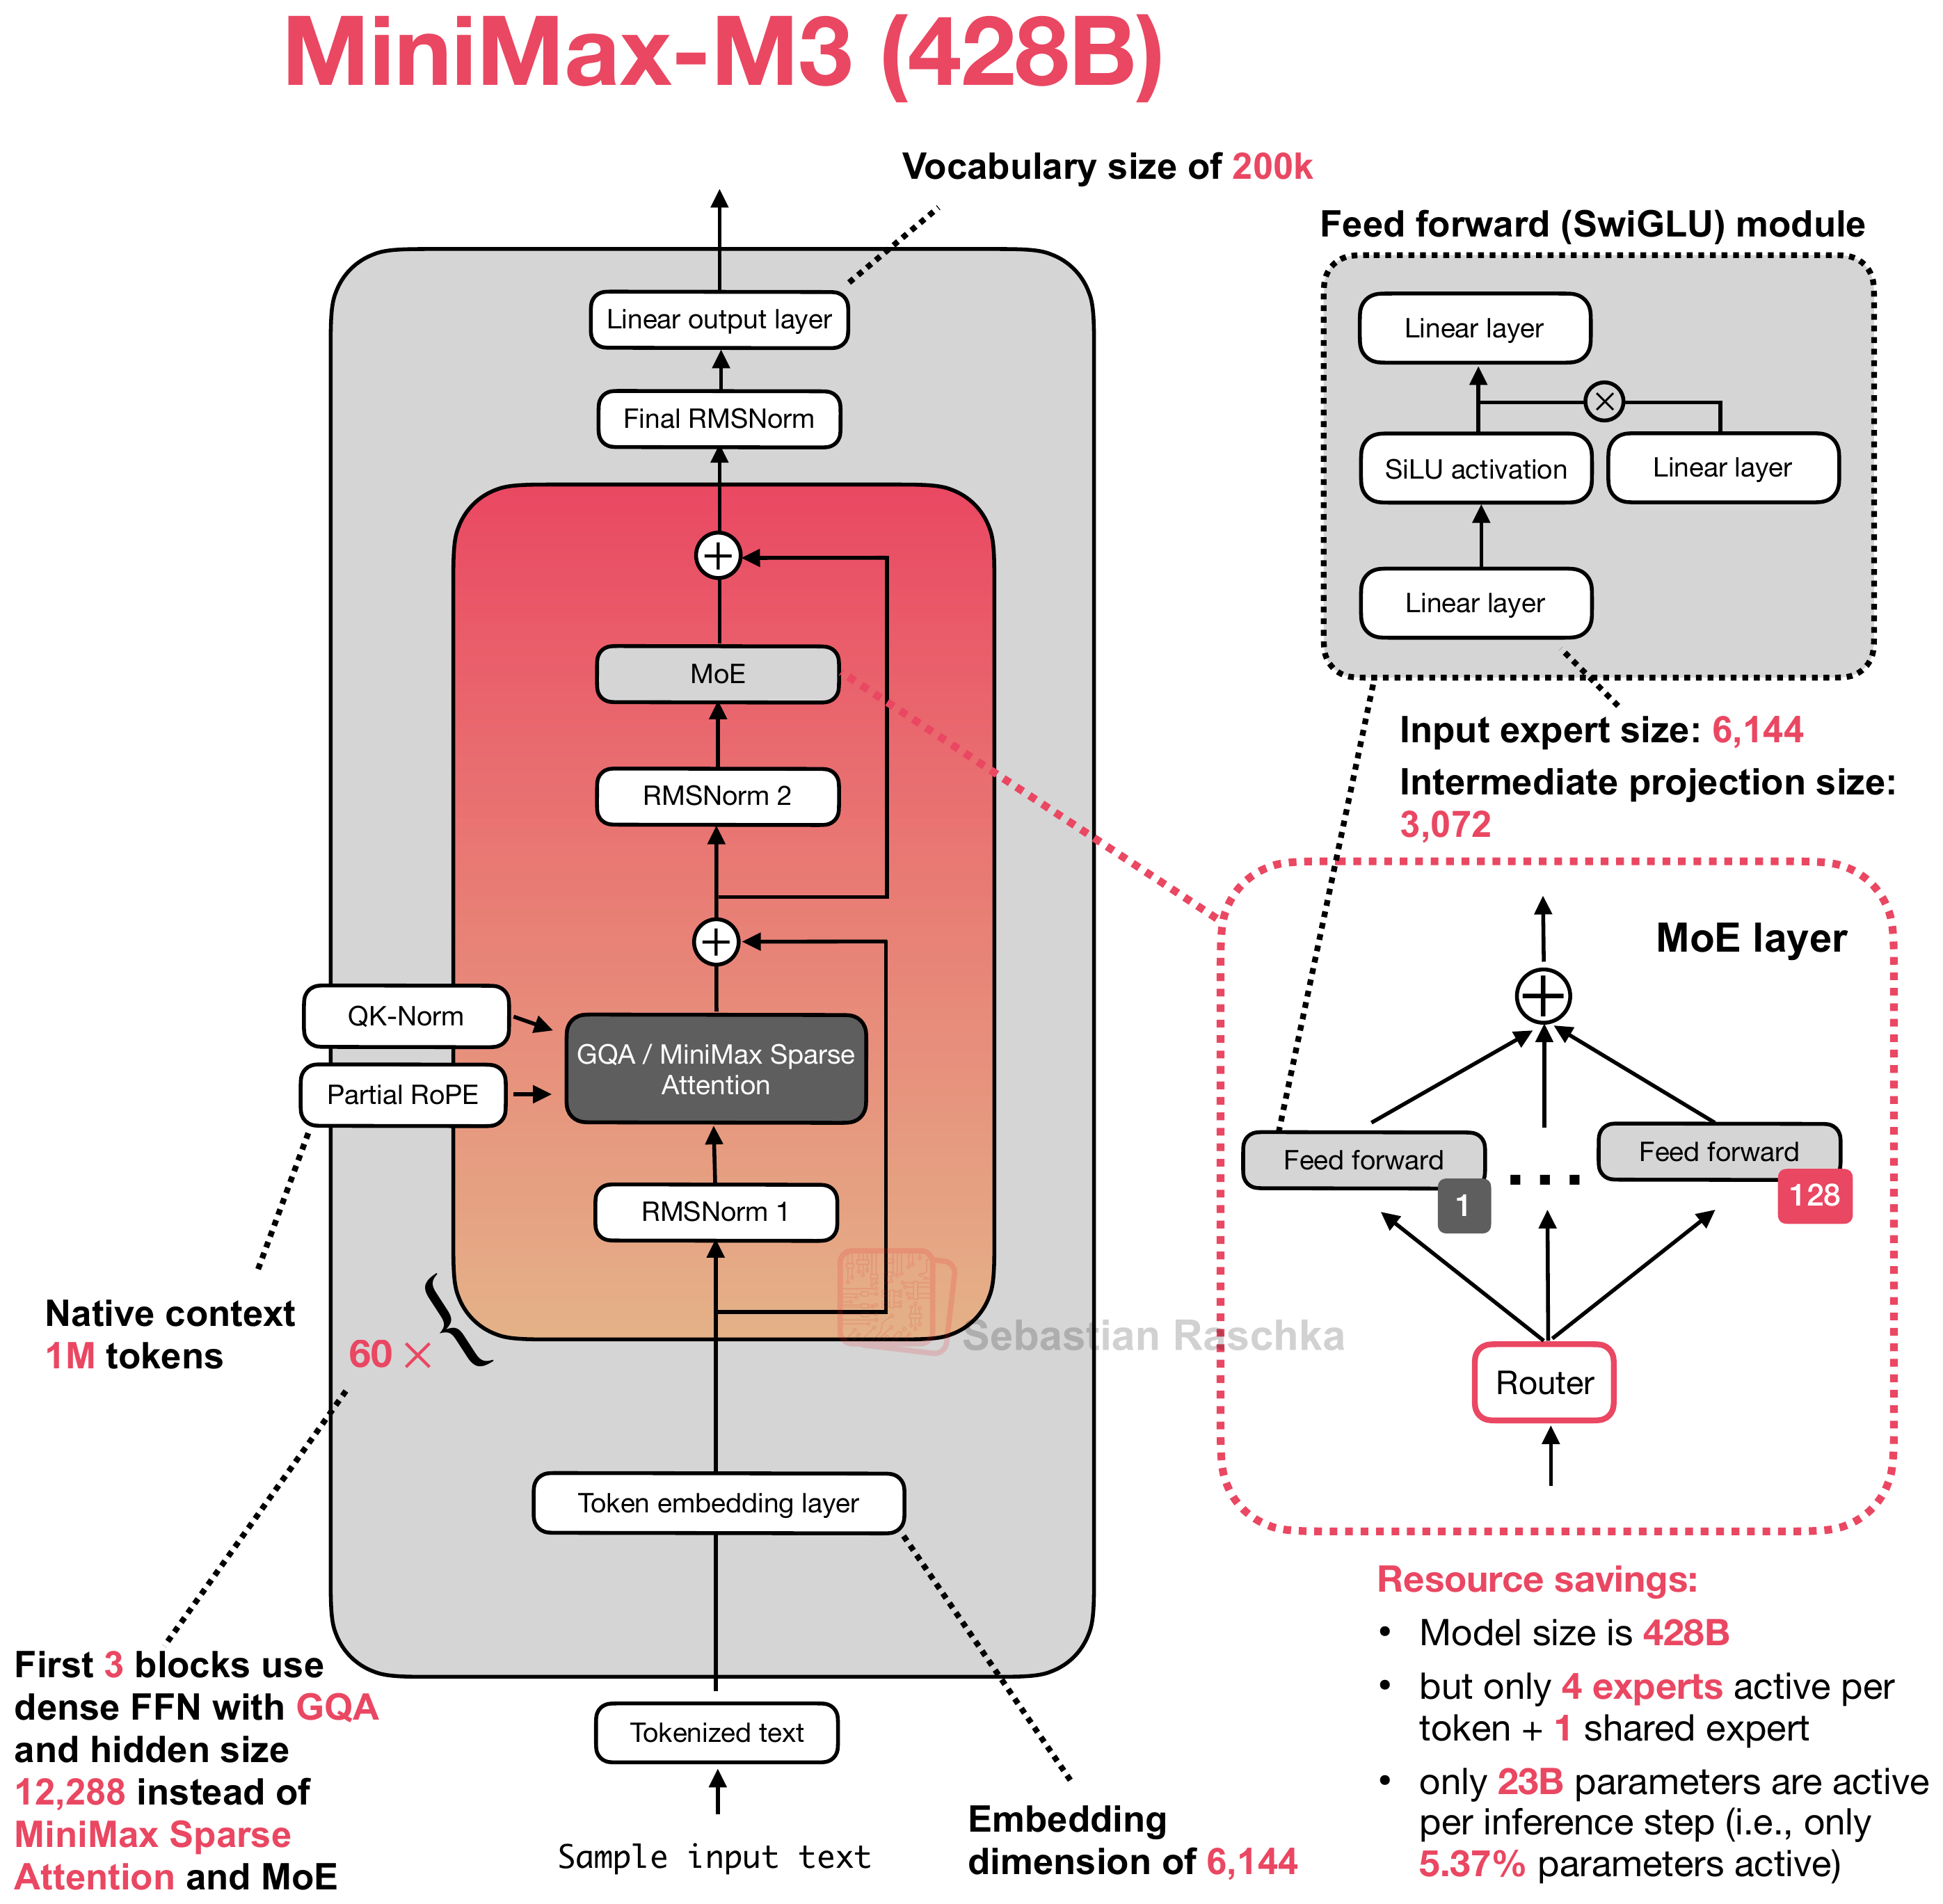
Native multimodal MiniMax model that adds sparse attention to an M2-style MoE backbone for 1M-token context.
Architecture and specifications
- Scale
- 428B total, 23B active (5.4% active)
- Context (tokens)
- 1,048,576
- License
- MiniMax Community License
- Date
- 2026-06-13
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm and MiniMax Sparse Attention
- Layer mix
- 3 full GQA + 57 MiniMax Sparse Attention
- KV cache / token (bf16) info
- 120 KiB · Moderate
- Key detail
- Uses three dense prefix layers, then 57 sparse-attention MoE layers with 128 routed experts and 4 routed plus 1 shared expert active per token.
Training and benchmarks
- Pretraining data
- Not disclosed The release describes native multimodal pretraining but gives no token total for the production 428B model. MiniMax M3 release
- Post-training methods
- RL, Rejection sampling Proof and verifier experts use RL with generative judges. Rejection-sampled fine-tuning trains a repair expert. These experts enter M3's merged training; the complete recipe is unspecified. MiniMax MaxProof training details