
LongCat-2.5 1.6T-A48B Architecture
Back to LongCat-2.5 1.6T-A48B in the gallery
Meituan
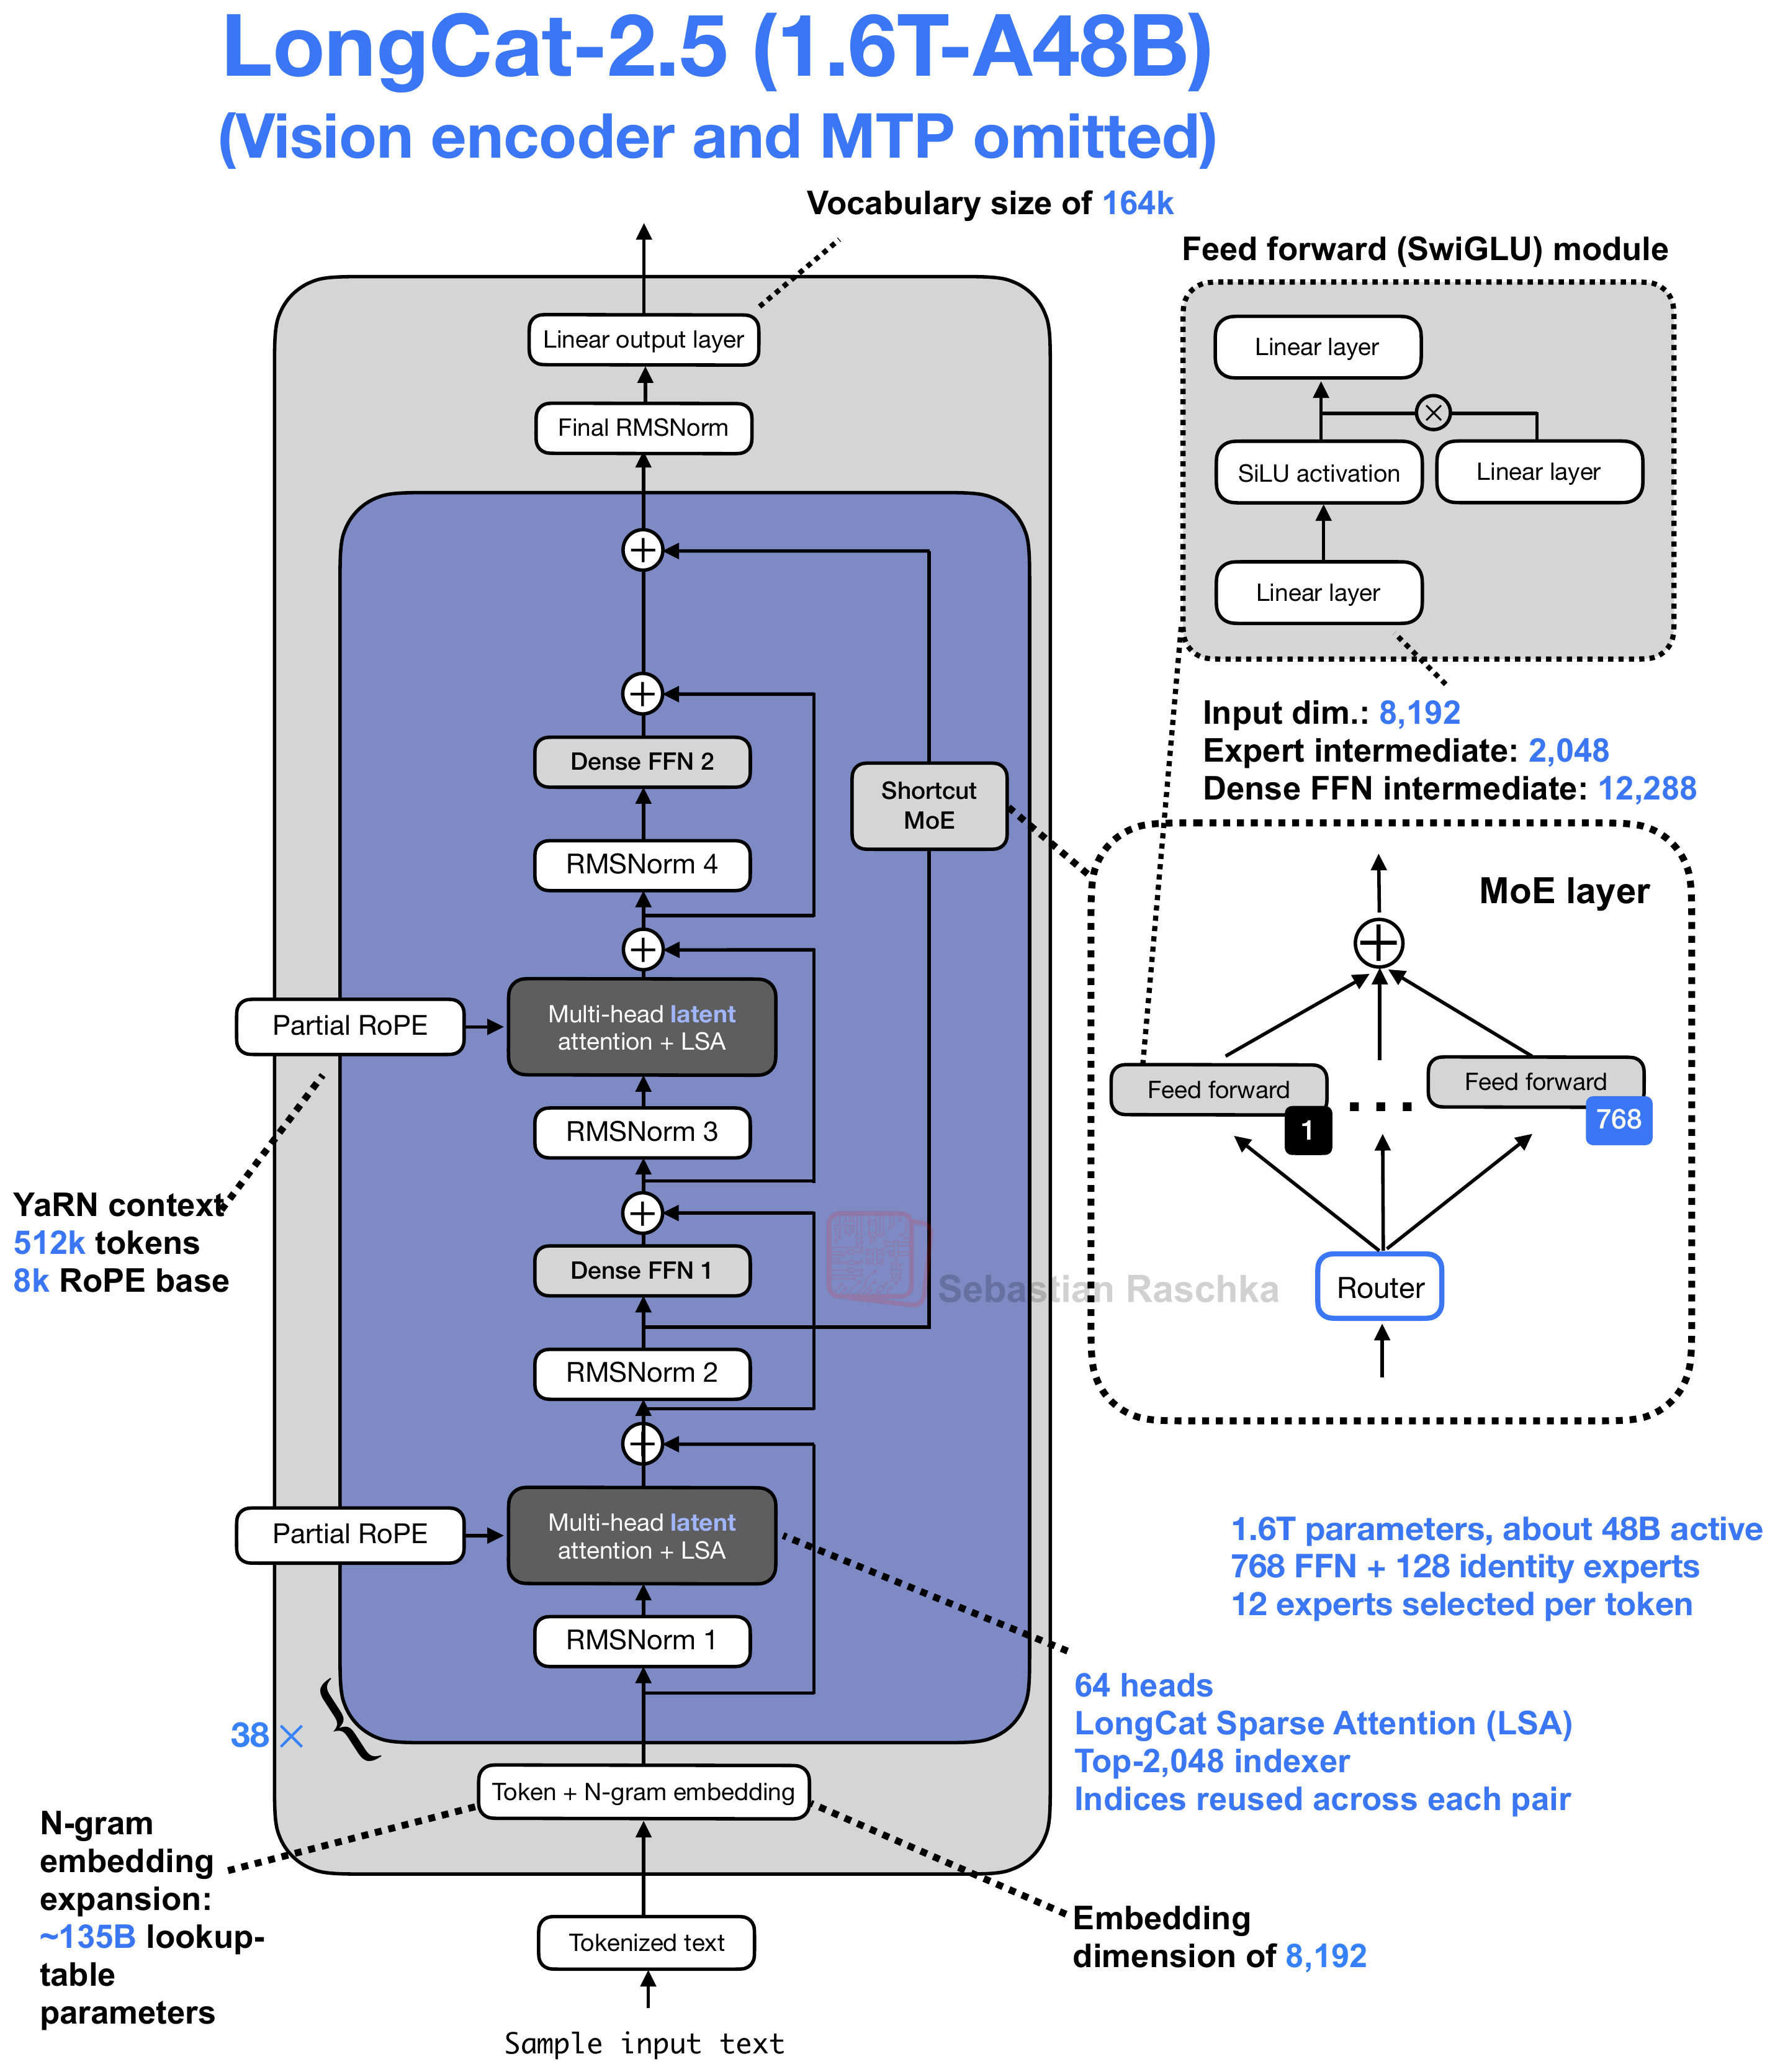
Meituan's native multimodal MoE combines Shortcut MoE, n-gram embeddings, and LongCat Sparse Attention. The figure shows the language backbone, with the vision encoder and MTP module omitted.
Architecture and specifications
- Scale
- 1.6T total, ~48B active (3% active)
- Context (tokens)
- 524,288
- Vocabulary
- 163,840 (~164k)
- License
- MIT License
- Date
- 2026-11-02
- Decoder type
- Sparse MoE
- Attention
- MLA with LongCat Sparse Attention (LSA) and cross-layer index reuse
- Layer mix
- 38 blocks / 76 MLA + LSA sublayers
- KV cache / token (bf16) info
- 95 KiB · Moderate
- Key detail
- Reuses top-2,048 token selections across each attention pair. Shortcut MoE selects 12 of 768 learned and 128 identity experts; n-gram lookup tables hold about 135B parameters.
Training and benchmarks
- Pretraining data
- Not disclosed The release card does not publish a pretraining-token total. Model card
- Post-training methods
- SFT, RL, Distillation The release describes long-sequence SFT, large-scale RL, and multi-teacher full-vocabulary KL distillation. Model card