
LFM2.5 8B-A1B Architecture
Back to LFM2.5 8B-A1B in the gallery
Liquid AI
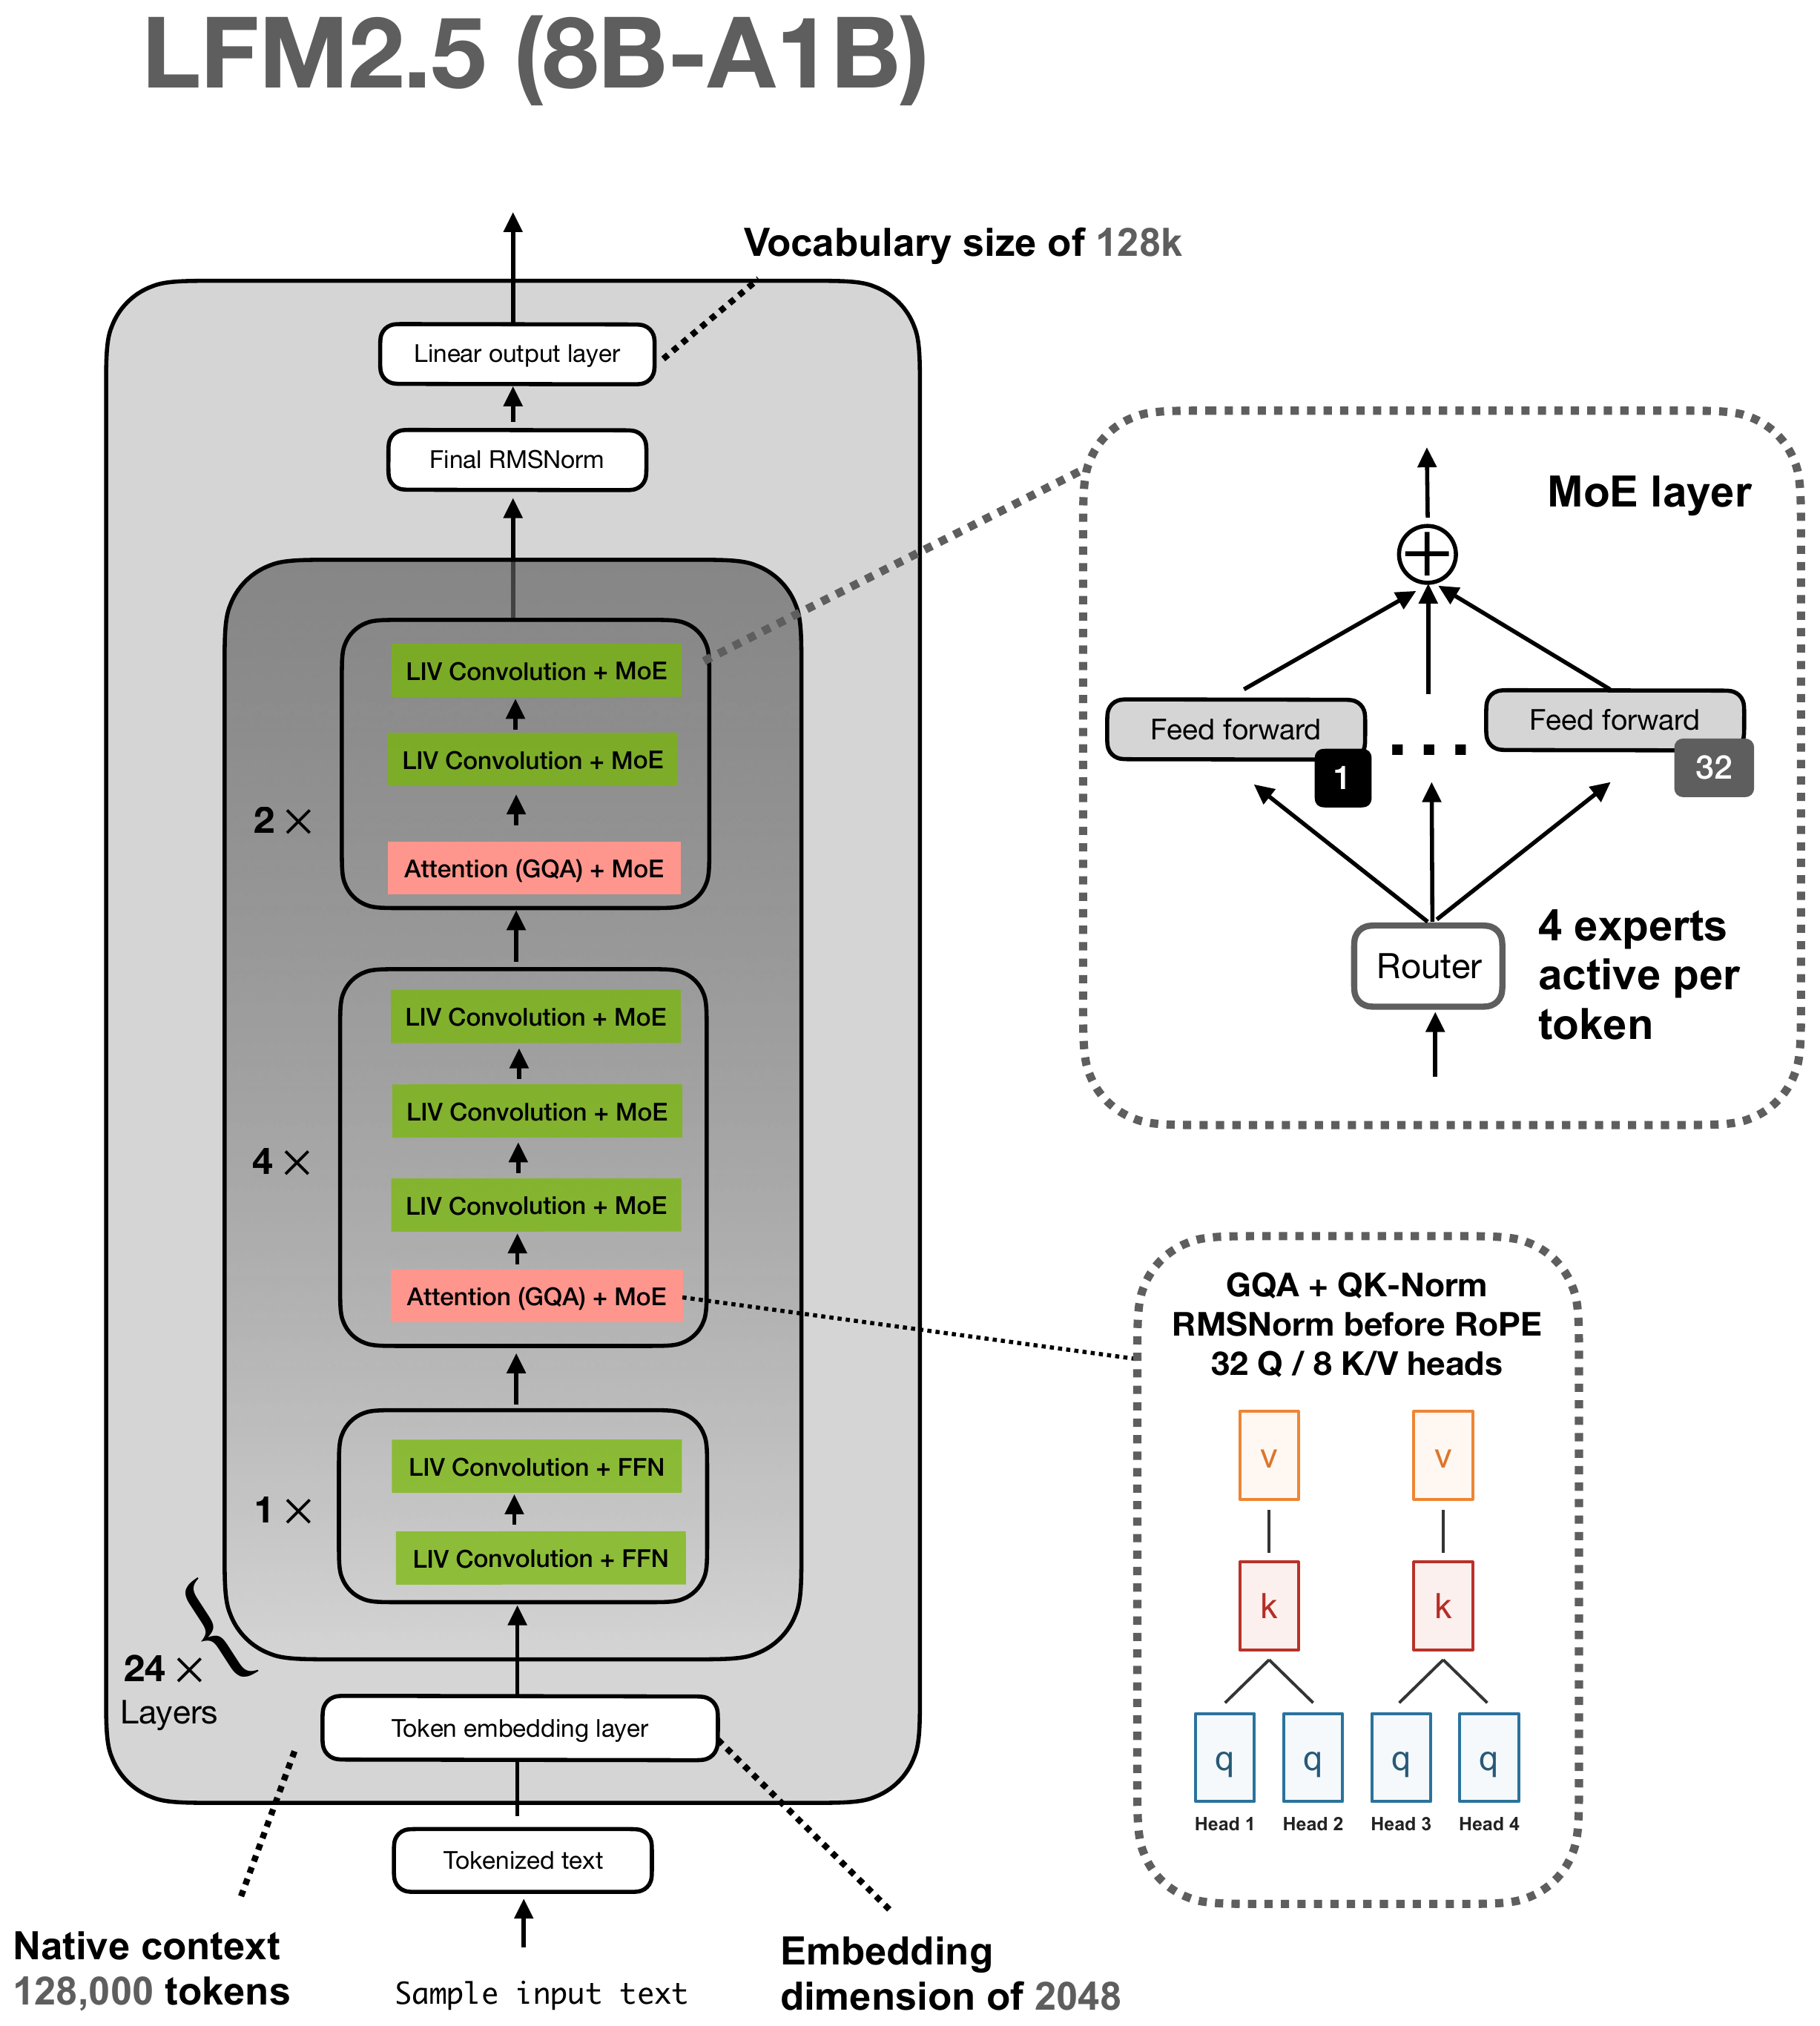
Liquid AI's sparse LFM2.5 model combines LIV convolution, GQA, and MoE routing with 4 of 32 experts active per token.
Architecture and specifications
- Scale
- 8.3B total, 1.5B active (18.1% active)
- Context (tokens)
- 128,000
- Vocabulary
- 128,000
- License
- LFM Open License v1.0
- Date
- 2026-05-28
- Decoder type
- Sparse hybrid
- Attention
- LIV convolution blocks plus GQA with QK-Norm and MoE
- Layer mix
- 18 LIV conv + 6 GQA + MoE FFNs
- KV cache / token (bf16) info
- 12 KiB · Very low
- Key detail
- GQA appears in layers 3, 7, 11, 15, 19, and 22. The first two feed-forward networks are dense. Later layers activate 4 of 32 experts per token.
Training and benchmarks
- Pretraining data
- 38T tokens The release reports pretraining scaled from 12T to 38T tokens. It also describes 2T and 400B context-extension stages without clearly separating them from that total. Release post
- Post-training methods
- RL, Preference optimization Large-scale RL includes a targeted hallucination-reduction stage. A separate preference-optimization stage reduces reasoning loops; its objective is not named DPO. Release post