
Kimi Linear 48B-A3B Architecture
Back to Kimi Linear 48B-A3B in the gallery
Moonshot AI
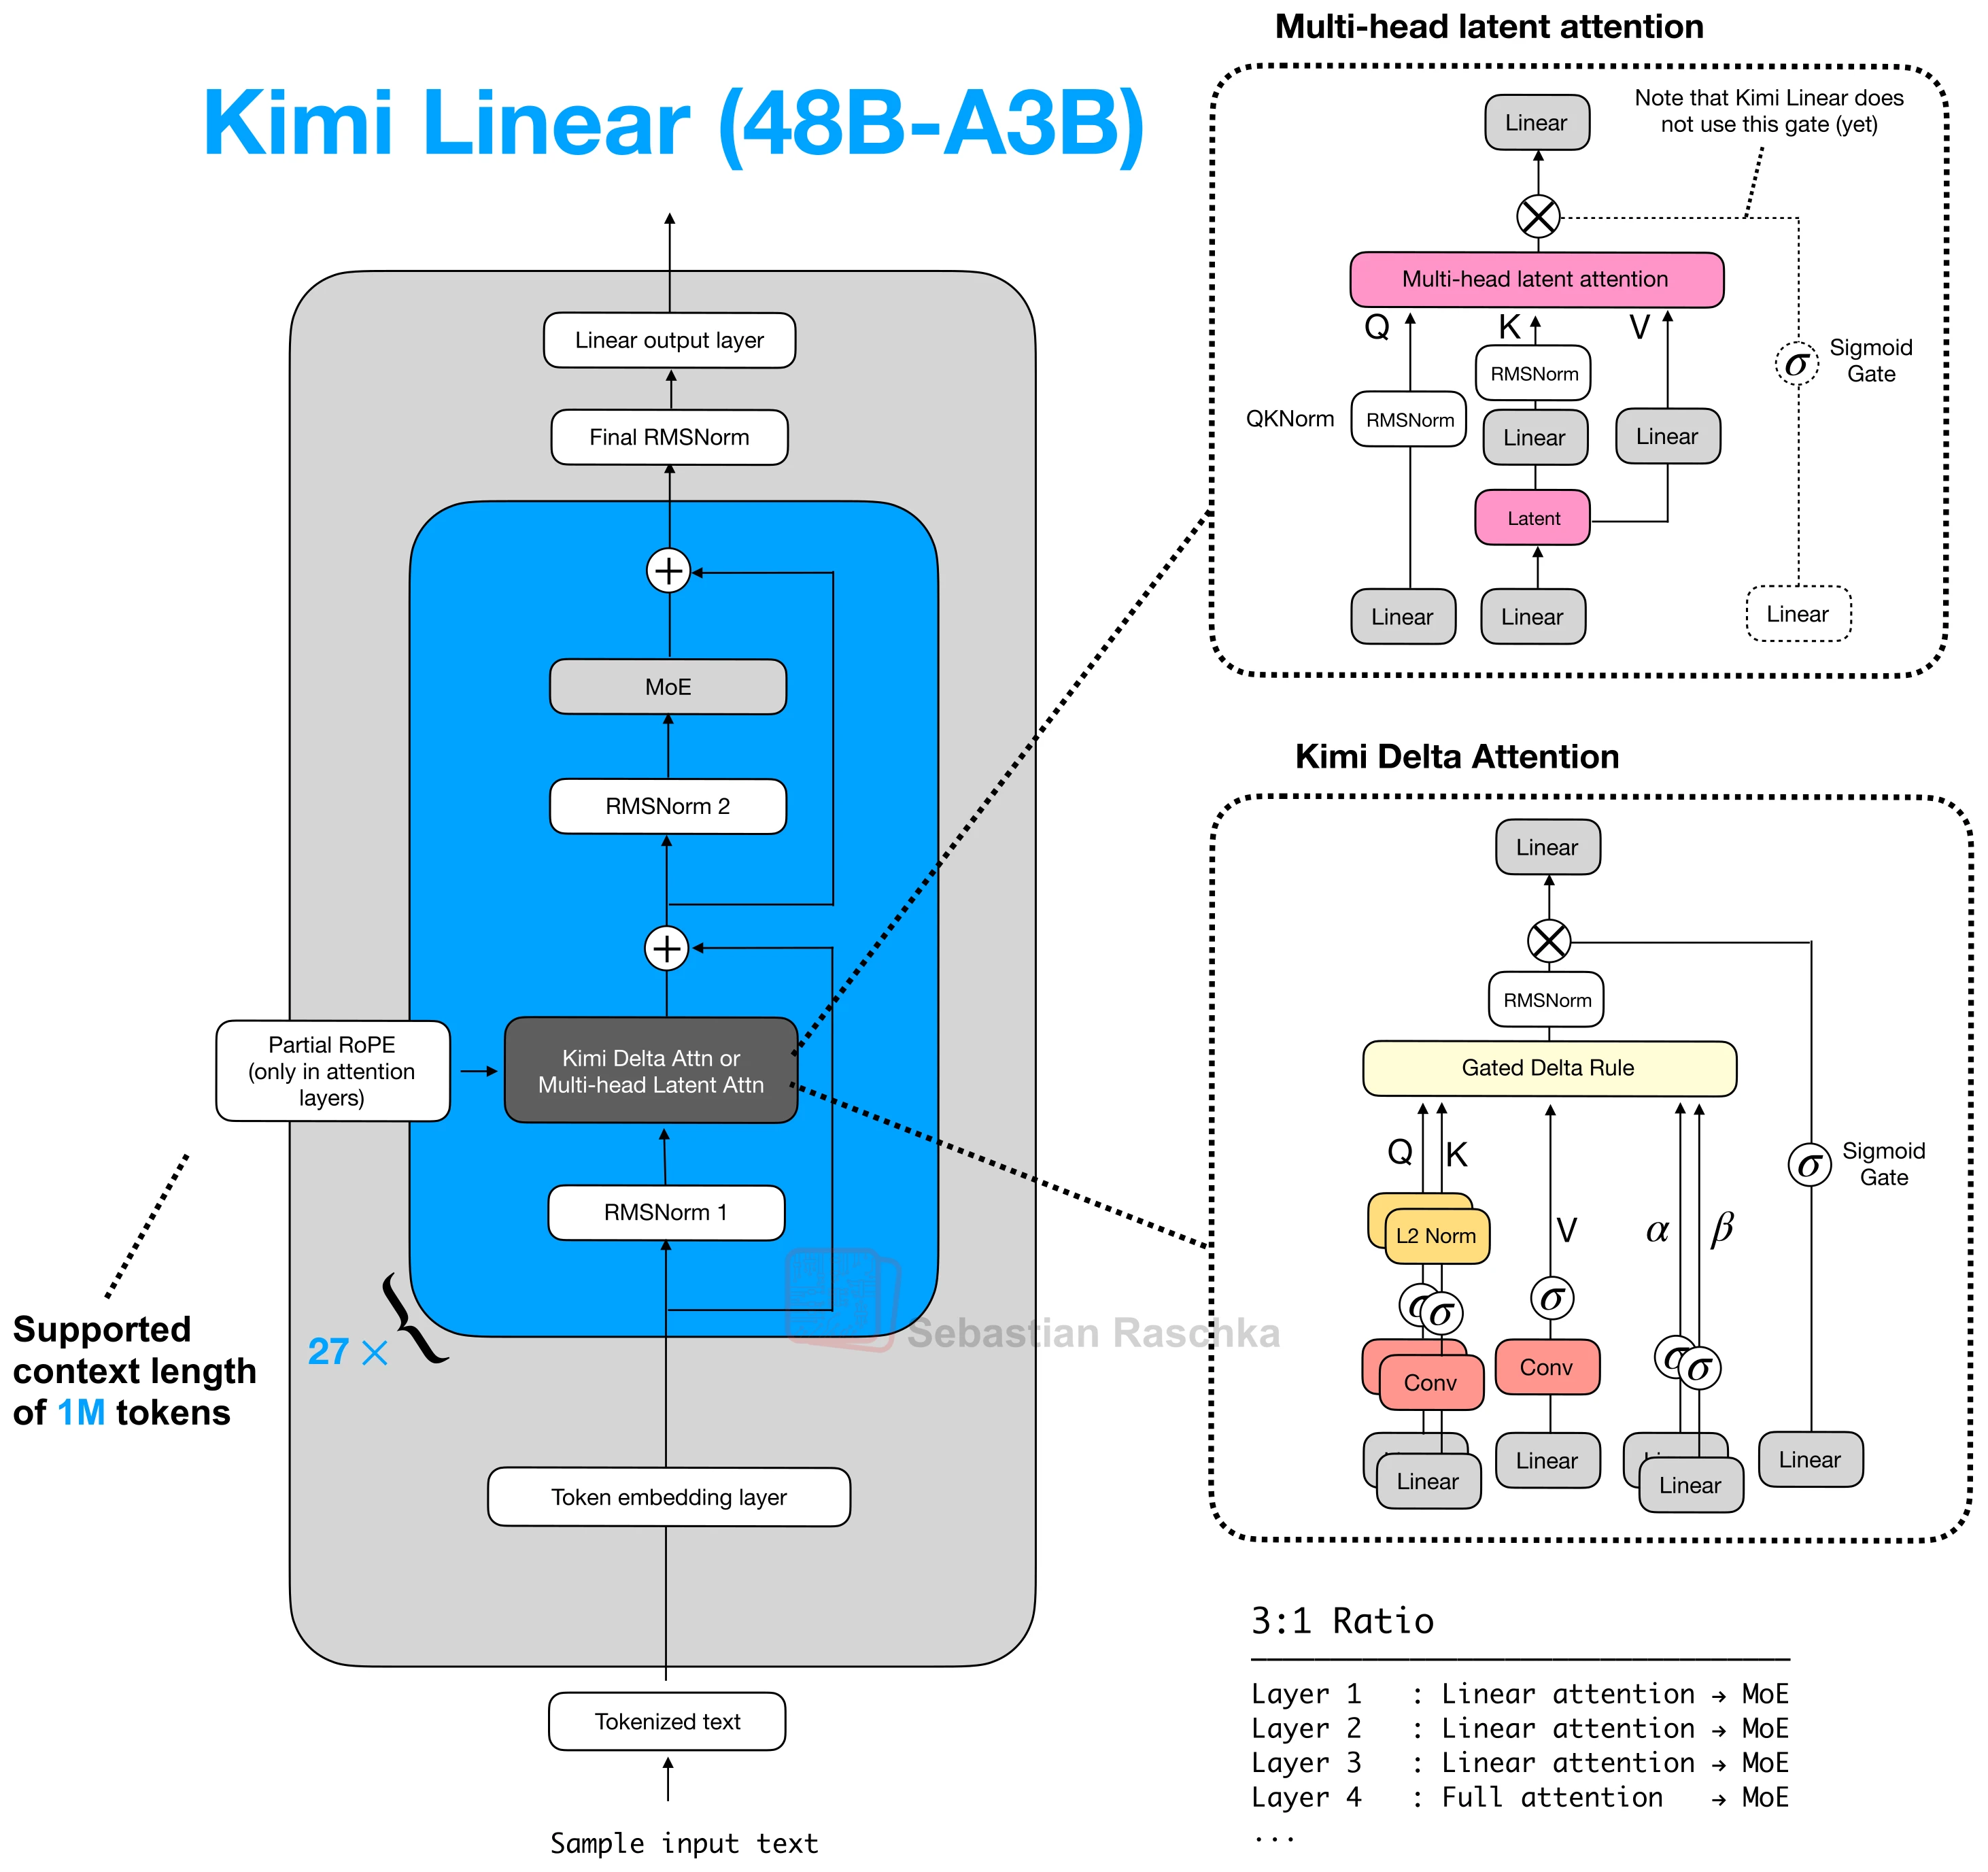
Linear-attention hybrid that keeps a transformer backbone but replaces most full-attention layers.
Architecture and specifications
- Scale
- 48B total, 3B active (6.3% active)
- Context (tokens)
- 1,048,576
- License
- MIT License
- Date
- 2025-10-30
- Decoder type
- Sparse hybrid
- Attention
- 3:1 Kimi Delta Attention and MLA
- Layer mix
- 7 MLA + 20 Kimi Delta Attention
- KV cache / token (bf16) info
- 7.9 KiB · Very low
- Key detail
- The 20 KDA layers use channel-wise gating and kernel-4 ShortConv on Q, K, and V. The 7 MLA layers normalize the compressed KV latent and use NoPE. The decoder adds a residual after each sequence mixer and each MoE.
Training and benchmarks
- Pretraining data
- 5.7T tokens Budget for the final released checkpoint; the report's 1.4T-token runs are architecture comparisons. Technical report
- Post-training methods
- SFT, RL The Instruct variant uses multi-stage SFT followed by RL on math, code, and STEM tasks, with concurrent supervised training to preserve general capabilities. Technical report