
GLM-5.2 Architecture
Back to GLM-5.2 in the gallery
Z.ai
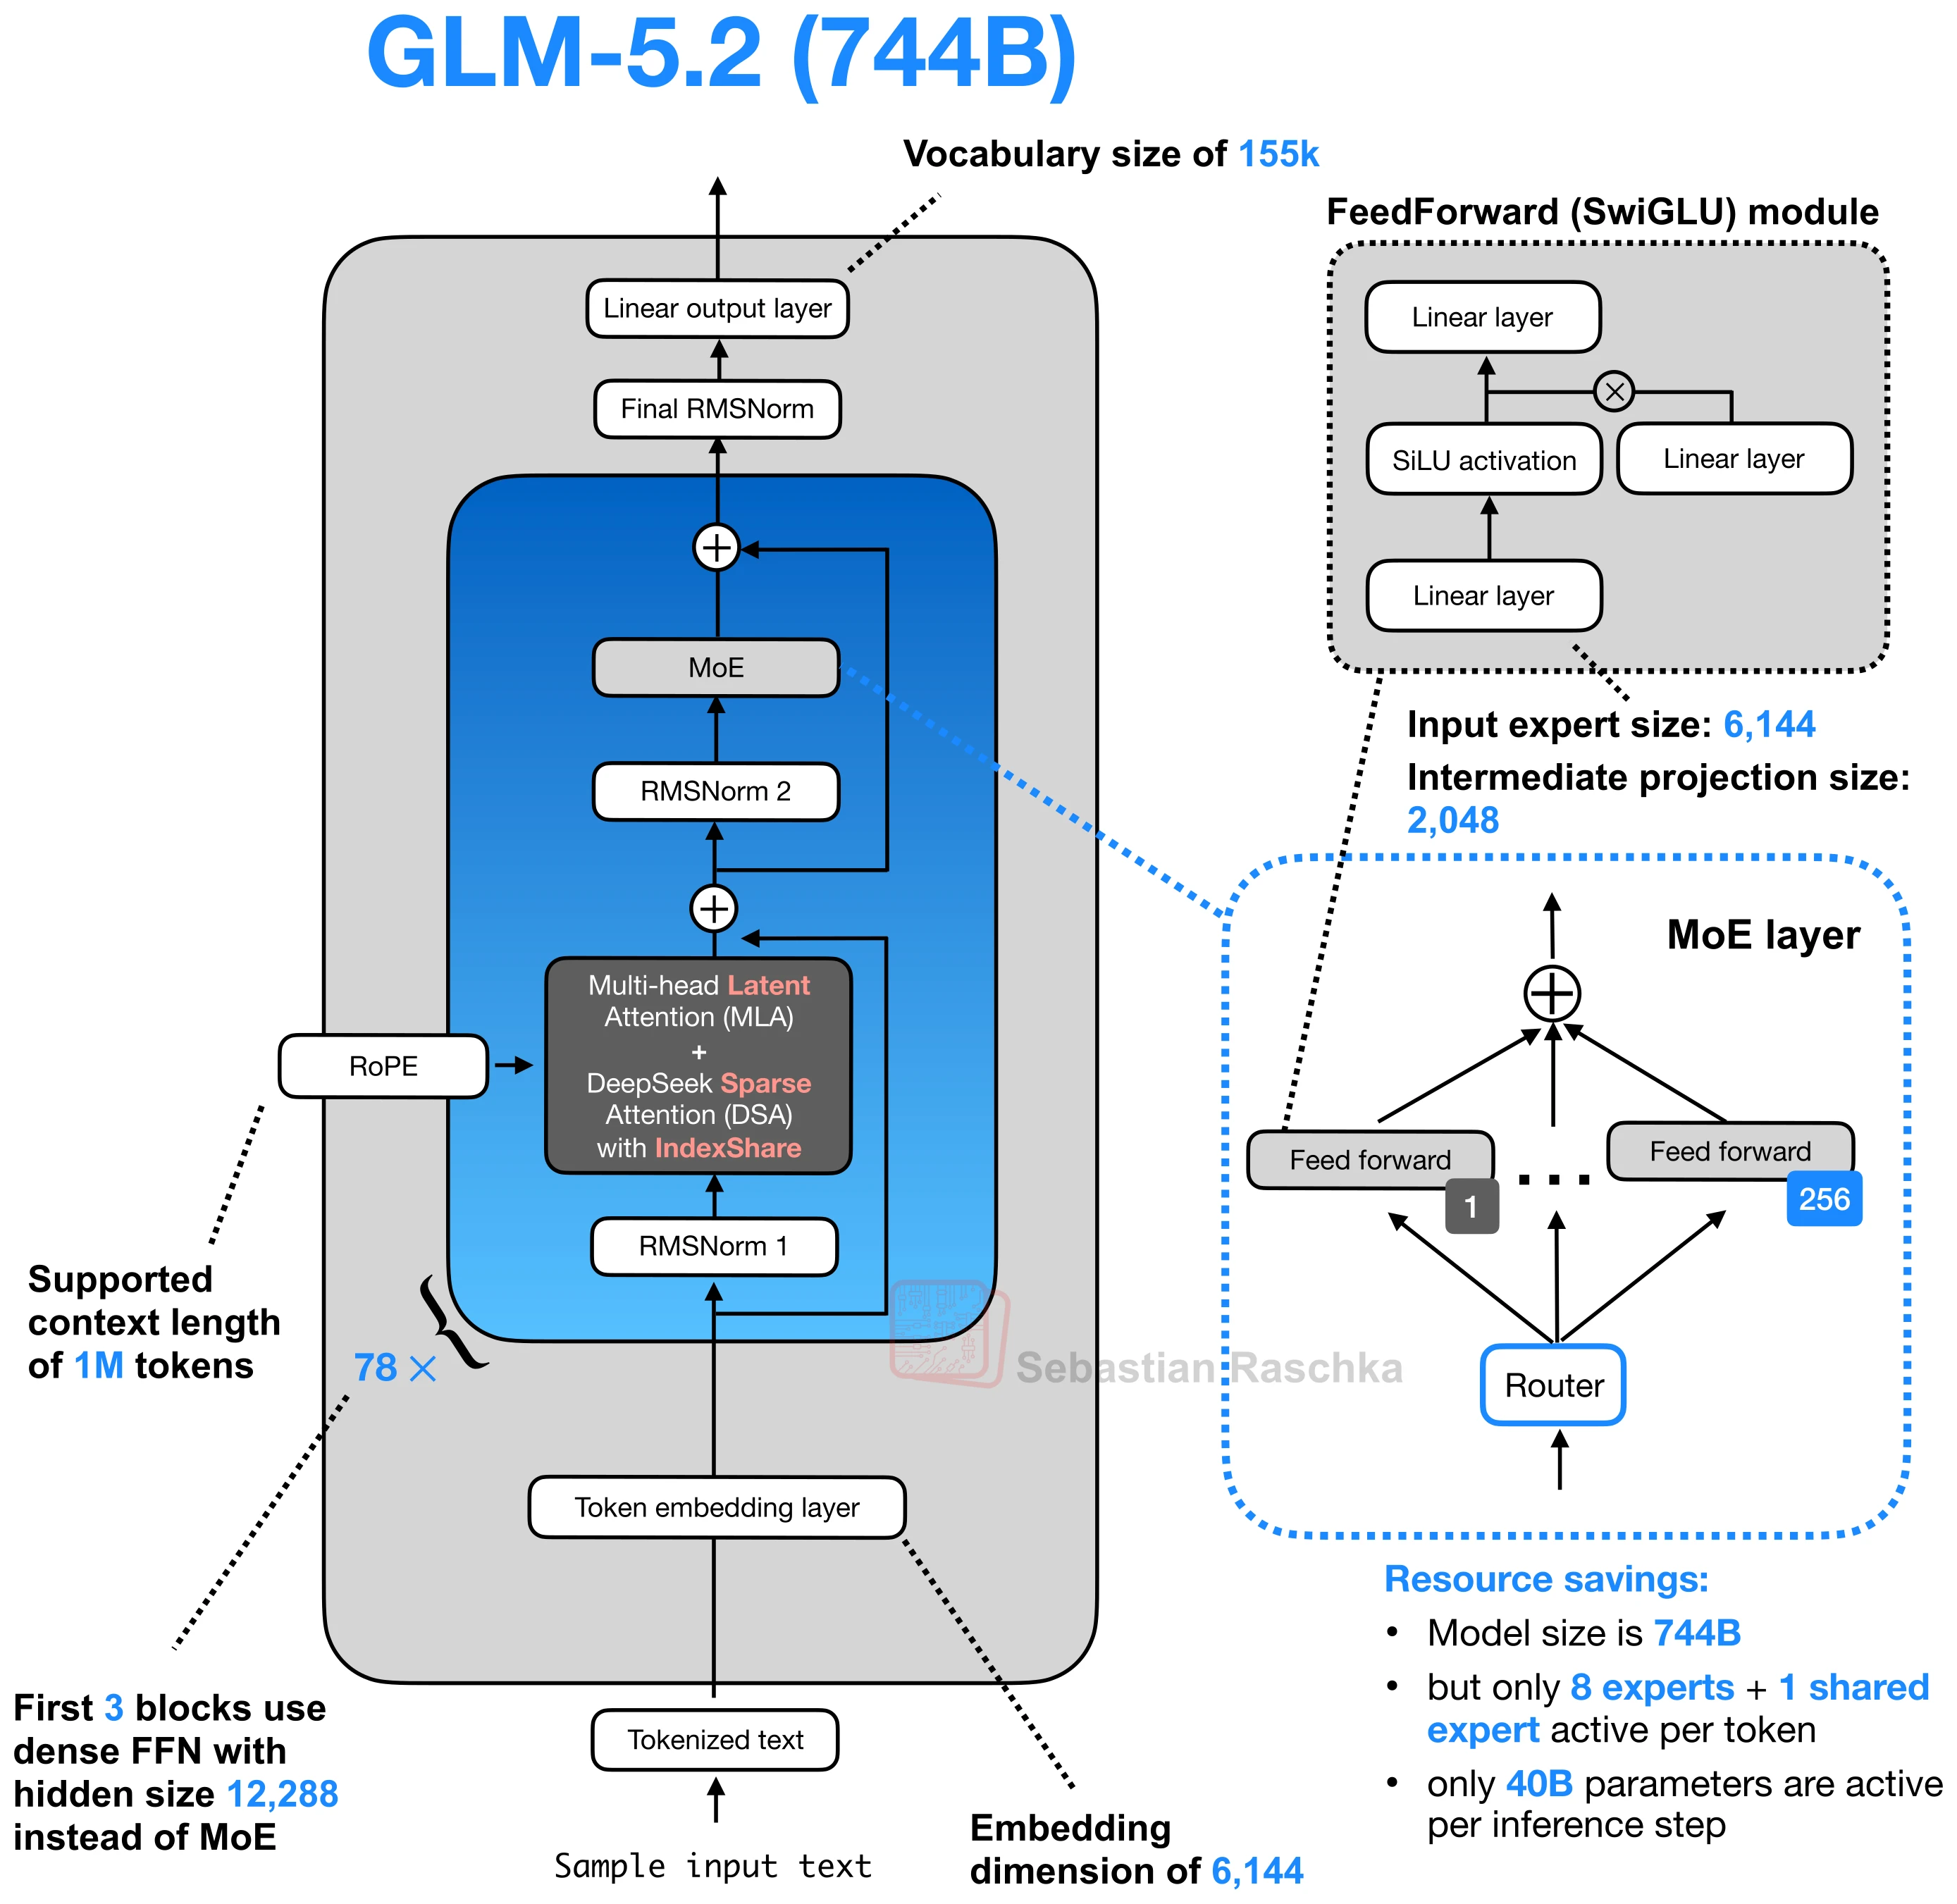
Long-context GLM refresh that keeps the 744B sparse MoE backbone and adds IndexShare for 1M-token DSA inference.
Architecture and specifications
- Scale
- 744B total, 40B active (5.4% active)
- Context (tokens)
- 1,048,576
- License
- MIT License
- Date
- 2026-06-17
- Decoder type
- Sparse MoE
- Attention
- MLA with DeepSeek Sparse Attention and IndexShare
- Layer mix
- 78 MLA/DSA
- KV cache / token (bf16) info
- 93 KiB · Moderate
- Key detail
- Reuses each full DSA indexer result across the next three layers, making 1M-token sparse attention cheaper.
Training and benchmarks
- Pretraining data
- Not disclosed The model card does not publish a pretraining-token total for this version. GLM-5.2 model card
- Post-training methods
- RL, Distillation Agentic RL includes PPO-based CompactionRL. Parallel on-policy distillation merges more than ten expert models. CompactionRL report · GLM-5.2 release