
Dory1.0 4B Architecture
Back to Dory1.0 4B in the gallery
NVIDIA
NVIDIA's dense looped transformer applies a shared 20-block core twice between 8-block input and output stacks, using normalized GPT (nGPT) residual updates.
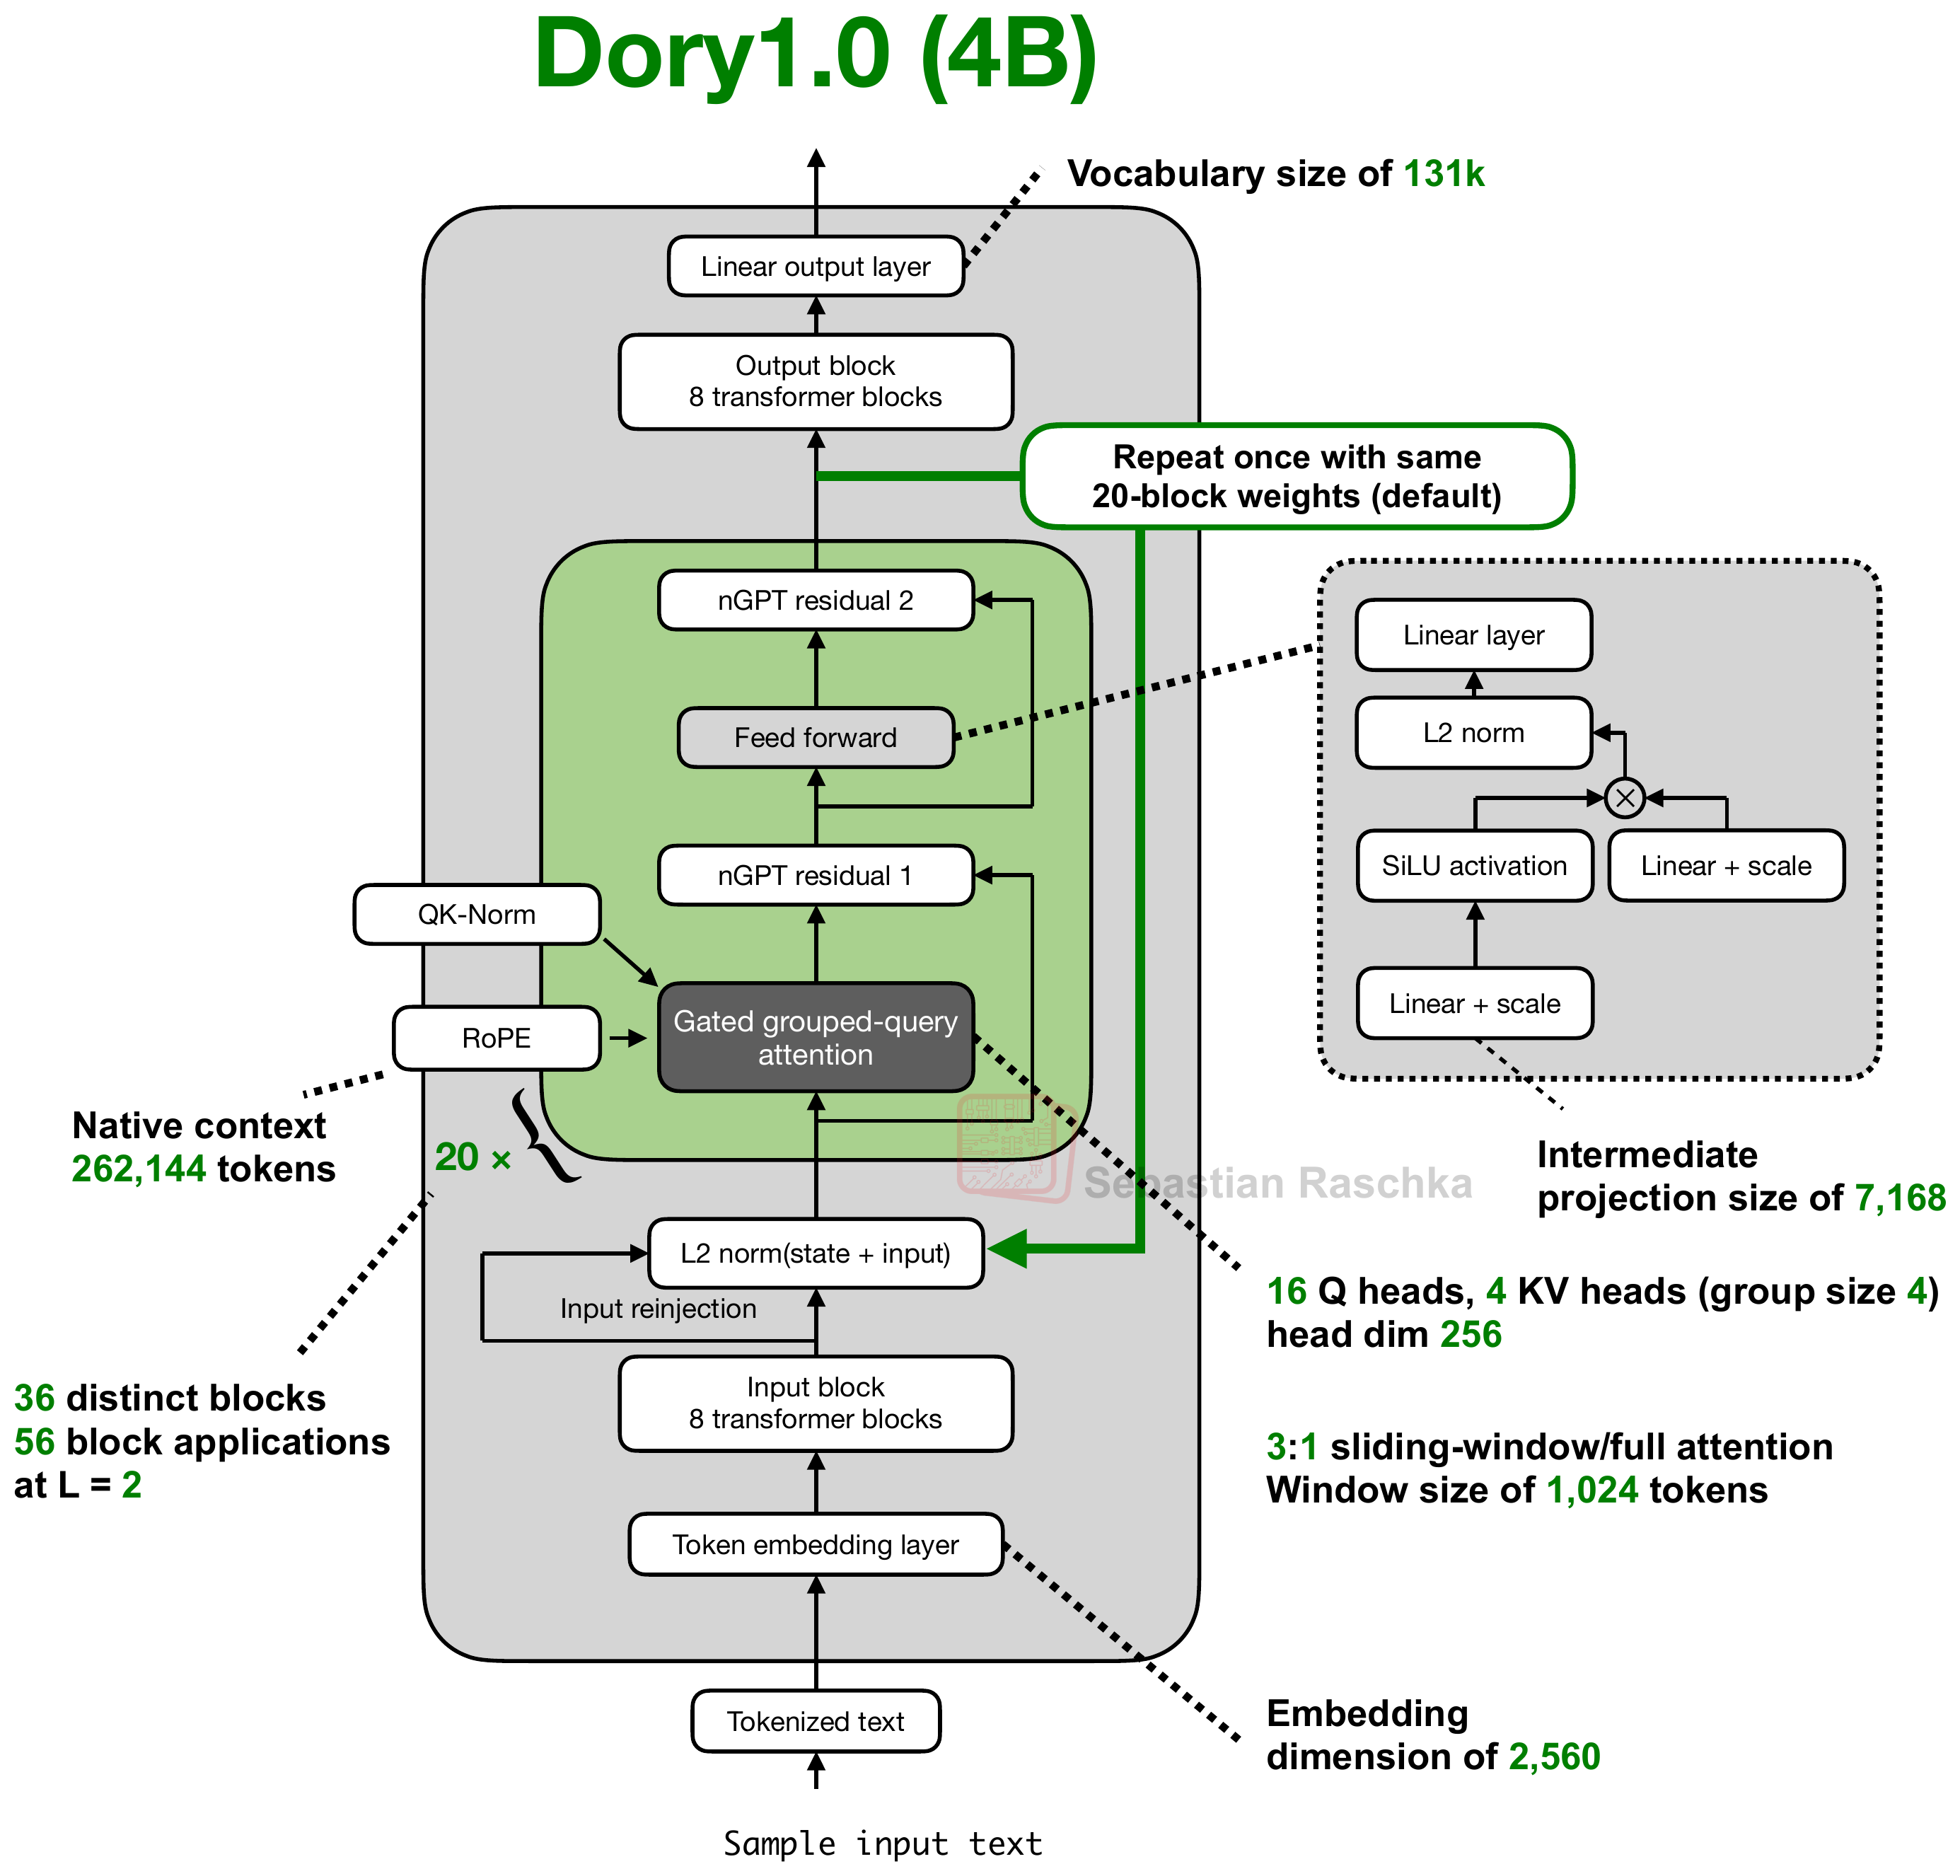
Architecture and specifications
- Scale
- 4B parameters
- Context (tokens)
- 262,144
- Vocabulary
- 131,072 (~131k)
- License
- OpenMDW 1.1
- Date
- 2026-10-16
- Decoder type
- Dense
- Attention
- Gated GQA; 3:1 sliding-window/full, RoPE
- Layer mix
- 8 input + 20 shared × 2 passes + 8 output (56 applications)
- KV cache / token (bf16) info
- 224 KiB · High
- Key detail
- Reinjects the input-stack output before each recurrent pass. The 36 distinct blocks give 56 block applications by default, with L2-normalized residual updates and a 1,024-token attention window.
Training and benchmarks
- Pretraining data
- 6T tokens + 300B context-extension tokens The model card reports pretraining and context extension separately. Dory 1.0 model card
- Post-training methods
- SFT, RL, Distillation SFT uses teacher-generated data, followed by multi-environment GRPO for reasoning, coding, tool use, and instruction following. Dory 1.0 model card