
DeepSeek V3 Architecture
Back to DeepSeek V3 in the gallery
DeepSeek
DeepSeek's flagship template kicked off the recent wave of large open MoE models.
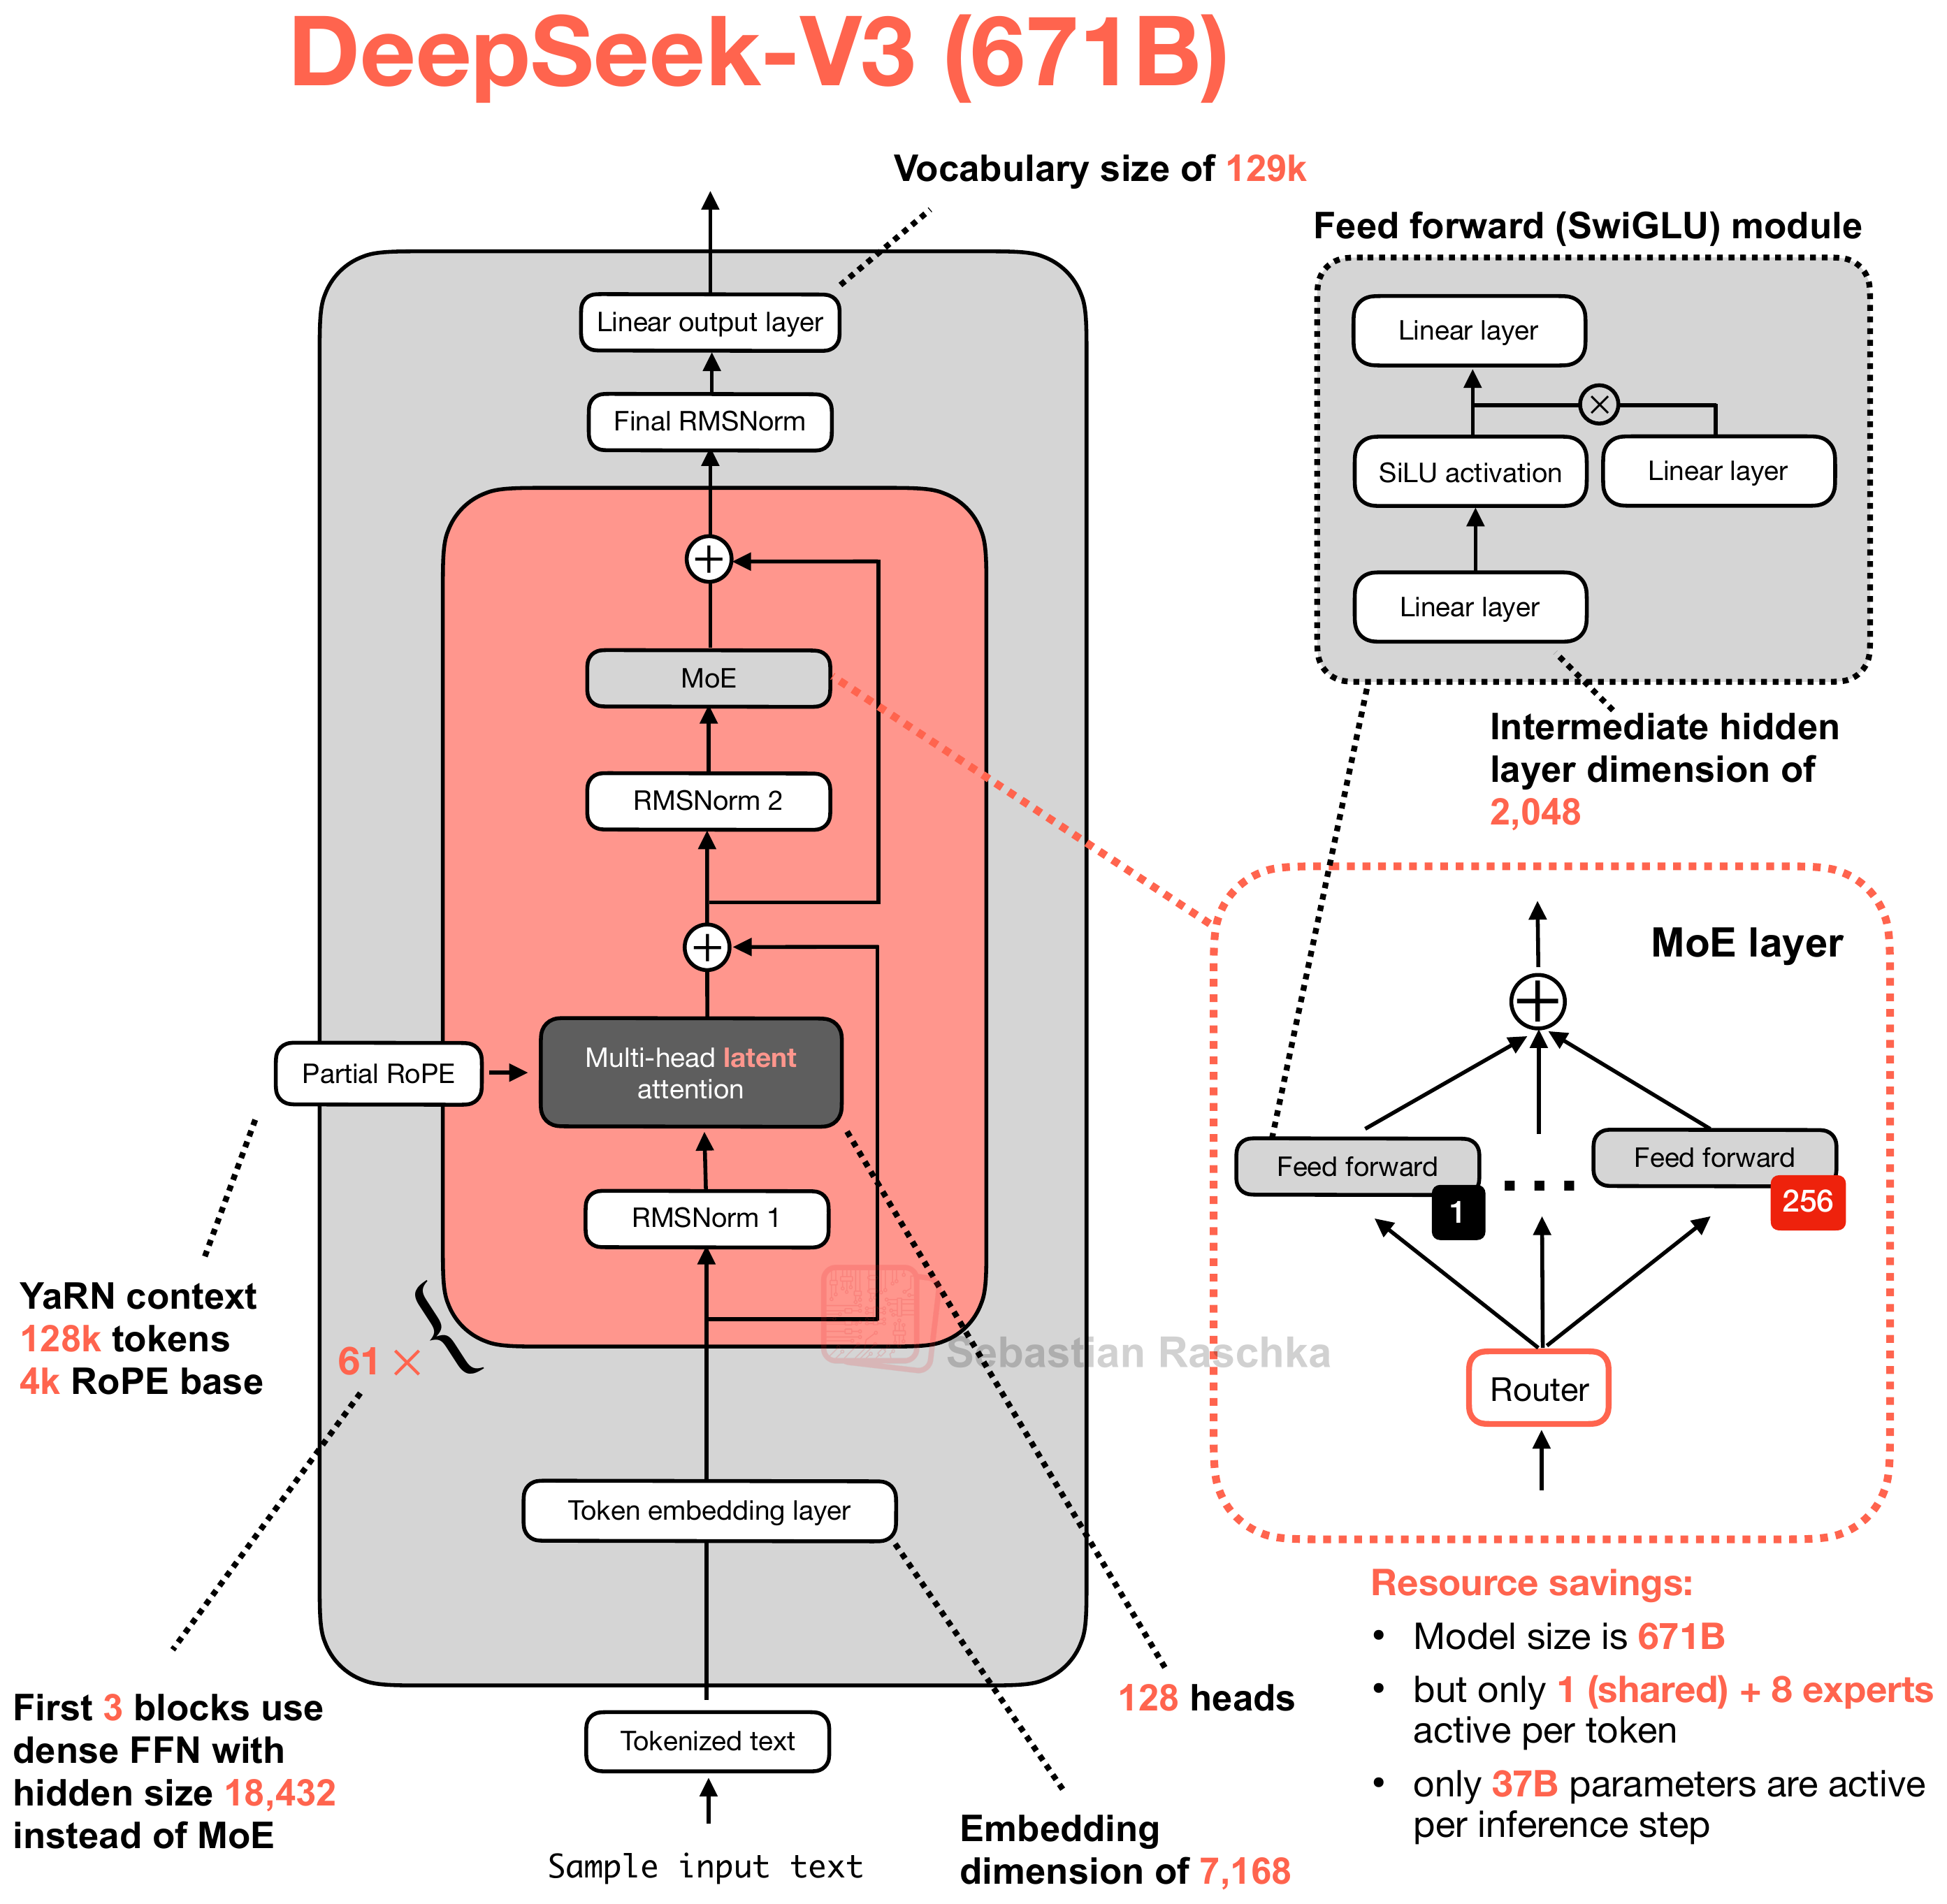
Architecture and specifications
- Scale
- 671B total, 37B active (5.5% active)
- Context (tokens)
- 128,000
- License
- DeepSeek License Agreement v1.0
- Date
- 2024-12-26
- Decoder type
- Sparse MoE
- Attention
- MLA
- Layer mix
- 61 MLA
- KV cache / token (bf16) info
- 68.6 KiB · Low
- Key detail
- Uses a dense prefix, shared expert, and MTP-1 objective to keep a very large model practical.
Training and benchmarks
- Pretraining data
- 14.8T tokens Base pretraining budget, before post-training. DeepSeek V3 report
- Post-training methods
- SFT, RLVR, RL, Distillation SFT includes R1-generated reasoning data. GRPO combines rule-based math/code rewards with learned reward models. DeepSeek V3 report