
Datology XL 30B-A3B Architecture
Back to Datology XL 30B-A3B in the gallery
DatologyAI
Qwen3-style research model, included for its excellent technical report on data curation, optimization, and controlled training experiments.
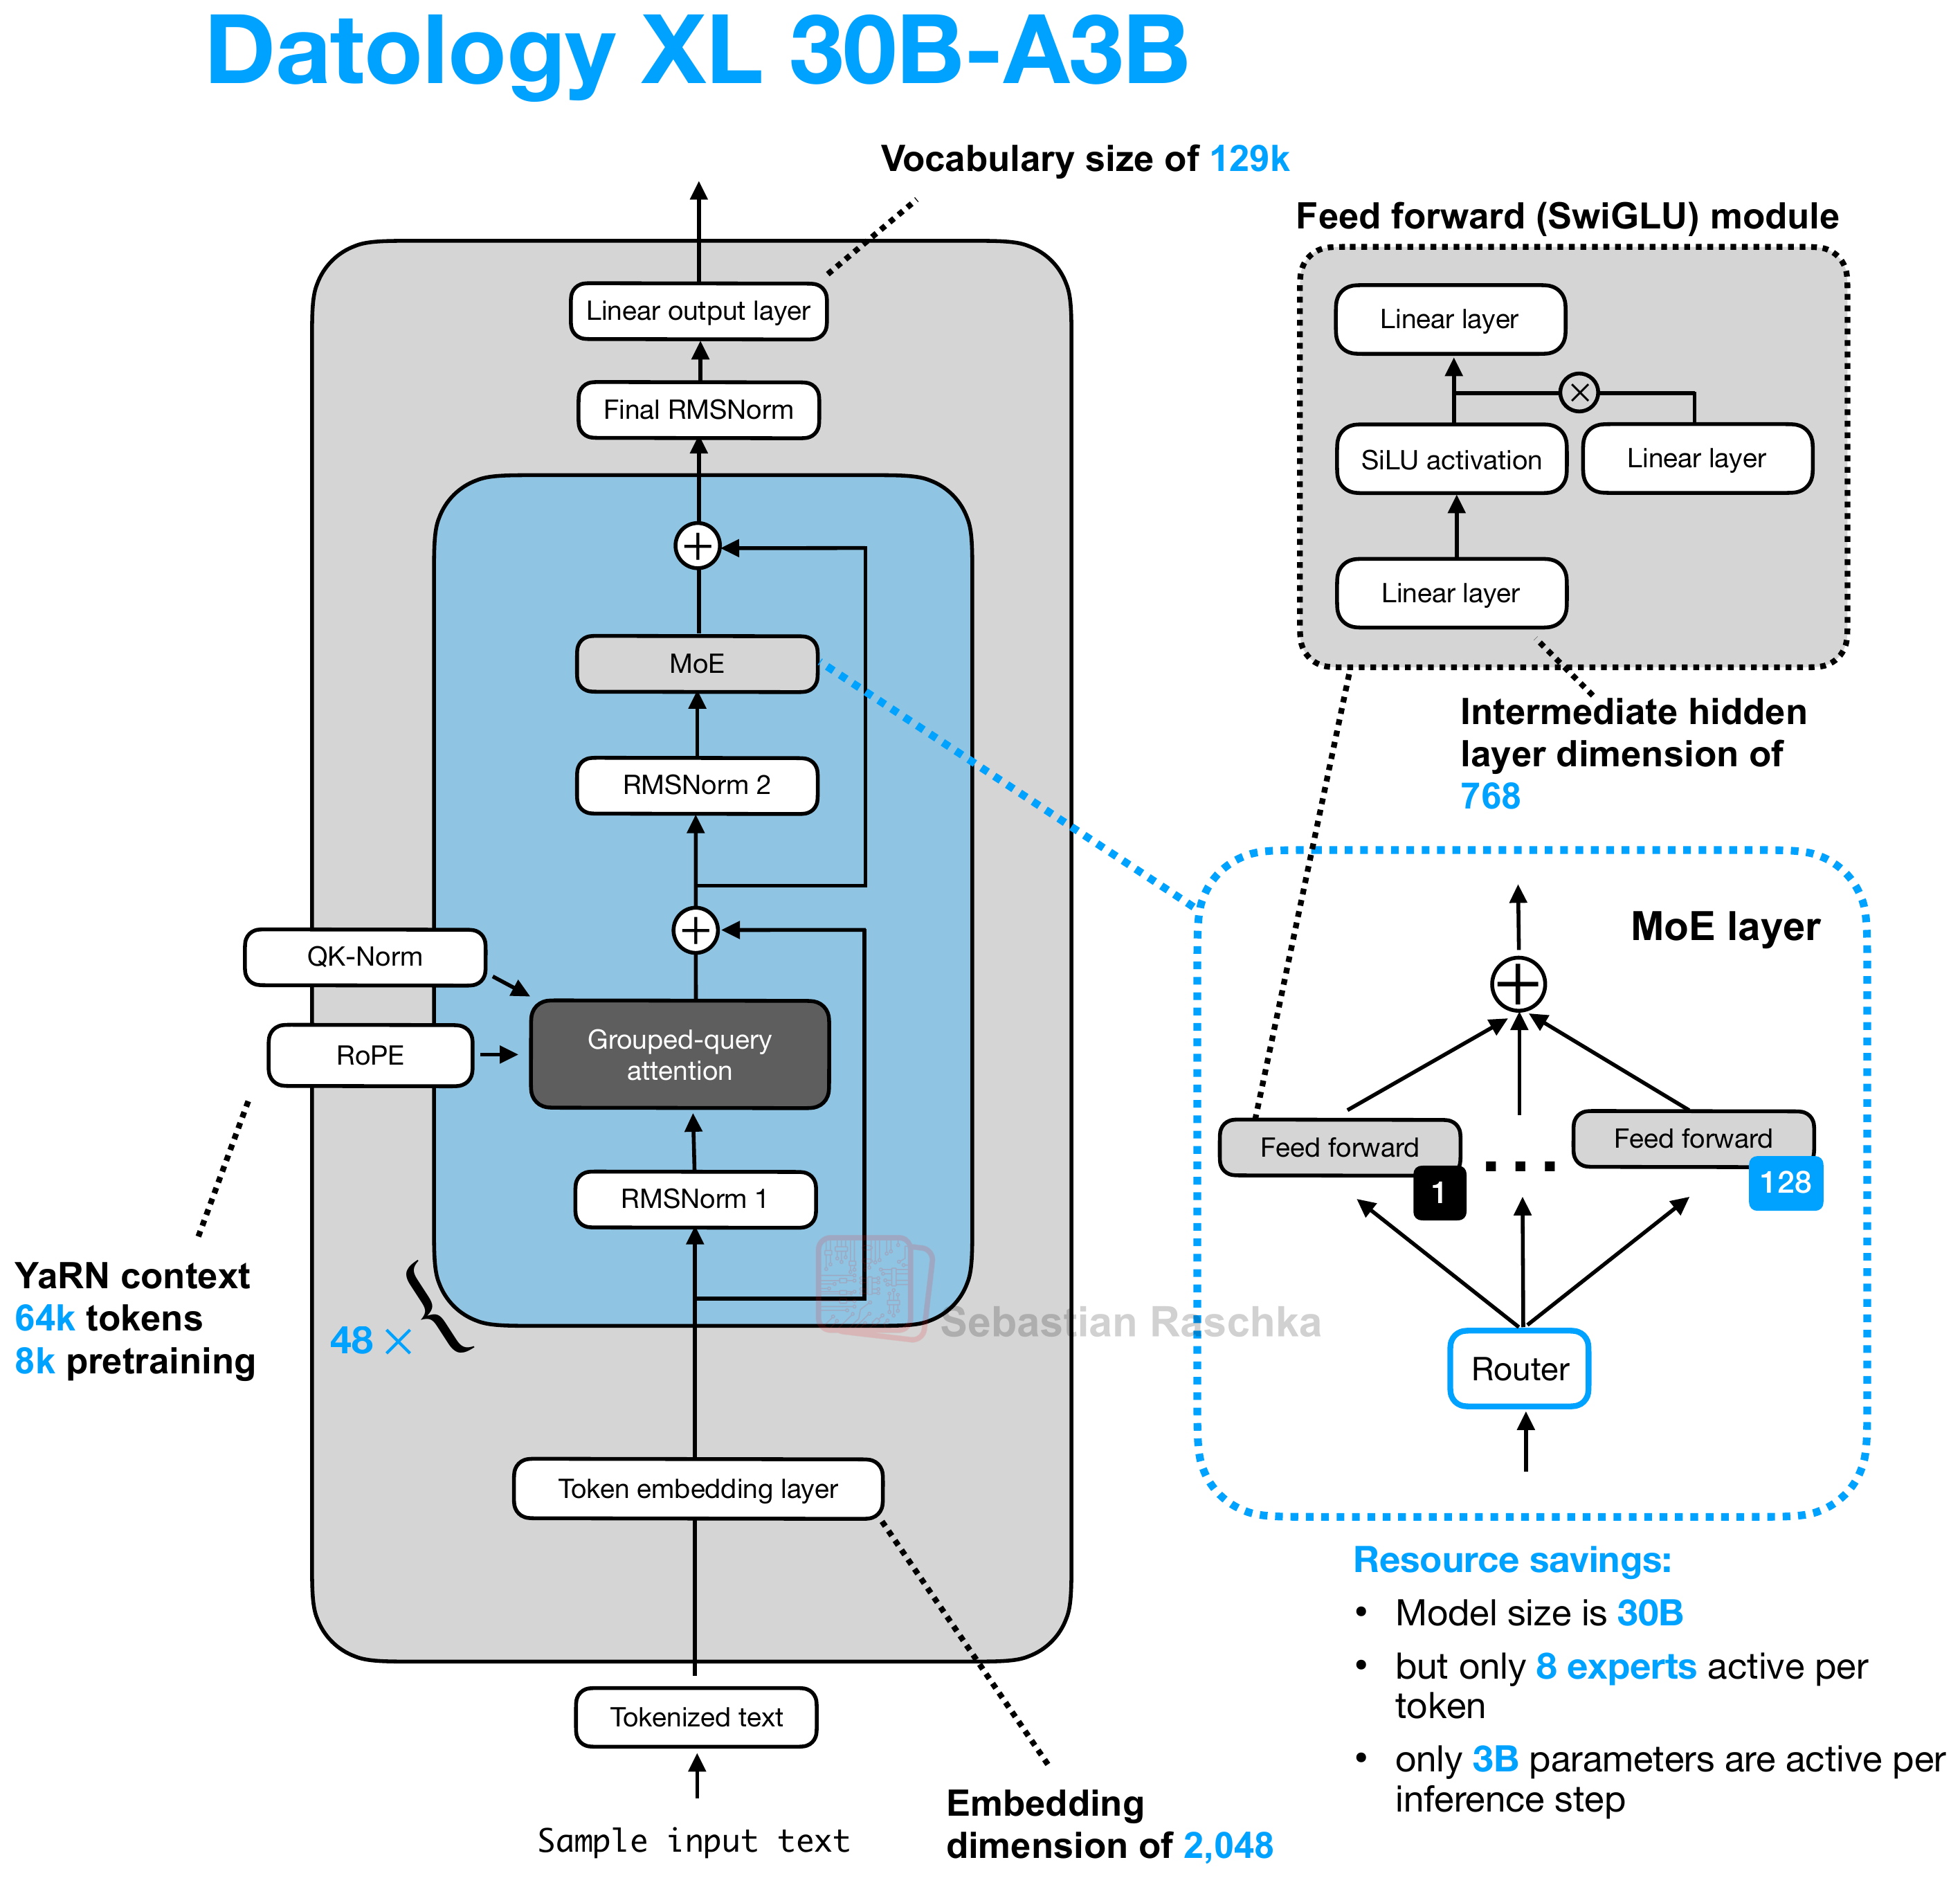
Architecture and specifications
- Scale
- 30.4B total, 3.26B active (10.7% active)
- Context (tokens)
- 65,536
- Vocabulary
- 129,280 (~129k)
- License
- N/A
- Date
- 2026-11-16
- Decoder type
- Sparse MoE
- Attention
- GQA with QK-Norm and RoPE
- Layer mix
- 48 GQA
- KV cache / token (bf16) info
- 96 KiB · Moderate
- Key detail
- Uses Qwen3-30B-A3B's 48-layer backbone with 8 of 128 experts active per token, the DeepSeek V4 tokenizer, and AdamH optimization with explicit weight-norm constraints.
Training and benchmarks
- Pretraining data
- 1T tokens XL curated model, pretrained from scratch on Datology-curated data. A further 10B tokens extend context from 8k to 64k. All token counts use the DeepSeek V4 tokenizer. Datology technical report
- Post-training methods
- SFT, RLVR, Model merging About 20B SFT tokens, followed by four GRPO specialists for mathematics, code, instruction following, and tool use. The specialists are merged into one model. Datology technical report