
LongCat-Flash-Lite 68.5B-A3B Architecture
Back to LongCat-Flash-Lite 68.5B-A3B in the gallery
Meituan
Meituan's LongCat-Next text backbone is a lightweight MoE that shifts a large share of parameters into N-gram embeddings while keeping sparse inference around 3B active parameters.
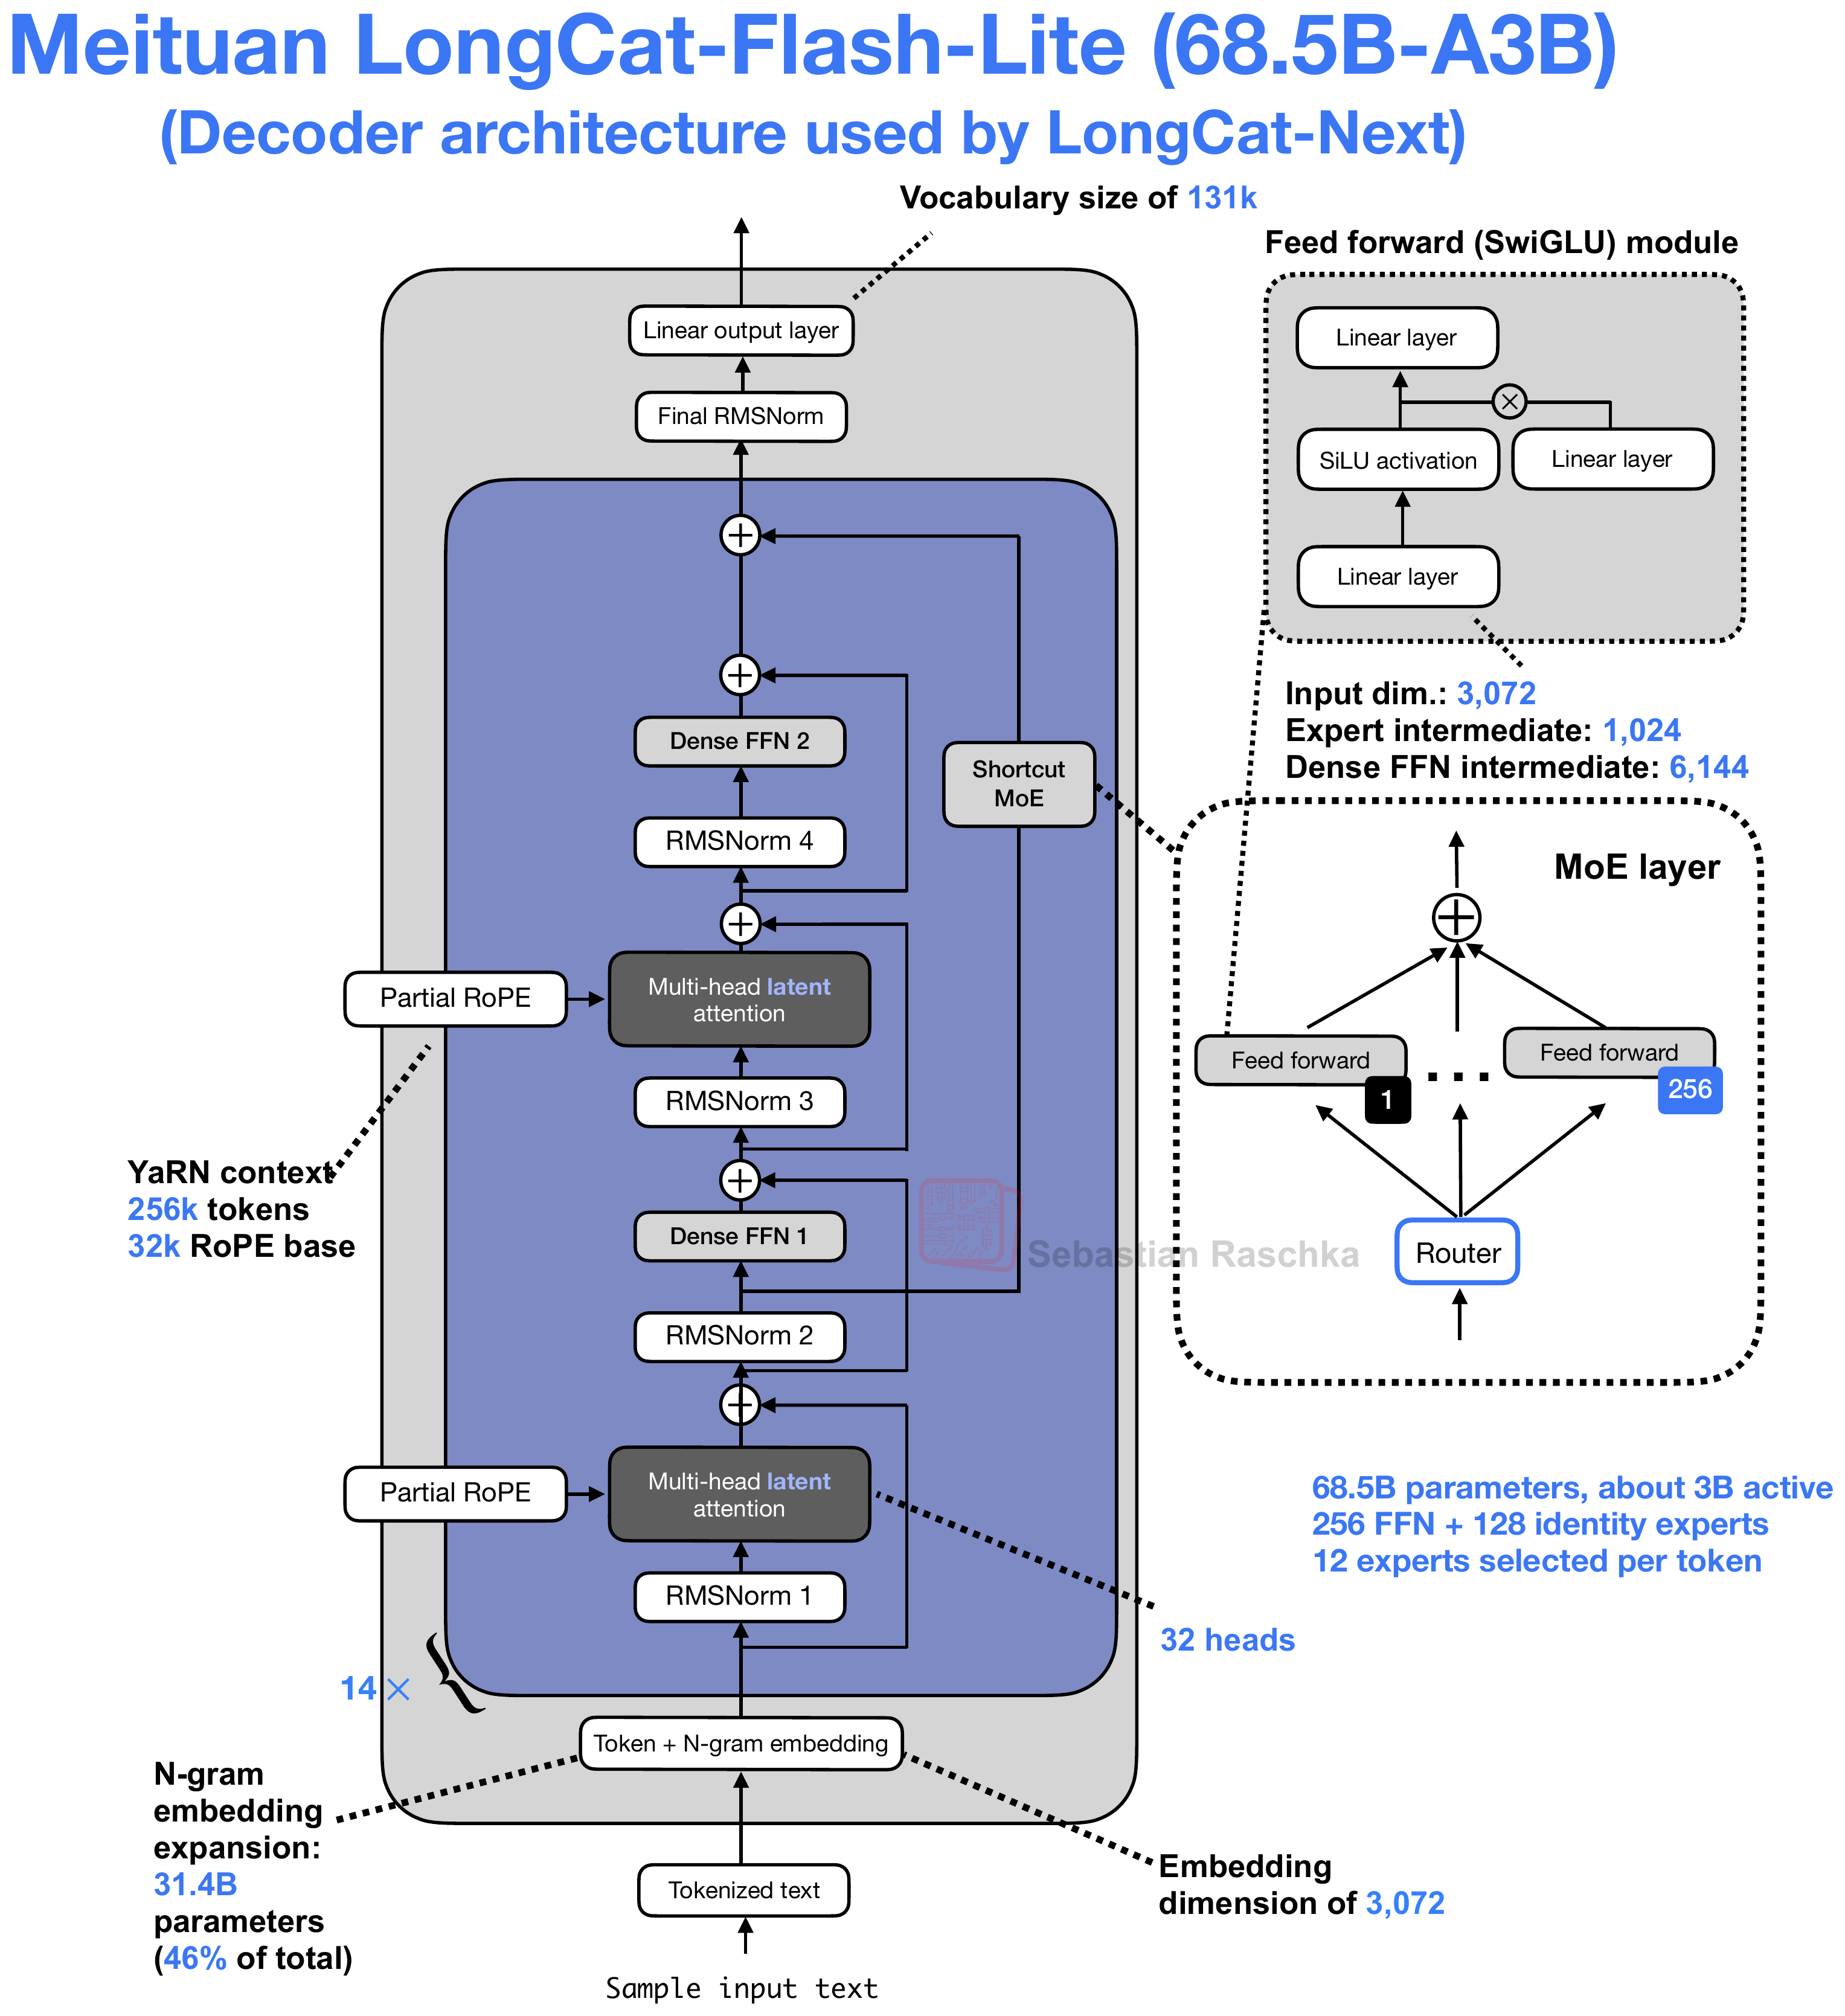
Architecture and specifications
- Scale
- 68.5B total, ~3B active avg (4.4% active)
- Context (tokens)
- 256,000
- Vocabulary
- 131,072
- License
- MIT License
- Date
- 2026-01-28
- Decoder type
- Sparse MoE
- Attention
- MLA with RoPE + NoPE
- Layer mix
- 14 logical layers / 28 MLA sublayers
- KV cache / token (bf16) info
- 31.5 KiB · Low
- Key detail
- Uses N-gram embedding expansion, Shortcut MoE routing over 256 routed plus 128 zero/identity experts, and top-k 12 expert choices per token.
Training and benchmarks
- Pretraining data
- 11T + 1.5T midtraining tokens 11T tokens of initial pretraining are followed by 1.5T tokens of midtraining and context extension, for 12.5T before SFT. Technical report
- Post-training methods
- SFT The report states that the released chat model is supervised fine-tuned after pretraining and midtraining. Technical report