
LFM2.5 1.2B Architecture
Back to LFM2.5 1.2B in the gallery
Liquid AI
Liquid AI's 1.2B LFM2.5 model keeps the 16-layer hybrid LIV convolution and GQA stack at a wider hidden size.
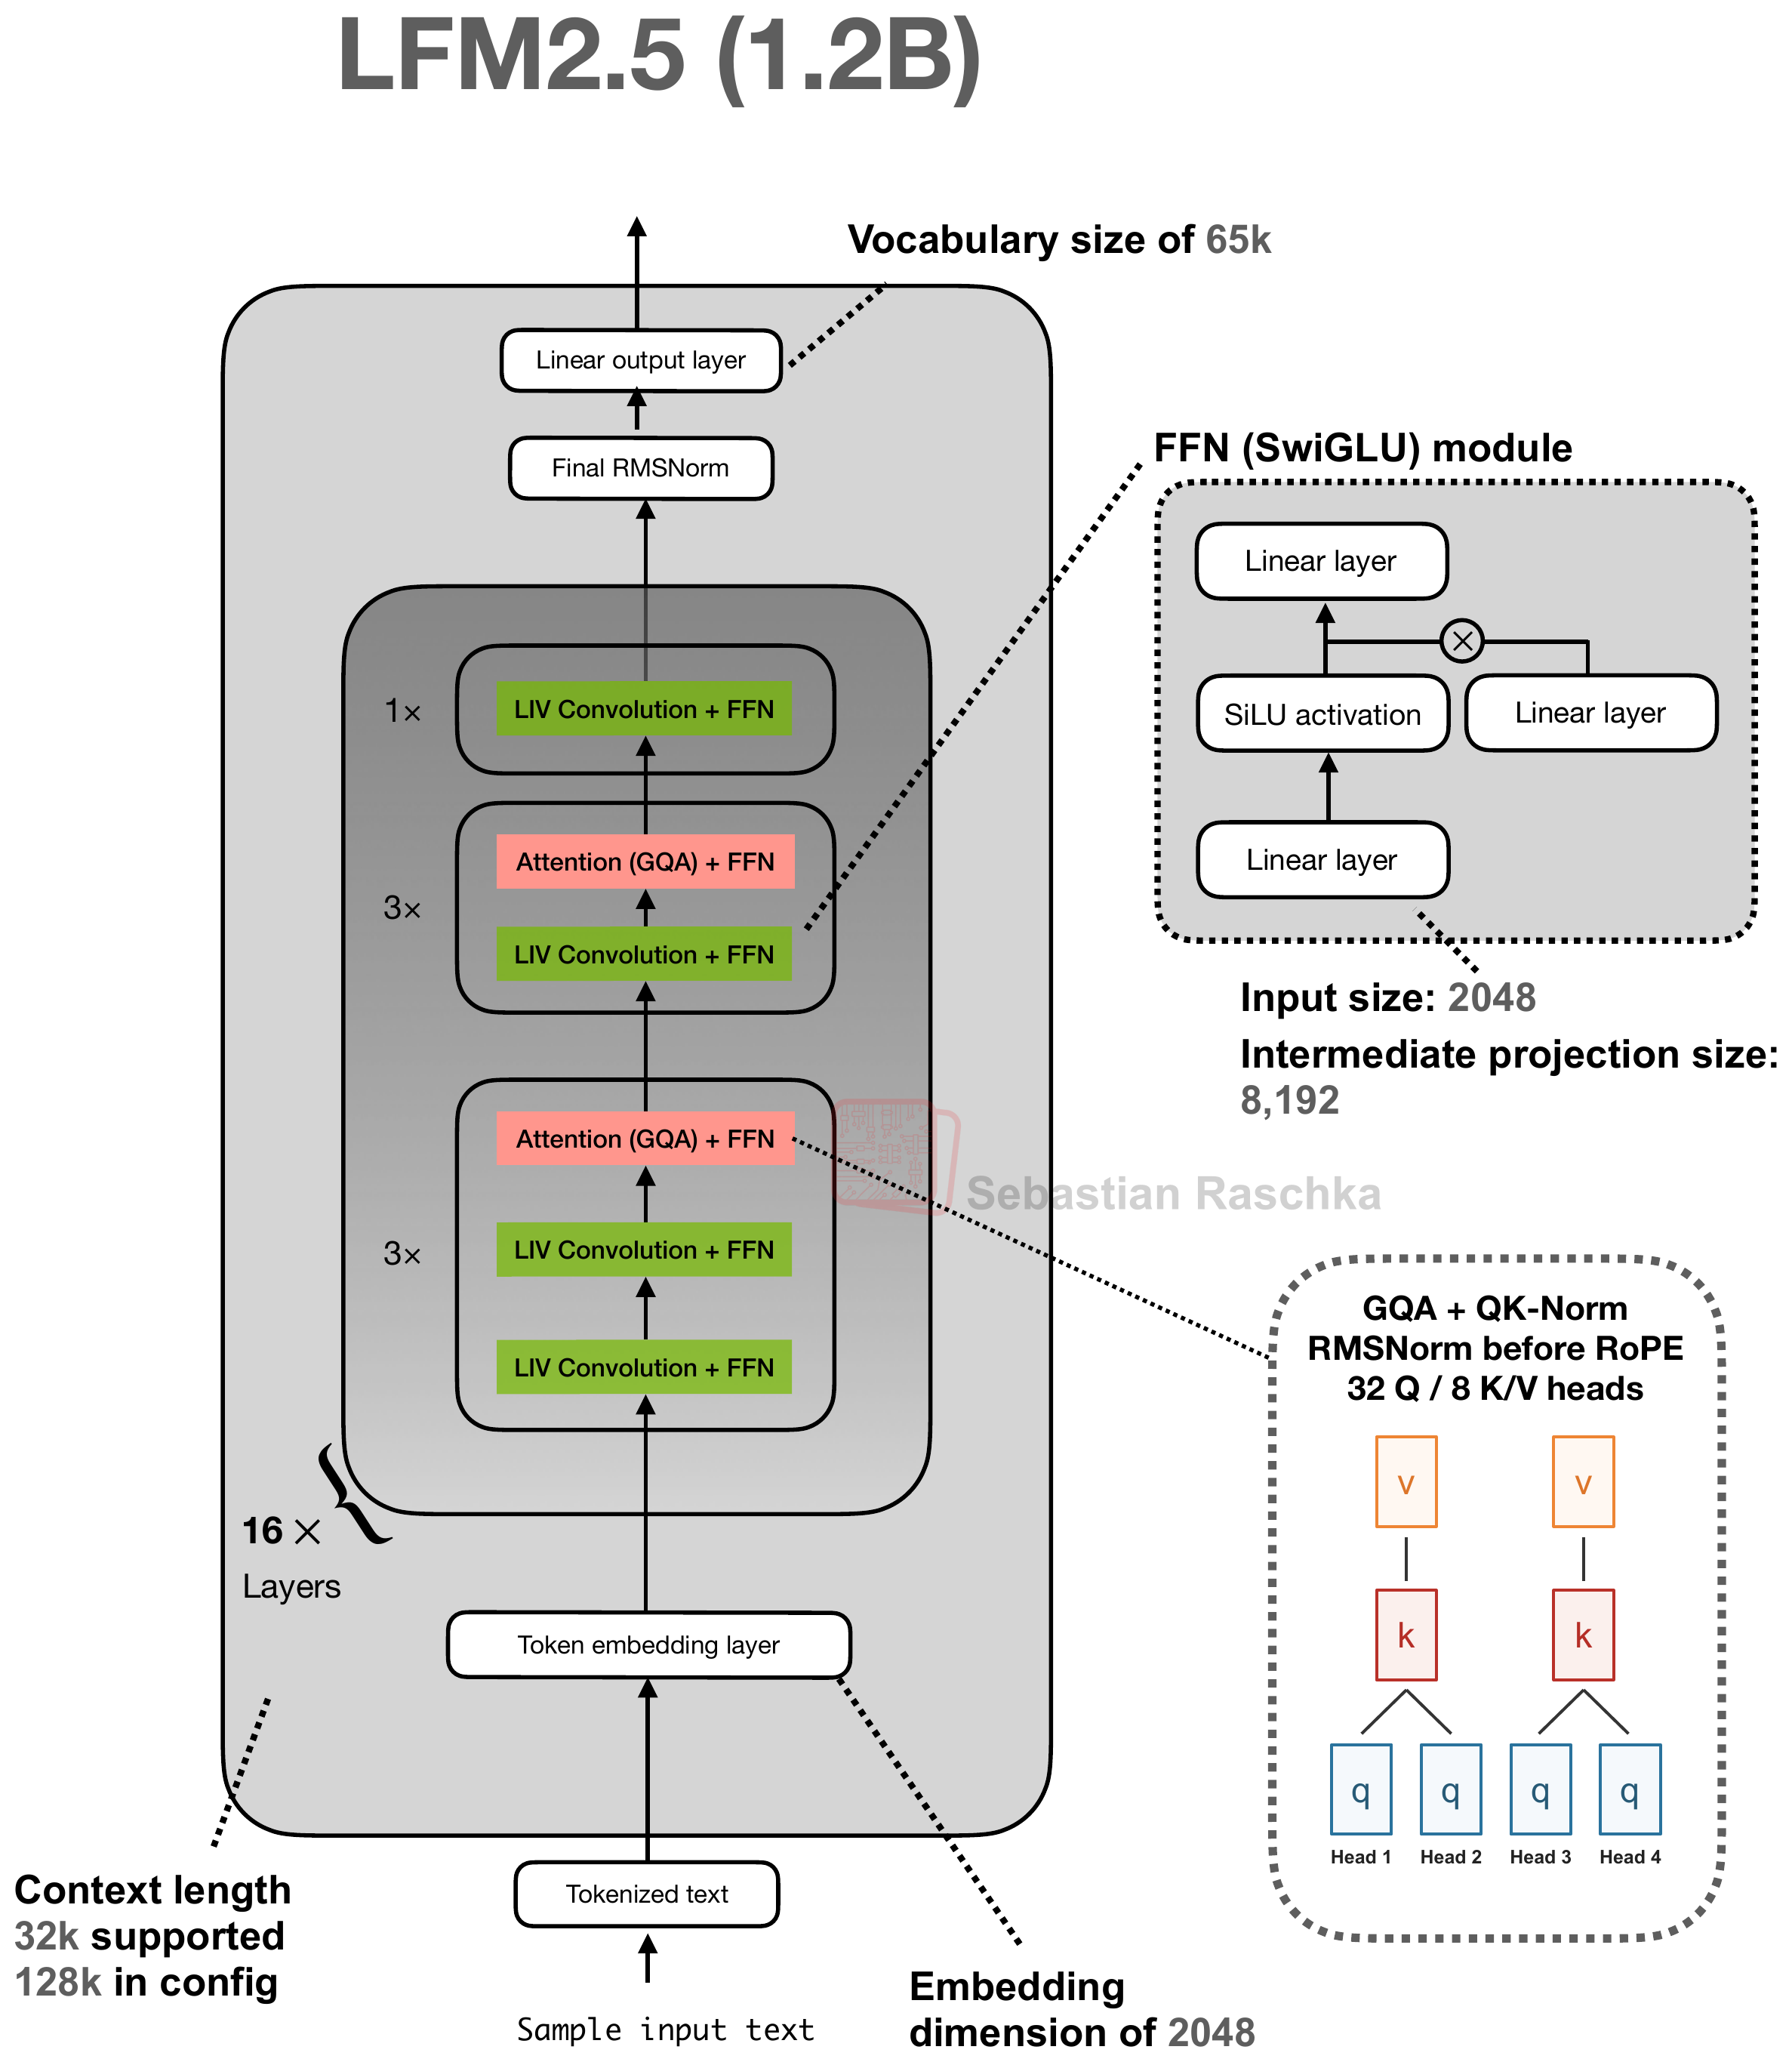
Architecture and specifications
- Scale
- 1.2B parameters
- Context (tokens)
- 32,768
- Vocabulary
- 65,536 (~65k)
- License
- LFM Open License v1.0
- Date
- 2026-05-28
- Decoder type
- Dense hybrid
- Attention
- LIV convolution blocks plus GQA with QK-Norm
- Layer mix
- 10 LIV conv + 6 GQA
- KV cache / token (bf16) info
- 12 KiB · Very low
- Key detail
- GQA appears in layers 3, 6, 9, 11, 13, and 15 of the 16-layer stack. Its feed-forward intermediate width is 8,192.
Training and benchmarks
- Pretraining data
- 28T tokens Pretraining budget for the 1.2B base used by the Thinking checkpoint. Model card
- Post-training methods
- SFT, DPO, RLVR The Thinking variant uses SFT, DPO, and domain-specific RL with verifiable rewards; the final recipe also merges RL checkpoints. Release post