
Kimi K2.7 Code Architecture
Back to Kimi K2.7 Code in the gallery
Moonshot AI
Coding-focused K2.6 successor that keeps the same 1T sparse MoE text backbone and emphasizes long-horizon software engineering agents.
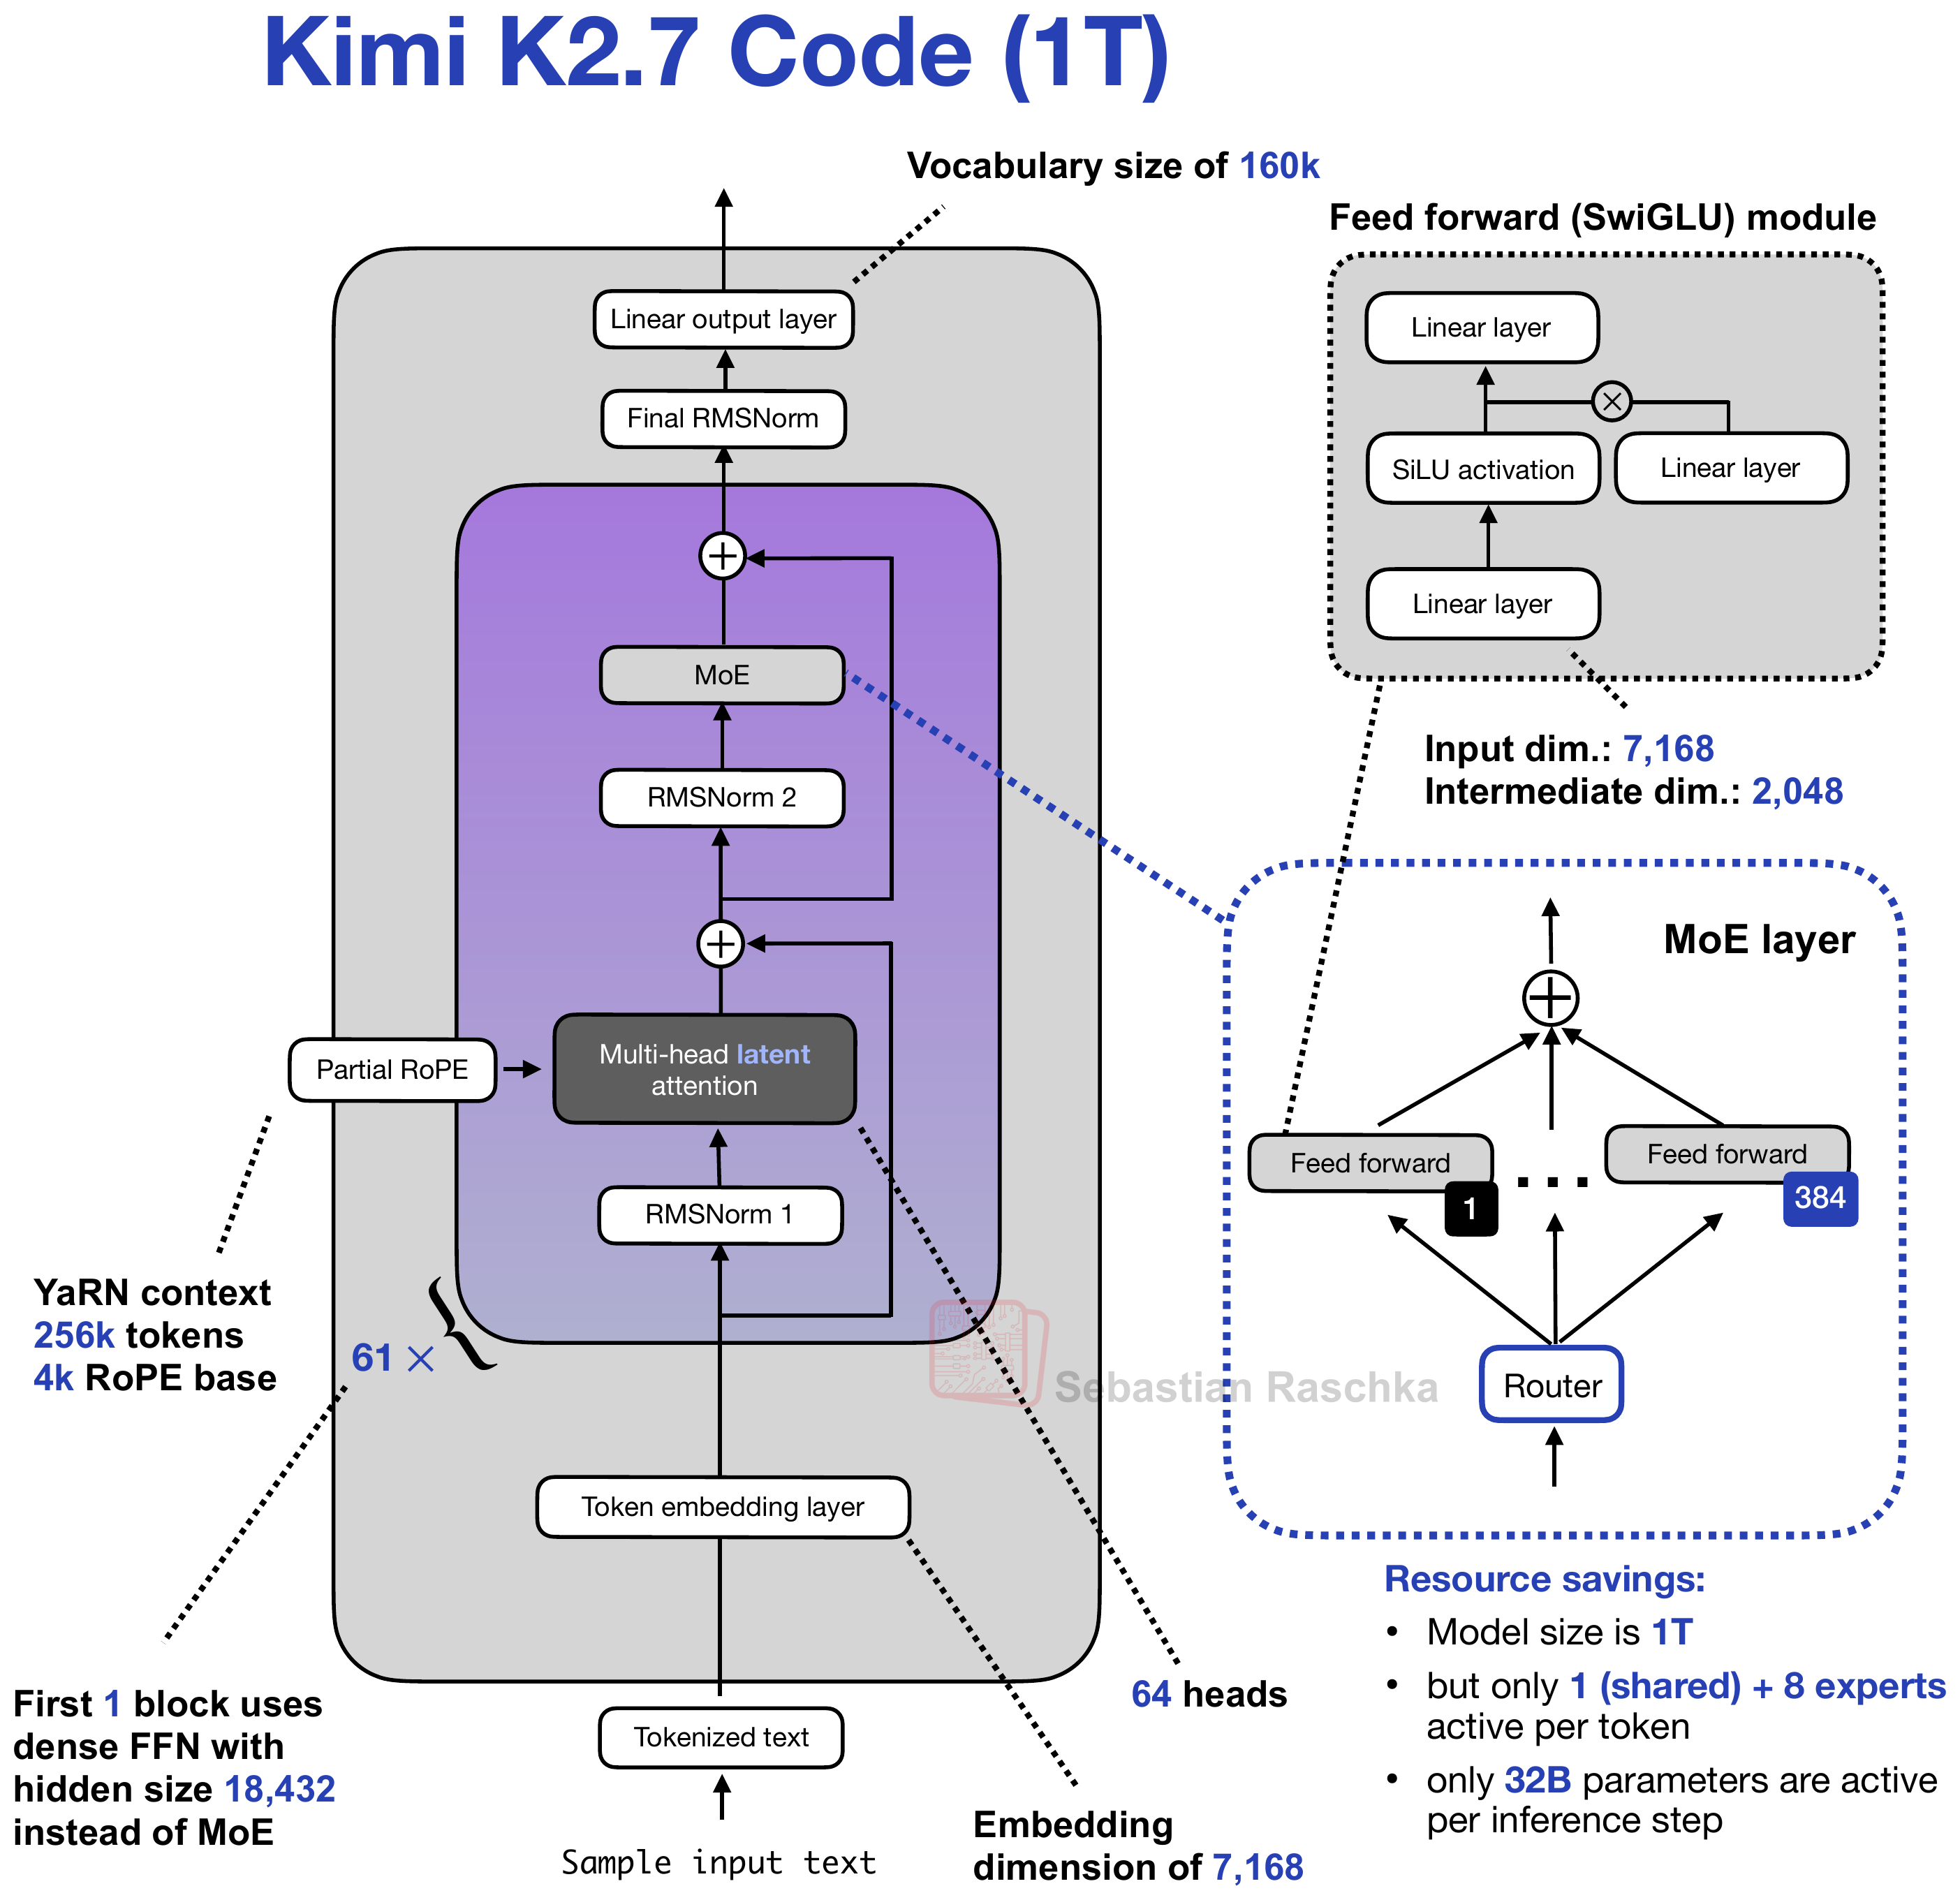
Architecture and specifications
- Scale
- 1T total, 32B active (3.2% active)
- Context (tokens)
- 262,144
- License
- Modified MIT License
- Date
- 2026-06-12
- Decoder type
- Sparse MoE
- Attention
- MLA
- Layer mix
- 61 MLA
- KV cache / token (bf16) info
- 68.6 KiB · Low
- Key detail
- Keeps the Kimi K2.5/K2.6 text architecture and shifts the release focus toward coding-agent workflows.
Training and benchmarks
- Pretraining data
- Not disclosed The release card does not disclose a version-specific pretraining-token total. Model card
- Post-training methods
- Not disclosed The release card does not specify the post-training methods used for this checkpoint. Model card