
JetBrains Mellum2 Thinking 12B-A2.5B Architecture
Back to JetBrains Mellum2 Thinking 12B-A2.5B in the gallery
JetBrains
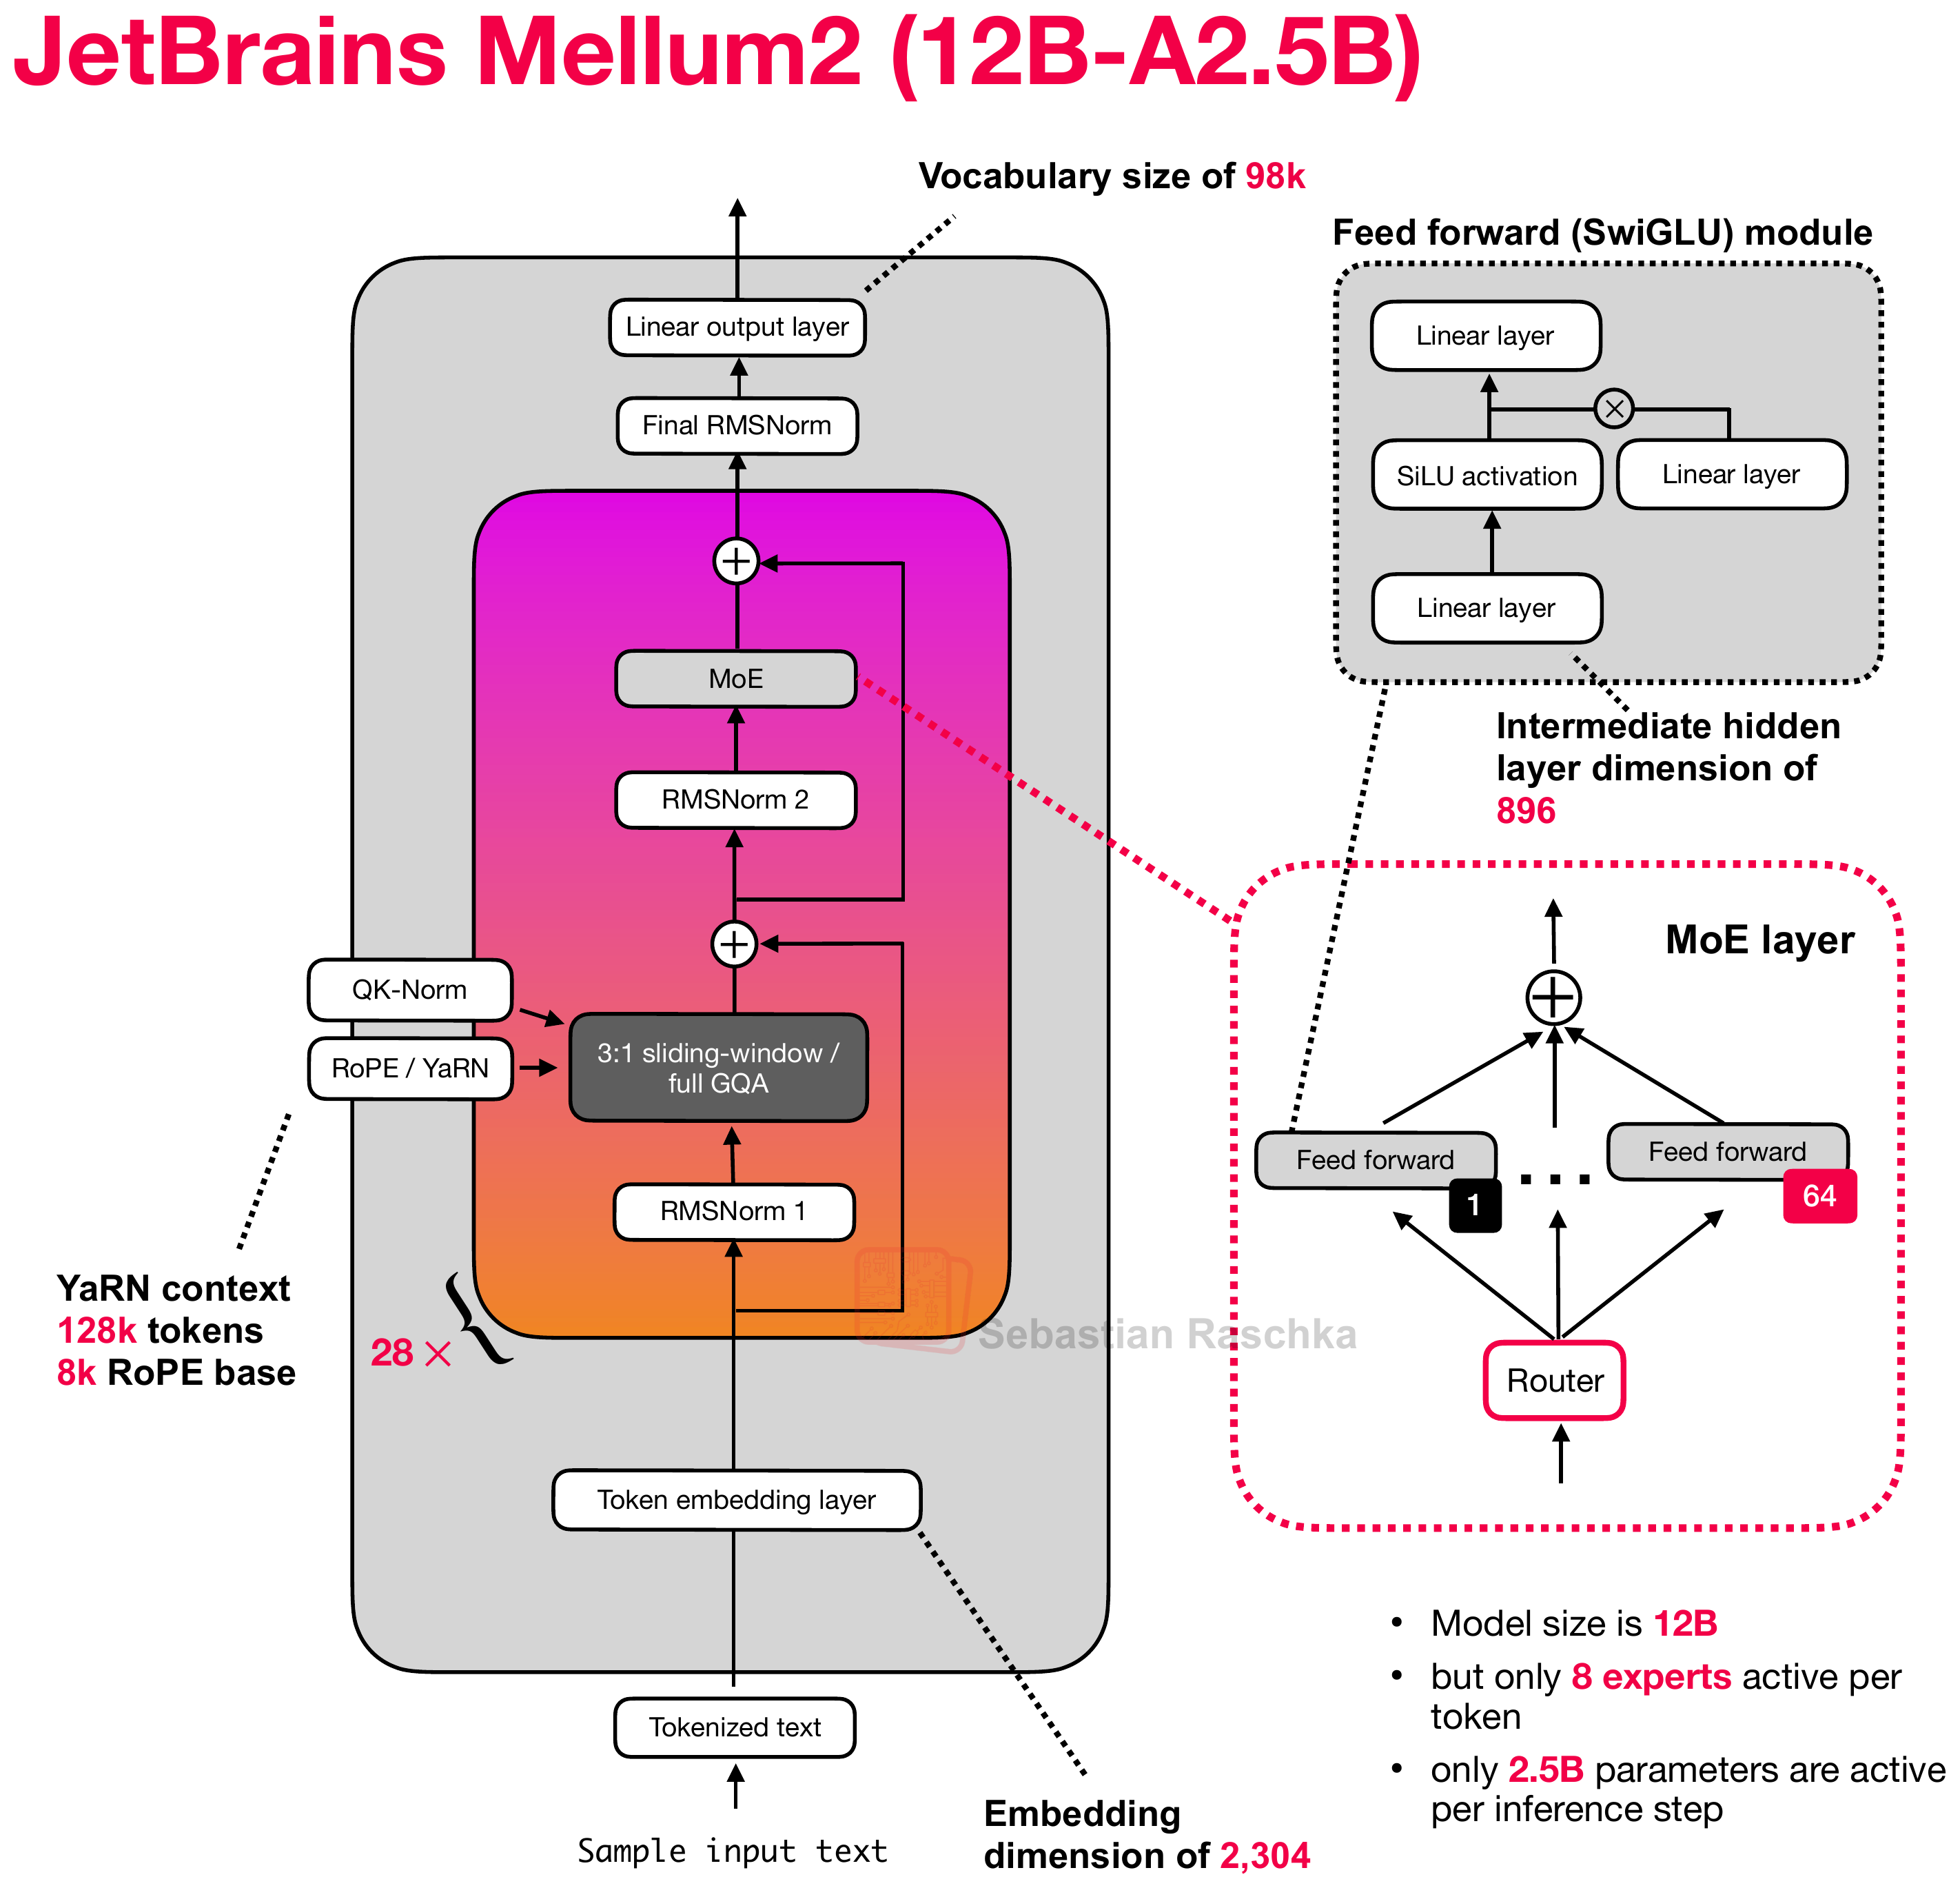
JetBrains' Mellum2 Thinking is a compact reasoning-tuned sparse MoE for code and agentic workflows.
Architecture and specifications
- Scale
- 12B total, 2.5B active (20.8% active)
- Context (tokens)
- 131,072
- Vocabulary
- 98,304 (~98k)
- License
- Apache License 2.0
- Date
- 2026-06-01
- Decoder type
- Sparse MoE
- Attention
- GQA with 3:1 sliding-window/full attention
- Layer mix
- 21 sliding-window + 7 full GQA
- KV cache / token (bf16) info
- 56 KiB · Low
- Key detail
- Uses 64 experts with 8 active per token, a 1024-token sliding window, and YaRN scaling on full-attention layers.
Training and benchmarks
- Pretraining data
- ~10.6T + 117B context-extension tokens Approximately 10.6T tokens in the main three-phase pretraining curriculum, followed by a separate approximately 117B-token long-context stage. Technical report
- Post-training methods
- SFT, RLVR The Thinking checkpoint uses SFT followed by RL with verifiable rewards, using GRPO across code, math, tool use, and other tasks. Technical report