
Gemma 4 12B Architecture
Back to Gemma 4 12B in the gallery
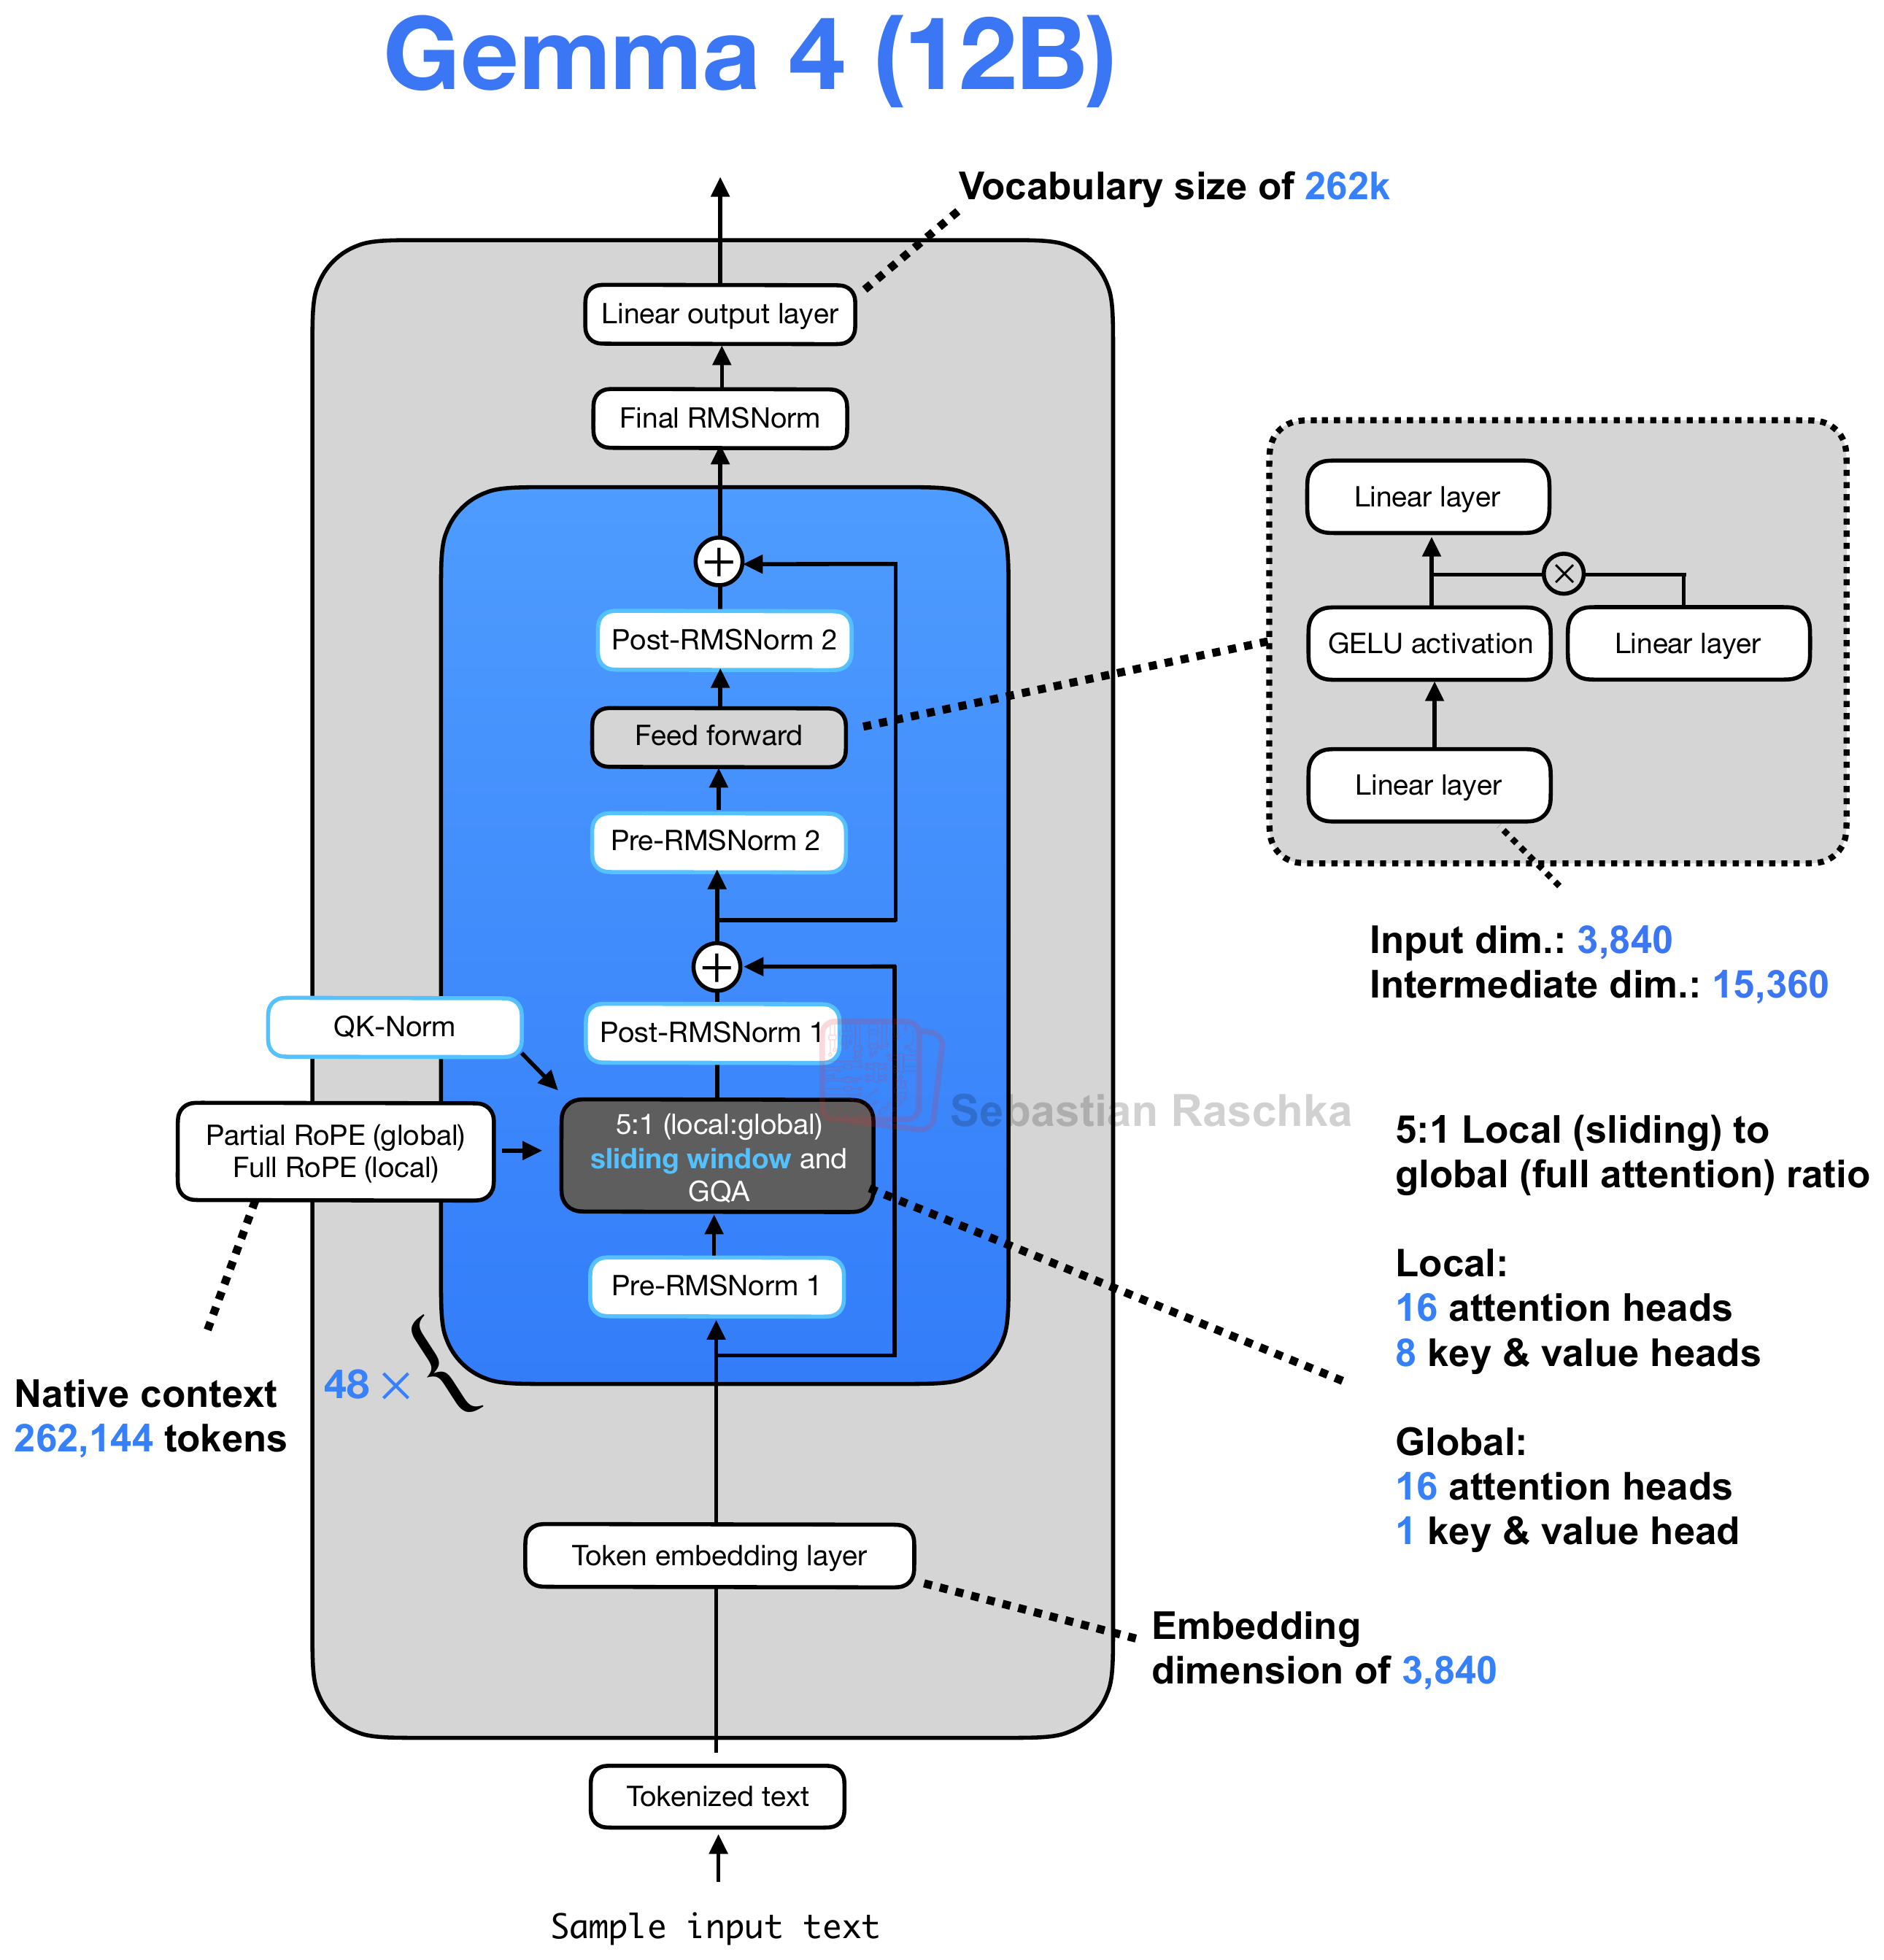
Dense Gemma 4 12B Unified uses an encoder-free multimodal input path, while its text decoder keeps the 31B-style local-global attention recipe.
Architecture and specifications
- Scale
- 12B parameters
- Context (tokens)
- 262,144
- Vocabulary
- 262,144 (~262k)
- License
- Apache License 2.0
- Date
- 2026-06-03
- Decoder type
- Dense
- Attention
- GQA with QK-Norm, unified K/V on global layers, p-RoPE on global layers, and 5:1 sliding-window/global attention
- Layer mix
- 40 sliding-window + 8 global
- KV cache / token (bf16) info
- 330 KiB (compact global K=V layout) · Very high
- Key detail
- Figure shows the 48-layer text decoder; the full 12B Unified model also projects audio, image, and video inputs directly into the decoder input stream.
Training and benchmarks
- Pretraining data
- Not disclosed No per-model pretraining-token count is published. Gemma 4 model card
- Post-training methods
- Instruction tuning IT variant; the report refers to Gemma 3-like post-training without itemizing alignment stages. Gemma 4 report