
Tencent Hy4 770B-A49B Architecture
Back to Tencent Hy4 770B-A49B in the gallery
Tencent
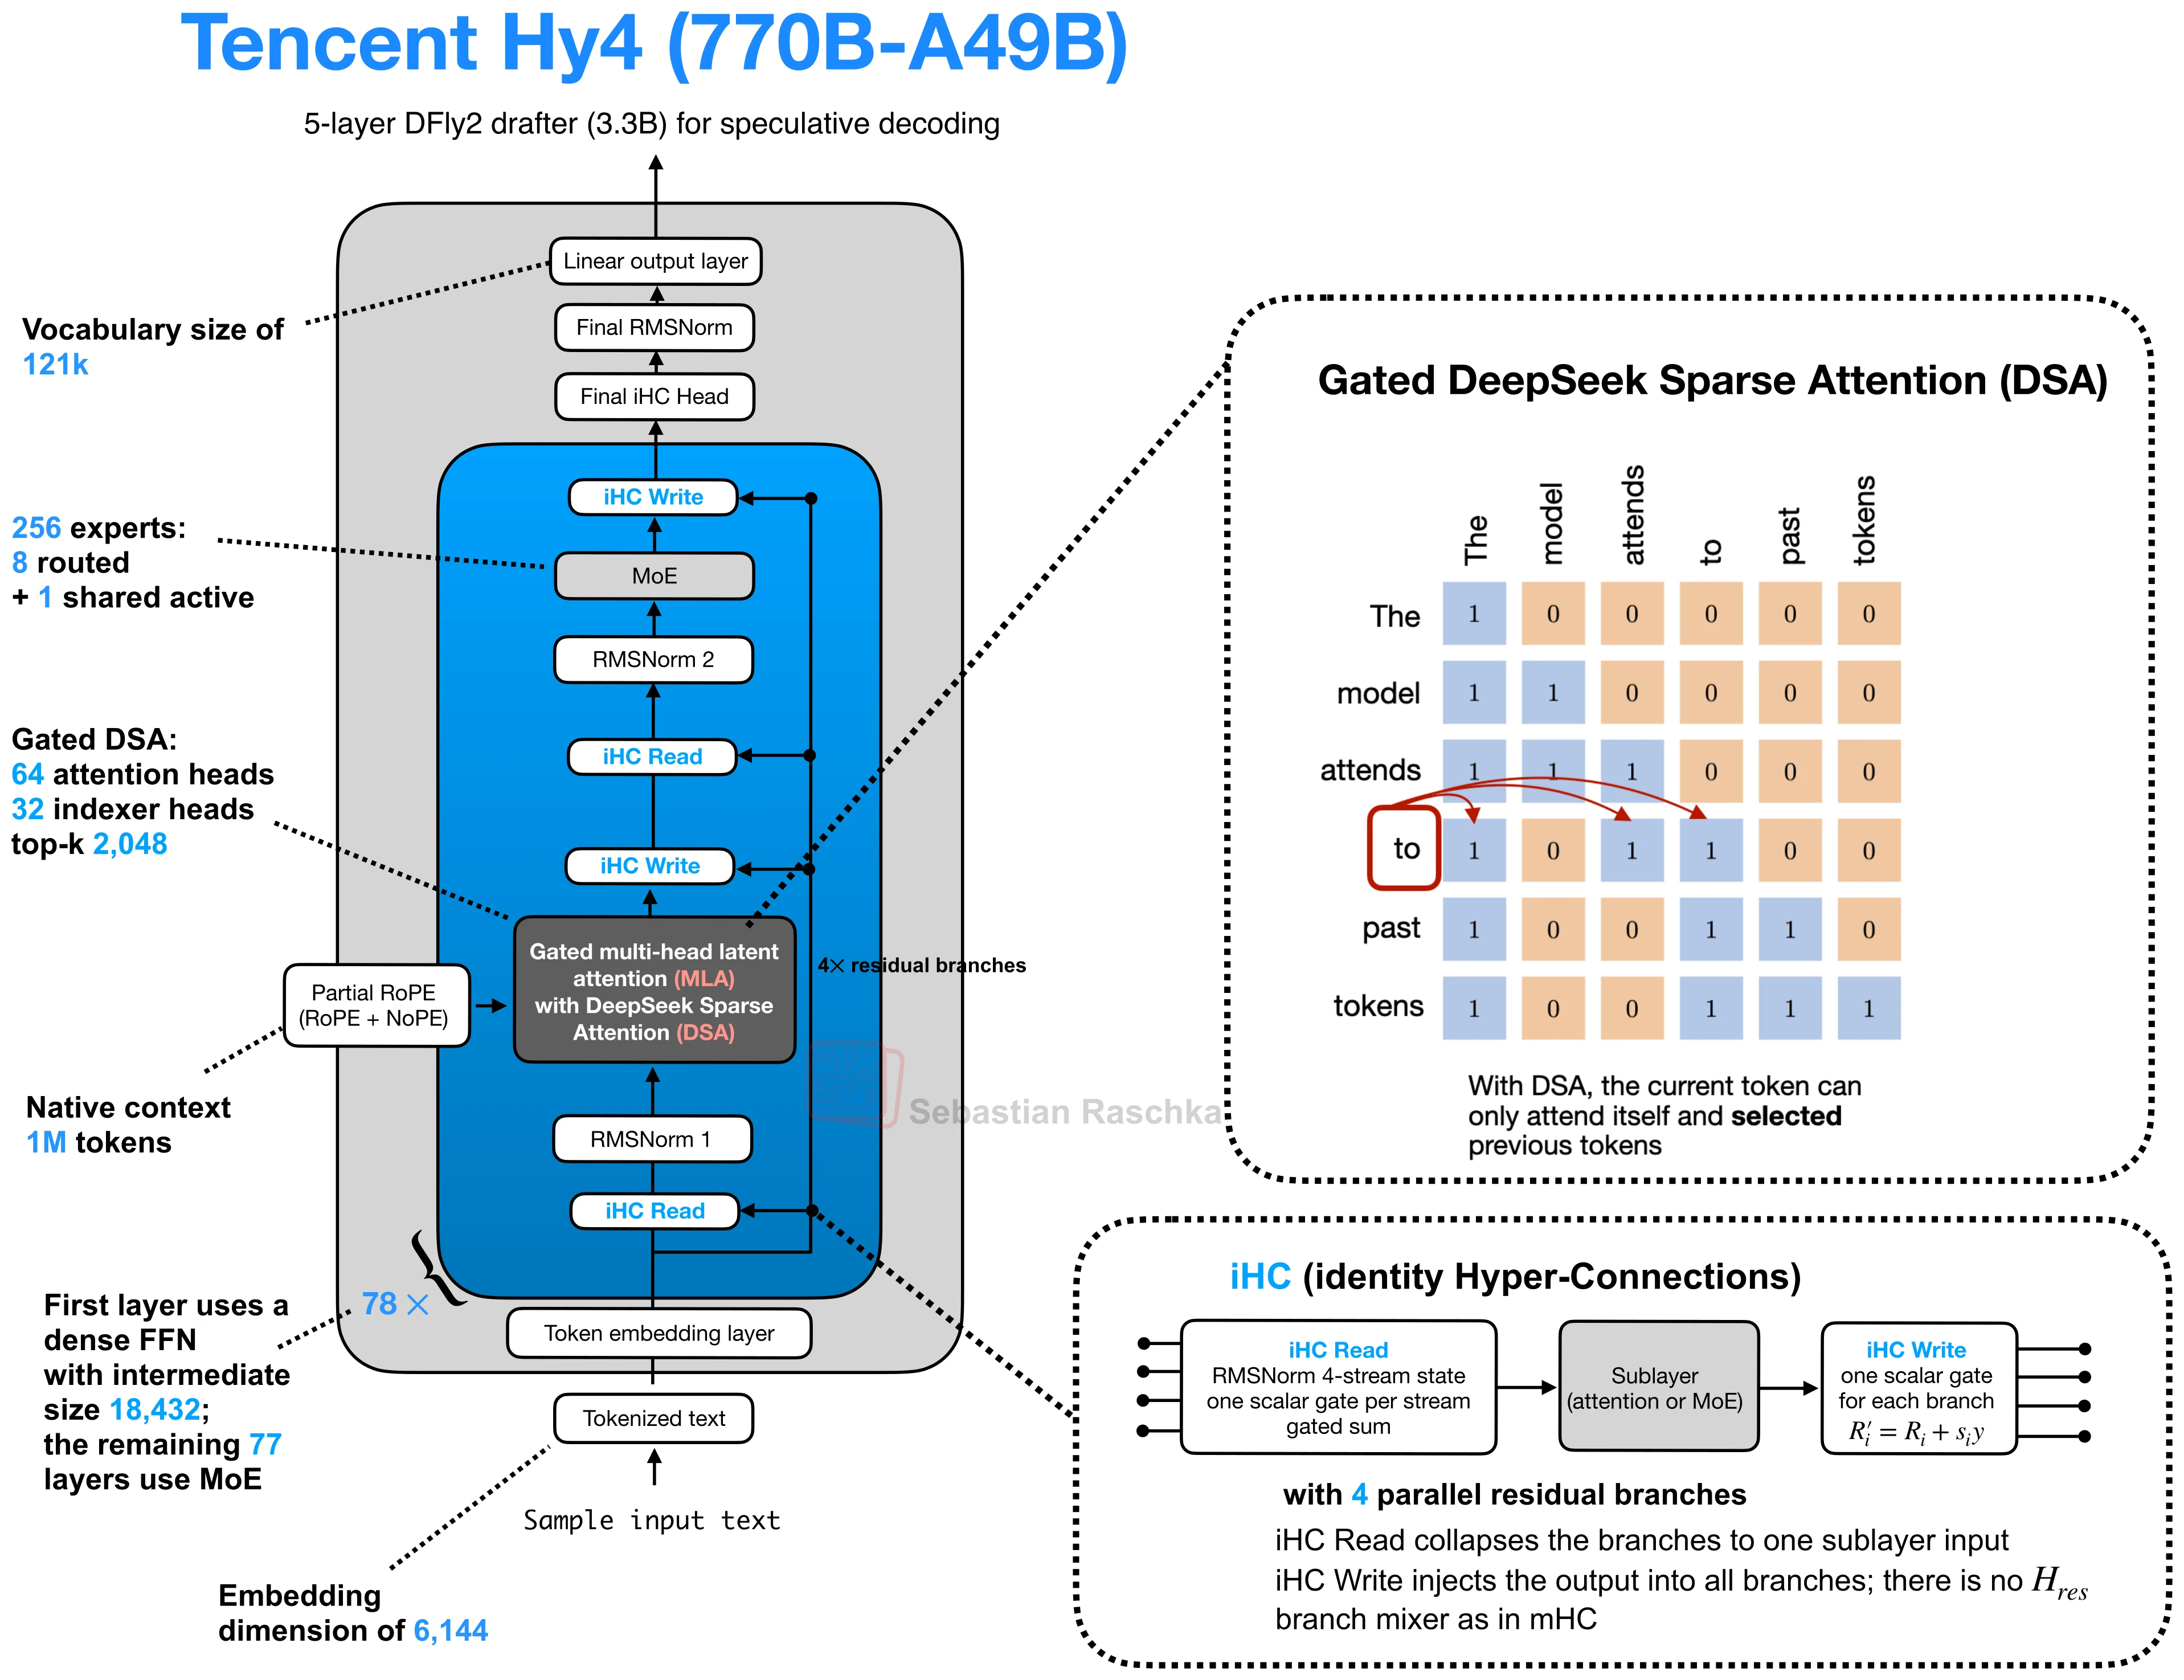
Tencent Hy4 770B-A49B combines gated DeepSeek Sparse Attention with four-stream identity Hyper-Connections (iHC). After one dense layer, each of the next 77 layers activates 8 of 256 routed experts and one shared expert per token.
Architecture and specifications
- Scale
- 770B backbone, 49B active (6.4% active), plus a 3.3B DFly2 drafter
- Context (tokens)
- 1,048,576
- Vocabulary
- 120,832 (~121k)
- License
- Tencent Hy License 1.0
- Date
- 2026-11-20
- Decoder type
- Sparse MoE
- Attention
- Gated MLA with DeepSeek Sparse Attention and cross-layer index reuse (IndexCache)
- Layer mix
- 78 gated MLA/DSA layers (1 dense FFN + 77 MoE)
- KV cache / token (bf16) info
- 93 KiB · Moderate
- Key detail
- The five-layer DFly2 drafter reuses both the backbone's KV cache and the token positions selected by its top-2,048 sparse attention indexer.
Training and benchmarks
- Pretraining data
- Not disclosed Tencent reports using synthetic instruction data during mid-training. The model card gives no total token count. Model card
- Post-training methods
- RL The team used reinforcement learning for reasoning and long-horizon agent tasks. Core contributor's description of Hy4 post-training · Model card