
Ouro-Thinking 2.6B Architecture
Back to Ouro-Thinking 2.6B in the gallery
ByteDance
ByteDance's dense LoopLM reuses one 48-layer MHA stack across four recurrent passes and trains an exit gate over the intermediate representations.
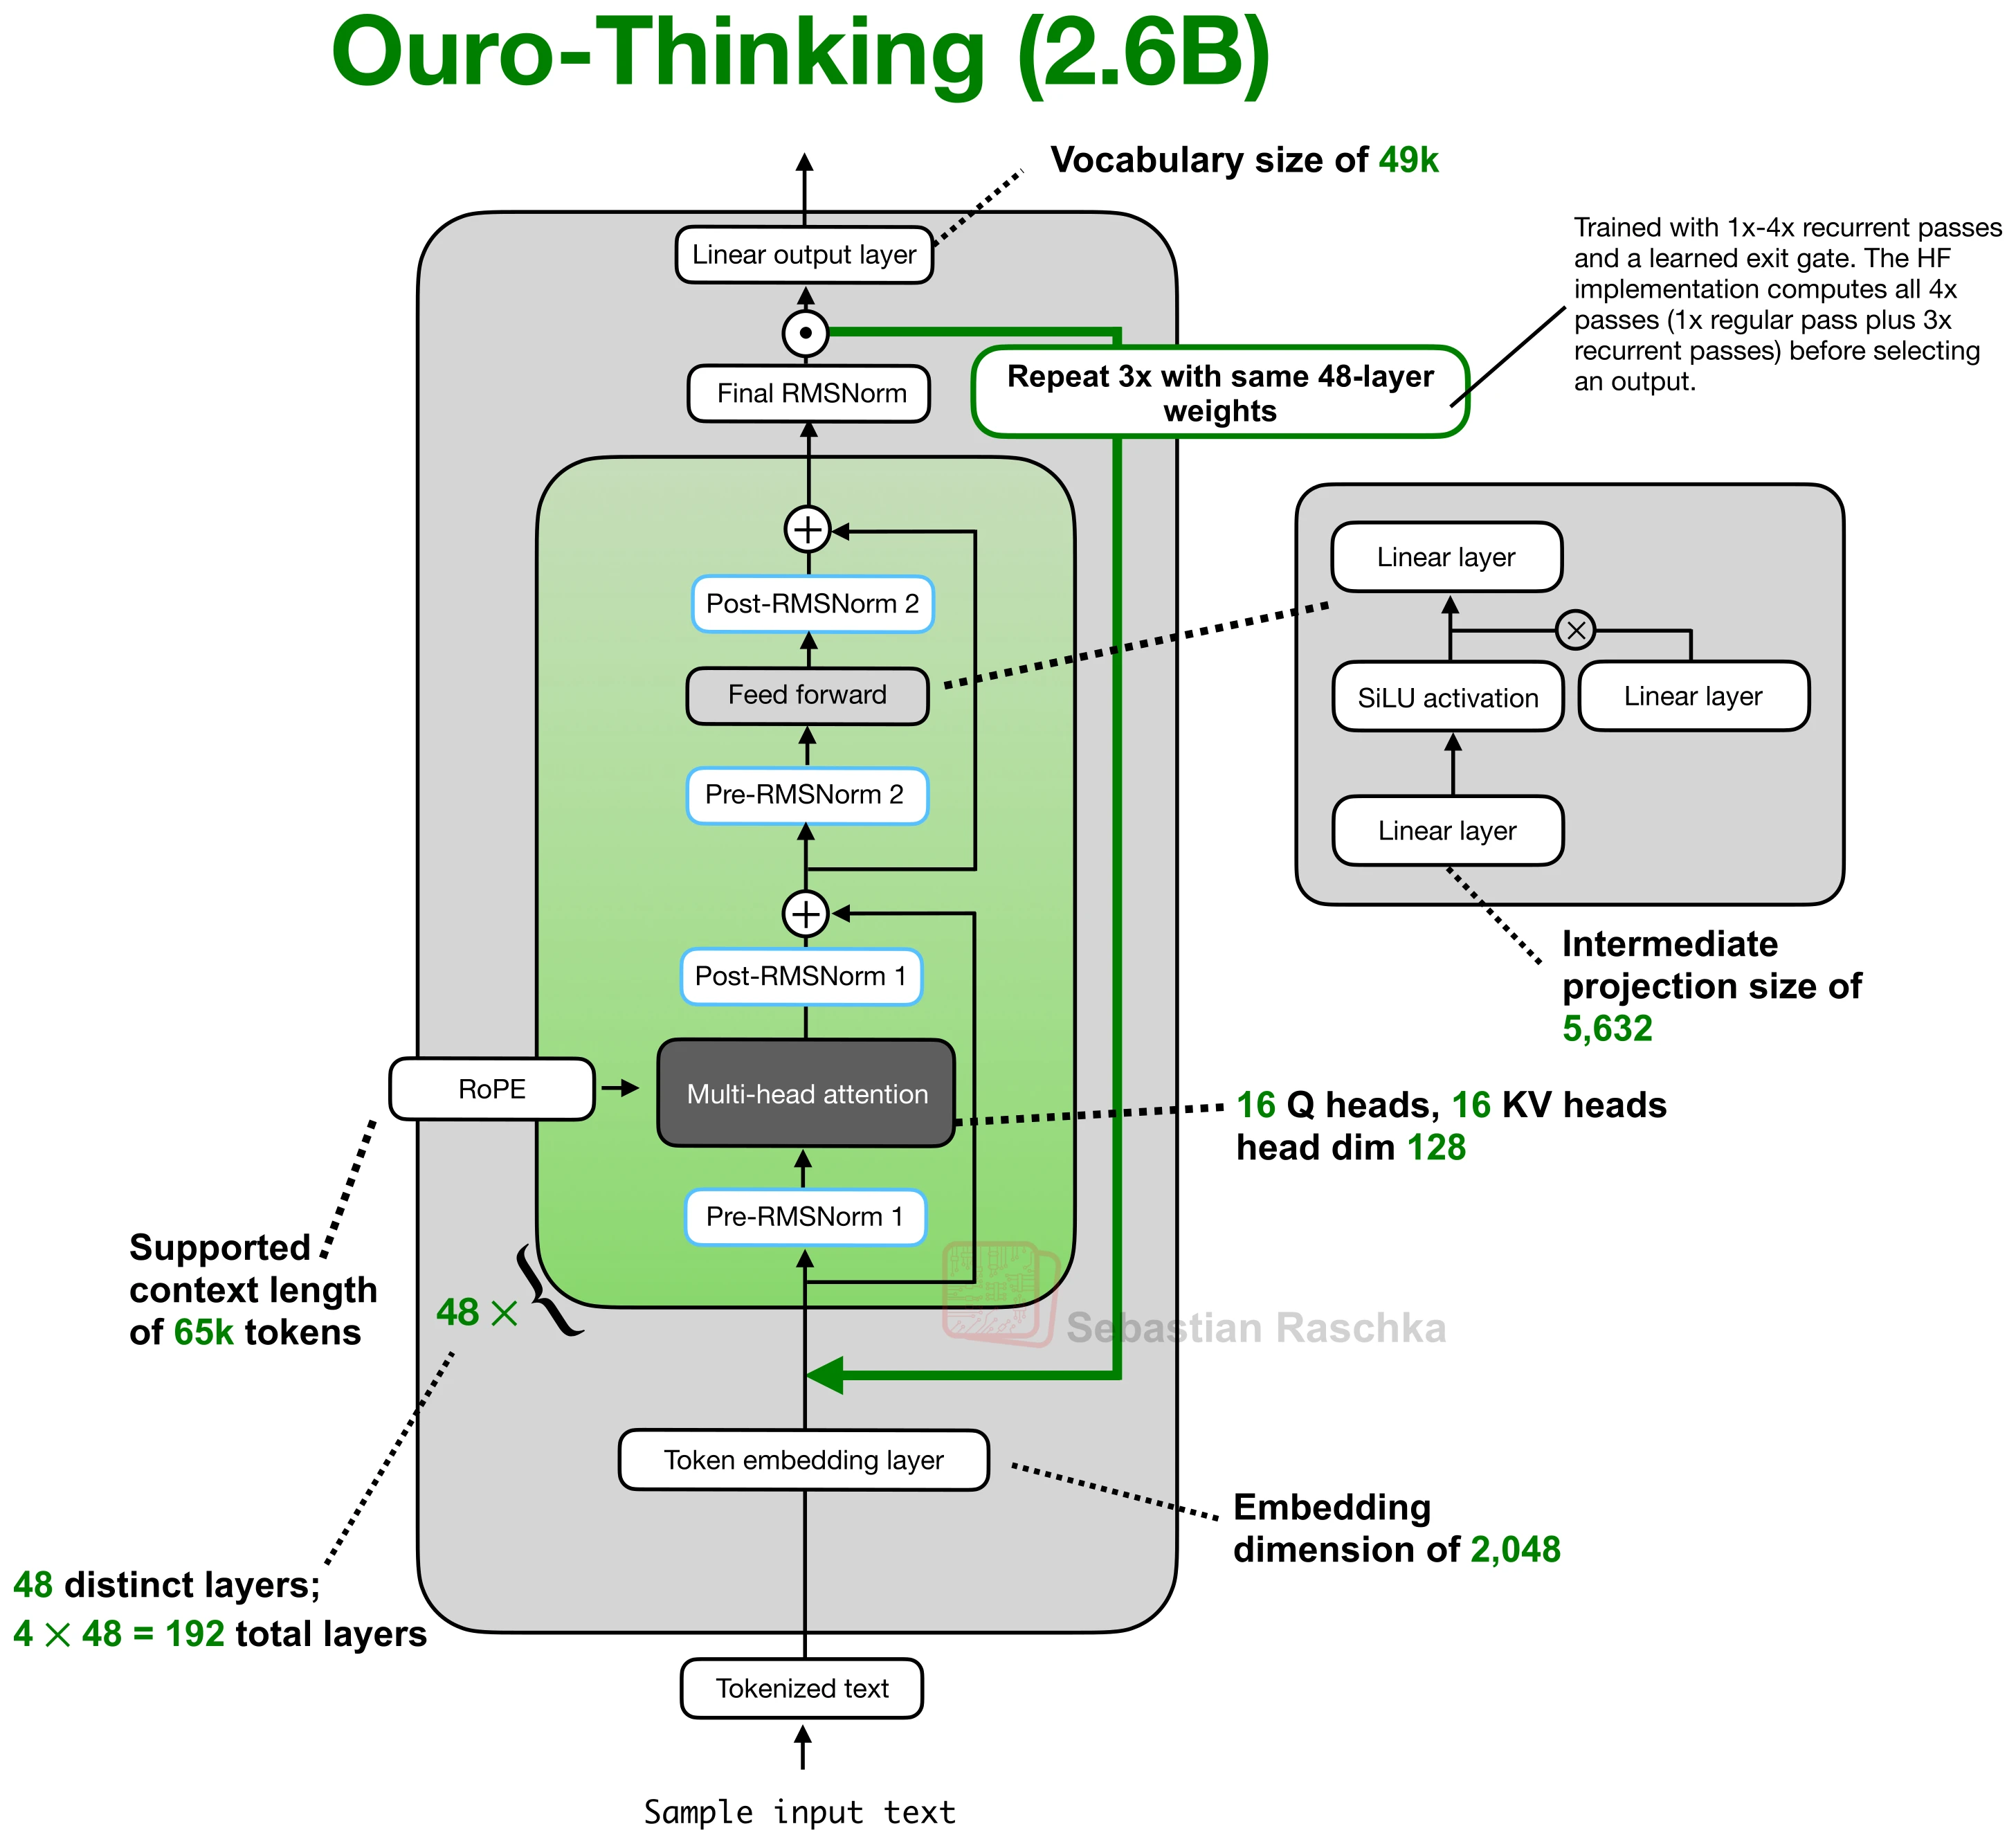
Architecture and specifications
- Scale
- 2.6B parameters
- Context (tokens)
- 65,536
- Vocabulary
- 49,152 (~49k)
- License
- Apache License 2.0
- Date
- 2025-10-29
- Decoder type
- Dense
- Attention
- MHA with RoPE
- Layer mix
- 48 shared MHA layers × 4 passes
- KV cache / token (bf16) info
- 1.5 MiB · Very high
- Key detail
- Reuses the same 48-layer MHA stack across four passes, yielding 192 block applications, with sandwich RMSNorm and a learned exit gate.
Training and benchmarks
- Pretraining data
- ≈7.7T tokens The report's rounded total covers initial pretraining, continued training, context extension, and mid-training before reasoning SFT. Ouro technical report
- Post-training methods
- SFT Reasoning SFT on approximately 8.3M examples produces the Thinking release. Separate exploratory RLVR runs did not outperform the final SFT checkpoint. Ouro technical report